mirror of
https://github.com/pgsty/minio.git
synced 2026-10-18 15:36:11 +03:00
Compare commits
195 Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Harshavardhana |
b598402738 | ||
|
Harshavardhana
|
bd026b913f | ||
|
Harshavardhana
|
72ff69d9bb | ||
|
Harshavardhana
|
f30417d9a8 | ||
|
jiuker
|
47a4ad3cd7 | ||
|
Klaus Post
|
2f7a10ab31 | ||
|
Harshavardhana
|
b534dc69ab | ||
|
Harshavardhana
|
7b7d2ea7d4 | ||
|
Aditya Manthramurthy
|
e00de1c302 | ||
|
Harshavardhana
|
3549e583a6 | ||
|
Andi
|
f5e3eedf34 | ||
|
Harshavardhana
|
519dbfebf6 | ||
|
Harshavardhana
|
9a267f9270 | ||
|
Anis Eleuch
|
67bd71b7a5 | ||
|
Klaus Post
|
ec49fff583 | ||
|
Andreas Auernhammer
|
8b660e18f2 | ||
|
Harshavardhana
|
981497799a | ||
|
Minio Trusted
|
b9bdc17465 | ||
|
Olli Janatuinen
|
b413ff9fdb | ||
|
Harshavardhana
|
6a15580817 | ||
|
Cesar N
|
39633a5581 | ||
|
Alex
|
1e83f15e2f | ||
|
Harshavardhana
|
888d2bb1d8 | ||
|
Klaus Post
|
847ee5ac45 | ||
|
jiuker
|
9a9a49aa84 | ||
|
Harshavardhana
|
a03ca80269 | ||
|
Harshavardhana
|
523bd769f1 | ||
|
Harshavardhana
|
8ff70ea5a9 | ||
|
Harshavardhana
|
da3e7747ca | ||
|
Klaus Post
|
4afb59e63f | ||
|
Harshavardhana
|
1526e7ece3 | ||
|
Krishnan Parthasarathi
|
6c07bfee8a | ||
|
Poorna
|
446c760820 | ||
|
Shireesh Anjal
|
04f92f1291 | ||
|
Klaus Post
|
4a60a7794d | ||
|
Bala FA
|
e5b16adb1c | ||
|
Harshavardhana
|
402a3ac719 | ||
|
Aditya Manthramurthy
|
f3d61c51fc | ||
|
Klaus Post
|
0cde17ae5d | ||
|
Harshavardhana
|
8c1bba681b | ||
|
Klaus Post
|
dbfb5e797b | ||
|
Harshavardhana
|
08ff702434 | ||
|
Klaus Post
|
0e2148264a | ||
|
Minio Trusted
|
a75f42344b | ||
|
Krishnan Parthasarathi
|
7926401cbd | ||
|
Harshavardhana
|
8161411c5d | ||
|
Klaus Post
|
f64dea2aac | ||
|
Shubhendu
|
6579304d8c | ||
|
jiuker
|
6bb10a81a6 | ||
|
Klaus Post
|
3cf8a7c888 | ||
|
Minio Trusted
|
2e38bb5175 | ||
|
Harshavardhana
|
a372c6a377 | ||
|
Harshavardhana
|
93b2f8a0c5 | ||
|
opencmit2
|
1a6568a25d | ||
|
Poorna
|
9e95703efc | ||
|
Anis Eleuch
|
d8e05aca81 | ||
|
Praveen raj Mani
|
410a1ac040 | ||
|
Shireesh Anjal
|
4caa3422bd | ||
|
Dennis Marttinen
|
a658b976f5 | ||
|
Anis Eleuch
|
135874ebdc | ||
|
Harshavardhana
|
f4f1c42cba | ||
|
Poorna
|
e7aa26dc29 | ||
|
Harshavardhana
|
c54ffde568 | ||
|
Anis Eleuch
|
9a3c992d7a | ||
|
Aditya Manthramurthy
|
0c855638de | ||
|
Cesar N
|
943d815783 | ||
|
Ramon de Klein
|
4c0acba62d | ||
|
Aditya Manthramurthy
|
62c3cdee75 | ||
|
Aditya Manthramurthy
|
3212d0c8cd | ||
|
Harshavardhana
|
1d03bea965 | ||
|
Klaus Post
|
fbfeb59658 | ||
|
Ramon de Klein
|
701da1282a | ||
|
jiuker
|
df93ff92ba | ||
|
Shireesh Anjal
|
77d5331e85 | ||
|
Bala FA
|
14cdadfb56 | ||
|
Harshavardhana
|
f3a52cc195 | ||
|
Aditya Manthramurthy
|
7640cd24c9 | ||
|
Shireesh Anjal
|
f7b665347e | ||
|
Harshavardhana
|
9693c382a8 | ||
|
jiuker
|
ee1047bd52 | ||
|
Seiya
|
5ea5ab162b | ||
|
Klaus Post
|
b5a09ff96b | ||
|
Harshavardhana
|
95c65f4e8f | ||
|
Harshavardhana
|
6bfff7532e | ||
|
Harshavardhana
|
1aa8896ad6 | ||
|
Krishnan Parthasarathi
|
3e32ceb39f | ||
|
dependabot[bot]
|
ca1350b092 | ||
|
jiuker
|
9205434ed3 | ||
|
Harshavardhana
|
cd50e9b4bc | ||
|
Klaus Post
|
ec816f3840 | ||
|
Klaus Post
|
5f774951b1 | ||
|
Harshavardhana
|
2ca9befd2a | ||
|
Harshavardhana
|
72f5cb577e | ||
|
Robert Lützner
|
928c0181bf | ||
|
Harshavardhana
|
03767d26da | ||
|
Sveinn
|
108e6f92d4 | ||
|
Harshavardhana
|
d653a59fc0 | ||
|
Minio Trusted
|
01bfdf949a | ||
|
Aditya Manthramurthy
|
98f7821eb3 | ||
|
jiuker
|
2d3898e0d5 | ||
|
Aditya Manthramurthy
|
ae46ce9937 | ||
|
Anis Eleuch
|
dfc112c06b | ||
|
Shireesh Anjal
|
ca5fab8656 | ||
|
Shireesh Anjal
|
6df76ca73c | ||
|
Harshavardhana
|
f65dd3e5a2 | ||
|
Harshavardhana
|
a8d601b64a | ||
|
Viktor Szépe
|
73b4794cf7 | ||
|
Klaus Post
|
e2709ea129 | ||
|
Allan Roger Reid
|
740ec80819 | ||
|
Harshavardhana
|
d95e054282 | ||
|
Allan Roger Reid
|
7c1f9667d1 | ||
|
Klaus Post
|
9246990496 | ||
|
Markus Wagner
|
0cf3d93360 | ||
|
Harshavardhana
|
cb06aee5ac | ||
|
Shubhendu
|
1c70e9ed1b | ||
|
jiuker
|
f3d6a2dd37 | ||
|
Harshavardhana
|
d1c58fc2eb | ||
|
Allan Roger Reid
|
b8f05b1471 | ||
|
Klaus Post
|
e7baf78ee8 | ||
|
guangwu
|
87299eba10 | ||
|
Shubhendu
|
d3a07c29ba | ||
|
Aditya Manthramurthy
|
8d39b715dc | ||
|
Harshavardhana
|
7e3166475d | ||
|
Klaus Post
|
5206c0e883 | ||
|
Harshavardhana
|
41ec038523 | ||
|
Shireesh Anjal
|
08d3d06a06 | ||
|
Harshavardhana
|
074febd9e1 | ||
|
Harshavardhana
|
aa8d25797b | ||
|
Alex
|
8d7d4adb91 | ||
|
Poorna
|
ffa91f9794 | ||
|
Harshavardhana
|
0c31e61343 | ||
|
Harshavardhana
|
9b926f7dbe | ||
|
Harshavardhana
|
35d8728990 | ||
|
Allan Roger Reid
|
f7ed9a75ba | ||
|
jiuker
|
9496c17e13 | ||
|
jiuker
|
ed64e91f06 | ||
|
jiuker
|
a481825ae1 | ||
|
Harshavardhana
|
7bb0f32332 | ||
|
Anis Eleuch
|
c6f8dc431e | ||
|
Alexander Thaller
|
78f177b8ee | ||
|
Anis Eleuch
|
787c44c39d | ||
|
Anis Eleuch
|
f06fee0364 | ||
|
Harshavardhana
|
c957e0d426 | ||
|
Harshavardhana
|
04101d472f | ||
|
Minio Trusted
|
51fc145161 | ||
|
Taran Pelkey
|
9d63bb1b41 | ||
|
Aditya Manthramurthy
|
8ff2a7a2b9 | ||
|
Harshavardhana
|
91f91d8f47 | ||
|
Harshavardhana
|
a207bd6790 | ||
|
Harshavardhana
|
96d226c0b1 | ||
|
Krishnan Parthasarathi
|
a86d98826d | ||
|
Harshavardhana
|
1bb670ecba | ||
|
Aditya Manthramurthy
|
c9e9a8e2b9 | ||
|
jiuker
|
272367ccd2 | ||
|
Anis Eleuch
|
95bf4a57b6 | ||
|
Harshavardhana
|
2228eb61cb | ||
|
Alexander Thaller
|
5f07eb2d17 | ||
|
Shubhendu
|
d96d696841 | ||
|
Harshavardhana
|
e18c0ab9bf | ||
|
Andreas Auernhammer
|
faeb2b7e79 | ||
|
Anis Eleuch
|
97ce11cb6b | ||
|
Harshavardhana
|
d7daae4762 | ||
|
jiuker
|
3d86ae12bc | ||
|
Sveinn
|
ba46ee5dfa | ||
|
Klaus Post
|
912bbb2f1d | ||
|
Harshavardhana
|
4f660a8eb7 | ||
|
Praveen raj Mani
|
ae4fb1b72e | ||
|
Klaus Post
|
b435806d91 | ||
|
Minio Trusted
|
06929258bc | ||
|
Harshavardhana
|
cb577835d9 | ||
|
Harshavardhana
|
7f35f74f14 | ||
|
Klaus Post
|
3d6194e93c | ||
|
Harshavardhana
|
72c7845f7e | ||
|
Harshavardhana
|
1c99597a06 | ||
|
Harshavardhana
|
feb9d8480b | ||
|
Aditya Manthramurthy
|
4e670458b8 | ||
|
Aditya Manthramurthy
|
48deccdc40 | ||
|
Andi Bräu
|
2eee744e34 | ||
|
Kaan Kabalak
|
3f72439b8a | ||
|
Shubhendu
|
468a9fae83 | ||
|
Shubhendu
|
d87f91720b | ||
|
Klaus Post
|
aa0eec16ab | ||
|
Shubhendu
|
d63e603040 | ||
|
jiuker
|
8222a640ac | ||
|
Aditya Manthramurthy
|
7e45d84ace | ||
|
Harshavardhana
|
139a606f0a | ||
|
Harshavardhana
|
289223b6de | ||
|
Harshavardhana
|
c61dd16a1e | ||
|
Harshavardhana
|
3e38fa54a5 | ||
|
jiuker
|
4a02189ba0 | ||
|
Shubhendu
|
3d4fc28ec9 | ||
|
jiuker
|
ec3a3bb10d | ||
|
Harshavardhana
|
364d3a0ac9 | ||
|
Harshavardhana
|
cb536a73eb | ||
|
Minio Trusted
|
428155add9 |
@@ -9,6 +9,6 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: 'Checkout Repository'
|
||||
uses: actions/checkout@v3
|
||||
uses: actions/checkout@v4
|
||||
- name: 'Dependency Review'
|
||||
uses: actions/dependency-review-action@v1
|
||||
uses: actions/dependency-review-action@v4
|
||||
|
||||
@@ -3,12 +3,12 @@ name: Crosscompile
|
||||
on:
|
||||
pull_request:
|
||||
branches:
|
||||
- master
|
||||
- next
|
||||
- master
|
||||
- next
|
||||
|
||||
# This ensures that previous jobs for the PR are canceled when the PR is
|
||||
# updated.
|
||||
concurrency:
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.head_ref }}
|
||||
cancel-in-progress: true
|
||||
|
||||
@@ -21,11 +21,11 @@ jobs:
|
||||
runs-on: ${{ matrix.os }}
|
||||
strategy:
|
||||
matrix:
|
||||
go-version: [1.21.x]
|
||||
go-version: [1.22.x]
|
||||
os: [ubuntu-latest]
|
||||
steps:
|
||||
- uses: actions/checkout@ac593985615ec2ede58e132d2e21d2b1cbd6127c # v3
|
||||
- uses: actions/setup-go@6edd4406fa81c3da01a34fa6f6343087c207a568 # v3
|
||||
- uses: actions/checkout@v4
|
||||
- uses: actions/setup-go@v5
|
||||
with:
|
||||
go-version: ${{ matrix.go-version }}
|
||||
check-latest: true
|
||||
|
||||
@@ -21,11 +21,11 @@ jobs:
|
||||
runs-on: ${{ matrix.os }}
|
||||
strategy:
|
||||
matrix:
|
||||
go-version: [1.21.x]
|
||||
go-version: [1.22.x]
|
||||
os: [ubuntu-latest]
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: actions/setup-go@v3
|
||||
- uses: actions/checkout@v4
|
||||
- uses: actions/setup-go@v5
|
||||
with:
|
||||
go-version: ${{ matrix.go-version }}
|
||||
|
||||
|
||||
@@ -21,11 +21,11 @@ jobs:
|
||||
runs-on: ${{ matrix.os }}
|
||||
strategy:
|
||||
matrix:
|
||||
go-version: [1.21.x]
|
||||
go-version: [1.22.x]
|
||||
os: [ubuntu-latest]
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: actions/setup-go@v3
|
||||
- uses: actions/checkout@v4
|
||||
- uses: actions/setup-go@v5
|
||||
with:
|
||||
go-version: ${{ matrix.go-version }}
|
||||
check-latest: true
|
||||
|
||||
@@ -21,11 +21,11 @@ jobs:
|
||||
runs-on: ${{ matrix.os }}
|
||||
strategy:
|
||||
matrix:
|
||||
go-version: [1.21.x]
|
||||
go-version: [1.22.x]
|
||||
os: [ubuntu-latest, windows-latest]
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: actions/setup-go@v3
|
||||
- uses: actions/checkout@v4
|
||||
- uses: actions/setup-go@v5
|
||||
with:
|
||||
go-version: ${{ matrix.go-version }}
|
||||
check-latest: true
|
||||
|
||||
@@ -21,11 +21,11 @@ jobs:
|
||||
runs-on: ${{ matrix.os }}
|
||||
strategy:
|
||||
matrix:
|
||||
go-version: [1.21.x]
|
||||
go-version: [1.22.x]
|
||||
os: [ubuntu-latest]
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: actions/setup-go@v3
|
||||
- uses: actions/checkout@v4
|
||||
- uses: actions/setup-go@v5
|
||||
with:
|
||||
go-version: ${{ matrix.go-version }}
|
||||
check-latest: true
|
||||
|
||||
@@ -20,7 +20,7 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v3
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: Install Helm
|
||||
uses: azure/setup-helm@v3
|
||||
|
||||
@@ -3,8 +3,8 @@ name: IAM integration
|
||||
on:
|
||||
pull_request:
|
||||
branches:
|
||||
- master
|
||||
- next
|
||||
- master
|
||||
- next
|
||||
|
||||
# This ensures that previous jobs for the PR are canceled when the PR is
|
||||
# updated.
|
||||
@@ -62,7 +62,7 @@ jobs:
|
||||
# are turned off - i.e. if ldap="", then ldap server is not enabled for
|
||||
# the tests.
|
||||
matrix:
|
||||
go-version: [1.21.x]
|
||||
go-version: [1.22.x]
|
||||
ldap: ["", "localhost:389"]
|
||||
etcd: ["", "http://localhost:2379"]
|
||||
openid: ["", "http://127.0.0.1:5556/dex"]
|
||||
@@ -76,8 +76,8 @@ jobs:
|
||||
openid: "http://127.0.0.1:5556/dex"
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: actions/setup-go@v3
|
||||
- uses: actions/checkout@v4
|
||||
- uses: actions/setup-go@v5
|
||||
with:
|
||||
go-version: ${{ matrix.go-version }}
|
||||
check-latest: true
|
||||
@@ -112,6 +112,12 @@ jobs:
|
||||
sudo sysctl net.ipv6.conf.default.disable_ipv6=0
|
||||
go run docs/iam/access-manager-plugin.go &
|
||||
make test-iam
|
||||
- name: Test MinIO Old Version data to IAM import current version
|
||||
if: matrix.ldap == 'ldaphost:389'
|
||||
env:
|
||||
_MINIO_LDAP_TEST_SERVER: ${{ matrix.ldap }}
|
||||
run: |
|
||||
make test-iam-ldap-upgrade-import
|
||||
- name: Test LDAP for automatic site replication
|
||||
if: matrix.ldap == 'localhost:389'
|
||||
run: |
|
||||
|
||||
@@ -25,12 +25,12 @@ jobs:
|
||||
sudo -S rm -rf ${GITHUB_WORKSPACE}
|
||||
mkdir ${GITHUB_WORKSPACE}
|
||||
- name: checkout-step
|
||||
uses: actions/checkout@v3
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: setup-go-step
|
||||
uses: actions/setup-go@v2
|
||||
uses: actions/setup-go@v5
|
||||
with:
|
||||
go-version: 1.21.x
|
||||
go-version: 1.22.x
|
||||
|
||||
- name: github sha short
|
||||
id: vars
|
||||
|
||||
@@ -24,10 +24,7 @@ if [ ! -f ./mc ]; then
|
||||
chmod +x mc
|
||||
fi
|
||||
|
||||
(
|
||||
cd ./docs/debugging/s3-check-md5
|
||||
go install -v
|
||||
)
|
||||
go install -v github.com/minio/minio/docs/debugging/s3-check-md5@latest
|
||||
|
||||
export RELEASE=RELEASE.2023-08-29T23-07-35Z
|
||||
|
||||
@@ -109,6 +106,43 @@ if [ $failed_count_site2 -ne 0 ]; then
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# Add user group test
|
||||
./mc admin user add site1 site-replication-issue-user site-replication-issue-password
|
||||
./mc admin group add site1 site-replication-issue-group site-replication-issue-user
|
||||
|
||||
max_wait_attempts=30
|
||||
wait_interval=5
|
||||
|
||||
attempt=1
|
||||
while true; do
|
||||
diff <(./mc admin group info site1 site-replication-issue-group) <(./mc admin group info site2 site-replication-issue-group)
|
||||
|
||||
if [[ $? -eq 0 ]]; then
|
||||
echo "Outputs are consistent."
|
||||
break
|
||||
fi
|
||||
|
||||
remaining_attempts=$((max_wait_attempts - attempt))
|
||||
if ((attempt >= max_wait_attempts)); then
|
||||
echo "Outputs remain inconsistent after $max_wait_attempts attempts. Exiting with error."
|
||||
exit 1
|
||||
else
|
||||
echo "Outputs are inconsistent. Waiting for $wait_interval seconds (attempt $attempt/$max_wait_attempts)."
|
||||
sleep $wait_interval
|
||||
fi
|
||||
|
||||
((attempt++))
|
||||
done
|
||||
|
||||
status=$(./mc admin group info site1 site-replication-issue-group --json | jq .groupStatus | tr -d '"')
|
||||
|
||||
if [[ $status == "enabled" ]]; then
|
||||
echo "Success"
|
||||
else
|
||||
echo "Expected status: enabled, actual status: $status"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
cleanup
|
||||
|
||||
## change working directory
|
||||
|
||||
@@ -22,11 +22,11 @@ jobs:
|
||||
|
||||
strategy:
|
||||
matrix:
|
||||
go-version: [1.21.x]
|
||||
go-version: [1.22.x]
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: actions/setup-go@v3
|
||||
- uses: actions/checkout@v4
|
||||
- uses: actions/setup-go@v5
|
||||
with:
|
||||
go-version: ${{ matrix.go-version }}
|
||||
check-latest: true
|
||||
@@ -36,6 +36,12 @@ jobs:
|
||||
sudo sysctl net.ipv6.conf.default.disable_ipv6=0
|
||||
make test-decom
|
||||
|
||||
- name: Test ILM
|
||||
run: |
|
||||
sudo sysctl net.ipv6.conf.all.disable_ipv6=0
|
||||
sudo sysctl net.ipv6.conf.default.disable_ipv6=0
|
||||
make test-ilm
|
||||
|
||||
- name: Test Config File
|
||||
run: |
|
||||
sudo sysctl net.ipv6.conf.all.disable_ipv6=0
|
||||
|
||||
@@ -21,12 +21,12 @@ jobs:
|
||||
runs-on: ${{ matrix.os }}
|
||||
strategy:
|
||||
matrix:
|
||||
go-version: [1.21.x]
|
||||
go-version: [1.22.x]
|
||||
os: [ubuntu-latest]
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: actions/setup-go@v3
|
||||
- uses: actions/checkout@v4
|
||||
- uses: actions/setup-go@v5
|
||||
with:
|
||||
go-version: ${{ matrix.go-version }}
|
||||
check-latest: true
|
||||
|
||||
@@ -14,7 +14,7 @@ jobs:
|
||||
name: runner / shfmt
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: actions/checkout@v4
|
||||
- uses: luizm/action-sh-checker@master
|
||||
env:
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
---
|
||||
name: Test GitHub Action
|
||||
name: Spelling
|
||||
on: [pull_request]
|
||||
|
||||
jobs:
|
||||
|
||||
@@ -21,12 +21,12 @@ jobs:
|
||||
runs-on: ${{ matrix.os }}
|
||||
strategy:
|
||||
matrix:
|
||||
go-version: [1.21.x]
|
||||
go-version: [1.22.x]
|
||||
os: [ubuntu-latest]
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: actions/setup-go@v3
|
||||
- uses: actions/checkout@v4
|
||||
- uses: actions/setup-go@v5
|
||||
with:
|
||||
go-version: ${{ matrix.go-version }}
|
||||
check-latest: true
|
||||
|
||||
@@ -17,15 +17,15 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v3
|
||||
uses: actions/checkout@v4
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v3
|
||||
uses: actions/setup-go@v5
|
||||
with:
|
||||
go-version: 1.21.8
|
||||
go-version: 1.22.3
|
||||
check-latest: true
|
||||
- name: Get official govulncheck
|
||||
run: go install golang.org/x/vuln/cmd/govulncheck@latest
|
||||
shell: bash
|
||||
- name: Run govulncheck
|
||||
run: govulncheck ./...
|
||||
run: govulncheck -show verbose ./...
|
||||
shell: bash
|
||||
|
||||
+12
-5
@@ -12,20 +12,27 @@ extend-ignore-re = [
|
||||
"[0-9A-Za-z/+=]{64}",
|
||||
"ZXJuZXQxDjAMBgNVBA-some-junk-Q4wDAYDVQQLEwVNaW5pbzEOMAwGA1UEAxMF",
|
||||
"eyJmb28iOiJiYXIifQ",
|
||||
"eyJ0eXAiOiJKV1QiLCJhbGciOiJSUzI1NiJ9.*",
|
||||
"MIIDBTCCAe2gAwIBAgIQWHw7h.*",
|
||||
'http\.Header\{"X-Amz-Server-Side-Encryptio":',
|
||||
'sessionToken',
|
||||
"ZoEoZdLlzVbOlT9rbhD7ZN7TLyiYXSAlB79uGEge",
|
||||
]
|
||||
|
||||
[default.extend-words]
|
||||
"encrypter" = "encrypter"
|
||||
"kms" = "kms"
|
||||
"requestor" = "requestor"
|
||||
|
||||
[default.extend-identifiers]
|
||||
"bui" = "bui"
|
||||
"toi" = "toi"
|
||||
"ot" = "ot"
|
||||
"dm2nd" = "dm2nd"
|
||||
"HashiCorp" = "HashiCorp"
|
||||
|
||||
[type.go.extend-identifiers]
|
||||
"bui" = "bui"
|
||||
"dm2nd" = "dm2nd"
|
||||
"ot" = "ot"
|
||||
"ParseND" = "ParseND"
|
||||
"ParseNDStream" = "ParseNDStream"
|
||||
"pn" = "pn"
|
||||
"TestGetPartialObjectMisAligned" = "TestGetPartialObjectMisAligned"
|
||||
"thr" = "thr"
|
||||
"toi" = "toi"
|
||||
|
||||
@@ -21,6 +21,11 @@ RUN curl -s -q https://dl.min.io/client/mc/release/linux-${TARGETARCH}/mc -o /go
|
||||
curl -s -q https://dl.min.io/client/mc/release/linux-${TARGETARCH}/mc.minisig -o /go/bin/mc.minisig && \
|
||||
chmod +x /go/bin/mc
|
||||
|
||||
RUN if [ "$TARGETARCH" = "amd64" ]; then \
|
||||
curl -L -s -q https://github.com/moparisthebest/static-curl/releases/latest/download/curl-${TARGETARCH} -o /go/bin/curl; \
|
||||
chmod +x /go/bin/curl; \
|
||||
fi
|
||||
|
||||
# Verify binary signature using public key "RWTx5Zr1tiHQLwG9keckT0c45M3AGeHD6IvimQHpyRywVWGbP1aVSGavRUN"
|
||||
RUN minisign -Vqm /go/bin/minio -x /go/bin/minio.minisig -P RWTx5Zr1tiHQLwG9keckT0c45M3AGeHD6IvimQHpyRywVWGbP1aVSGav && \
|
||||
minisign -Vqm /go/bin/mc -x /go/bin/mc.minisig -P RWTx5Zr1tiHQLwG9keckT0c45M3AGeHD6IvimQHpyRywVWGbP1aVSGav
|
||||
@@ -49,6 +54,7 @@ ENV MINIO_ACCESS_KEY_FILE=access_key \
|
||||
COPY --from=build /etc/ssl/certs/ca-certificates.crt /etc/ssl/certs/
|
||||
COPY --from=build /go/bin/minio /usr/bin/minio
|
||||
COPY --from=build /go/bin/mc /usr/bin/mc
|
||||
COPY --from=build /go/bin/cur* /usr/bin/
|
||||
|
||||
COPY CREDITS /licenses/CREDITS
|
||||
COPY LICENSE /licenses/LICENSE
|
||||
|
||||
@@ -16,6 +16,11 @@ RUN curl -s -q https://dl.min.io/server/minio/release/linux-${TARGETARCH}/archiv
|
||||
curl -s -q https://dl.min.io/server/minio/release/linux-${TARGETARCH}/archive/minio.${RELEASE}.fips.minisig -o /go/bin/minio.minisig && \
|
||||
chmod +x /go/bin/minio
|
||||
|
||||
RUN if [ "$TARGETARCH" = "amd64" ]; then \
|
||||
curl -L -s -q https://github.com/moparisthebest/static-curl/releases/latest/download/curl-${TARGETARCH} -o /go/bin/curl; \
|
||||
chmod +x /go/bin/curl; \
|
||||
fi
|
||||
|
||||
# Verify binary signature using public key "RWTx5Zr1tiHQLwG9keckT0c45M3AGeHD6IvimQHpyRywVWGbP1aVSGavRUN"
|
||||
RUN minisign -Vqm /go/bin/minio -x /go/bin/minio.minisig -P RWTx5Zr1tiHQLwG9keckT0c45M3AGeHD6IvimQHpyRywVWGbP1aVSGav
|
||||
|
||||
@@ -41,6 +46,7 @@ ENV MINIO_ACCESS_KEY_FILE=access_key \
|
||||
|
||||
COPY --from=build /etc/ssl/certs/ca-certificates.crt /etc/ssl/certs/
|
||||
COPY --from=build /go/bin/minio /usr/bin/minio
|
||||
COPY --from=build /go/bin/cur* /usr/bin/
|
||||
|
||||
COPY CREDITS /licenses/CREDITS
|
||||
COPY LICENSE /licenses/LICENSE
|
||||
|
||||
@@ -21,6 +21,11 @@ RUN curl -s -q https://dl.min.io/client/mc/release/linux-${TARGETARCH}/mc -o /go
|
||||
curl -s -q https://dl.min.io/client/mc/release/linux-${TARGETARCH}/mc.minisig -o /go/bin/mc.minisig && \
|
||||
chmod +x /go/bin/mc
|
||||
|
||||
RUN if [ "$TARGETARCH" = "amd64" ]; then \
|
||||
curl -L -s -q https://github.com/moparisthebest/static-curl/releases/latest/download/curl-${TARGETARCH} -o /go/bin/curl; \
|
||||
chmod +x /go/bin/curl; \
|
||||
fi
|
||||
|
||||
# Verify binary signature using public key "RWTx5Zr1tiHQLwG9keckT0c45M3AGeHD6IvimQHpyRywVWGbP1aVSGavRUN"
|
||||
RUN minisign -Vqm /go/bin/minio -x /go/bin/minio.minisig -P RWTx5Zr1tiHQLwG9keckT0c45M3AGeHD6IvimQHpyRywVWGbP1aVSGav && \
|
||||
minisign -Vqm /go/bin/mc -x /go/bin/mc.minisig -P RWTx5Zr1tiHQLwG9keckT0c45M3AGeHD6IvimQHpyRywVWGbP1aVSGav
|
||||
@@ -49,6 +54,7 @@ ENV MINIO_ACCESS_KEY_FILE=access_key \
|
||||
COPY --from=build /etc/ssl/certs/ca-certificates.crt /etc/ssl/certs/
|
||||
COPY --from=build /go/bin/minio /usr/bin/minio
|
||||
COPY --from=build /go/bin/mc /usr/bin/mc
|
||||
COPY --from=build /go/bin/cur* /usr/bin/
|
||||
|
||||
COPY CREDITS /licenses/CREDITS
|
||||
COPY LICENSE /licenses/LICENSE
|
||||
|
||||
@@ -53,6 +53,10 @@ test-root-disable: install-race
|
||||
@echo "Running minio root lockdown tests"
|
||||
@env bash $(PWD)/buildscripts/disable-root.sh
|
||||
|
||||
test-ilm: install-race
|
||||
@echo "Running ILM tests"
|
||||
@env bash $(PWD)/docs/bucket/replication/setup_ilm_expiry_replication.sh
|
||||
|
||||
test-decom: install-race
|
||||
@echo "Running minio decom tests"
|
||||
@env bash $(PWD)/docs/distributed/decom.sh
|
||||
@@ -81,6 +85,10 @@ test-iam: build ## verify IAM (external IDP, etcd backends)
|
||||
@echo "Running tests for IAM (external IDP, etcd backends) with -race"
|
||||
@MINIO_API_REQUESTS_MAX=10000 GORACE=history_size=7 CGO_ENABLED=1 go test -race -tags kqueue -v -run TestIAM* ./cmd
|
||||
|
||||
test-iam-ldap-upgrade-import: build ## verify IAM (external LDAP IDP)
|
||||
@echo "Running upgrade tests for IAM (LDAP backend)"
|
||||
@env bash $(PWD)/buildscripts/minio-iam-ldap-upgrade-import-test.sh
|
||||
|
||||
test-sio-error:
|
||||
@(env bash $(PWD)/docs/bucket/replication/sio-error.sh)
|
||||
|
||||
@@ -107,6 +115,12 @@ test-site-replication-oidc: install-race ## verify automatic site replication
|
||||
test-site-replication-minio: install-race ## verify automatic site replication
|
||||
@echo "Running tests for automatic site replication of IAM (with MinIO IDP)"
|
||||
@(env bash $(PWD)/docs/site-replication/run-multi-site-minio-idp.sh)
|
||||
@echo "Running tests for automatic site replication of SSE-C objects"
|
||||
@(env bash $(PWD)/docs/site-replication/run-ssec-object-replication.sh)
|
||||
@echo "Running tests for automatic site replication of SSE-C objects with SSE-KMS enabled for bucket"
|
||||
@(env bash $(PWD)/docs/site-replication/run-sse-kms-object-replication.sh)
|
||||
@echo "Running tests for automatic site replication of SSE-C objects with compression enabled for site"
|
||||
@(env bash $(PWD)/docs/site-replication/run-ssec-object-replication-with-compression.sh)
|
||||
|
||||
verify: ## verify minio various setups
|
||||
@echo "Verifying build with race"
|
||||
@@ -117,6 +131,7 @@ verify-healing: ## verify healing and replacing disks with minio binary
|
||||
@echo "Verify healing build with race"
|
||||
@GORACE=history_size=7 CGO_ENABLED=1 go build -race -tags kqueue -trimpath --ldflags "$(LDFLAGS)" -o $(PWD)/minio 1>/dev/null
|
||||
@(env bash $(PWD)/buildscripts/verify-healing.sh)
|
||||
@(env bash $(PWD)/buildscripts/verify-healing-empty-erasure-set.sh)
|
||||
@(env bash $(PWD)/buildscripts/heal-inconsistent-versions.sh)
|
||||
|
||||
verify-healing-with-root-disks: ## verify healing root disks
|
||||
@@ -147,9 +162,9 @@ hotfix-vars:
|
||||
$(eval VERSION := $(shell git describe --tags --abbrev=0).hotfix.$(shell git rev-parse --short HEAD))
|
||||
|
||||
hotfix: hotfix-vars clean install ## builds minio binary with hotfix tags
|
||||
@wget -q -c https://github.com/minio/pkger/releases/download/v2.2.1/pkger_2.2.1_linux_amd64.deb
|
||||
@wget -q -c https://github.com/minio/pkger/releases/download/v2.2.9/pkger_2.2.9_linux_amd64.deb
|
||||
@wget -q -c https://raw.githubusercontent.com/minio/minio-service/v1.0.1/linux-systemd/distributed/minio.service
|
||||
@sudo apt install ./pkger_2.2.1_linux_amd64.deb --yes
|
||||
@sudo apt install ./pkger_2.2.9_linux_amd64.deb --yes
|
||||
@mkdir -p minio-release/$(GOOS)-$(GOARCH)/archive
|
||||
@cp -af ./minio minio-release/$(GOOS)-$(GOARCH)/minio
|
||||
@cp -af ./minio minio-release/$(GOOS)-$(GOARCH)/minio.$(VERSION)
|
||||
|
||||
@@ -210,10 +210,6 @@ For deployments behind a load balancer, proxy, or ingress rule where the MinIO h
|
||||
|
||||
For example, consider a MinIO deployment behind a proxy `https://minio.example.net`, `https://console.minio.example.net` with rules for forwarding traffic on port :9000 and :9001 to MinIO and the MinIO Console respectively on the internal network. Set `MINIO_BROWSER_REDIRECT_URL` to `https://console.minio.example.net` to ensure the browser receives a valid reachable URL.
|
||||
|
||||
Similarly, if your TLS certificates do not have the IP SAN for the MinIO server host, the MinIO Console may fail to validate the connection to the server. Use the `MINIO_SERVER_URL` environment variable and specify the proxy-accessible hostname of the MinIO server to allow the Console to use the MinIO server API using the TLS certificate.
|
||||
|
||||
For example: `export MINIO_SERVER_URL="https://minio.example.net"`
|
||||
|
||||
| Dashboard | Creating a bucket |
|
||||
| ------------- | ------------- |
|
||||
| 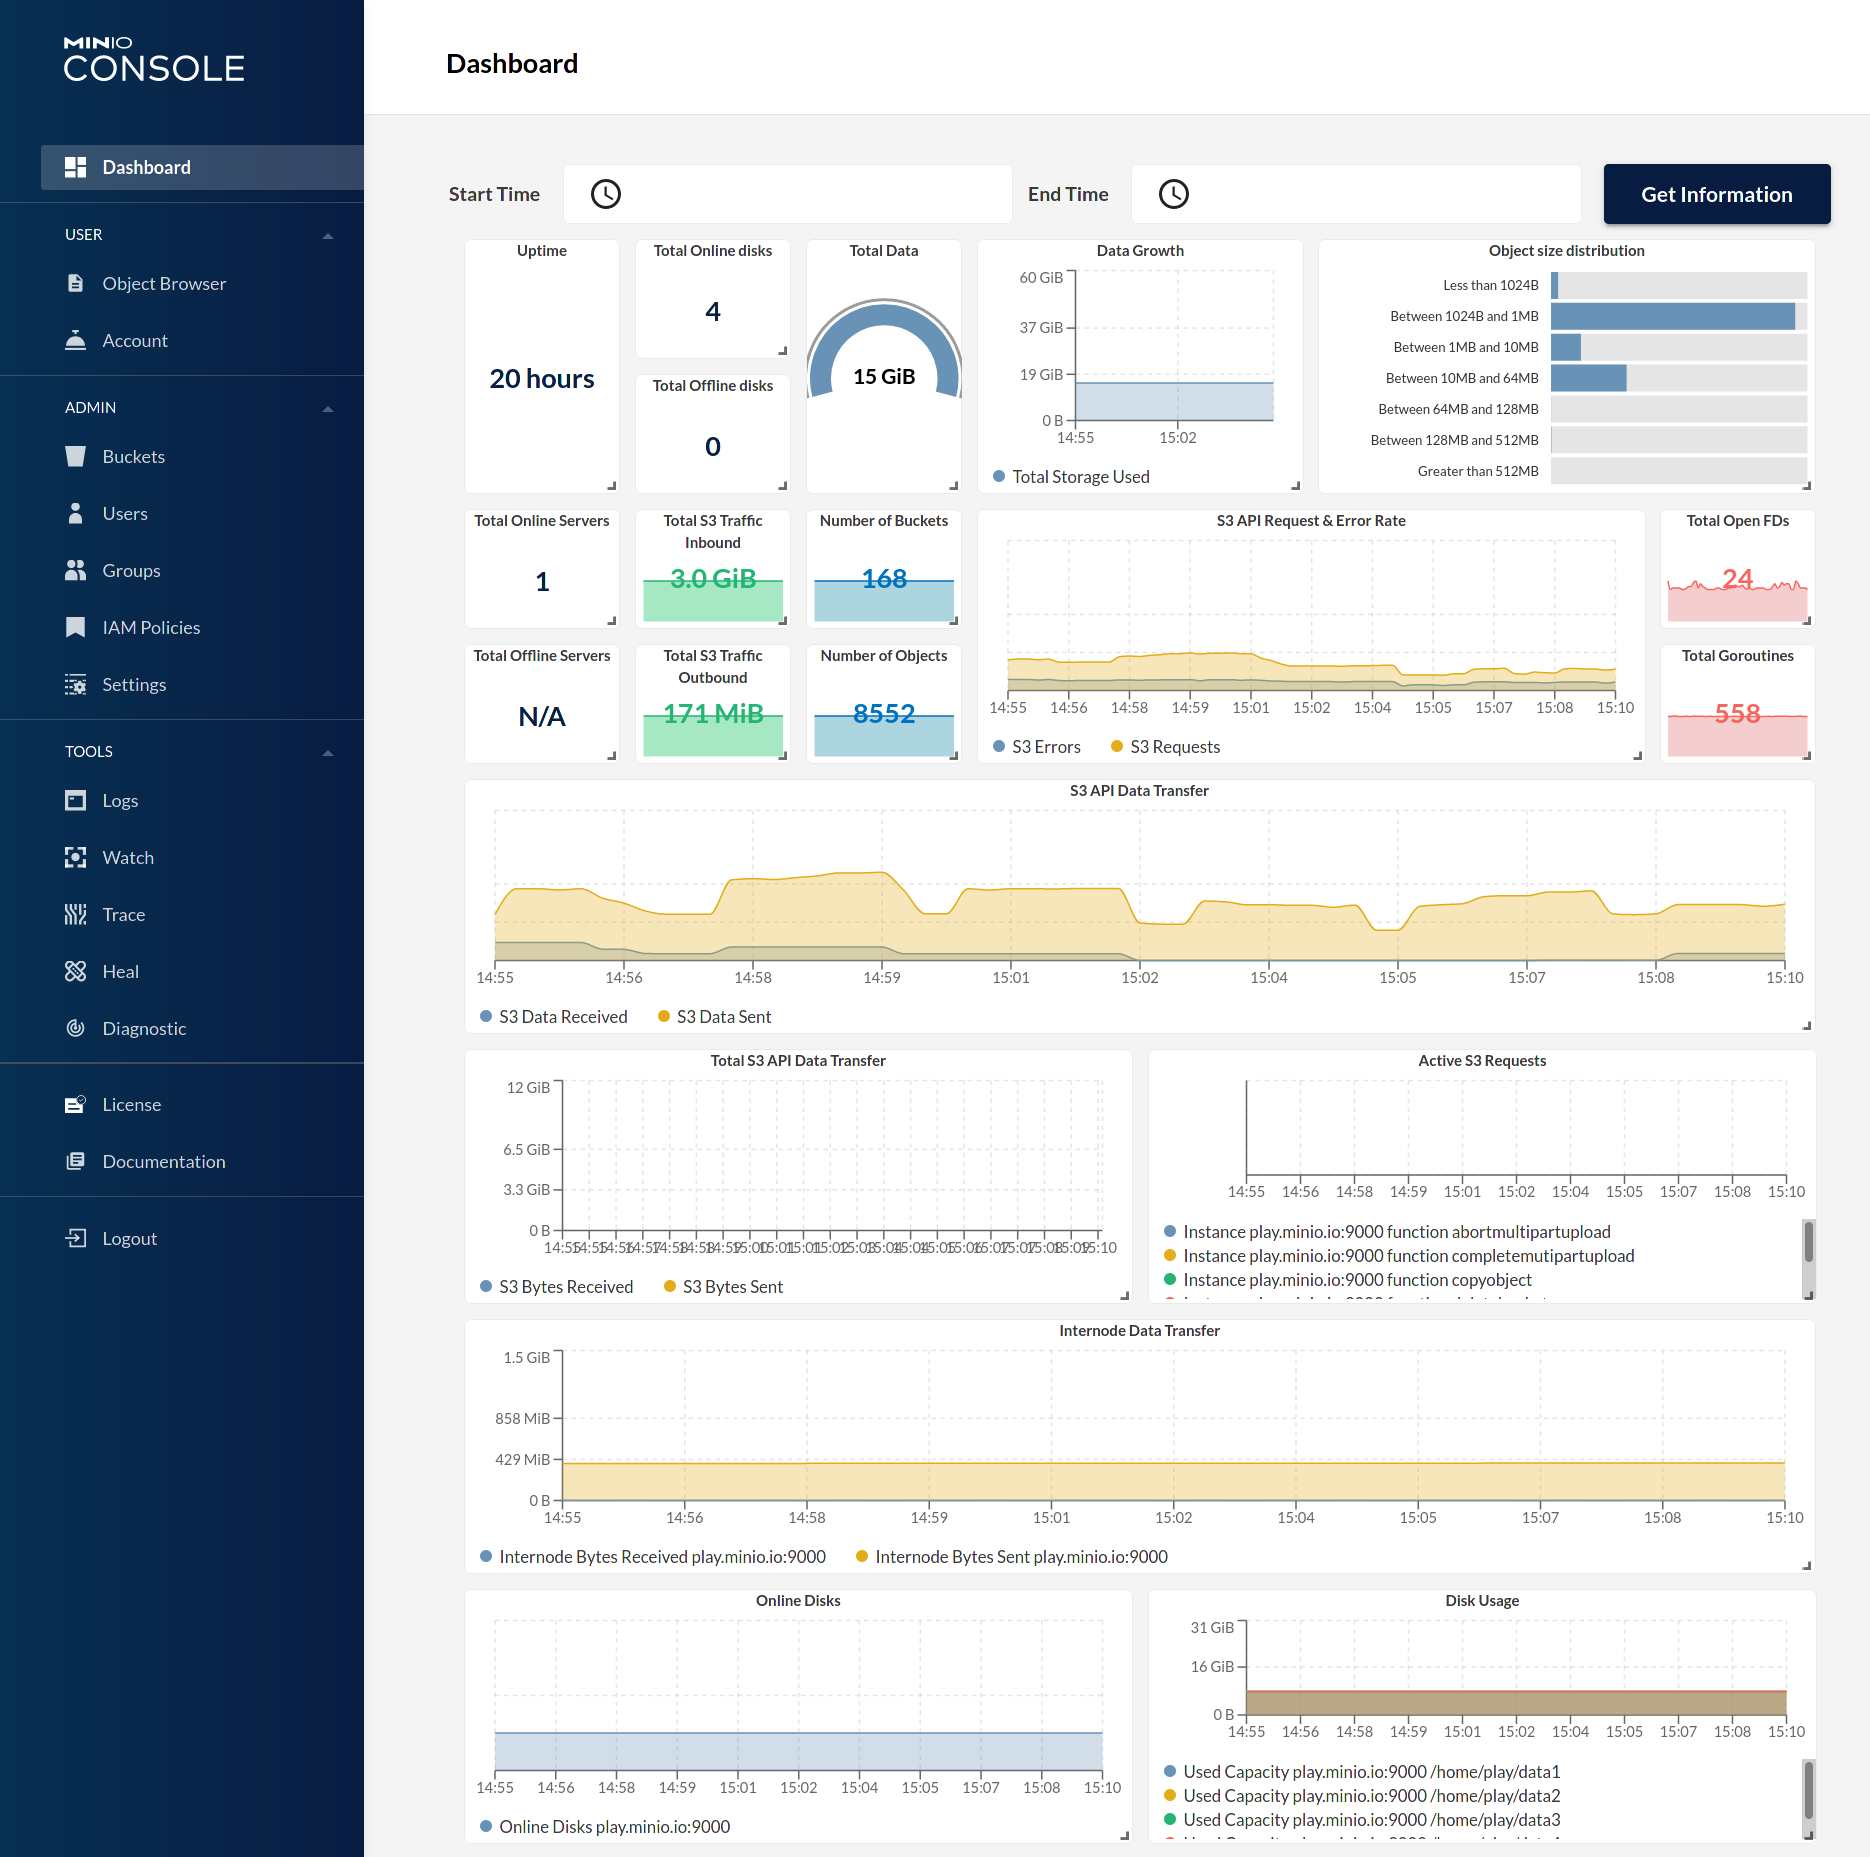 | 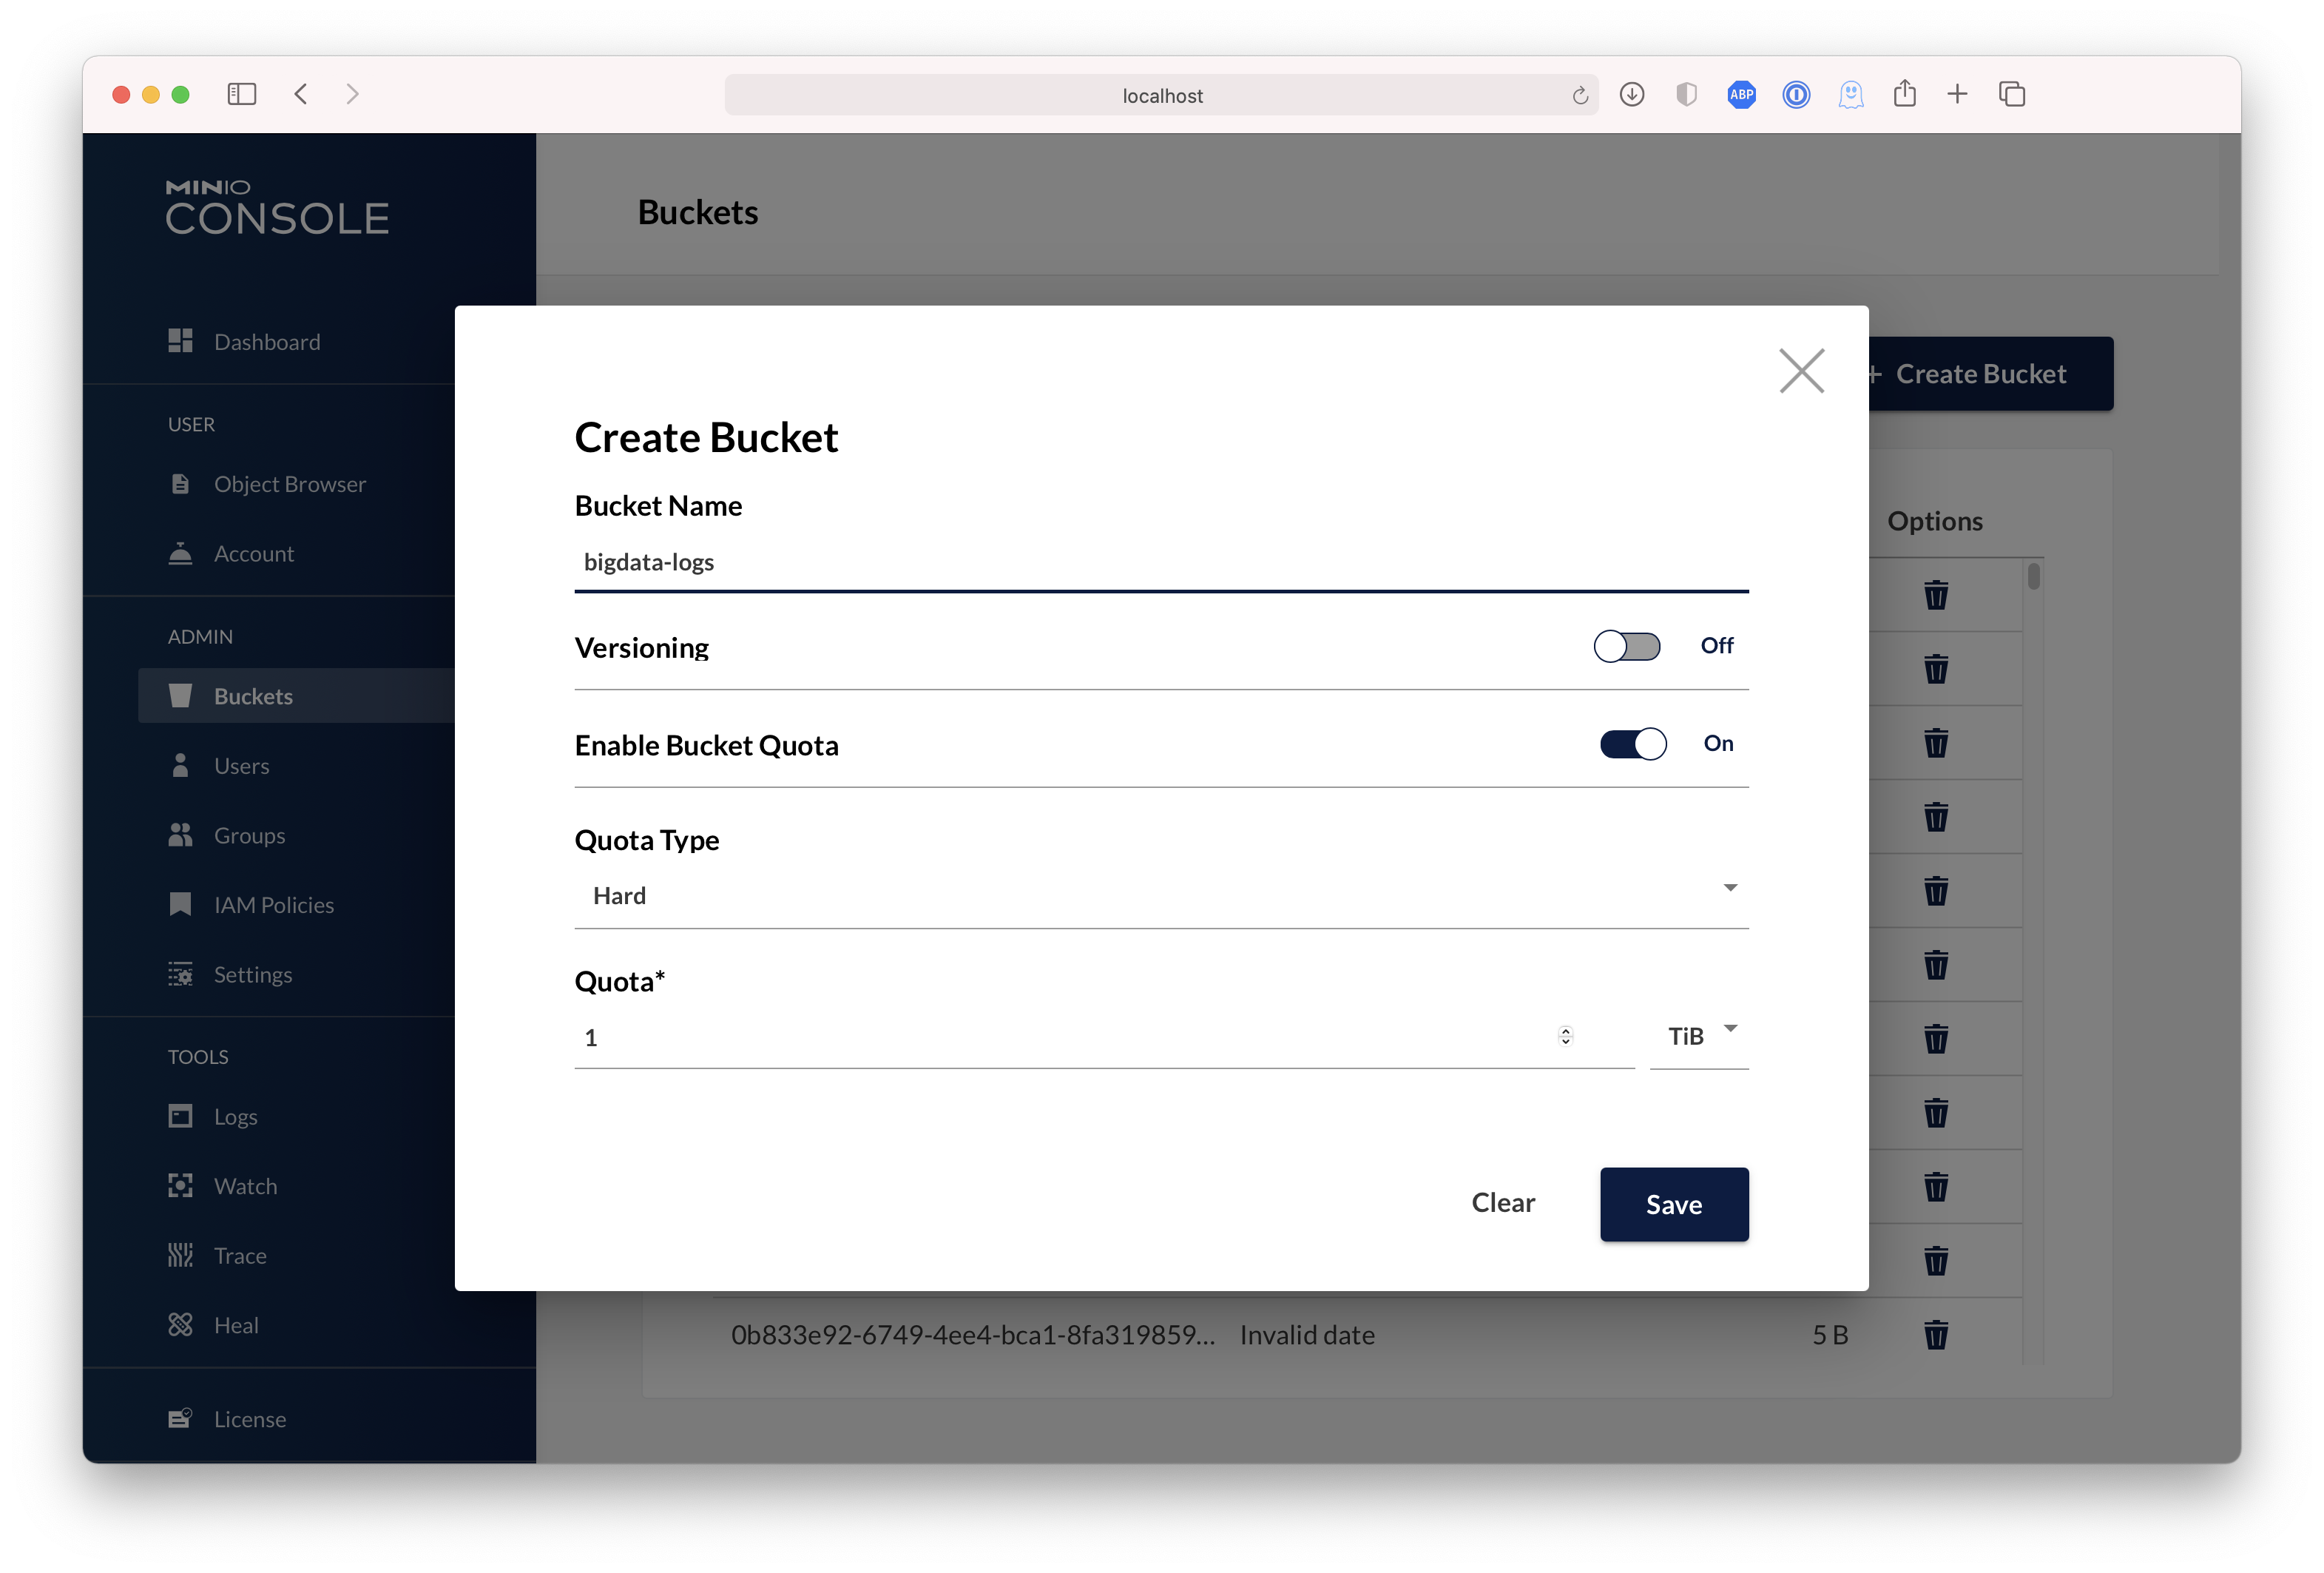 |
|
||||
|
||||
+125
@@ -0,0 +1,125 @@
|
||||
#!/bin/bash
|
||||
|
||||
# This script is used to test the migration of IAM content from old minio
|
||||
# instance to new minio instance.
|
||||
#
|
||||
# To run it locally, start the LDAP server in github.com/minio/minio-iam-testing
|
||||
# repo (e.g. make podman-run), and then run this script.
|
||||
#
|
||||
# This script assumes that LDAP server is at:
|
||||
#
|
||||
# `localhost:1389`
|
||||
#
|
||||
# if this is not the case, set the environment variable
|
||||
# `_MINIO_LDAP_TEST_SERVER`.
|
||||
|
||||
OLD_VERSION=RELEASE.2024-03-26T22-10-45Z
|
||||
OLD_BINARY_LINK=https://dl.min.io/server/minio/release/linux-amd64/archive/minio.${OLD_VERSION}
|
||||
|
||||
__init__() {
|
||||
if which curl &>/dev/null; then
|
||||
echo "curl is already installed"
|
||||
else
|
||||
echo "Installing curl:"
|
||||
sudo apt install curl -y
|
||||
fi
|
||||
|
||||
export GOPATH=/tmp/gopath
|
||||
export PATH="${PATH}":"${GOPATH}"/bin
|
||||
|
||||
if which mc &>/dev/null; then
|
||||
echo "mc is already installed"
|
||||
else
|
||||
echo "Installing mc:"
|
||||
go install github.com/minio/mc@latest
|
||||
fi
|
||||
|
||||
if [ ! -x ./minio.${OLD_VERSION} ]; then
|
||||
echo "Downloading minio.${OLD_VERSION} binary"
|
||||
curl -o minio.${OLD_VERSION} ${OLD_BINARY_LINK}
|
||||
chmod +x minio.${OLD_VERSION}
|
||||
fi
|
||||
|
||||
if [ -z "$_MINIO_LDAP_TEST_SERVER" ]; then
|
||||
export _MINIO_LDAP_TEST_SERVER=localhost:1389
|
||||
echo "Using default LDAP endpoint: $_MINIO_LDAP_TEST_SERVER"
|
||||
fi
|
||||
|
||||
rm -rf /tmp/data
|
||||
}
|
||||
|
||||
create_iam_content_in_old_minio() {
|
||||
echo "Creating IAM content in old minio instance."
|
||||
|
||||
MINIO_CI_CD=1 ./minio.${OLD_VERSION} server /tmp/data/{1...4} &
|
||||
sleep 5
|
||||
|
||||
set -x
|
||||
mc alias set old-minio http://localhost:9000 minioadmin minioadmin
|
||||
mc idp ldap add old-minio \
|
||||
server_addr=localhost:1389 \
|
||||
server_insecure=on \
|
||||
lookup_bind_dn=cn=admin,dc=min,dc=io \
|
||||
lookup_bind_password=admin \
|
||||
user_dn_search_base_dn=dc=min,dc=io \
|
||||
user_dn_search_filter="(uid=%s)" \
|
||||
group_search_base_dn=ou=swengg,dc=min,dc=io \
|
||||
group_search_filter="(&(objectclass=groupOfNames)(member=%d))"
|
||||
mc admin service restart old-minio
|
||||
|
||||
mc idp ldap policy attach old-minio readwrite --user=UID=dillon,ou=people,ou=swengg,dc=min,dc=io
|
||||
mc idp ldap policy attach old-minio readwrite --group=CN=project.c,ou=groups,ou=swengg,dc=min,dc=io
|
||||
|
||||
mc idp ldap policy entities old-minio
|
||||
|
||||
mc admin cluster iam export old-minio
|
||||
set +x
|
||||
|
||||
mc admin service stop old-minio
|
||||
}
|
||||
|
||||
import_iam_content_in_new_minio() {
|
||||
echo "Importing IAM content in new minio instance."
|
||||
# Assume current minio binary exists.
|
||||
MINIO_CI_CD=1 ./minio server /tmp/data/{1...4} &
|
||||
sleep 5
|
||||
|
||||
set -x
|
||||
mc alias set new-minio http://localhost:9000 minioadmin minioadmin
|
||||
echo "BEFORE IMPORT mappings:"
|
||||
mc idp ldap policy entities new-minio
|
||||
mc admin cluster iam import new-minio ./old-minio-iam-info.zip
|
||||
echo "AFTER IMPORT mappings:"
|
||||
mc idp ldap policy entities new-minio
|
||||
set +x
|
||||
|
||||
# mc admin service stop new-minio
|
||||
}
|
||||
|
||||
verify_iam_content_in_new_minio() {
|
||||
output=$(mc idp ldap policy entities new-minio --json)
|
||||
|
||||
groups=$(echo "$output" | jq -r '.result.policyMappings[] | select(.policy == "readwrite") | .groups[]')
|
||||
if [ "$groups" != "cn=project.c,ou=groups,ou=swengg,dc=min,dc=io" ]; then
|
||||
echo "Failed to verify groups: $groups"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
users=$(echo "$output" | jq -r '.result.policyMappings[] | select(.policy == "readwrite") | .users[]')
|
||||
if [ "$users" != "uid=dillon,ou=people,ou=swengg,dc=min,dc=io" ]; then
|
||||
echo "Failed to verify users: $users"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
mc admin service stop new-minio
|
||||
}
|
||||
|
||||
main() {
|
||||
create_iam_content_in_old_minio
|
||||
|
||||
import_iam_content_in_new_minio
|
||||
|
||||
verify_iam_content_in_new_minio
|
||||
}
|
||||
|
||||
(__init__ "$@" && main "$@")
|
||||
@@ -55,6 +55,11 @@ __init__() {
|
||||
|
||||
go install github.com/minio/mc@latest
|
||||
|
||||
## this is needed because github actions don't have
|
||||
## docker-compose on all runners
|
||||
go install github.com/docker/compose/v2/cmd@latest
|
||||
mv -v /tmp/gopath/bin/cmd /tmp/gopath/bin/docker-compose
|
||||
|
||||
TAG=minio/minio:dev make docker
|
||||
|
||||
MINIO_VERSION=RELEASE.2019-12-19T22-52-26Z docker-compose \
|
||||
|
||||
@@ -87,10 +87,7 @@ function verify_rewrite() {
|
||||
exit 1
|
||||
fi
|
||||
|
||||
(
|
||||
cd ./docs/debugging/s3-check-md5
|
||||
go install -v
|
||||
)
|
||||
go install -v github.com/minio/minio/docs/debugging/s3-check-md5@latest
|
||||
|
||||
if ! s3-check-md5 \
|
||||
-debug \
|
||||
|
||||
+140
@@ -0,0 +1,140 @@
|
||||
#!/bin/bash -e
|
||||
#
|
||||
|
||||
set -E
|
||||
set -o pipefail
|
||||
|
||||
if [ ! -x "$PWD/minio" ]; then
|
||||
echo "minio executable binary not found in current directory"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
WORK_DIR="$PWD/.verify-$RANDOM"
|
||||
MINIO_CONFIG_DIR="$WORK_DIR/.minio"
|
||||
MINIO=("$PWD/minio" --config-dir "$MINIO_CONFIG_DIR" server)
|
||||
|
||||
function start_minio_3_node() {
|
||||
export MINIO_ROOT_USER=minio
|
||||
export MINIO_ROOT_PASSWORD=minio123
|
||||
export MINIO_ERASURE_SET_DRIVE_COUNT=6
|
||||
export MINIO_CI_CD=1
|
||||
|
||||
start_port=$2
|
||||
args=""
|
||||
for i in $(seq 1 3); do
|
||||
args="$args http://127.0.0.1:$((start_port + i))${WORK_DIR}/$i/1/ http://127.0.0.1:$((start_port + i))${WORK_DIR}/$i/2/ http://127.0.0.1:$((start_port + i))${WORK_DIR}/$i/3/ http://127.0.0.1:$((start_port + i))${WORK_DIR}/$i/4/ http://127.0.0.1:$((start_port + i))${WORK_DIR}/$i/5/ http://127.0.0.1:$((start_port + i))${WORK_DIR}/$i/6/"
|
||||
done
|
||||
|
||||
"${MINIO[@]}" --address ":$((start_port + 1))" $args >"${WORK_DIR}/dist-minio-server1.log" 2>&1 &
|
||||
pid1=$!
|
||||
disown ${pid1}
|
||||
|
||||
"${MINIO[@]}" --address ":$((start_port + 2))" $args >"${WORK_DIR}/dist-minio-server2.log" 2>&1 &
|
||||
pid2=$!
|
||||
disown $pid2
|
||||
|
||||
"${MINIO[@]}" --address ":$((start_port + 3))" $args >"${WORK_DIR}/dist-minio-server3.log" 2>&1 &
|
||||
pid3=$!
|
||||
disown $pid3
|
||||
|
||||
sleep "$1"
|
||||
|
||||
if ! ps -p $pid1 1>&2 >/dev/null; then
|
||||
echo "server1 log:"
|
||||
cat "${WORK_DIR}/dist-minio-server1.log"
|
||||
echo "FAILED"
|
||||
purge "$WORK_DIR"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
if ! ps -p $pid2 1>&2 >/dev/null; then
|
||||
echo "server2 log:"
|
||||
cat "${WORK_DIR}/dist-minio-server2.log"
|
||||
echo "FAILED"
|
||||
purge "$WORK_DIR"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
if ! ps -p $pid3 1>&2 >/dev/null; then
|
||||
echo "server3 log:"
|
||||
cat "${WORK_DIR}/dist-minio-server3.log"
|
||||
echo "FAILED"
|
||||
purge "$WORK_DIR"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
if ! pkill minio; then
|
||||
for i in $(seq 1 3); do
|
||||
echo "server$i log:"
|
||||
cat "${WORK_DIR}/dist-minio-server$i.log"
|
||||
done
|
||||
echo "FAILED"
|
||||
purge "$WORK_DIR"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
sleep 1
|
||||
if pgrep minio; then
|
||||
# forcibly killing, to proceed further properly.
|
||||
if ! pkill -9 minio; then
|
||||
echo "no minio process running anymore, proceed."
|
||||
fi
|
||||
fi
|
||||
}
|
||||
|
||||
function check_online() {
|
||||
if ! grep -q 'Status:' ${WORK_DIR}/dist-minio-*.log; then
|
||||
echo "1"
|
||||
fi
|
||||
}
|
||||
|
||||
function purge() {
|
||||
rm -rf "$1"
|
||||
}
|
||||
|
||||
function __init__() {
|
||||
echo "Initializing environment"
|
||||
mkdir -p "$WORK_DIR"
|
||||
mkdir -p "$MINIO_CONFIG_DIR"
|
||||
|
||||
## version is purposefully set to '3' for minio to migrate configuration file
|
||||
echo '{"version": "3", "credential": {"accessKey": "minio", "secretKey": "minio123"}, "region": "us-east-1"}' >"$MINIO_CONFIG_DIR/config.json"
|
||||
}
|
||||
|
||||
function perform_test() {
|
||||
start_minio_3_node 120 $2
|
||||
|
||||
echo "Testing Distributed Erasure setup healing of drives"
|
||||
echo "Remove the contents of the disks belonging to '${1}' erasure set"
|
||||
|
||||
rm -rf ${WORK_DIR}/${1}/*/
|
||||
|
||||
set -x
|
||||
start_minio_3_node 120 $2
|
||||
|
||||
rv=$(check_online)
|
||||
if [ "$rv" == "1" ]; then
|
||||
for i in $(seq 1 3); do
|
||||
echo "server$i log:"
|
||||
cat "${WORK_DIR}/dist-minio-server$i.log"
|
||||
done
|
||||
pkill -9 minio
|
||||
echo "FAILED"
|
||||
purge "$WORK_DIR"
|
||||
exit 1
|
||||
fi
|
||||
}
|
||||
|
||||
function main() {
|
||||
# use same ports for all tests
|
||||
start_port=$(shuf -i 10000-65000 -n 1)
|
||||
|
||||
perform_test "2" ${start_port}
|
||||
perform_test "1" ${start_port}
|
||||
perform_test "3" ${start_port}
|
||||
}
|
||||
|
||||
(__init__ "$@" && main "$@")
|
||||
rv=$?
|
||||
purge "$WORK_DIR"
|
||||
exit "$rv"
|
||||
@@ -12,6 +12,7 @@ fi
|
||||
WORK_DIR="$PWD/.verify-$RANDOM"
|
||||
MINIO_CONFIG_DIR="$WORK_DIR/.minio"
|
||||
MINIO=("$PWD/minio" --config-dir "$MINIO_CONFIG_DIR" server)
|
||||
GOPATH=/tmp/gopath
|
||||
|
||||
function start_minio_3_node() {
|
||||
export MINIO_ROOT_USER=minio
|
||||
@@ -19,10 +20,14 @@ function start_minio_3_node() {
|
||||
export MINIO_ERASURE_SET_DRIVE_COUNT=6
|
||||
export MINIO_CI_CD=1
|
||||
|
||||
first_time=$(find ${WORK_DIR}/ | grep format.json | wc -l)
|
||||
|
||||
start_port=$2
|
||||
args=""
|
||||
for i in $(seq 1 3); do
|
||||
args="$args http://127.0.0.1:$((start_port + i))${WORK_DIR}/$i/1/ http://127.0.0.1:$((start_port + i))${WORK_DIR}/$i/2/ http://127.0.0.1:$((start_port + i))${WORK_DIR}/$i/3/ http://127.0.0.1:$((start_port + i))${WORK_DIR}/$i/4/ http://127.0.0.1:$((start_port + i))${WORK_DIR}/$i/5/ http://127.0.0.1:$((start_port + i))${WORK_DIR}/$i/6/"
|
||||
for d in $(seq 1 3 5); do
|
||||
args="$args http://127.0.0.1:$((start_port + 1))${WORK_DIR}/1/${d}/ http://127.0.0.1:$((start_port + 2))${WORK_DIR}/2/${d}/ http://127.0.0.1:$((start_port + 3))${WORK_DIR}/3/${d}/ "
|
||||
d=$((d + 1))
|
||||
args="$args http://127.0.0.1:$((start_port + 1))${WORK_DIR}/1/${d}/ http://127.0.0.1:$((start_port + 2))${WORK_DIR}/2/${d}/ http://127.0.0.1:$((start_port + 3))${WORK_DIR}/3/${d}/ "
|
||||
done
|
||||
|
||||
"${MINIO[@]}" --address ":$((start_port + 1))" $args >"${WORK_DIR}/dist-minio-server1.log" 2>&1 &
|
||||
@@ -39,6 +44,8 @@ function start_minio_3_node() {
|
||||
|
||||
sleep "$1"
|
||||
|
||||
[ ${first_time} -eq 0 ] && upload_objects $start_port
|
||||
|
||||
if ! ps -p $pid1 1>&2 >/dev/null; then
|
||||
echo "server1 log:"
|
||||
cat "${WORK_DIR}/dist-minio-server1.log"
|
||||
@@ -82,10 +89,23 @@ function start_minio_3_node() {
|
||||
fi
|
||||
}
|
||||
|
||||
function check_online() {
|
||||
function check_heal() {
|
||||
if ! grep -q 'Status:' ${WORK_DIR}/dist-minio-*.log; then
|
||||
echo "1"
|
||||
return 1
|
||||
fi
|
||||
|
||||
for ((i = 0; i < 20; i++)); do
|
||||
test -f ${WORK_DIR}/$1/1/.minio.sys/format.json
|
||||
v1=$?
|
||||
nextInES=$(($1 + 1)) && [ $nextInES -gt 3 ] && nextInES=1
|
||||
foundFiles1=$(find ${WORK_DIR}/$1/1/ | grep -v .minio.sys | grep xl.meta | wc -l)
|
||||
foundFiles2=$(find ${WORK_DIR}/$nextInES/1/ | grep -v .minio.sys | grep xl.meta | wc -l)
|
||||
test $foundFiles1 -eq $foundFiles2
|
||||
v2=$?
|
||||
[ $v1 == 0 -a $v2 == 0 ] && return 0
|
||||
sleep 10
|
||||
done
|
||||
return 1
|
||||
}
|
||||
|
||||
function purge() {
|
||||
@@ -99,20 +119,39 @@ function __init__() {
|
||||
|
||||
## version is purposefully set to '3' for minio to migrate configuration file
|
||||
echo '{"version": "3", "credential": {"accessKey": "minio", "secretKey": "minio123"}, "region": "us-east-1"}' >"$MINIO_CONFIG_DIR/config.json"
|
||||
|
||||
if [ ! -f /tmp/mc ]; then
|
||||
wget --quiet -O /tmp/mc https://dl.minio.io/client/mc/release/linux-amd64/mc &&
|
||||
chmod +x /tmp/mc
|
||||
fi
|
||||
}
|
||||
|
||||
function upload_objects() {
|
||||
start_port=$1
|
||||
|
||||
/tmp/mc alias set myminio http://127.0.0.1:$((start_port + 1)) minio minio123 --api=s3v4
|
||||
/tmp/mc ready myminio
|
||||
/tmp/mc mb myminio/testbucket/
|
||||
for ((i = 0; i < 20; i++)); do
|
||||
echo "my content" | /tmp/mc pipe myminio/testbucket/file-$i
|
||||
done
|
||||
}
|
||||
|
||||
function perform_test() {
|
||||
start_minio_3_node 120 $2
|
||||
start_port=$2
|
||||
|
||||
start_minio_3_node 120 $start_port
|
||||
|
||||
echo "Testing Distributed Erasure setup healing of drives"
|
||||
echo "Remove the contents of the disks belonging to '${1}' erasure set"
|
||||
echo "Remove the contents of the disks belonging to '${1}' node"
|
||||
|
||||
rm -rf ${WORK_DIR}/${1}/*/
|
||||
|
||||
set -x
|
||||
start_minio_3_node 120 $2
|
||||
start_minio_3_node 120 $start_port
|
||||
|
||||
rv=$(check_online)
|
||||
check_heal ${1}
|
||||
rv=$?
|
||||
if [ "$rv" == "1" ]; then
|
||||
for i in $(seq 1 3); do
|
||||
echo "server$i log:"
|
||||
|
||||
@@ -39,7 +39,6 @@ import (
|
||||
"github.com/minio/minio/internal/bucket/versioning"
|
||||
"github.com/minio/minio/internal/event"
|
||||
"github.com/minio/minio/internal/kms"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/mux"
|
||||
"github.com/minio/pkg/v2/policy"
|
||||
)
|
||||
@@ -99,7 +98,7 @@ func (a adminAPIHandlers) PutBucketQuotaConfigHandler(w http.ResponseWriter, r *
|
||||
}
|
||||
|
||||
// Call site replication hook.
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, bucketMeta))
|
||||
replLogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, bucketMeta))
|
||||
|
||||
// Write success response.
|
||||
writeSuccessResponseHeadersOnly(w)
|
||||
@@ -431,7 +430,7 @@ func (a adminAPIHandlers) ExportBucketMetadataHandler(w http.ResponseWriter, r *
|
||||
case bucketNotificationConfig:
|
||||
config, err := globalBucketMetadataSys.GetNotificationConfig(bucket)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponse(ctx, w, exportError(ctx, err, cfgFile, bucket), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -447,7 +446,7 @@ func (a adminAPIHandlers) ExportBucketMetadataHandler(w http.ResponseWriter, r *
|
||||
if errors.Is(err, BucketLifecycleNotFound{Bucket: bucket}) {
|
||||
continue
|
||||
}
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponse(ctx, w, exportError(ctx, err, cfgFile, bucket), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -736,7 +735,7 @@ func (a adminAPIHandlers) ImportBucketMetadataHandler(w http.ResponseWriter, r *
|
||||
rpt.SetStatus(bucket, fileName, fmt.Errorf("An Object Lock configuration is present on this bucket, so the versioning state cannot be suspended."))
|
||||
continue
|
||||
}
|
||||
if _, err := getReplicationConfig(ctx, bucket); err == nil && v.Suspended() {
|
||||
if rcfg, _ := getReplicationConfig(ctx, bucket); rcfg != nil && v.Suspended() {
|
||||
rpt.SetStatus(bucket, fileName, fmt.Errorf("A replication configuration is present on this bucket, so the versioning state cannot be suspended."))
|
||||
continue
|
||||
}
|
||||
@@ -875,8 +874,10 @@ func (a adminAPIHandlers) ImportBucketMetadataHandler(w http.ResponseWriter, r *
|
||||
}
|
||||
kmsKey := encConfig.KeyID()
|
||||
if kmsKey != "" {
|
||||
kmsContext := kms.Context{"MinIO admin API": "ServerInfoHandler"} // Context for a test key operation
|
||||
_, err := GlobalKMS.GenerateKey(ctx, kmsKey, kmsContext)
|
||||
_, err := GlobalKMS.GenerateKey(ctx, &kms.GenerateKeyRequest{
|
||||
Name: kmsKey,
|
||||
AssociatedData: kms.Context{"MinIO admin API": "ServerInfoHandler"}, // Context for a test key operation
|
||||
})
|
||||
if err != nil {
|
||||
if errors.Is(err, kes.ErrKeyNotFound) {
|
||||
rpt.SetStatus(bucket, fileName, errKMSKeyNotFound)
|
||||
|
||||
@@ -58,7 +58,7 @@ func (a adminAPIHandlers) DelConfigKVHandler(w http.ResponseWriter, r *http.Requ
|
||||
password := cred.SecretKey
|
||||
kvBytes, err := madmin.DecryptData(password, io.LimitReader(r.Body, r.ContentLength))
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err, logger.ErrorKind)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAdminConfigBadJSON), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -162,7 +162,7 @@ func (a adminAPIHandlers) SetConfigKVHandler(w http.ResponseWriter, r *http.Requ
|
||||
password := cred.SecretKey
|
||||
kvBytes, err := madmin.DecryptData(password, io.LimitReader(r.Body, r.ContentLength))
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err, logger.ErrorKind)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAdminConfigBadJSON), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -443,7 +443,7 @@ func (a adminAPIHandlers) SetConfigHandler(w http.ResponseWriter, r *http.Reques
|
||||
password := cred.SecretKey
|
||||
kvBytes, err := madmin.DecryptData(password, io.LimitReader(r.Body, r.ContentLength))
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err, logger.ErrorKind)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAdminConfigBadJSON), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
@@ -31,7 +31,6 @@ import (
|
||||
"github.com/minio/minio/internal/config"
|
||||
cfgldap "github.com/minio/minio/internal/config/identity/ldap"
|
||||
"github.com/minio/minio/internal/config/identity/openid"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/mux"
|
||||
"github.com/minio/pkg/v2/ldap"
|
||||
"github.com/minio/pkg/v2/policy"
|
||||
@@ -60,7 +59,7 @@ func addOrUpdateIDPHandler(ctx context.Context, w http.ResponseWriter, r *http.R
|
||||
password := cred.SecretKey
|
||||
reqBytes, err := madmin.DecryptData(password, io.LimitReader(r.Body, r.ContentLength))
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err, logger.ErrorKind)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAdminConfigBadJSON), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
@@ -20,14 +20,12 @@ package cmd
|
||||
import (
|
||||
"encoding/json"
|
||||
"errors"
|
||||
"fmt"
|
||||
"io"
|
||||
"net/http"
|
||||
"strings"
|
||||
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio/internal/auth"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/mux"
|
||||
"github.com/minio/pkg/v2/policy"
|
||||
)
|
||||
@@ -105,6 +103,12 @@ func (a adminAPIHandlers) AttachDetachPolicyLDAP(w http.ResponseWriter, r *http.
|
||||
return
|
||||
}
|
||||
|
||||
// fail if ldap is not enabled
|
||||
if !globalIAMSys.LDAPConfig.Enabled() {
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAdminLDAPNotEnabled), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
if r.ContentLength > maxEConfigJSONSize || r.ContentLength == -1 {
|
||||
// More than maxConfigSize bytes were available
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAdminConfigTooLarge), r.URL)
|
||||
@@ -132,7 +136,7 @@ func (a adminAPIHandlers) AttachDetachPolicyLDAP(w http.ResponseWriter, r *http.
|
||||
password := cred.SecretKey
|
||||
reqBytes, err := madmin.DecryptData(password, io.LimitReader(r.Body, r.ContentLength))
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err, logger.ErrorKind)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAdminConfigBadJSON), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -192,7 +196,7 @@ func (a adminAPIHandlers) AddServiceAccountLDAP(w http.ResponseWriter, r *http.R
|
||||
|
||||
// fail if ldap is not enabled
|
||||
if !globalIAMSys.LDAPConfig.Enabled() {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, errors.New("LDAP not enabled")), r.URL)
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAdminLDAPNotEnabled), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
@@ -218,9 +222,8 @@ func (a adminAPIHandlers) AddServiceAccountLDAP(w http.ResponseWriter, r *http.R
|
||||
err error
|
||||
)
|
||||
|
||||
// If we are creating svc account for request sender, ensure
|
||||
// that targetUser is a real user (i.e. not derived
|
||||
// credentials).
|
||||
// If we are creating svc account for request sender, ensure that targetUser
|
||||
// is a real user (i.e. not derived credentials).
|
||||
if isSvcAccForRequestor {
|
||||
if requestorIsDerivedCredential {
|
||||
if requestorParentUser == "" {
|
||||
@@ -233,12 +236,12 @@ func (a adminAPIHandlers) AddServiceAccountLDAP(w http.ResponseWriter, r *http.R
|
||||
targetGroups = requestorGroups
|
||||
|
||||
// Deny if the target user is not LDAP
|
||||
isLDAP, err := globalIAMSys.LDAPConfig.DoesUsernameExist(targetUser)
|
||||
foundLDAPDN, err := globalIAMSys.LDAPConfig.GetValidatedDNForUsername(targetUser)
|
||||
if err != nil {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
if isLDAP == "" {
|
||||
if foundLDAPDN == "" {
|
||||
err := errors.New("Specified user does not exist on LDAP server")
|
||||
APIErr := errorCodes.ToAPIErrWithErr(ErrAdminNoSuchUser, err)
|
||||
writeErrorResponseJSON(ctx, w, APIErr, r.URL)
|
||||
@@ -254,15 +257,23 @@ func (a adminAPIHandlers) AddServiceAccountLDAP(w http.ResponseWriter, r *http.R
|
||||
opts.claims[k] = v
|
||||
}
|
||||
} else {
|
||||
isDN := globalIAMSys.LDAPConfig.IsLDAPUserDN(targetUser)
|
||||
// We still need to ensure that the target user is a valid LDAP user.
|
||||
//
|
||||
// The target user may be supplied as a (short) username or a DN.
|
||||
// However, for now, we only support using the short username.
|
||||
|
||||
isDN := globalIAMSys.LDAPConfig.ParsesAsDN(targetUser)
|
||||
opts.claims[ldapUserN] = targetUser // simple username
|
||||
targetUser, targetGroups, err = globalIAMSys.LDAPConfig.LookupUserDN(targetUser)
|
||||
if err != nil {
|
||||
// if not found, check if DN
|
||||
if strings.Contains(err.Error(), "not found") && isDN {
|
||||
// warn user that DNs are not allowed
|
||||
err = fmt.Errorf("Must use short username to add service account. %w", err)
|
||||
if strings.Contains(err.Error(), "User DN not found for:") {
|
||||
if isDN {
|
||||
// warn user that DNs are not allowed
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErrWithErr(ErrAdminLDAPExpectedLoginName, err), r.URL)
|
||||
} else {
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErrWithErr(ErrAdminNoSuchUser, err), r.URL)
|
||||
}
|
||||
}
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
@@ -301,7 +312,7 @@ func (a adminAPIHandlers) AddServiceAccountLDAP(w http.ResponseWriter, r *http.R
|
||||
// Call hook for cluster-replication if the service account is not for a
|
||||
// root user.
|
||||
if newCred.ParentUser != globalActiveCred.AccessKey {
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
replLogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemSvcAcc,
|
||||
SvcAccChange: &madmin.SRSvcAccChange{
|
||||
Create: &madmin.SRSvcAccCreate{
|
||||
@@ -374,11 +385,12 @@ func (a adminAPIHandlers) ListAccessKeysLDAP(w http.ResponseWriter, r *http.Requ
|
||||
}
|
||||
}
|
||||
|
||||
targetAccount, err := globalIAMSys.LDAPConfig.DoesUsernameExist(userDN)
|
||||
targetAccount, err := globalIAMSys.LDAPConfig.GetValidatedDNForUsername(userDN)
|
||||
if err != nil {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
} else if userDN == "" {
|
||||
}
|
||||
if targetAccount == "" {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, errNoSuchUser), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
+31
-32
@@ -1,4 +1,4 @@
|
||||
// Copyright (c) 2015-2021 MinIO, Inc.
|
||||
// Copyright (c) 2015-2024 MinIO, Inc.
|
||||
//
|
||||
// This file is part of MinIO Object Storage stack
|
||||
//
|
||||
@@ -18,6 +18,7 @@
|
||||
package cmd
|
||||
|
||||
import (
|
||||
"context"
|
||||
"encoding/json"
|
||||
"errors"
|
||||
"fmt"
|
||||
@@ -25,8 +26,8 @@ import (
|
||||
"strconv"
|
||||
"strings"
|
||||
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/mux"
|
||||
"github.com/minio/pkg/v2/env"
|
||||
"github.com/minio/pkg/v2/policy"
|
||||
)
|
||||
|
||||
@@ -106,21 +107,12 @@ func (a adminAPIHandlers) StartDecommission(w http.ResponseWriter, r *http.Reque
|
||||
poolIndices = append(poolIndices, idx)
|
||||
}
|
||||
|
||||
if len(poolIndices) > 0 && !globalEndpoints[poolIndices[0]].Endpoints[0].IsLocal {
|
||||
ep := globalEndpoints[poolIndices[0]].Endpoints[0]
|
||||
for nodeIdx, proxyEp := range globalProxyEndpoints {
|
||||
if proxyEp.Endpoint.Host == ep.Host {
|
||||
if proxyRequestByNodeIndex(ctx, w, r, nodeIdx) {
|
||||
return
|
||||
}
|
||||
}
|
||||
if len(poolIndices) == 0 || !proxyDecommissionRequest(ctx, globalEndpoints[poolIndices[0]].Endpoints[0], w, r) {
|
||||
if err := z.Decommission(r.Context(), poolIndices...); err != nil {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
if err := z.Decommission(r.Context(), poolIndices...); err != nil {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
func (a adminAPIHandlers) CancelDecommission(w http.ResponseWriter, r *http.Request) {
|
||||
@@ -162,20 +154,12 @@ func (a adminAPIHandlers) CancelDecommission(w http.ResponseWriter, r *http.Requ
|
||||
return
|
||||
}
|
||||
|
||||
if ep := globalEndpoints[idx].Endpoints[0]; !ep.IsLocal {
|
||||
for nodeIdx, proxyEp := range globalProxyEndpoints {
|
||||
if proxyEp.Endpoint.Host == ep.Host {
|
||||
if proxyRequestByNodeIndex(ctx, w, r, nodeIdx) {
|
||||
return
|
||||
}
|
||||
}
|
||||
if !proxyDecommissionRequest(ctx, globalEndpoints[idx].Endpoints[0], w, r) {
|
||||
if err := pools.DecommissionCancel(ctx, idx); err != nil {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
if err := pools.DecommissionCancel(ctx, idx); err != nil {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
func (a adminAPIHandlers) StatusPool(w http.ResponseWriter, r *http.Request) {
|
||||
@@ -225,7 +209,7 @@ func (a adminAPIHandlers) StatusPool(w http.ResponseWriter, r *http.Request) {
|
||||
return
|
||||
}
|
||||
|
||||
logger.LogIf(r.Context(), json.NewEncoder(w).Encode(&status))
|
||||
adminLogIf(r.Context(), json.NewEncoder(w).Encode(&status))
|
||||
}
|
||||
|
||||
func (a adminAPIHandlers) ListPools(w http.ResponseWriter, r *http.Request) {
|
||||
@@ -258,7 +242,7 @@ func (a adminAPIHandlers) ListPools(w http.ResponseWriter, r *http.Request) {
|
||||
poolsStatus[idx] = status
|
||||
}
|
||||
|
||||
logger.LogIf(r.Context(), json.NewEncoder(w).Encode(poolsStatus))
|
||||
adminLogIf(r.Context(), json.NewEncoder(w).Encode(poolsStatus))
|
||||
}
|
||||
|
||||
func (a adminAPIHandlers) RebalanceStart(w http.ResponseWriter, r *http.Request) {
|
||||
@@ -365,11 +349,11 @@ func (a adminAPIHandlers) RebalanceStatus(w http.ResponseWriter, r *http.Request
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAdminRebalanceNotStarted), r.URL)
|
||||
return
|
||||
}
|
||||
logger.LogIf(ctx, fmt.Errorf("failed to fetch rebalance status: %w", err))
|
||||
adminLogIf(ctx, fmt.Errorf("failed to fetch rebalance status: %w", err))
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
logger.LogIf(r.Context(), json.NewEncoder(w).Encode(rs))
|
||||
adminLogIf(r.Context(), json.NewEncoder(w).Encode(rs))
|
||||
}
|
||||
|
||||
func (a adminAPIHandlers) RebalanceStop(w http.ResponseWriter, r *http.Request) {
|
||||
@@ -389,5 +373,20 @@ func (a adminAPIHandlers) RebalanceStop(w http.ResponseWriter, r *http.Request)
|
||||
// Cancel any ongoing rebalance operation
|
||||
globalNotificationSys.StopRebalance(r.Context())
|
||||
writeSuccessResponseHeadersOnly(w)
|
||||
logger.LogIf(ctx, pools.saveRebalanceStats(GlobalContext, 0, rebalSaveStoppedAt))
|
||||
adminLogIf(ctx, pools.saveRebalanceStats(GlobalContext, 0, rebalSaveStoppedAt))
|
||||
}
|
||||
|
||||
func proxyDecommissionRequest(ctx context.Context, defaultEndPoint Endpoint, w http.ResponseWriter, r *http.Request) (proxy bool) {
|
||||
host := env.Get("_MINIO_DECOM_ENDPOINT_HOST", defaultEndPoint.Host)
|
||||
if host == "" {
|
||||
return
|
||||
}
|
||||
for nodeIdx, proxyEp := range globalProxyEndpoints {
|
||||
if proxyEp.Endpoint.Host == host && !proxyEp.IsLocal {
|
||||
if proxyRequestByNodeIndex(ctx, w, r, nodeIdx) {
|
||||
return true
|
||||
}
|
||||
}
|
||||
}
|
||||
return
|
||||
}
|
||||
|
||||
@@ -32,7 +32,6 @@ import (
|
||||
"github.com/dustin/go-humanize"
|
||||
"github.com/minio/madmin-go/v3"
|
||||
xioutil "github.com/minio/minio/internal/ioutil"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/mux"
|
||||
"github.com/minio/pkg/v2/policy"
|
||||
)
|
||||
@@ -55,7 +54,7 @@ func (a adminAPIHandlers) SiteReplicationAdd(w http.ResponseWriter, r *http.Requ
|
||||
opts := getSRAddOptions(r)
|
||||
status, err := globalSiteReplicationSys.AddPeerClusters(ctx, sites, opts)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -93,7 +92,7 @@ func (a adminAPIHandlers) SRPeerJoin(w http.ResponseWriter, r *http.Request) {
|
||||
}
|
||||
|
||||
if err := globalSiteReplicationSys.PeerJoinReq(ctx, joinArg); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -140,7 +139,7 @@ func (a adminAPIHandlers) SRPeerBucketOps(w http.ResponseWriter, r *http.Request
|
||||
globalSiteReplicationSys.purgeDeletedBucket(ctx, objectAPI, bucket)
|
||||
}
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -192,7 +191,7 @@ func (a adminAPIHandlers) SRPeerReplicateIAMItem(w http.ResponseWriter, r *http.
|
||||
err = globalSiteReplicationSys.PeerGroupInfoChangeHandler(ctx, item.GroupInfo, item.UpdatedAt)
|
||||
}
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -263,7 +262,7 @@ func (a adminAPIHandlers) SRPeerReplicateBucketItem(w http.ResponseWriter, r *ht
|
||||
err = globalSiteReplicationSys.PeerBucketLCConfigHandler(ctx, item.Bucket, item.ExpiryLCConfig, item.UpdatedAt)
|
||||
}
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -316,7 +315,6 @@ func parseJSONBody(ctx context.Context, body io.Reader, v interface{}, encryptio
|
||||
if encryptionKey != "" {
|
||||
data, err = madmin.DecryptData(encryptionKey, bytes.NewReader(data))
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
return SRError{
|
||||
Cause: err,
|
||||
Code: ErrSiteReplicationInvalidRequest,
|
||||
@@ -349,6 +347,18 @@ func (a adminAPIHandlers) SiteReplicationStatus(w http.ResponseWriter, r *http.R
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
// Report the ILMExpiryStats only if at least one site has replication of ILM expiry enabled
|
||||
var replicateILMExpiry bool
|
||||
for _, site := range info.Sites {
|
||||
if site.ReplicateILMExpiry {
|
||||
replicateILMExpiry = true
|
||||
break
|
||||
}
|
||||
}
|
||||
if !replicateILMExpiry {
|
||||
// explicitly send nil for ILMExpiryStats
|
||||
info.ILMExpiryStats = nil
|
||||
}
|
||||
|
||||
if err = json.NewEncoder(w).Encode(info); err != nil {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
@@ -396,7 +406,7 @@ func (a adminAPIHandlers) SiteReplicationEdit(w http.ResponseWriter, r *http.Req
|
||||
opts := getSREditOptions(r)
|
||||
status, err := globalSiteReplicationSys.EditPeerCluster(ctx, site, opts)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -433,7 +443,7 @@ func (a adminAPIHandlers) SRPeerEdit(w http.ResponseWriter, r *http.Request) {
|
||||
}
|
||||
|
||||
if err := globalSiteReplicationSys.PeerEditReq(ctx, pi); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -456,7 +466,7 @@ func (a adminAPIHandlers) SRStateEdit(w http.ResponseWriter, r *http.Request) {
|
||||
return
|
||||
}
|
||||
if err := globalSiteReplicationSys.PeerStateEditReq(ctx, state); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -493,7 +503,7 @@ func (a adminAPIHandlers) SiteReplicationRemove(w http.ResponseWriter, r *http.R
|
||||
}
|
||||
status, err := globalSiteReplicationSys.RemovePeerCluster(ctx, objectAPI, rreq)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -524,7 +534,7 @@ func (a adminAPIHandlers) SRPeerRemove(w http.ResponseWriter, r *http.Request) {
|
||||
}
|
||||
|
||||
if err := globalSiteReplicationSys.InternalRemoveReq(ctx, objectAPI, req); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -586,7 +596,7 @@ func (a adminAPIHandlers) SiteReplicationDevNull(w http.ResponseWriter, r *http.
|
||||
// If there is a disconnection before globalNetPerfMinDuration (we give a margin of error of 1 sec)
|
||||
// would mean the network is not stable. Logging here will help in debugging network issues.
|
||||
if time.Since(connectTime) < (globalNetPerfMinDuration - time.Second) {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
}
|
||||
}
|
||||
if err != nil {
|
||||
@@ -609,5 +619,5 @@ func (a adminAPIHandlers) SiteReplicationNetPerf(w http.ResponseWriter, r *http.
|
||||
duration = globalNetPerfMinDuration
|
||||
}
|
||||
result := siteNetperf(r.Context(), duration)
|
||||
logger.LogIf(r.Context(), gob.NewEncoder(w).Encode(result))
|
||||
adminLogIf(r.Context(), gob.NewEncoder(w).Encode(result))
|
||||
}
|
||||
|
||||
+147
-120
@@ -35,7 +35,6 @@ import (
|
||||
"github.com/minio/minio/internal/auth"
|
||||
"github.com/minio/minio/internal/cachevalue"
|
||||
"github.com/minio/minio/internal/config/dns"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/mux"
|
||||
"github.com/minio/pkg/v2/policy"
|
||||
"github.com/puzpuzpuz/xsync/v3"
|
||||
@@ -75,7 +74,7 @@ func (a adminAPIHandlers) RemoveUser(w http.ResponseWriter, r *http.Request) {
|
||||
return
|
||||
}
|
||||
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
replLogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemIAMUser,
|
||||
IAMUser: &madmin.SRIAMUser{
|
||||
AccessKey: accessKey,
|
||||
@@ -272,14 +271,21 @@ func (a adminAPIHandlers) UpdateGroupMembers(w http.ResponseWriter, r *http.Requ
|
||||
return
|
||||
}
|
||||
}
|
||||
updatedAt, err = globalIAMSys.AddUsersToGroup(ctx, updReq.Group, updReq.Members)
|
||||
|
||||
if globalIAMSys.LDAPConfig.Enabled() {
|
||||
// We don't allow internal group manipulation in this API when LDAP
|
||||
// is enabled for now.
|
||||
err = errIAMActionNotAllowed
|
||||
} else {
|
||||
updatedAt, err = globalIAMSys.AddUsersToGroup(ctx, updReq.Group, updReq.Members)
|
||||
}
|
||||
}
|
||||
if err != nil {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
replLogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemGroupInfo,
|
||||
GroupInfo: &madmin.SRGroupInfo{
|
||||
UpdateReq: updReq,
|
||||
@@ -369,7 +375,7 @@ func (a adminAPIHandlers) SetGroupStatus(w http.ResponseWriter, r *http.Request)
|
||||
return
|
||||
}
|
||||
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
replLogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemGroupInfo,
|
||||
GroupInfo: &madmin.SRGroupInfo{
|
||||
UpdateReq: madmin.GroupAddRemove{
|
||||
@@ -407,7 +413,7 @@ func (a adminAPIHandlers) SetUserStatus(w http.ResponseWriter, r *http.Request)
|
||||
return
|
||||
}
|
||||
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
replLogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemIAMUser,
|
||||
IAMUser: &madmin.SRIAMUser{
|
||||
AccessKey: accessKey,
|
||||
@@ -496,25 +502,31 @@ func (a adminAPIHandlers) AddUser(w http.ResponseWriter, r *http.Request) {
|
||||
password := cred.SecretKey
|
||||
configBytes, err := madmin.DecryptData(password, io.LimitReader(r.Body, r.ContentLength))
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAdminConfigBadJSON), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
var ureq madmin.AddOrUpdateUserReq
|
||||
if err = json.Unmarshal(configBytes, &ureq); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAdminConfigBadJSON), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
// We don't allow internal user creation with LDAP enabled for now.
|
||||
if globalIAMSys.LDAPConfig.Enabled() {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, errIAMActionNotAllowed), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
updatedAt, err := globalIAMSys.CreateUser(ctx, accessKey, ureq)
|
||||
if err != nil {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
replLogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemIAMUser,
|
||||
IAMUser: &madmin.SRIAMUser{
|
||||
AccessKey: accessKey,
|
||||
@@ -732,7 +744,7 @@ func (a adminAPIHandlers) AddServiceAccount(w http.ResponseWriter, r *http.Reque
|
||||
// Call hook for cluster-replication if the service account is not for a
|
||||
// root user.
|
||||
if newCred.ParentUser != globalActiveCred.AccessKey {
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
replLogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemSvcAcc,
|
||||
SvcAccChange: &madmin.SRSvcAccChange{
|
||||
Create: &madmin.SRSvcAccCreate{
|
||||
@@ -854,7 +866,7 @@ func (a adminAPIHandlers) UpdateServiceAccount(w http.ResponseWriter, r *http.Re
|
||||
|
||||
// Call site replication hook - non-root user accounts are replicated.
|
||||
if svcAccount.ParentUser != globalActiveCred.AccessKey {
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
replLogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemSvcAcc,
|
||||
SvcAccChange: &madmin.SRSvcAccChange{
|
||||
Update: &madmin.SRSvcAccUpdate{
|
||||
@@ -1027,8 +1039,13 @@ func (a adminAPIHandlers) ListServiceAccounts(w http.ResponseWriter, r *http.Req
|
||||
for _, svc := range serviceAccounts {
|
||||
expiryTime := svc.Expiration
|
||||
serviceAccountList = append(serviceAccountList, madmin.ServiceAccountInfo{
|
||||
AccessKey: svc.AccessKey,
|
||||
Expiration: &expiryTime,
|
||||
Description: svc.Description,
|
||||
ParentUser: svc.ParentUser,
|
||||
Name: svc.Name,
|
||||
AccountStatus: svc.Status,
|
||||
AccessKey: svc.AccessKey,
|
||||
ImpliedPolicy: svc.IsImpliedPolicy(),
|
||||
Expiration: &expiryTime,
|
||||
})
|
||||
}
|
||||
|
||||
@@ -1116,7 +1133,7 @@ func (a adminAPIHandlers) DeleteServiceAccount(w http.ResponseWriter, r *http.Re
|
||||
|
||||
// Call site replication hook - non-root user accounts are replicated.
|
||||
if svcAccount.ParentUser != "" && svcAccount.ParentUser != globalActiveCred.AccessKey {
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
replLogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemSvcAcc,
|
||||
SvcAccChange: &madmin.SRSvcAccChange{
|
||||
Delete: &madmin.SRSvcAccDelete{
|
||||
@@ -1200,9 +1217,9 @@ func (a adminAPIHandlers) AccountInfoHandler(w http.ResponseWriter, r *http.Requ
|
||||
}
|
||||
|
||||
bucketStorageCache.InitOnce(10*time.Second,
|
||||
cachevalue.Opts{ReturnLastGood: true, NoWait: true},
|
||||
func() (DataUsageInfo, error) {
|
||||
ctx, done := context.WithTimeout(context.Background(), 2*time.Second)
|
||||
cachevalue.Opts{ReturnLastGood: true},
|
||||
func(ctx context.Context) (DataUsageInfo, error) {
|
||||
ctx, done := context.WithTimeout(ctx, 2*time.Second)
|
||||
defer done()
|
||||
|
||||
return loadDataUsageFromBackend(ctx, objectAPI)
|
||||
@@ -1274,7 +1291,7 @@ func (a adminAPIHandlers) AccountInfoHandler(w http.ResponseWriter, r *http.Requ
|
||||
default:
|
||||
policies, err := globalIAMSys.PolicyDBGet(accountName, cred.Groups...)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -1426,7 +1443,7 @@ func (a adminAPIHandlers) ListBucketPolicies(w http.ResponseWriter, r *http.Requ
|
||||
for name, p := range policies {
|
||||
_, err = json.Marshal(p)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
newPolicies[name] = p
|
||||
@@ -1456,7 +1473,7 @@ func (a adminAPIHandlers) ListCannedPolicies(w http.ResponseWriter, r *http.Requ
|
||||
for name, p := range policies {
|
||||
_, err = json.Marshal(p)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
newPolicies[name] = p
|
||||
@@ -1486,7 +1503,7 @@ func (a adminAPIHandlers) RemoveCannedPolicy(w http.ResponseWriter, r *http.Requ
|
||||
|
||||
// Call cluster-replication policy creation hook to replicate policy deletion to
|
||||
// other minio clusters.
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
replLogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemPolicy,
|
||||
Name: policyName,
|
||||
UpdatedAt: UTCNow(),
|
||||
@@ -1549,7 +1566,7 @@ func (a adminAPIHandlers) AddCannedPolicy(w http.ResponseWriter, r *http.Request
|
||||
|
||||
// Call cluster-replication policy creation hook to replicate policy to
|
||||
// other minio clusters.
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
replLogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemPolicy,
|
||||
Name: policyName,
|
||||
Policy: iamPolicyBytes,
|
||||
@@ -1557,7 +1574,12 @@ func (a adminAPIHandlers) AddCannedPolicy(w http.ResponseWriter, r *http.Request
|
||||
}))
|
||||
}
|
||||
|
||||
// SetPolicyForUserOrGroup - PUT /minio/admin/v3/set-policy?policy=xxx&user-or-group=?[&is-group]
|
||||
// SetPolicyForUserOrGroup - sets a policy on a user or a group.
|
||||
//
|
||||
// PUT /minio/admin/v3/set-policy?policy=xxx&user-or-group=?[&is-group]
|
||||
//
|
||||
// Deprecated: This API is replaced by attach/detach policy APIs for specific
|
||||
// type of users (builtin or LDAP).
|
||||
func (a adminAPIHandlers) SetPolicyForUserOrGroup(w http.ResponseWriter, r *http.Request) {
|
||||
ctx := r.Context()
|
||||
|
||||
@@ -1609,6 +1631,32 @@ func (a adminAPIHandlers) SetPolicyForUserOrGroup(w http.ResponseWriter, r *http
|
||||
userType := regUser
|
||||
if globalIAMSys.GetUsersSysType() == LDAPUsersSysType {
|
||||
userType = stsUser
|
||||
|
||||
// Validate that the user or group exists in LDAP and use the normalized
|
||||
// form of the entityName (which will be an LDAP DN).
|
||||
var err error
|
||||
if isGroup {
|
||||
var foundGroupDN string
|
||||
var underBaseDN bool
|
||||
if foundGroupDN, underBaseDN, err = globalIAMSys.LDAPConfig.GetValidatedGroupDN(nil, entityName); err != nil {
|
||||
iamLogIf(ctx, err)
|
||||
} else if foundGroupDN == "" || !underBaseDN {
|
||||
err = errNoSuchGroup
|
||||
}
|
||||
entityName = foundGroupDN
|
||||
} else {
|
||||
var foundUserDN string
|
||||
if foundUserDN, err = globalIAMSys.LDAPConfig.GetValidatedDNForUsername(entityName); err != nil {
|
||||
iamLogIf(ctx, err)
|
||||
} else if foundUserDN == "" {
|
||||
err = errNoSuchUser
|
||||
}
|
||||
entityName = foundUserDN
|
||||
}
|
||||
if err != nil {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
updatedAt, err := globalIAMSys.PolicyDBSet(ctx, entityName, policyName, userType, isGroup)
|
||||
@@ -1617,7 +1665,7 @@ func (a adminAPIHandlers) SetPolicyForUserOrGroup(w http.ResponseWriter, r *http
|
||||
return
|
||||
}
|
||||
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
replLogIf(ctx, globalSiteReplicationSys.IAMChangeHook(ctx, madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemPolicyMapping,
|
||||
PolicyMapping: &madmin.SRPolicyMapping{
|
||||
UserOrGroup: entityName,
|
||||
@@ -1757,17 +1805,27 @@ func (a adminAPIHandlers) AttachDetachPolicyBuiltin(w http.ResponseWriter, r *ht
|
||||
}
|
||||
|
||||
const (
|
||||
allPoliciesFile = "policies.json"
|
||||
allUsersFile = "users.json"
|
||||
allGroupsFile = "groups.json"
|
||||
allSvcAcctsFile = "svcaccts.json"
|
||||
userPolicyMappingsFile = "user_mappings.json"
|
||||
groupPolicyMappingsFile = "group_mappings.json"
|
||||
stsUserPolicyMappingsFile = "stsuser_mappings.json"
|
||||
stsGroupPolicyMappingsFile = "stsgroup_mappings.json"
|
||||
iamAssetsDir = "iam-assets"
|
||||
allPoliciesFile = "policies.json"
|
||||
allUsersFile = "users.json"
|
||||
allGroupsFile = "groups.json"
|
||||
allSvcAcctsFile = "svcaccts.json"
|
||||
userPolicyMappingsFile = "user_mappings.json"
|
||||
groupPolicyMappingsFile = "group_mappings.json"
|
||||
stsUserPolicyMappingsFile = "stsuser_mappings.json"
|
||||
|
||||
iamAssetsDir = "iam-assets"
|
||||
)
|
||||
|
||||
var iamExportFiles = []string{
|
||||
allPoliciesFile,
|
||||
allUsersFile,
|
||||
allGroupsFile,
|
||||
allSvcAcctsFile,
|
||||
userPolicyMappingsFile,
|
||||
groupPolicyMappingsFile,
|
||||
stsUserPolicyMappingsFile,
|
||||
}
|
||||
|
||||
// ExportIAMHandler - exports all iam info as a zipped file
|
||||
func (a adminAPIHandlers) ExportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
ctx := r.Context()
|
||||
@@ -1791,38 +1849,28 @@ func (a adminAPIHandlers) ExportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
sys: nil,
|
||||
})
|
||||
if zerr != nil {
|
||||
logger.LogIf(ctx, zerr)
|
||||
adminLogIf(ctx, zerr)
|
||||
return nil
|
||||
}
|
||||
header.Method = zip.Deflate
|
||||
zwriter, zerr := zipWriter.CreateHeader(header)
|
||||
if zerr != nil {
|
||||
logger.LogIf(ctx, zerr)
|
||||
adminLogIf(ctx, zerr)
|
||||
return nil
|
||||
}
|
||||
if _, err := io.Copy(zwriter, r); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
iamFiles := []string{
|
||||
allPoliciesFile,
|
||||
allUsersFile,
|
||||
allGroupsFile,
|
||||
allSvcAcctsFile,
|
||||
userPolicyMappingsFile,
|
||||
groupPolicyMappingsFile,
|
||||
stsUserPolicyMappingsFile,
|
||||
stsGroupPolicyMappingsFile,
|
||||
}
|
||||
for _, f := range iamFiles {
|
||||
for _, f := range iamExportFiles {
|
||||
iamFile := pathJoin(iamAssetsDir, f)
|
||||
switch f {
|
||||
case allPoliciesFile:
|
||||
allPolicies, err := globalIAMSys.ListPolicies(ctx, "")
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
writeErrorResponse(ctx, w, exportError(ctx, err, iamFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -1901,7 +1949,7 @@ func (a adminAPIHandlers) ExportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
writeErrorResponse(ctx, w, exportError(ctx, err, iamFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
_, policy, err := globalIAMSys.GetServiceAccount(ctx, acc.Credentials.AccessKey)
|
||||
sa, policy, err := globalIAMSys.GetServiceAccount(ctx, acc.Credentials.AccessKey)
|
||||
if err != nil {
|
||||
writeErrorResponse(ctx, w, exportError(ctx, err, iamFile, ""), r.URL)
|
||||
return
|
||||
@@ -1923,6 +1971,9 @@ func (a adminAPIHandlers) ExportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
Claims: claims,
|
||||
SessionPolicy: json.RawMessage(policyJSON),
|
||||
Status: acc.Credentials.Status,
|
||||
Name: sa.Name,
|
||||
Description: sa.Description,
|
||||
Expiration: &sa.Expiration,
|
||||
}
|
||||
}
|
||||
|
||||
@@ -1986,22 +2037,6 @@ func (a adminAPIHandlers) ExportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
writeErrorResponse(ctx, w, exportError(ctx, err, iamFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
case stsGroupPolicyMappingsFile:
|
||||
groupPolicyMap := xsync.NewMapOf[string, MappedPolicy]()
|
||||
err := globalIAMSys.store.loadMappedPolicies(ctx, stsUser, true, groupPolicyMap)
|
||||
if err != nil {
|
||||
writeErrorResponse(ctx, w, exportError(ctx, err, iamFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
grpPolData, err := json.Marshal(mappedPoliciesToMap(groupPolicyMap))
|
||||
if err != nil {
|
||||
writeErrorResponse(ctx, w, exportError(ctx, err, iamFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
if err = rawDataFn(bytes.NewReader(grpPolData), iamFile, len(grpPolData)); err != nil {
|
||||
writeErrorResponse(ctx, w, exportError(ctx, err, iamFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -2171,12 +2206,12 @@ func (a adminAPIHandlers) ImportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
// If group does not exist, then check if the group has beginning and end space characters
|
||||
// we will reject such group names.
|
||||
if errors.Is(gerr, errNoSuchGroup) && hasSpaceBE(group) {
|
||||
writeErrorResponseJSON(ctx, w, importErrorWithAPIErr(ctx, ErrAdminResourceInvalidArgument, err, allGroupsFile, group), r.URL)
|
||||
writeErrorResponseJSON(ctx, w, importErrorWithAPIErr(ctx, ErrAdminResourceInvalidArgument, gerr, allGroupsFile, group), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
if _, gerr := globalIAMSys.AddUsersToGroup(ctx, group, grpInfo.Members); gerr != nil {
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, err, allGroupsFile, group), r.URL)
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, gerr, allGroupsFile, group), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
@@ -2203,6 +2238,16 @@ func (a adminAPIHandlers) ImportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
writeErrorResponseJSON(ctx, w, importErrorWithAPIErr(ctx, ErrAdminConfigBadJSON, err, allSvcAcctsFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
// Validations for LDAP enabled deployments.
|
||||
if globalIAMSys.LDAPConfig.Enabled() {
|
||||
err := globalIAMSys.NormalizeLDAPAccessKeypairs(ctx, serviceAcctReqs)
|
||||
if err != nil {
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, err, allSvcAcctsFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
for user, svcAcctReq := range serviceAcctReqs {
|
||||
var sp *policy.Policy
|
||||
var err error
|
||||
@@ -2213,7 +2258,8 @@ func (a adminAPIHandlers) ImportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
return
|
||||
}
|
||||
}
|
||||
// service account access key cannot have space characters beginning and end of the string.
|
||||
// service account access key cannot have space characters
|
||||
// beginning and end of the string.
|
||||
if hasSpaceBE(svcAcctReq.AccessKey) {
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAdminResourceInvalidArgument), r.URL)
|
||||
return
|
||||
@@ -2239,20 +2285,14 @@ func (a adminAPIHandlers) ImportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
updateReq = false
|
||||
}
|
||||
if updateReq {
|
||||
opts := updateServiceAccountOpts{
|
||||
secretKey: svcAcctReq.SecretKey,
|
||||
status: svcAcctReq.Status,
|
||||
name: svcAcctReq.Name,
|
||||
description: svcAcctReq.Description,
|
||||
expiration: svcAcctReq.Expiration,
|
||||
sessionPolicy: sp,
|
||||
}
|
||||
_, err = globalIAMSys.UpdateServiceAccount(ctx, svcAcctReq.AccessKey, opts)
|
||||
// If the service account exists, we remove it to ensure a
|
||||
// clean import.
|
||||
err := globalIAMSys.DeleteServiceAccount(ctx, svcAcctReq.AccessKey, true)
|
||||
if err != nil {
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, err, allSvcAcctsFile, user), r.URL)
|
||||
delErr := fmt.Errorf("failed to delete existing service account(%s) before importing it: %w", svcAcctReq.AccessKey, err)
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, delErr, allSvcAcctsFile, user), r.URL)
|
||||
return
|
||||
}
|
||||
continue
|
||||
}
|
||||
opts := newServiceAccountOpts{
|
||||
accessKey: user,
|
||||
@@ -2265,18 +2305,6 @@ func (a adminAPIHandlers) ImportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
allowSiteReplicatorAccount: false,
|
||||
}
|
||||
|
||||
// In case of LDAP we need to resolve the targetUser to a DN and
|
||||
// query their groups:
|
||||
if globalIAMSys.LDAPConfig.Enabled() {
|
||||
opts.claims[ldapUserN] = svcAcctReq.AccessKey // simple username
|
||||
targetUser, _, err := globalIAMSys.LDAPConfig.LookupUserDN(svcAcctReq.AccessKey)
|
||||
if err != nil {
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, err, allSvcAcctsFile, user), r.URL)
|
||||
return
|
||||
}
|
||||
opts.claims[ldapUser] = targetUser // username DN
|
||||
}
|
||||
|
||||
if _, _, err = globalIAMSys.NewServiceAccount(ctx, svcAcctReq.Parent, svcAcctReq.Groups, opts); err != nil {
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, err, allSvcAcctsFile, user), r.URL)
|
||||
return
|
||||
@@ -2345,6 +2373,17 @@ func (a adminAPIHandlers) ImportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
writeErrorResponseJSON(ctx, w, importErrorWithAPIErr(ctx, ErrAdminConfigBadJSON, err, groupPolicyMappingsFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
// Validations for LDAP enabled deployments.
|
||||
if globalIAMSys.LDAPConfig.Enabled() {
|
||||
isGroup := true
|
||||
err := globalIAMSys.NormalizeLDAPMappingImport(ctx, isGroup, grpPolicyMap)
|
||||
if err != nil {
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, err, groupPolicyMappingsFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
for g, pm := range grpPolicyMap {
|
||||
if _, err := globalIAMSys.PolicyDBSet(ctx, g, pm.Policies, unknownIAMUserType, true); err != nil {
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, err, groupPolicyMappingsFile, g), r.URL)
|
||||
@@ -2374,6 +2413,16 @@ func (a adminAPIHandlers) ImportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
writeErrorResponseJSON(ctx, w, importErrorWithAPIErr(ctx, ErrAdminConfigBadJSON, err, stsUserPolicyMappingsFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
// Validations for LDAP enabled deployments.
|
||||
if globalIAMSys.LDAPConfig.Enabled() {
|
||||
isGroup := true
|
||||
err := globalIAMSys.NormalizeLDAPMappingImport(ctx, !isGroup, userPolicyMap)
|
||||
if err != nil {
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, err, stsUserPolicyMappingsFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
for u, pm := range userPolicyMap {
|
||||
// disallow setting policy mapping if user is a temporary user
|
||||
ok, _, err := globalIAMSys.IsTempUser(u)
|
||||
@@ -2385,6 +2434,7 @@ func (a adminAPIHandlers) ImportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, errIAMActionNotAllowed, stsUserPolicyMappingsFile, u), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
if _, err := globalIAMSys.PolicyDBSet(ctx, u, pm.Policies, stsUser, false); err != nil {
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, err, stsUserPolicyMappingsFile, u), r.URL)
|
||||
return
|
||||
@@ -2392,35 +2442,6 @@ func (a adminAPIHandlers) ImportIAM(w http.ResponseWriter, r *http.Request) {
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// import sts group policy mappings
|
||||
{
|
||||
f, err := zr.Open(pathJoin(iamAssetsDir, stsGroupPolicyMappingsFile))
|
||||
switch {
|
||||
case errors.Is(err, os.ErrNotExist):
|
||||
case err != nil:
|
||||
writeErrorResponseJSON(ctx, w, importErrorWithAPIErr(ctx, ErrInvalidRequest, err, stsGroupPolicyMappingsFile, ""), r.URL)
|
||||
return
|
||||
default:
|
||||
defer f.Close()
|
||||
var grpPolicyMap map[string]MappedPolicy
|
||||
data, err := io.ReadAll(f)
|
||||
if err != nil {
|
||||
writeErrorResponseJSON(ctx, w, importErrorWithAPIErr(ctx, ErrInvalidRequest, err, stsGroupPolicyMappingsFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
if err = json.Unmarshal(data, &grpPolicyMap); err != nil {
|
||||
writeErrorResponseJSON(ctx, w, importErrorWithAPIErr(ctx, ErrAdminConfigBadJSON, err, stsGroupPolicyMappingsFile, ""), r.URL)
|
||||
return
|
||||
}
|
||||
for g, pm := range grpPolicyMap {
|
||||
if _, err := globalIAMSys.PolicyDBSet(ctx, g, pm.Policies, unknownIAMUserType, true); err != nil {
|
||||
writeErrorResponseJSON(ctx, w, importError(ctx, err, stsGroupPolicyMappingsFile, g), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
func addExpirationToCondValues(exp *time.Time, condValues map[string][]string) {
|
||||
@@ -2455,6 +2476,12 @@ func commonAddServiceAccount(r *http.Request) (context.Context, auth.Credentials
|
||||
return ctx, auth.Credentials{}, newServiceAccountOpts{}, madmin.AddServiceAccountReq{}, "", errorCodes.ToAPIErrWithErr(ErrAdminConfigBadJSON, err)
|
||||
}
|
||||
|
||||
if createReq.Expiration != nil && !createReq.Expiration.IsZero() {
|
||||
// truncate expiration at the second.
|
||||
truncateTime := createReq.Expiration.Truncate(time.Second)
|
||||
createReq.Expiration = &truncateTime
|
||||
}
|
||||
|
||||
// service account access key cannot have space characters beginning and end of the string.
|
||||
if hasSpaceBE(createReq.AccessKey) {
|
||||
return ctx, auth.Credentials{}, newServiceAccountOpts{}, madmin.AddServiceAccountReq{}, "", errorCodes.ToAPIErr(ErrAdminResourceInvalidArgument)
|
||||
|
||||
+170
-130
@@ -36,6 +36,7 @@ import (
|
||||
"net/url"
|
||||
"os"
|
||||
"path"
|
||||
"path/filepath"
|
||||
"regexp"
|
||||
"runtime"
|
||||
"sort"
|
||||
@@ -49,6 +50,7 @@ import (
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/madmin-go/v3/estream"
|
||||
"github.com/minio/minio-go/v7/pkg/set"
|
||||
"github.com/minio/minio/internal/auth"
|
||||
"github.com/minio/minio/internal/dsync"
|
||||
"github.com/minio/minio/internal/grid"
|
||||
"github.com/minio/minio/internal/handlers"
|
||||
@@ -130,7 +132,7 @@ func (a adminAPIHandlers) ServerUpdateV2Handler(w http.ResponseWriter, r *http.R
|
||||
// Download Binary Once
|
||||
binC, bin, err := downloadBinary(u, mode)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("server update failed with %w", err))
|
||||
adminLogIf(ctx, fmt.Errorf("server update failed with %w", err))
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -354,7 +356,7 @@ func (a adminAPIHandlers) ServerUpdateHandler(w http.ResponseWriter, r *http.Req
|
||||
// Download Binary Once
|
||||
binC, bin, err := downloadBinary(u, mode)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("server update failed with %w", err))
|
||||
adminLogIf(ctx, fmt.Errorf("server update failed with %w", err))
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -368,7 +370,7 @@ func (a adminAPIHandlers) ServerUpdateHandler(w http.ResponseWriter, r *http.Req
|
||||
StatusCode: http.StatusInternalServerError,
|
||||
}
|
||||
logger.GetReqInfo(ctx).SetTags("peerAddress", nerr.Host.String())
|
||||
logger.LogIf(ctx, fmt.Errorf("server update failed with %w", err))
|
||||
adminLogIf(ctx, fmt.Errorf("server update failed with %w", err))
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -376,7 +378,7 @@ func (a adminAPIHandlers) ServerUpdateHandler(w http.ResponseWriter, r *http.Req
|
||||
|
||||
err = verifyBinary(u, sha256Sum, releaseInfo, mode, bytes.NewReader(bin))
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("server update failed with %w", err))
|
||||
adminLogIf(ctx, fmt.Errorf("server update failed with %w", err))
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -389,7 +391,7 @@ func (a adminAPIHandlers) ServerUpdateHandler(w http.ResponseWriter, r *http.Req
|
||||
StatusCode: http.StatusInternalServerError,
|
||||
}
|
||||
logger.GetReqInfo(ctx).SetTags("peerAddress", nerr.Host.String())
|
||||
logger.LogIf(ctx, fmt.Errorf("server update failed with %w", err))
|
||||
adminLogIf(ctx, fmt.Errorf("server update failed with %w", err))
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -397,7 +399,7 @@ func (a adminAPIHandlers) ServerUpdateHandler(w http.ResponseWriter, r *http.Req
|
||||
|
||||
err = commitBinary()
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("server update failed with %w", err))
|
||||
adminLogIf(ctx, fmt.Errorf("server update failed with %w", err))
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -420,7 +422,7 @@ func (a adminAPIHandlers) ServerUpdateHandler(w http.ResponseWriter, r *http.Req
|
||||
for _, nerr := range globalNotificationSys.SignalService(serviceRestart) {
|
||||
if nerr.Err != nil {
|
||||
logger.GetReqInfo(ctx).SetTags("peerAddress", nerr.Host.String())
|
||||
logger.LogIf(ctx, nerr.Err)
|
||||
adminLogIf(ctx, nerr.Err)
|
||||
}
|
||||
}
|
||||
|
||||
@@ -451,7 +453,7 @@ func (a adminAPIHandlers) ServiceHandler(w http.ResponseWriter, r *http.Request)
|
||||
case madmin.ServiceActionUnfreeze:
|
||||
serviceSig = serviceUnFreeze
|
||||
default:
|
||||
logger.LogIf(ctx, fmt.Errorf("Unrecognized service action %s requested", action), logger.ErrorKind)
|
||||
adminLogIf(ctx, fmt.Errorf("Unrecognized service action %s requested", action), logger.ErrorKind)
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrMalformedPOSTRequest), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -473,7 +475,7 @@ func (a adminAPIHandlers) ServiceHandler(w http.ResponseWriter, r *http.Request)
|
||||
for _, nerr := range globalNotificationSys.SignalService(serviceSig) {
|
||||
if nerr.Err != nil {
|
||||
logger.GetReqInfo(ctx).SetTags("peerAddress", nerr.Host.String())
|
||||
logger.LogIf(ctx, nerr.Err)
|
||||
adminLogIf(ctx, nerr.Err)
|
||||
}
|
||||
}
|
||||
|
||||
@@ -534,7 +536,7 @@ func (a adminAPIHandlers) ServiceV2Handler(w http.ResponseWriter, r *http.Reques
|
||||
case madmin.ServiceActionUnfreeze:
|
||||
serviceSig = serviceUnFreeze
|
||||
default:
|
||||
logger.LogIf(ctx, fmt.Errorf("Unrecognized service action %s requested", action), logger.ErrorKind)
|
||||
adminLogIf(ctx, fmt.Errorf("Unrecognized service action %s requested", action), logger.ErrorKind)
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrMalformedPOSTRequest), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -1239,7 +1241,7 @@ func extractHealInitParams(vars map[string]string, qParams url.Values, r io.Read
|
||||
if hip.clientToken == "" {
|
||||
jerr := json.NewDecoder(r).Decode(&hip.hs)
|
||||
if jerr != nil {
|
||||
logger.LogIf(GlobalContext, jerr, logger.ErrorKind)
|
||||
adminLogIf(GlobalContext, jerr, logger.ErrorKind)
|
||||
err = ErrRequestBodyParse
|
||||
return
|
||||
}
|
||||
@@ -1433,7 +1435,7 @@ func getAggregatedBackgroundHealState(ctx context.Context, o ObjectLayer) (madmi
|
||||
var errCount int
|
||||
for _, nerr := range nerrs {
|
||||
if nerr.Err != nil {
|
||||
logger.LogIf(ctx, nerr.Err)
|
||||
adminLogIf(ctx, nerr.Err)
|
||||
errCount++
|
||||
}
|
||||
}
|
||||
@@ -1561,7 +1563,7 @@ func (a adminAPIHandlers) ClientDevNull(w http.ResponseWriter, r *http.Request)
|
||||
if err != nil && err != io.EOF && err != io.ErrUnexpectedEOF {
|
||||
// would mean the network is not stable. Logging here will help in debugging network issues.
|
||||
if time.Since(connectTime) < (globalNetPerfMinDuration - time.Second) {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
}
|
||||
}
|
||||
totalRx += n
|
||||
@@ -1575,7 +1577,8 @@ func (a adminAPIHandlers) ClientDevNull(w http.ResponseWriter, r *http.Request)
|
||||
|
||||
// NetperfHandler - perform mesh style network throughput test
|
||||
func (a adminAPIHandlers) NetperfHandler(w http.ResponseWriter, r *http.Request) {
|
||||
ctx := r.Context()
|
||||
ctx, cancel := context.WithCancel(r.Context())
|
||||
defer cancel()
|
||||
|
||||
objectAPI, _ := validateAdminReq(ctx, w, r, policy.HealthInfoAdminAction)
|
||||
if objectAPI == nil {
|
||||
@@ -1596,6 +1599,15 @@ func (a adminAPIHandlers) NetperfHandler(w http.ResponseWriter, r *http.Request)
|
||||
ctx = lkctx.Context()
|
||||
defer nsLock.Unlock(lkctx)
|
||||
|
||||
// Freeze all incoming S3 API calls before running speedtest.
|
||||
globalNotificationSys.ServiceFreeze(ctx, true)
|
||||
|
||||
// Unfreeze as soon as request context is canceled or when the function returns.
|
||||
go func() {
|
||||
<-ctx.Done()
|
||||
globalNotificationSys.ServiceFreeze(ctx, false)
|
||||
}()
|
||||
|
||||
durationStr := r.Form.Get(peerRESTDuration)
|
||||
duration, err := time.ParseDuration(durationStr)
|
||||
if err != nil {
|
||||
@@ -1616,18 +1628,73 @@ func (a adminAPIHandlers) NetperfHandler(w http.ResponseWriter, r *http.Request)
|
||||
}
|
||||
}
|
||||
|
||||
func isAllowedRWAccess(r *http.Request, cred auth.Credentials, bucketName string) (rd, wr bool) {
|
||||
owner := cred.AccessKey == globalActiveCred.AccessKey
|
||||
|
||||
// Set prefix value for "s3:prefix" policy conditionals.
|
||||
r.Header.Set("prefix", "")
|
||||
|
||||
// Set delimiter value for "s3:delimiter" policy conditionals.
|
||||
r.Header.Set("delimiter", SlashSeparator)
|
||||
|
||||
isAllowedAccess := func(bucketName string) (rd, wr bool) {
|
||||
if globalIAMSys.IsAllowed(policy.Args{
|
||||
AccountName: cred.AccessKey,
|
||||
Groups: cred.Groups,
|
||||
Action: policy.GetObjectAction,
|
||||
BucketName: bucketName,
|
||||
ConditionValues: getConditionValues(r, "", cred),
|
||||
IsOwner: owner,
|
||||
ObjectName: "",
|
||||
Claims: cred.Claims,
|
||||
}) {
|
||||
rd = true
|
||||
}
|
||||
|
||||
if globalIAMSys.IsAllowed(policy.Args{
|
||||
AccountName: cred.AccessKey,
|
||||
Groups: cred.Groups,
|
||||
Action: policy.PutObjectAction,
|
||||
BucketName: bucketName,
|
||||
ConditionValues: getConditionValues(r, "", cred),
|
||||
IsOwner: owner,
|
||||
ObjectName: "",
|
||||
Claims: cred.Claims,
|
||||
}) {
|
||||
wr = true
|
||||
}
|
||||
|
||||
return rd, wr
|
||||
}
|
||||
return isAllowedAccess(bucketName)
|
||||
}
|
||||
|
||||
// ObjectSpeedTestHandler - reports maximum speed of a cluster by performing PUT and
|
||||
// GET operations on the server, supports auto tuning by default by automatically
|
||||
// increasing concurrency and stopping when we have reached the limits on the
|
||||
// system.
|
||||
func (a adminAPIHandlers) ObjectSpeedTestHandler(w http.ResponseWriter, r *http.Request) {
|
||||
ctx := r.Context()
|
||||
ctx, cancel := context.WithCancel(r.Context())
|
||||
defer cancel()
|
||||
|
||||
objectAPI, _ := validateAdminReq(ctx, w, r, policy.HealthInfoAdminAction)
|
||||
objectAPI, creds := validateAdminReq(ctx, w, r, policy.HealthInfoAdminAction)
|
||||
if objectAPI == nil {
|
||||
return
|
||||
}
|
||||
|
||||
if !globalAPIConfig.permitRootAccess() {
|
||||
rd, wr := isAllowedRWAccess(r, creds, globalObjectPerfBucket)
|
||||
if !rd || !wr {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, AdminError{
|
||||
Code: "XMinioSpeedtestInsufficientPermissions",
|
||||
Message: fmt.Sprintf("%s does not have read and write access to '%s' bucket", creds.AccessKey,
|
||||
globalObjectPerfBucket),
|
||||
StatusCode: http.StatusForbidden,
|
||||
}), r.URL)
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
sizeStr := r.Form.Get(peerRESTSize)
|
||||
durationStr := r.Form.Get(peerRESTDuration)
|
||||
concurrentStr := r.Form.Get(peerRESTConcurrent)
|
||||
@@ -1636,6 +1703,7 @@ func (a adminAPIHandlers) ObjectSpeedTestHandler(w http.ResponseWriter, r *http.
|
||||
autotune := r.Form.Get("autotune") == "true"
|
||||
noClear := r.Form.Get("noclear") == "true"
|
||||
enableSha256 := r.Form.Get("enableSha256") == "true"
|
||||
enableMultipart := r.Form.Get("enableMultipart") == "true"
|
||||
|
||||
size, err := strconv.Atoi(sizeStr)
|
||||
if err != nil {
|
||||
@@ -1691,8 +1759,11 @@ func (a adminAPIHandlers) ObjectSpeedTestHandler(w http.ResponseWriter, r *http.
|
||||
// Freeze all incoming S3 API calls before running speedtest.
|
||||
globalNotificationSys.ServiceFreeze(ctx, true)
|
||||
|
||||
// unfreeze all incoming S3 API calls after speedtest.
|
||||
defer globalNotificationSys.ServiceFreeze(ctx, false)
|
||||
// Unfreeze as soon as request context is canceled or when the function returns.
|
||||
go func() {
|
||||
<-ctx.Done()
|
||||
globalNotificationSys.ServiceFreeze(ctx, false)
|
||||
}()
|
||||
|
||||
keepAliveTicker := time.NewTicker(500 * time.Millisecond)
|
||||
defer keepAliveTicker.Stop()
|
||||
@@ -1706,6 +1777,8 @@ func (a adminAPIHandlers) ObjectSpeedTestHandler(w http.ResponseWriter, r *http.
|
||||
storageClass: storageClass,
|
||||
bucketName: customBucket,
|
||||
enableSha256: enableSha256,
|
||||
enableMultipart: enableMultipart,
|
||||
creds: creds,
|
||||
})
|
||||
var prevResult madmin.SpeedTestResult
|
||||
for {
|
||||
@@ -1792,7 +1865,8 @@ func validateObjPerfOptions(ctx context.Context, storageInfo madmin.StorageInfo,
|
||||
|
||||
// DriveSpeedtestHandler - reports throughput of drives available in the cluster
|
||||
func (a adminAPIHandlers) DriveSpeedtestHandler(w http.ResponseWriter, r *http.Request) {
|
||||
ctx := r.Context()
|
||||
ctx, cancel := context.WithCancel(r.Context())
|
||||
defer cancel()
|
||||
|
||||
objectAPI, _ := validateAdminReq(ctx, w, r, policy.HealthInfoAdminAction)
|
||||
if objectAPI == nil {
|
||||
@@ -1802,8 +1876,11 @@ func (a adminAPIHandlers) DriveSpeedtestHandler(w http.ResponseWriter, r *http.R
|
||||
// Freeze all incoming S3 API calls before running speedtest.
|
||||
globalNotificationSys.ServiceFreeze(ctx, true)
|
||||
|
||||
// unfreeze all incoming S3 API calls after speedtest.
|
||||
defer globalNotificationSys.ServiceFreeze(ctx, false)
|
||||
// Unfreeze as soon as request context is canceled or when the function returns.
|
||||
go func() {
|
||||
<-ctx.Done()
|
||||
globalNotificationSys.ServiceFreeze(ctx, false)
|
||||
}()
|
||||
|
||||
serial := r.Form.Get("serial") == "true"
|
||||
blockSizeStr := r.Form.Get("blocksize")
|
||||
@@ -2096,7 +2173,9 @@ func (a adminAPIHandlers) KMSCreateKeyHandler(w http.ResponseWriter, r *http.Req
|
||||
return
|
||||
}
|
||||
|
||||
if err := GlobalKMS.CreateKey(ctx, r.Form.Get("key-id")); err != nil {
|
||||
if err := GlobalKMS.CreateKey(ctx, &kms.CreateKeyRequest{
|
||||
Name: r.Form.Get("key-id"),
|
||||
}); err != nil {
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -2117,22 +2196,12 @@ func (a adminAPIHandlers) KMSStatusHandler(w http.ResponseWriter, r *http.Reques
|
||||
return
|
||||
}
|
||||
|
||||
stat, err := GlobalKMS.Stat(ctx)
|
||||
stat, err := GlobalKMS.Status(ctx)
|
||||
if err != nil {
|
||||
writeCustomErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrInternalError), err.Error(), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
status := madmin.KMSStatus{
|
||||
Name: stat.Name,
|
||||
DefaultKeyID: stat.DefaultKey,
|
||||
Endpoints: make(map[string]madmin.ItemState, len(stat.Endpoints)),
|
||||
}
|
||||
for _, endpoint := range stat.Endpoints {
|
||||
status.Endpoints[endpoint] = madmin.ItemOnline // TODO(aead): Implement an online check for mTLS
|
||||
}
|
||||
|
||||
resp, err := json.Marshal(status)
|
||||
resp, err := json.Marshal(stat)
|
||||
if err != nil {
|
||||
writeCustomErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrInternalError), err.Error(), r.URL)
|
||||
return
|
||||
@@ -2154,15 +2223,9 @@ func (a adminAPIHandlers) KMSKeyStatusHandler(w http.ResponseWriter, r *http.Req
|
||||
return
|
||||
}
|
||||
|
||||
stat, err := GlobalKMS.Stat(ctx)
|
||||
if err != nil {
|
||||
writeCustomErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrInternalError), err.Error(), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
keyID := r.Form.Get("key-id")
|
||||
if keyID == "" {
|
||||
keyID = stat.DefaultKey
|
||||
keyID = GlobalKMS.DefaultKey
|
||||
}
|
||||
response := madmin.KMSKeyStatus{
|
||||
KeyID: keyID,
|
||||
@@ -2170,7 +2233,10 @@ func (a adminAPIHandlers) KMSKeyStatusHandler(w http.ResponseWriter, r *http.Req
|
||||
|
||||
kmsContext := kms.Context{"MinIO admin API": "KMSKeyStatusHandler"} // Context for a test key operation
|
||||
// 1. Generate a new key using the KMS.
|
||||
key, err := GlobalKMS.GenerateKey(ctx, keyID, kmsContext)
|
||||
key, err := GlobalKMS.GenerateKey(ctx, &kms.GenerateKeyRequest{
|
||||
Name: keyID,
|
||||
AssociatedData: kmsContext,
|
||||
})
|
||||
if err != nil {
|
||||
response.EncryptionErr = err.Error()
|
||||
resp, err := json.Marshal(response)
|
||||
@@ -2183,7 +2249,11 @@ func (a adminAPIHandlers) KMSKeyStatusHandler(w http.ResponseWriter, r *http.Req
|
||||
}
|
||||
|
||||
// 2. Verify that we can indeed decrypt the (encrypted) key
|
||||
decryptedKey, err := GlobalKMS.DecryptKey(key.KeyID, key.Ciphertext, kmsContext)
|
||||
decryptedKey, err := GlobalKMS.Decrypt(ctx, &kms.DecryptRequest{
|
||||
Name: key.KeyID,
|
||||
Ciphertext: key.Ciphertext,
|
||||
AssociatedData: kmsContext,
|
||||
})
|
||||
if err != nil {
|
||||
response.DecryptionErr = err.Error()
|
||||
resp, err := json.Marshal(response)
|
||||
@@ -2336,8 +2406,7 @@ func getServerInfo(ctx context.Context, pools, metrics bool, r *http.Request) ma
|
||||
|
||||
domain := globalDomainNames
|
||||
services := madmin.Services{
|
||||
KMS: fetchKMSStatus(),
|
||||
KMSStatus: fetchKMSStatusV2(ctx),
|
||||
KMSStatus: fetchKMSStatus(ctx),
|
||||
LDAP: ldap,
|
||||
Logger: log,
|
||||
Audit: audit,
|
||||
@@ -2375,7 +2444,7 @@ func getKubernetesInfo(dctx context.Context) madmin.KubernetesInfo {
|
||||
}
|
||||
|
||||
client := &http.Client{
|
||||
Transport: globalHealthChkTransport,
|
||||
Transport: globalRemoteTargetTransport,
|
||||
Timeout: 10 * time.Second,
|
||||
}
|
||||
|
||||
@@ -2800,7 +2869,7 @@ func (a adminAPIHandlers) HealthInfoHandler(w http.ResponseWriter, r *http.Reque
|
||||
w.Header().Get(xhttp.AmzRequestID), w.Header().Get(xhttp.AmzRequestHostID))
|
||||
encodedErrorResponse := encodeResponse(errorResponse)
|
||||
healthInfo.Error = string(encodedErrorResponse)
|
||||
logger.LogIf(ctx, enc.Encode(healthInfo))
|
||||
adminLogIf(ctx, enc.Encode(healthInfo))
|
||||
}
|
||||
|
||||
deadline := 10 * time.Second // Default deadline is 10secs for health diagnostics.
|
||||
@@ -2947,66 +3016,25 @@ func fetchLambdaInfo() []map[string][]madmin.TargetIDStatus {
|
||||
return notify
|
||||
}
|
||||
|
||||
// fetchKMSStatus fetches KMS-related status information.
|
||||
func fetchKMSStatus() madmin.KMS {
|
||||
kmsStat := madmin.KMS{}
|
||||
if GlobalKMS == nil {
|
||||
kmsStat.Status = "disabled"
|
||||
return kmsStat
|
||||
}
|
||||
|
||||
stat, err := GlobalKMS.Stat(context.Background())
|
||||
if err != nil {
|
||||
kmsStat.Status = string(madmin.ItemOffline)
|
||||
return kmsStat
|
||||
}
|
||||
if len(stat.Endpoints) == 0 {
|
||||
kmsStat.Status = stat.Name
|
||||
return kmsStat
|
||||
}
|
||||
kmsStat.Status = string(madmin.ItemOnline)
|
||||
|
||||
kmsContext := kms.Context{"MinIO admin API": "ServerInfoHandler"} // Context for a test key operation
|
||||
// 1. Generate a new key using the KMS.
|
||||
key, err := GlobalKMS.GenerateKey(context.Background(), "", kmsContext)
|
||||
if err != nil {
|
||||
kmsStat.Encrypt = fmt.Sprintf("Encryption failed: %v", err)
|
||||
} else {
|
||||
kmsStat.Encrypt = "success"
|
||||
}
|
||||
|
||||
// 2. Verify that we can indeed decrypt the (encrypted) key
|
||||
decryptedKey, err := GlobalKMS.DecryptKey(key.KeyID, key.Ciphertext, kmsContext)
|
||||
switch {
|
||||
case err != nil:
|
||||
kmsStat.Decrypt = fmt.Sprintf("Decryption failed: %v", err)
|
||||
case subtle.ConstantTimeCompare(key.Plaintext, decryptedKey) != 1:
|
||||
kmsStat.Decrypt = "Decryption failed: decrypted key does not match generated key"
|
||||
default:
|
||||
kmsStat.Decrypt = "success"
|
||||
}
|
||||
return kmsStat
|
||||
}
|
||||
|
||||
// fetchKMSStatusV2 fetches KMS-related status information for all instances
|
||||
func fetchKMSStatusV2(ctx context.Context) []madmin.KMS {
|
||||
// fetchKMSStatus fetches KMS-related status information for all instances
|
||||
func fetchKMSStatus(ctx context.Context) []madmin.KMS {
|
||||
if GlobalKMS == nil {
|
||||
return []madmin.KMS{}
|
||||
}
|
||||
|
||||
results := GlobalKMS.Verify(ctx)
|
||||
|
||||
stats := []madmin.KMS{}
|
||||
for _, result := range results {
|
||||
stats = append(stats, madmin.KMS{
|
||||
Status: result.Status,
|
||||
Endpoint: result.Endpoint,
|
||||
Encrypt: result.Encrypt,
|
||||
Decrypt: result.Decrypt,
|
||||
Version: result.Version,
|
||||
})
|
||||
stat, err := GlobalKMS.Status(ctx)
|
||||
if err != nil {
|
||||
kmsLogIf(ctx, err, "failed to fetch KMS status information")
|
||||
return []madmin.KMS{}
|
||||
}
|
||||
|
||||
stats := make([]madmin.KMS, 0, len(stat.Endpoints))
|
||||
for endpoint, state := range stat.Endpoints {
|
||||
stats = append(stats, madmin.KMS{
|
||||
Status: string(state),
|
||||
Endpoint: endpoint,
|
||||
})
|
||||
}
|
||||
return stats
|
||||
}
|
||||
|
||||
@@ -3113,7 +3141,7 @@ func getClusterMetaInfo(ctx context.Context) []byte {
|
||||
case ci := <-resultCh:
|
||||
out, err := json.MarshalIndent(ci, "", " ")
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
bugLogIf(ctx, err)
|
||||
return nil
|
||||
}
|
||||
return out
|
||||
@@ -3172,11 +3200,11 @@ func (a adminAPIHandlers) InspectDataHandler(w http.ResponseWriter, r *http.Requ
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrInvalidRequest), r.URL)
|
||||
return
|
||||
}
|
||||
file = strings.ReplaceAll(file, string(os.PathSeparator), "/")
|
||||
|
||||
file = filepath.ToSlash(file)
|
||||
// Reject attempts to traverse parent or absolute paths.
|
||||
if strings.Contains(file, "..") || strings.Contains(volume, "..") {
|
||||
writeErrorResponseJSON(ctx, w, errorCodes.ToAPIErr(ErrAccessDenied), r.URL)
|
||||
if hasBadPathComponent(volume) || hasBadPathComponent(file) {
|
||||
writeErrorResponse(r.Context(), w, errorCodes.ToAPIErr(ErrInvalidResourceName), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
@@ -3195,6 +3223,7 @@ func (a adminAPIHandlers) InspectDataHandler(w http.ResponseWriter, r *http.Requ
|
||||
return
|
||||
}
|
||||
}
|
||||
addErr := func(msg string) {}
|
||||
|
||||
// Write a version for making *incompatible* changes.
|
||||
// The AdminClient will reject any version it does not know.
|
||||
@@ -3206,18 +3235,18 @@ func (a adminAPIHandlers) InspectDataHandler(w http.ResponseWriter, r *http.Requ
|
||||
|
||||
clusterKey, err := bytesToPublicKey(getSubnetAdminPublicKey())
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, stream.AddError(err.Error()))
|
||||
bugLogIf(ctx, stream.AddError(err.Error()))
|
||||
return
|
||||
}
|
||||
err = stream.AddKeyEncrypted(clusterKey)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, stream.AddError(err.Error()))
|
||||
bugLogIf(ctx, stream.AddError(err.Error()))
|
||||
return
|
||||
}
|
||||
if b := getClusterMetaInfo(ctx); len(b) > 0 {
|
||||
w, err := stream.AddEncryptedStream("cluster.info", nil)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
bugLogIf(ctx, err)
|
||||
return
|
||||
}
|
||||
w.Write(b)
|
||||
@@ -3226,14 +3255,19 @@ func (a adminAPIHandlers) InspectDataHandler(w http.ResponseWriter, r *http.Requ
|
||||
|
||||
// Add new key for inspect data.
|
||||
if err := stream.AddKeyEncrypted(publicKey); err != nil {
|
||||
logger.LogIf(ctx, stream.AddError(err.Error()))
|
||||
bugLogIf(ctx, stream.AddError(err.Error()))
|
||||
return
|
||||
}
|
||||
encStream, err := stream.AddEncryptedStream("inspect.zip", nil)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, stream.AddError(err.Error()))
|
||||
bugLogIf(ctx, stream.AddError(err.Error()))
|
||||
return
|
||||
}
|
||||
addErr = func(msg string) {
|
||||
inspectZipW.Close()
|
||||
encStream.Close()
|
||||
stream.AddError(msg)
|
||||
}
|
||||
defer encStream.Close()
|
||||
|
||||
inspectZipW = zip.NewWriter(encStream)
|
||||
@@ -3244,7 +3278,7 @@ func (a adminAPIHandlers) InspectDataHandler(w http.ResponseWriter, r *http.Requ
|
||||
// MUST use crypto/rand
|
||||
n, err := crand.Read(key[:])
|
||||
if err != nil || n != len(key) {
|
||||
logger.LogIf(ctx, err)
|
||||
bugLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAdminAPIErr(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -3258,7 +3292,7 @@ func (a adminAPIHandlers) InspectDataHandler(w http.ResponseWriter, r *http.Requ
|
||||
|
||||
stream, err := sio.AES_256_GCM.Stream(key[:])
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
bugLogIf(ctx, err)
|
||||
return
|
||||
}
|
||||
// Zero nonce, we only use each key once, and 32 bytes is plenty.
|
||||
@@ -3272,7 +3306,7 @@ func (a adminAPIHandlers) InspectDataHandler(w http.ResponseWriter, r *http.Requ
|
||||
defer inspectZipW.Close()
|
||||
|
||||
if b := getClusterMetaInfo(ctx); len(b) > 0 {
|
||||
logger.LogIf(ctx, embedFileInZip(inspectZipW, "cluster.info", b, 0o600))
|
||||
adminLogIf(ctx, embedFileInZip(inspectZipW, "cluster.info", b, 0o600))
|
||||
}
|
||||
}
|
||||
|
||||
@@ -3300,32 +3334,20 @@ func (a adminAPIHandlers) InspectDataHandler(w http.ResponseWriter, r *http.Requ
|
||||
sys: nil,
|
||||
})
|
||||
if zerr != nil {
|
||||
logger.LogIf(ctx, zerr)
|
||||
bugLogIf(ctx, zerr)
|
||||
return nil
|
||||
}
|
||||
header.Method = zip.Deflate
|
||||
zwriter, zerr := inspectZipW.CreateHeader(header)
|
||||
if zerr != nil {
|
||||
logger.LogIf(ctx, zerr)
|
||||
bugLogIf(ctx, zerr)
|
||||
return nil
|
||||
}
|
||||
if _, err := io.Copy(zwriter, r); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
adminLogIf(ctx, err)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
err := o.GetRawData(ctx, volume, file, rawDataFn)
|
||||
if !errors.Is(err, errFileNotFound) {
|
||||
logger.LogIf(ctx, err)
|
||||
}
|
||||
|
||||
// save the format.json as part of inspect by default
|
||||
if !(volume == minioMetaBucket && file == formatConfigFile) {
|
||||
err = o.GetRawData(ctx, minioMetaBucket, formatConfigFile, rawDataFn)
|
||||
}
|
||||
if !errors.Is(err, errFileNotFound) {
|
||||
logger.LogIf(ctx, err)
|
||||
}
|
||||
|
||||
// save args passed to inspect command
|
||||
var sb bytes.Buffer
|
||||
@@ -3336,7 +3358,25 @@ func (a adminAPIHandlers) InspectDataHandler(w http.ResponseWriter, r *http.Requ
|
||||
sb.WriteString(pool.CmdLine)
|
||||
}
|
||||
sb.WriteString("\n")
|
||||
logger.LogIf(ctx, embedFileInZip(inspectZipW, "inspect-input.txt", sb.Bytes(), 0o600))
|
||||
adminLogIf(ctx, embedFileInZip(inspectZipW, "inspect-input.txt", sb.Bytes(), 0o600))
|
||||
|
||||
err := o.GetRawData(ctx, volume, file, rawDataFn)
|
||||
if err != nil {
|
||||
if errors.Is(err, errFileNotFound) {
|
||||
addErr("GetRawData: No files matched the given pattern")
|
||||
return
|
||||
}
|
||||
embedFileInZip(inspectZipW, "GetRawData-err.txt", []byte(err.Error()), 0o600)
|
||||
adminLogIf(ctx, err)
|
||||
}
|
||||
|
||||
// save the format.json as part of inspect by default
|
||||
if !(volume == minioMetaBucket && file == formatConfigFile) {
|
||||
err = o.GetRawData(ctx, minioMetaBucket, formatConfigFile, rawDataFn)
|
||||
}
|
||||
if !errors.Is(err, errFileNotFound) {
|
||||
adminLogIf(ctx, err)
|
||||
}
|
||||
|
||||
scheme := "https"
|
||||
if !globalIsTLS {
|
||||
@@ -3370,7 +3410,7 @@ function main() {
|
||||
}
|
||||
|
||||
main "$@"`, scheme)
|
||||
logger.LogIf(ctx, embedFileInZip(inspectZipW, "start-minio.sh", scrb.Bytes(), 0o755))
|
||||
adminLogIf(ctx, embedFileInZip(inspectZipW, "start-minio.sh", scrb.Bytes(), 0o755))
|
||||
}
|
||||
|
||||
func getSubnetAdminPublicKey() []byte {
|
||||
|
||||
+47
-38
@@ -63,8 +63,8 @@ const (
|
||||
)
|
||||
|
||||
var (
|
||||
errHealIdleTimeout = fmt.Errorf("healing results were not consumed for too long")
|
||||
errHealStopSignalled = fmt.Errorf("heal stop signaled")
|
||||
errHealIdleTimeout = errors.New("healing results were not consumed for too long")
|
||||
errHealStopSignalled = errors.New("heal stop signaled")
|
||||
|
||||
errFnHealFromAPIErr = func(ctx context.Context, err error) error {
|
||||
apiErr := toAdminAPIErr(ctx, err)
|
||||
@@ -329,21 +329,25 @@ func (ahs *allHealState) LaunchNewHealSequence(h *healSequence, objAPI ObjectLay
|
||||
// Add heal state and start sequence
|
||||
ahs.healSeqMap[hpath] = h
|
||||
|
||||
// Launch top-level background heal go-routine
|
||||
go h.healSequenceStart(objAPI)
|
||||
|
||||
clientToken := h.clientToken
|
||||
if globalIsDistErasure {
|
||||
clientToken = fmt.Sprintf("%s:%d", h.clientToken, GetProxyEndpointLocalIndex(globalProxyEndpoints))
|
||||
}
|
||||
|
||||
if h.clientToken == bgHealingUUID {
|
||||
// For background heal do nothing, do not spawn an unnecessary goroutine.
|
||||
} else {
|
||||
// Launch top-level background heal go-routine
|
||||
go h.healSequenceStart(objAPI)
|
||||
}
|
||||
|
||||
b, err := json.Marshal(madmin.HealStartSuccess{
|
||||
ClientToken: clientToken,
|
||||
ClientAddress: h.clientAddress,
|
||||
StartTime: h.startTime,
|
||||
})
|
||||
if err != nil {
|
||||
logger.LogIf(h.ctx, err)
|
||||
bugLogIf(h.ctx, err)
|
||||
return nil, toAdminAPIErr(h.ctx, err), ""
|
||||
}
|
||||
return b, noError, ""
|
||||
@@ -390,7 +394,7 @@ func (ahs *allHealState) PopHealStatusJSON(hpath string,
|
||||
if err != nil {
|
||||
h.currentStatus.Items = nil
|
||||
|
||||
logger.LogIf(h.ctx, err)
|
||||
bugLogIf(h.ctx, err)
|
||||
return nil, ErrInternalError
|
||||
}
|
||||
|
||||
@@ -451,8 +455,8 @@ type healSequence struct {
|
||||
// Number of total items healed against item type
|
||||
healedItemsMap map[madmin.HealItemType]int64
|
||||
|
||||
// Number of total items where healing failed against endpoint and drive state
|
||||
healFailedItemsMap map[string]int64
|
||||
// Number of total items where healing failed against item type
|
||||
healFailedItemsMap map[madmin.HealItemType]int64
|
||||
|
||||
// The time of the last scan/heal activity
|
||||
lastHealActivity time.Time
|
||||
@@ -493,7 +497,7 @@ func newHealSequence(ctx context.Context, bucket, objPrefix, clientAddr string,
|
||||
ctx: ctx,
|
||||
scannedItemsMap: make(map[madmin.HealItemType]int64),
|
||||
healedItemsMap: make(map[madmin.HealItemType]int64),
|
||||
healFailedItemsMap: make(map[string]int64),
|
||||
healFailedItemsMap: make(map[madmin.HealItemType]int64),
|
||||
}
|
||||
}
|
||||
|
||||
@@ -537,14 +541,14 @@ func (h *healSequence) getHealedItemsMap() map[madmin.HealItemType]int64 {
|
||||
return retMap
|
||||
}
|
||||
|
||||
// gethealFailedItemsMap - returns map of all items where heal failed against
|
||||
// getHealFailedItemsMap - returns map of all items where heal failed against
|
||||
// drive endpoint and status
|
||||
func (h *healSequence) gethealFailedItemsMap() map[string]int64 {
|
||||
func (h *healSequence) getHealFailedItemsMap() map[madmin.HealItemType]int64 {
|
||||
h.mutex.RLock()
|
||||
defer h.mutex.RUnlock()
|
||||
|
||||
// Make a copy before returning the value
|
||||
retMap := make(map[string]int64, len(h.healFailedItemsMap))
|
||||
retMap := make(map[madmin.HealItemType]int64, len(h.healFailedItemsMap))
|
||||
for k, v := range h.healFailedItemsMap {
|
||||
retMap[k] = v
|
||||
}
|
||||
@@ -552,6 +556,30 @@ func (h *healSequence) gethealFailedItemsMap() map[string]int64 {
|
||||
return retMap
|
||||
}
|
||||
|
||||
func (h *healSequence) countFailed(healType madmin.HealItemType) {
|
||||
h.mutex.Lock()
|
||||
defer h.mutex.Unlock()
|
||||
|
||||
h.healFailedItemsMap[healType]++
|
||||
h.lastHealActivity = UTCNow()
|
||||
}
|
||||
|
||||
func (h *healSequence) countScanned(healType madmin.HealItemType) {
|
||||
h.mutex.Lock()
|
||||
defer h.mutex.Unlock()
|
||||
|
||||
h.scannedItemsMap[healType]++
|
||||
h.lastHealActivity = UTCNow()
|
||||
}
|
||||
|
||||
func (h *healSequence) countHealed(healType madmin.HealItemType) {
|
||||
h.mutex.Lock()
|
||||
defer h.mutex.Unlock()
|
||||
|
||||
h.healedItemsMap[healType]++
|
||||
h.lastHealActivity = UTCNow()
|
||||
}
|
||||
|
||||
// isQuitting - determines if the heal sequence is quitting (due to an
|
||||
// external signal)
|
||||
func (h *healSequence) isQuitting() bool {
|
||||
@@ -704,10 +732,7 @@ func (h *healSequence) queueHealTask(source healSource, healType madmin.HealItem
|
||||
task.opts.ScanMode = madmin.HealNormalScan
|
||||
}
|
||||
|
||||
h.mutex.Lock()
|
||||
h.scannedItemsMap[healType]++
|
||||
h.lastHealActivity = UTCNow()
|
||||
h.mutex.Unlock()
|
||||
h.countScanned(healType)
|
||||
|
||||
if source.noWait {
|
||||
select {
|
||||
@@ -739,37 +764,21 @@ func (h *healSequence) queueHealTask(source healSource, healType madmin.HealItem
|
||||
// task queued, now wait for the response.
|
||||
select {
|
||||
case res := <-task.respCh:
|
||||
if res.err == nil {
|
||||
h.countHealed(healType)
|
||||
} else {
|
||||
h.countFailed(healType)
|
||||
}
|
||||
if !h.reportProgress {
|
||||
if errors.Is(res.err, errSkipFile) { // this is only sent usually by nopHeal
|
||||
return nil
|
||||
}
|
||||
|
||||
h.mutex.Lock()
|
||||
defer h.mutex.Unlock()
|
||||
|
||||
// Progress is not reported in case of background heal processing.
|
||||
// Instead we increment relevant counter based on the heal result
|
||||
// for prometheus reporting.
|
||||
if res.err != nil {
|
||||
for _, d := range res.result.After.Drives {
|
||||
// For failed items we report the endpoint and drive state
|
||||
// This will help users take corrective actions for drives
|
||||
h.healFailedItemsMap[d.Endpoint+","+d.State]++
|
||||
}
|
||||
} else {
|
||||
// Only object type reported for successful healing
|
||||
h.healedItemsMap[res.result.Type]++
|
||||
}
|
||||
|
||||
// Report caller of any failure
|
||||
return res.err
|
||||
}
|
||||
res.result.Type = healType
|
||||
if res.err != nil {
|
||||
// Only report object error
|
||||
if healType != madmin.HealItemObject {
|
||||
return res.err
|
||||
}
|
||||
res.result.Detail = res.err.Error()
|
||||
}
|
||||
return h.pushHealResultItem(res.result)
|
||||
|
||||
@@ -31,7 +31,6 @@ import (
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio/internal/config"
|
||||
"github.com/minio/minio/internal/kms"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
)
|
||||
|
||||
// getLocalServerProperty - returns madmin.ServerProperties for only the
|
||||
@@ -67,7 +66,7 @@ func getLocalServerProperty(endpointServerPools EndpointServerPools, r *http.Req
|
||||
} else {
|
||||
network[nodeName] = string(madmin.ItemOffline)
|
||||
// log once the error
|
||||
logger.LogOnceIf(context.Background(), err, nodeName)
|
||||
peersLogOnceIf(context.Background(), err, nodeName)
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
+64
-26
@@ -56,19 +56,23 @@ type APIError struct {
|
||||
Code string
|
||||
Description string
|
||||
HTTPStatusCode int
|
||||
ObjectSize string
|
||||
RangeRequested string
|
||||
}
|
||||
|
||||
// APIErrorResponse - error response format
|
||||
type APIErrorResponse struct {
|
||||
XMLName xml.Name `xml:"Error" json:"-"`
|
||||
Code string
|
||||
Message string
|
||||
Key string `xml:"Key,omitempty" json:"Key,omitempty"`
|
||||
BucketName string `xml:"BucketName,omitempty" json:"BucketName,omitempty"`
|
||||
Resource string
|
||||
Region string `xml:"Region,omitempty" json:"Region,omitempty"`
|
||||
RequestID string `xml:"RequestId" json:"RequestId"`
|
||||
HostID string `xml:"HostId" json:"HostId"`
|
||||
ActualObjectSize string `xml:"ActualObjectSize,omitempty" json:"ActualObjectSize,omitempty"`
|
||||
RangeRequested string `xml:"RangeRequested,omitempty" json:"RangeRequested,omitempty"`
|
||||
}
|
||||
|
||||
// APIErrorCode type of error status.
|
||||
@@ -263,6 +267,7 @@ const (
|
||||
ErrInvalidResourceName
|
||||
ErrInvalidLifecycleQueryParameter
|
||||
ErrServerNotInitialized
|
||||
ErrBucketMetadataNotInitialized
|
||||
ErrRequestTimedout
|
||||
ErrClientDisconnected
|
||||
ErrTooManyRequests
|
||||
@@ -278,6 +283,7 @@ const (
|
||||
ErrMalformedJSON
|
||||
ErrAdminNoSuchUser
|
||||
ErrAdminNoSuchUserLDAPWarn
|
||||
ErrAdminLDAPExpectedLoginName
|
||||
ErrAdminNoSuchGroup
|
||||
ErrAdminGroupNotEmpty
|
||||
ErrAdminGroupDisabled
|
||||
@@ -300,6 +306,7 @@ const (
|
||||
ErrAdminConfigIDPCfgNameDoesNotExist
|
||||
ErrInsecureClientRequest
|
||||
ErrObjectTampered
|
||||
ErrAdminLDAPNotEnabled
|
||||
|
||||
// Site-Replication errors
|
||||
ErrSiteReplicationInvalidRequest
|
||||
@@ -1293,7 +1300,12 @@ var errorCodes = errorCodeMap{
|
||||
},
|
||||
ErrServerNotInitialized: {
|
||||
Code: "XMinioServerNotInitialized",
|
||||
Description: "Server not initialized, please try again.",
|
||||
Description: "Server not initialized yet, please try again.",
|
||||
HTTPStatusCode: http.StatusServiceUnavailable,
|
||||
},
|
||||
ErrBucketMetadataNotInitialized: {
|
||||
Code: "XMinioBucketMetadataNotInitialized",
|
||||
Description: "Bucket metadata not initialized yet, please try again.",
|
||||
HTTPStatusCode: http.StatusServiceUnavailable,
|
||||
},
|
||||
ErrMalformedJSON: {
|
||||
@@ -1466,7 +1478,7 @@ var errorCodes = errorCodeMap{
|
||||
ErrTooManyRequests: {
|
||||
Code: "TooManyRequests",
|
||||
Description: "Deadline exceeded while waiting in incoming queue, please reduce your request rate",
|
||||
HTTPStatusCode: http.StatusServiceUnavailable,
|
||||
HTTPStatusCode: http.StatusTooManyRequests,
|
||||
},
|
||||
ErrUnsupportedMetadata: {
|
||||
Code: "InvalidArgument",
|
||||
@@ -2079,7 +2091,16 @@ var errorCodes = errorCodeMap{
|
||||
Description: "Invalid attribute name specified.",
|
||||
HTTPStatusCode: http.StatusBadRequest,
|
||||
},
|
||||
// Add your error structure here.
|
||||
ErrAdminLDAPNotEnabled: {
|
||||
Code: "XMinioLDAPNotEnabled",
|
||||
Description: "LDAP is not enabled. LDAP must be enabled to make LDAP requests.",
|
||||
HTTPStatusCode: http.StatusNotImplemented,
|
||||
},
|
||||
ErrAdminLDAPExpectedLoginName: {
|
||||
Code: "XMinioLDAPExpectedLoginName",
|
||||
Description: "Expected LDAP short username but was given full DN.",
|
||||
HTTPStatusCode: http.StatusBadRequest,
|
||||
},
|
||||
}
|
||||
|
||||
// toAPIErrorCode - Converts embedded errors. Convenience
|
||||
@@ -2200,6 +2221,10 @@ func toAPIErrorCode(ctx context.Context, err error) (apiErr APIErrorCode) {
|
||||
apiErr = ErrInvalidMaxParts
|
||||
case ioutil.ErrOverread:
|
||||
apiErr = ErrExcessData
|
||||
case errServerNotInitialized:
|
||||
apiErr = ErrServerNotInitialized
|
||||
case errBucketMetadataNotInitialized:
|
||||
apiErr = ErrBucketMetadataNotInitialized
|
||||
}
|
||||
|
||||
// Compression errors
|
||||
@@ -2391,10 +2416,9 @@ func toAPIError(ctx context.Context, err error) APIError {
|
||||
apiErr := errorCodes.ToAPIErr(toAPIErrorCode(ctx, err))
|
||||
switch apiErr.Code {
|
||||
case "NotImplemented":
|
||||
desc := fmt.Sprintf("%s (%v)", apiErr.Description, err)
|
||||
apiErr = APIError{
|
||||
Code: apiErr.Code,
|
||||
Description: desc,
|
||||
Description: fmt.Sprintf("%s (%v)", apiErr.Description, err),
|
||||
HTTPStatusCode: apiErr.HTTPStatusCode,
|
||||
}
|
||||
case "XMinioBackendDown":
|
||||
@@ -2406,12 +2430,24 @@ func toAPIError(ctx context.Context, err error) APIError {
|
||||
switch e := err.(type) {
|
||||
case kms.Error:
|
||||
apiErr = APIError{
|
||||
Description: e.Err.Error(),
|
||||
Code: e.APICode,
|
||||
HTTPStatusCode: e.HTTPStatusCode,
|
||||
Description: e.Err,
|
||||
HTTPStatusCode: e.Code,
|
||||
}
|
||||
case batchReplicationJobError:
|
||||
apiErr = APIError(e)
|
||||
apiErr = APIError{
|
||||
Description: e.Description,
|
||||
Code: e.Code,
|
||||
HTTPStatusCode: e.HTTPStatusCode,
|
||||
}
|
||||
case InvalidRange:
|
||||
apiErr = APIError{
|
||||
Code: "InvalidRange",
|
||||
Description: e.Error(),
|
||||
HTTPStatusCode: errorCodes[ErrInvalidRange].HTTPStatusCode,
|
||||
ObjectSize: strconv.FormatInt(e.ResourceSize, 10),
|
||||
RangeRequested: fmt.Sprintf("%d-%d", e.OffsetBegin, e.OffsetEnd),
|
||||
}
|
||||
case InvalidArgument:
|
||||
apiErr = APIError{
|
||||
Code: "InvalidArgument",
|
||||
@@ -2519,7 +2555,7 @@ func toAPIError(ctx context.Context, err error) APIError {
|
||||
// Make sure to log the errors which we cannot translate
|
||||
// to a meaningful S3 API errors. This is added to aid in
|
||||
// debugging unexpected/unhandled errors.
|
||||
logger.LogIf(ctx, err)
|
||||
internalLogIf(ctx, err)
|
||||
}
|
||||
|
||||
return apiErr
|
||||
@@ -2538,13 +2574,15 @@ func getAPIError(code APIErrorCode) APIError {
|
||||
func getAPIErrorResponse(ctx context.Context, err APIError, resource, requestID, hostID string) APIErrorResponse {
|
||||
reqInfo := logger.GetReqInfo(ctx)
|
||||
return APIErrorResponse{
|
||||
Code: err.Code,
|
||||
Message: err.Description,
|
||||
BucketName: reqInfo.BucketName,
|
||||
Key: reqInfo.ObjectName,
|
||||
Resource: resource,
|
||||
Region: globalSite.Region,
|
||||
RequestID: requestID,
|
||||
HostID: hostID,
|
||||
Code: err.Code,
|
||||
Message: err.Description,
|
||||
BucketName: reqInfo.BucketName,
|
||||
Key: reqInfo.ObjectName,
|
||||
Resource: resource,
|
||||
Region: globalSite.Region,
|
||||
RequestID: requestID,
|
||||
HostID: hostID,
|
||||
ActualObjectSize: err.ObjectSize,
|
||||
RangeRequested: err.RangeRequested,
|
||||
}
|
||||
}
|
||||
|
||||
+2
-3
@@ -30,7 +30,6 @@ import (
|
||||
"github.com/minio/minio-go/v7/pkg/tags"
|
||||
"github.com/minio/minio/internal/crypto"
|
||||
xhttp "github.com/minio/minio/internal/http"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
xxml "github.com/minio/xxml"
|
||||
)
|
||||
|
||||
@@ -68,7 +67,7 @@ func encodeResponse(response interface{}) []byte {
|
||||
var buf bytes.Buffer
|
||||
buf.WriteString(xml.Header)
|
||||
if err := xml.NewEncoder(&buf).Encode(response); err != nil {
|
||||
logger.LogIf(GlobalContext, err)
|
||||
bugLogIf(GlobalContext, err)
|
||||
return nil
|
||||
}
|
||||
return buf.Bytes()
|
||||
@@ -86,7 +85,7 @@ func encodeResponseList(response interface{}) []byte {
|
||||
var buf bytes.Buffer
|
||||
buf.WriteString(xxml.Header)
|
||||
if err := xxml.NewEncoder(&buf).Encode(response); err != nil {
|
||||
logger.LogIf(GlobalContext, err)
|
||||
bugLogIf(GlobalContext, err)
|
||||
return nil
|
||||
}
|
||||
return buf.Bytes()
|
||||
|
||||
+2
-2
@@ -891,7 +891,7 @@ func writeResponse(w http.ResponseWriter, statusCode int, response []byte, mType
|
||||
}
|
||||
// Similar check to http.checkWriteHeaderCode
|
||||
if statusCode < 100 || statusCode > 999 {
|
||||
logger.LogIf(context.Background(), fmt.Errorf("invalid WriteHeader code %v", statusCode))
|
||||
bugLogIf(context.Background(), fmt.Errorf("invalid WriteHeader code %v", statusCode))
|
||||
statusCode = http.StatusInternalServerError
|
||||
}
|
||||
setCommonHeaders(w)
|
||||
@@ -961,7 +961,7 @@ func writeErrorResponse(ctx context.Context, w http.ResponseWriter, err APIError
|
||||
|
||||
// Similar check to http.checkWriteHeaderCode
|
||||
if err.HTTPStatusCode < 100 || err.HTTPStatusCode > 999 {
|
||||
logger.LogIf(ctx, fmt.Errorf("invalid WriteHeader code %v from %v", err.HTTPStatusCode, err.Code))
|
||||
bugLogIf(ctx, fmt.Errorf("invalid WriteHeader code %v from %v", err.HTTPStatusCode, err.Code))
|
||||
err.HTTPStatusCode = http.StatusInternalServerError
|
||||
}
|
||||
|
||||
|
||||
+157
-154
File diff suppressed because one or more lines are too long
+4
-4
@@ -126,7 +126,7 @@ func getRequestAuthType(r *http.Request) (at authType) {
|
||||
var err error
|
||||
r.Form, err = url.ParseQuery(r.URL.RawQuery)
|
||||
if err != nil {
|
||||
logger.LogIf(r.Context(), err)
|
||||
authNLogIf(r.Context(), err)
|
||||
return authTypeUnknown
|
||||
}
|
||||
}
|
||||
@@ -257,7 +257,7 @@ func getClaimsFromTokenWithSecret(token, secret string) (map[string]interface{},
|
||||
if err != nil {
|
||||
// Base64 decoding fails, we should log to indicate
|
||||
// something is malforming the request sent by client.
|
||||
logger.LogIf(GlobalContext, err, logger.ErrorKind)
|
||||
authNLogIf(GlobalContext, err, logger.ErrorKind)
|
||||
return nil, errAuthentication
|
||||
}
|
||||
claims.MapClaims[sessionPolicyNameExtracted] = string(spBytes)
|
||||
@@ -353,7 +353,7 @@ func checkRequestAuthTypeWithVID(ctx context.Context, r *http.Request, action po
|
||||
|
||||
func authenticateRequest(ctx context.Context, r *http.Request, action policy.Action) (s3Err APIErrorCode) {
|
||||
if logger.GetReqInfo(ctx) == nil {
|
||||
logger.LogIf(ctx, errors.New("unexpected context.Context does not have a logger.ReqInfo"), logger.ErrorKind)
|
||||
bugLogIf(ctx, errors.New("unexpected context.Context does not have a logger.ReqInfo"), logger.ErrorKind)
|
||||
return ErrAccessDenied
|
||||
}
|
||||
|
||||
@@ -392,7 +392,7 @@ func authenticateRequest(ctx context.Context, r *http.Request, action policy.Act
|
||||
// To extract region from XML in request body, get copy of request body.
|
||||
payload, err := io.ReadAll(io.LimitReader(r.Body, maxLocationConstraintSize))
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err, logger.ErrorKind)
|
||||
authZLogIf(ctx, err, logger.ErrorKind)
|
||||
return ErrMalformedXML
|
||||
}
|
||||
|
||||
|
||||
@@ -25,7 +25,6 @@ import (
|
||||
"time"
|
||||
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/env"
|
||||
)
|
||||
|
||||
@@ -101,16 +100,17 @@ func waitForLowHTTPReq() {
|
||||
}
|
||||
|
||||
func initBackgroundHealing(ctx context.Context, objAPI ObjectLayer) {
|
||||
bgSeq := newBgHealSequence()
|
||||
// Run the background healer
|
||||
for i := 0; i < globalBackgroundHealRoutine.workers; i++ {
|
||||
go globalBackgroundHealRoutine.AddWorker(ctx, objAPI)
|
||||
go globalBackgroundHealRoutine.AddWorker(ctx, objAPI, bgSeq)
|
||||
}
|
||||
|
||||
globalBackgroundHealState.LaunchNewHealSequence(newBgHealSequence(), objAPI)
|
||||
globalBackgroundHealState.LaunchNewHealSequence(bgSeq, objAPI)
|
||||
}
|
||||
|
||||
// Wait for heal requests and process them
|
||||
func (h *healRoutine) AddWorker(ctx context.Context, objAPI ObjectLayer) {
|
||||
func (h *healRoutine) AddWorker(ctx context.Context, objAPI ObjectLayer, bgSeq *healSequence) {
|
||||
for {
|
||||
select {
|
||||
case task, ok := <-h.tasks:
|
||||
@@ -135,8 +135,18 @@ func (h *healRoutine) AddWorker(ctx context.Context, objAPI ObjectLayer) {
|
||||
|
||||
if task.respCh != nil {
|
||||
task.respCh <- healResult{result: res, err: err}
|
||||
continue
|
||||
}
|
||||
|
||||
// when respCh is not set caller is not waiting but we
|
||||
// update the relevant metrics for them
|
||||
if bgSeq != nil {
|
||||
if err == nil {
|
||||
bgSeq.countHealed(res.Type)
|
||||
} else {
|
||||
bgSeq.countFailed(res.Type)
|
||||
}
|
||||
}
|
||||
case <-ctx.Done():
|
||||
return
|
||||
}
|
||||
@@ -148,7 +158,7 @@ func newHealRoutine() *healRoutine {
|
||||
|
||||
if envHealWorkers := env.Get("_MINIO_HEAL_WORKERS", ""); envHealWorkers != "" {
|
||||
if numHealers, err := strconv.Atoi(envHealWorkers); err != nil {
|
||||
logger.LogIf(context.Background(), fmt.Errorf("invalid _MINIO_HEAL_WORKERS value: %w", err))
|
||||
bugLogIf(context.Background(), fmt.Errorf("invalid _MINIO_HEAL_WORKERS value: %w", err))
|
||||
} else {
|
||||
workers = numHealers
|
||||
}
|
||||
|
||||
@@ -33,7 +33,6 @@ import (
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio-go/v7/pkg/set"
|
||||
"github.com/minio/minio/internal/config"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/env"
|
||||
)
|
||||
|
||||
@@ -409,11 +408,11 @@ func healFreshDisk(ctx context.Context, z *erasureServerPools, endpoint Endpoint
|
||||
if errors.Is(err, errFileNotFound) {
|
||||
return nil
|
||||
}
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to load healing tracker on '%s': %w, re-initializing..", disk, err))
|
||||
healingLogIf(ctx, fmt.Errorf("Unable to load healing tracker on '%s': %w, re-initializing..", disk, err))
|
||||
tracker = initHealingTracker(disk, mustGetUUID())
|
||||
}
|
||||
|
||||
logger.Event(ctx, "Healing drive '%s' - 'mc admin heal alias/ --verbose' to check the current status.", endpoint)
|
||||
healingLogEvent(ctx, "Healing drive '%s' - 'mc admin heal alias/ --verbose' to check the current status.", endpoint)
|
||||
|
||||
buckets, _ := z.ListBuckets(ctx, BucketOptions{})
|
||||
// Buckets data are dispersed in multiple pools/sets, make
|
||||
@@ -452,7 +451,7 @@ func healFreshDisk(ctx context.Context, z *erasureServerPools, endpoint Endpoint
|
||||
return err
|
||||
}
|
||||
|
||||
logger.Event(ctx, "Healing of drive '%s' is finished (healed: %d, skipped: %d, failed: %d).", disk, tracker.ItemsHealed, tracker.ItemsSkipped, tracker.ItemsFailed)
|
||||
healingLogEvent(ctx, "Healing of drive '%s' is finished (healed: %d, skipped: %d, failed: %d).", disk, tracker.ItemsHealed, tracker.ItemsSkipped, tracker.ItemsFailed)
|
||||
|
||||
if len(tracker.QueuedBuckets) > 0 {
|
||||
return fmt.Errorf("not all buckets were healed: %v", tracker.QueuedBuckets)
|
||||
@@ -464,7 +463,7 @@ func healFreshDisk(ctx context.Context, z *erasureServerPools, endpoint Endpoint
|
||||
}
|
||||
|
||||
if tracker.HealID == "" { // HealID was empty only before Feb 2023
|
||||
logger.LogIf(ctx, tracker.delete(ctx))
|
||||
bugLogIf(ctx, tracker.delete(ctx))
|
||||
return nil
|
||||
}
|
||||
|
||||
@@ -482,7 +481,7 @@ func healFreshDisk(ctx context.Context, z *erasureServerPools, endpoint Endpoint
|
||||
t, err := loadHealingTracker(ctx, disk)
|
||||
if err != nil {
|
||||
if !errors.Is(err, errFileNotFound) {
|
||||
logger.LogIf(ctx, err)
|
||||
healingLogIf(ctx, err)
|
||||
}
|
||||
continue
|
||||
}
|
||||
@@ -517,7 +516,7 @@ func monitorLocalDisksAndHeal(ctx context.Context, z *erasureServerPools) {
|
||||
// Reformat disks immediately
|
||||
_, err := z.HealFormat(context.Background(), false)
|
||||
if err != nil && !errors.Is(err, errNoHealRequired) {
|
||||
logger.LogIf(ctx, err)
|
||||
healingLogIf(ctx, err)
|
||||
// Reset for next interval.
|
||||
diskCheckTimer.Reset(defaultMonitorNewDiskInterval)
|
||||
continue
|
||||
|
||||
+32
-25
@@ -33,7 +33,6 @@ import (
|
||||
"github.com/minio/minio/internal/bucket/versioning"
|
||||
xhttp "github.com/minio/minio/internal/http"
|
||||
xioutil "github.com/minio/minio/internal/ioutil"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/env"
|
||||
"github.com/minio/pkg/v2/wildcard"
|
||||
"github.com/minio/pkg/v2/workers"
|
||||
@@ -156,7 +155,7 @@ func (ef BatchJobExpireFilter) Matches(obj ObjectInfo, now time.Time) bool {
|
||||
}
|
||||
default:
|
||||
// we should never come here, Validate should have caught this.
|
||||
logger.LogOnceIf(context.Background(), fmt.Errorf("invalid filter type: %s", ef.Type), ef.Type)
|
||||
batchLogOnceIf(context.Background(), fmt.Errorf("invalid filter type: %s", ef.Type), ef.Type)
|
||||
return false
|
||||
}
|
||||
|
||||
@@ -321,7 +320,7 @@ func (r BatchJobExpire) Notify(ctx context.Context, body io.Reader) error {
|
||||
req.Header.Set("Authorization", r.NotificationCfg.Token)
|
||||
}
|
||||
|
||||
clnt := http.Client{Transport: getRemoteInstanceTransport}
|
||||
clnt := http.Client{Transport: getRemoteInstanceTransport()}
|
||||
resp, err := clnt.Do(req)
|
||||
if err != nil {
|
||||
return err
|
||||
@@ -428,11 +427,12 @@ func batchObjsForDelete(ctx context.Context, r *BatchJobExpire, ri *batchJobInfo
|
||||
}
|
||||
stopFn := globalBatchJobsMetrics.trace(batchJobMetricExpire, ri.JobID, attempts)
|
||||
_, err := api.DeleteObject(ctx, exp.Bucket, encodeDirObject(exp.Name), ObjectOptions{
|
||||
DeletePrefix: true,
|
||||
DeletePrefix: true,
|
||||
DeletePrefixObject: true, // use prefix delete on exact object (this is an optimization to avoid fan-out calls)
|
||||
})
|
||||
if err != nil {
|
||||
stopFn(exp, err)
|
||||
logger.LogIf(ctx, fmt.Errorf("Failed to expire %s/%s versionID=%s due to %v (attempts=%d)", toExpire[i].Bucket, toExpire[i].Name, toExpire[i].VersionID, err, attempts))
|
||||
batchLogIf(ctx, fmt.Errorf("Failed to expire %s/%s versionID=%s due to %v (attempts=%d)", toExpire[i].Bucket, toExpire[i].Name, toExpire[i].VersionID, err, attempts))
|
||||
} else {
|
||||
stopFn(exp, err)
|
||||
success = true
|
||||
@@ -470,19 +470,19 @@ func batchObjsForDelete(ctx context.Context, r *BatchJobExpire, ri *batchJobInfo
|
||||
for i, err := range errs {
|
||||
if err != nil {
|
||||
stopFn(toDelCopy[i], err)
|
||||
logger.LogIf(ctx, fmt.Errorf("Failed to expire %s/%s versionID=%s due to %v (attempts=%d)", ri.Bucket, toDelCopy[i].ObjectName, toDelCopy[i].VersionID, err, attempts))
|
||||
batchLogIf(ctx, fmt.Errorf("Failed to expire %s/%s versionID=%s due to %v (attempts=%d)", ri.Bucket, toDelCopy[i].ObjectName, toDelCopy[i].VersionID, err, attempts))
|
||||
failed++
|
||||
if attempts == retryAttempts { // all retry attempts failed, record failure
|
||||
if oi, ok := oiCache.Get(toDelCopy[i]); ok {
|
||||
ri.trackCurrentBucketObject(r.Bucket, *oi, false)
|
||||
}
|
||||
} else {
|
||||
if oi, ok := oiCache.Get(toDelCopy[i]); ok {
|
||||
ri.trackCurrentBucketObject(r.Bucket, *oi, false, attempts)
|
||||
}
|
||||
if attempts != retryAttempts {
|
||||
// retry
|
||||
toDel = append(toDel, toDelCopy[i])
|
||||
}
|
||||
} else {
|
||||
stopFn(toDelCopy[i], nil)
|
||||
if oi, ok := oiCache.Get(toDelCopy[i]); ok {
|
||||
ri.trackCurrentBucketObject(r.Bucket, *oi, true)
|
||||
ri.trackCurrentBucketObject(r.Bucket, *oi, true, attempts)
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -537,7 +537,7 @@ func (r *BatchJobExpire) Start(ctx context.Context, api ObjectLayer, job BatchJo
|
||||
ctx, cancel := context.WithCancel(ctx)
|
||||
defer cancel()
|
||||
|
||||
results := make(chan ObjectInfo, workerSize)
|
||||
results := make(chan itemOrErr[ObjectInfo], workerSize)
|
||||
if err := api.Walk(ctx, r.Bucket, r.Prefix, results, WalkOptions{
|
||||
Marker: lastObject,
|
||||
LatestOnly: false, // we need to visit all versions of the object to implement purge: retainVersions
|
||||
@@ -556,16 +556,16 @@ func (r *BatchJobExpire) Start(ctx context.Context, api ObjectLayer, job BatchJo
|
||||
select {
|
||||
case <-saveTicker.C:
|
||||
// persist in-memory state to disk after every 10secs.
|
||||
logger.LogIf(ctx, ri.updateAfter(ctx, api, 10*time.Second, job))
|
||||
batchLogIf(ctx, ri.updateAfter(ctx, api, 10*time.Second, job))
|
||||
|
||||
case <-ctx.Done():
|
||||
// persist in-memory state immediately before exiting due to context cancellation.
|
||||
logger.LogIf(ctx, ri.updateAfter(ctx, api, 0, job))
|
||||
batchLogIf(ctx, ri.updateAfter(ctx, api, 0, job))
|
||||
return
|
||||
|
||||
case <-saverQuitCh:
|
||||
// persist in-memory state immediately to disk.
|
||||
logger.LogIf(ctx, ri.updateAfter(ctx, api, 0, job))
|
||||
batchLogIf(ctx, ri.updateAfter(ctx, api, 0, job))
|
||||
return
|
||||
}
|
||||
}
|
||||
@@ -584,11 +584,18 @@ func (r *BatchJobExpire) Start(ctx context.Context, api ObjectLayer, job BatchJo
|
||||
versionsCount int
|
||||
toDel []expireObjInfo
|
||||
)
|
||||
failed := true
|
||||
for result := range results {
|
||||
if result.Err != nil {
|
||||
failed = true
|
||||
batchLogIf(ctx, result.Err)
|
||||
continue
|
||||
}
|
||||
|
||||
// Apply filter to find the matching rule to apply expiry
|
||||
// actions accordingly.
|
||||
// nolint:gocritic
|
||||
if result.IsLatest {
|
||||
if result.Item.IsLatest {
|
||||
// send down filtered entries to be deleted using
|
||||
// DeleteObjects method
|
||||
if len(toDel) > 10 { // batch up to 10 objects/versions to be expired simultaneously.
|
||||
@@ -609,7 +616,7 @@ func (r *BatchJobExpire) Start(ctx context.Context, api ObjectLayer, job BatchJo
|
||||
var match BatchJobExpireFilter
|
||||
var found bool
|
||||
for _, rule := range r.Rules {
|
||||
if rule.Matches(result, now) {
|
||||
if rule.Matches(result.Item, now) {
|
||||
match = rule
|
||||
found = true
|
||||
break
|
||||
@@ -619,18 +626,18 @@ func (r *BatchJobExpire) Start(ctx context.Context, api ObjectLayer, job BatchJo
|
||||
continue
|
||||
}
|
||||
|
||||
prevObj = result
|
||||
prevObj = result.Item
|
||||
matchedFilter = match
|
||||
versionsCount = 1
|
||||
// Include the latest version
|
||||
if matchedFilter.Purge.RetainVersions == 0 {
|
||||
toDel = append(toDel, expireObjInfo{
|
||||
ObjectInfo: result,
|
||||
ObjectInfo: result.Item,
|
||||
ExpireAll: true,
|
||||
})
|
||||
continue
|
||||
}
|
||||
} else if prevObj.Name == result.Name {
|
||||
} else if prevObj.Name == result.Item.Name {
|
||||
if matchedFilter.Purge.RetainVersions == 0 {
|
||||
continue // including latest version in toDel suffices, skipping other versions
|
||||
}
|
||||
@@ -643,7 +650,7 @@ func (r *BatchJobExpire) Start(ctx context.Context, api ObjectLayer, job BatchJo
|
||||
continue // retain versions
|
||||
}
|
||||
toDel = append(toDel, expireObjInfo{
|
||||
ObjectInfo: result,
|
||||
ObjectInfo: result.Item,
|
||||
})
|
||||
}
|
||||
// Send any remaining objects downstream
|
||||
@@ -658,8 +665,8 @@ func (r *BatchJobExpire) Start(ctx context.Context, api ObjectLayer, job BatchJo
|
||||
<-expireDoneCh // waits for the expire goroutine to complete
|
||||
wk.Wait() // waits for all expire workers to retire
|
||||
|
||||
ri.Complete = ri.ObjectsFailed == 0
|
||||
ri.Failed = ri.ObjectsFailed > 0
|
||||
ri.Complete = !failed && ri.ObjectsFailed == 0
|
||||
ri.Failed = failed || ri.ObjectsFailed > 0
|
||||
globalBatchJobsMetrics.save(job.ID, ri)
|
||||
|
||||
// Close the saverQuitCh - this also triggers saving in-memory state
|
||||
@@ -669,7 +676,7 @@ func (r *BatchJobExpire) Start(ctx context.Context, api ObjectLayer, job BatchJo
|
||||
// Notify expire jobs final status to the configured endpoint
|
||||
buf, _ := json.Marshal(ri)
|
||||
if err := r.Notify(context.Background(), bytes.NewReader(buf)); err != nil {
|
||||
logger.LogIf(context.Background(), fmt.Errorf("unable to notify %v", err))
|
||||
batchLogIf(context.Background(), fmt.Errorf("unable to notify %v", err))
|
||||
}
|
||||
|
||||
return nil
|
||||
|
||||
+89
-62
@@ -48,7 +48,6 @@ import (
|
||||
xhttp "github.com/minio/minio/internal/http"
|
||||
"github.com/minio/minio/internal/ioutil"
|
||||
xioutil "github.com/minio/minio/internal/ioutil"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/console"
|
||||
"github.com/minio/pkg/v2/env"
|
||||
"github.com/minio/pkg/v2/policy"
|
||||
@@ -92,7 +91,7 @@ func notifyEndpoint(ctx context.Context, ri *batchJobInfo, endpoint, token strin
|
||||
}
|
||||
req.Header.Set("Content-Type", "application/json")
|
||||
|
||||
clnt := http.Client{Transport: getRemoteInstanceTransport}
|
||||
clnt := http.Client{Transport: getRemoteInstanceTransport()}
|
||||
resp, err := clnt.Do(req)
|
||||
if err != nil {
|
||||
return err
|
||||
@@ -206,7 +205,7 @@ func (r *BatchJobReplicateV1) copyWithMultipartfromSource(ctx context.Context, a
|
||||
if aerr == nil {
|
||||
return
|
||||
}
|
||||
logger.LogIf(ctx,
|
||||
batchLogIf(ctx,
|
||||
fmt.Errorf("trying %s: Unable to cleanup failed multipart replication %s on remote %s/%s: %w - this may consume space on remote cluster",
|
||||
humanize.Ordinal(attempts), res.UploadID, tgtBucket, tgtObject, aerr))
|
||||
attempts++
|
||||
@@ -351,7 +350,7 @@ func (r *BatchJobReplicateV1) StartFromSource(ctx context.Context, api ObjectLay
|
||||
c, err := miniogo.New(u.Host, &miniogo.Options{
|
||||
Creds: credentials.NewStaticV4(cred.AccessKey, cred.SecretKey, cred.SessionToken),
|
||||
Secure: u.Scheme == "https",
|
||||
Transport: getRemoteInstanceTransport,
|
||||
Transport: getRemoteInstanceTransport(),
|
||||
BucketLookup: lookupStyle(r.Source.Path),
|
||||
})
|
||||
if err != nil {
|
||||
@@ -402,7 +401,7 @@ func (r *BatchJobReplicateV1) StartFromSource(ctx context.Context, api ObjectLay
|
||||
} else {
|
||||
if !isErrMethodNotAllowed(ErrorRespToObjectError(err, r.Source.Bucket, obj.Key)) &&
|
||||
!isErrObjectNotFound(ErrorRespToObjectError(err, r.Source.Bucket, obj.Key)) {
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
}
|
||||
continue
|
||||
}
|
||||
@@ -414,7 +413,7 @@ func (r *BatchJobReplicateV1) StartFromSource(ctx context.Context, api ObjectLay
|
||||
} else {
|
||||
if !isErrMethodNotAllowed(ErrorRespToObjectError(err, r.Source.Bucket, obj.Key)) &&
|
||||
!isErrObjectNotFound(ErrorRespToObjectError(err, r.Source.Bucket, obj.Key)) {
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
}
|
||||
continue
|
||||
}
|
||||
@@ -443,15 +442,15 @@ func (r *BatchJobReplicateV1) StartFromSource(ctx context.Context, api ObjectLay
|
||||
return
|
||||
}
|
||||
stopFn(oi, err)
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
success = false
|
||||
} else {
|
||||
stopFn(oi, nil)
|
||||
}
|
||||
ri.trackCurrentBucketObject(r.Target.Bucket, oi, success)
|
||||
ri.trackCurrentBucketObject(r.Target.Bucket, oi, success, attempts)
|
||||
globalBatchJobsMetrics.save(job.ID, ri)
|
||||
// persist in-memory state to disk after every 10secs.
|
||||
logger.LogIf(ctx, ri.updateAfter(ctx, api, 10*time.Second, job))
|
||||
batchLogIf(ctx, ri.updateAfter(ctx, api, 10*time.Second, job))
|
||||
|
||||
if wait := globalBatchConfig.ReplicationWait(); wait > 0 {
|
||||
time.Sleep(wait)
|
||||
@@ -466,10 +465,10 @@ func (r *BatchJobReplicateV1) StartFromSource(ctx context.Context, api ObjectLay
|
||||
|
||||
globalBatchJobsMetrics.save(job.ID, ri)
|
||||
// persist in-memory state to disk.
|
||||
logger.LogIf(ctx, ri.updateAfter(ctx, api, 0, job))
|
||||
batchLogIf(ctx, ri.updateAfter(ctx, api, 0, job))
|
||||
|
||||
if err := r.Notify(ctx, ri); err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to notify %v", err))
|
||||
batchLogIf(ctx, fmt.Errorf("unable to notify %v", err))
|
||||
}
|
||||
|
||||
cancel()
|
||||
@@ -553,7 +552,7 @@ func (r BatchJobReplicateV1) writeAsArchive(ctx context.Context, objAPI ObjectLa
|
||||
VersionID: entry.VersionID,
|
||||
})
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
|
||||
@@ -572,7 +571,7 @@ func (r BatchJobReplicateV1) writeAsArchive(ctx context.Context, objAPI ObjectLa
|
||||
|
||||
opts, err := batchReplicationOpts(ctx, "", gr.ObjInfo)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
|
||||
@@ -691,6 +690,7 @@ type batchJobInfo struct {
|
||||
StartTime time.Time `json:"startTime" msg:"st"`
|
||||
LastUpdate time.Time `json:"lastUpdate" msg:"lu"`
|
||||
RetryAttempts int `json:"retryAttempts" msg:"ra"`
|
||||
Attempts int `json:"attempts" msg:"at"`
|
||||
|
||||
Complete bool `json:"complete" msg:"cmp"`
|
||||
Failed bool `json:"failed" msg:"fld"`
|
||||
@@ -834,13 +834,15 @@ func (ri *batchJobInfo) clone() *batchJobInfo {
|
||||
ObjectsFailed: ri.ObjectsFailed,
|
||||
BytesTransferred: ri.BytesTransferred,
|
||||
BytesFailed: ri.BytesFailed,
|
||||
Attempts: ri.Attempts,
|
||||
}
|
||||
}
|
||||
|
||||
func (ri *batchJobInfo) countItem(size int64, dmarker, success bool) {
|
||||
func (ri *batchJobInfo) countItem(size int64, dmarker, success bool, attempt int) {
|
||||
if ri == nil {
|
||||
return
|
||||
}
|
||||
ri.Attempts++
|
||||
if success {
|
||||
if dmarker {
|
||||
ri.DeleteMarkers++
|
||||
@@ -848,7 +850,19 @@ func (ri *batchJobInfo) countItem(size int64, dmarker, success bool) {
|
||||
ri.Objects++
|
||||
ri.BytesTransferred += size
|
||||
}
|
||||
if attempt > 1 {
|
||||
if dmarker {
|
||||
ri.DeleteMarkersFailed--
|
||||
} else {
|
||||
ri.ObjectsFailed--
|
||||
ri.BytesFailed += size
|
||||
}
|
||||
}
|
||||
} else {
|
||||
if attempt > 1 {
|
||||
// Only count first attempt
|
||||
return
|
||||
}
|
||||
if dmarker {
|
||||
ri.DeleteMarkersFailed++
|
||||
} else {
|
||||
@@ -922,7 +936,7 @@ func (ri *batchJobInfo) trackMultipleObjectVersions(bucket string, info ObjectIn
|
||||
}
|
||||
}
|
||||
|
||||
func (ri *batchJobInfo) trackCurrentBucketObject(bucket string, info ObjectInfo, success bool) {
|
||||
func (ri *batchJobInfo) trackCurrentBucketObject(bucket string, info ObjectInfo, success bool, attempt int) {
|
||||
if ri == nil {
|
||||
return
|
||||
}
|
||||
@@ -932,7 +946,7 @@ func (ri *batchJobInfo) trackCurrentBucketObject(bucket string, info ObjectInfo,
|
||||
|
||||
ri.Bucket = bucket
|
||||
ri.Object = info.Name
|
||||
ri.countItem(info.Size, info.DeleteMarker, success)
|
||||
ri.countItem(info.Size, info.DeleteMarker, success, attempt)
|
||||
}
|
||||
|
||||
func (ri *batchJobInfo) trackCurrentBucketBatch(bucket string, batch []ObjectInfo) {
|
||||
@@ -946,7 +960,7 @@ func (ri *batchJobInfo) trackCurrentBucketBatch(bucket string, batch []ObjectInf
|
||||
ri.Bucket = bucket
|
||||
for i := range batch {
|
||||
ri.Object = batch[i].Name
|
||||
ri.countItem(batch[i].Size, batch[i].DeleteMarker, true)
|
||||
ri.countItem(batch[i].Size, batch[i].DeleteMarker, true, 1)
|
||||
}
|
||||
}
|
||||
|
||||
@@ -1048,7 +1062,7 @@ func (r *BatchJobReplicateV1) Start(ctx context.Context, api ObjectLayer, job Ba
|
||||
c, err := miniogo.NewCore(u.Host, &miniogo.Options{
|
||||
Creds: credentials.NewStaticV4(cred.AccessKey, cred.SecretKey, cred.SessionToken),
|
||||
Secure: u.Scheme == "https",
|
||||
Transport: getRemoteInstanceTransport,
|
||||
Transport: getRemoteInstanceTransport(),
|
||||
BucketLookup: lookupStyle(r.Target.Path),
|
||||
})
|
||||
if err != nil {
|
||||
@@ -1058,8 +1072,8 @@ func (r *BatchJobReplicateV1) Start(ctx context.Context, api ObjectLayer, job Ba
|
||||
c.SetAppInfo("minio-"+batchJobPrefix, r.APIVersion+" "+job.ID)
|
||||
|
||||
var (
|
||||
walkCh = make(chan ObjectInfo, 100)
|
||||
slowCh = make(chan ObjectInfo, 100)
|
||||
walkCh = make(chan itemOrErr[ObjectInfo], 100)
|
||||
slowCh = make(chan itemOrErr[ObjectInfo], 100)
|
||||
)
|
||||
|
||||
if !*r.Source.Snowball.Disable && r.Source.Type.isMinio() && r.Target.Type.isMinio() {
|
||||
@@ -1068,11 +1082,11 @@ func (r *BatchJobReplicateV1) Start(ctx context.Context, api ObjectLayer, job Ba
|
||||
cl, err := miniogo.New(u.Host, &miniogo.Options{
|
||||
Creds: credentials.NewStaticV4(cred.AccessKey, cred.SecretKey, cred.SessionToken),
|
||||
Secure: u.Scheme == "https",
|
||||
Transport: getRemoteInstanceTransport,
|
||||
Transport: getRemoteInstanceTransport(),
|
||||
BucketLookup: lookupStyle(r.Target.Path),
|
||||
})
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
return
|
||||
}
|
||||
|
||||
@@ -1083,25 +1097,25 @@ func (r *BatchJobReplicateV1) Start(ctx context.Context, api ObjectLayer, job Ba
|
||||
writeFn := func(batch []ObjectInfo) {
|
||||
if len(batch) > 0 {
|
||||
if err := r.writeAsArchive(ctx, api, cl, batch); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
for _, b := range batch {
|
||||
slowCh <- b
|
||||
slowCh <- itemOrErr[ObjectInfo]{Item: b}
|
||||
}
|
||||
} else {
|
||||
ri.trackCurrentBucketBatch(r.Source.Bucket, batch)
|
||||
globalBatchJobsMetrics.save(job.ID, ri)
|
||||
// persist in-memory state to disk after every 10secs.
|
||||
logger.LogIf(ctx, ri.updateAfter(ctx, api, 10*time.Second, job))
|
||||
batchLogIf(ctx, ri.updateAfter(ctx, api, 10*time.Second, job))
|
||||
}
|
||||
}
|
||||
}
|
||||
for obj := range walkCh {
|
||||
if obj.DeleteMarker || !obj.VersionPurgeStatus.Empty() || obj.Size >= int64(smallerThan) {
|
||||
if obj.Item.DeleteMarker || !obj.Item.VersionPurgeStatus.Empty() || obj.Item.Size >= int64(smallerThan) {
|
||||
slowCh <- obj
|
||||
continue
|
||||
}
|
||||
|
||||
batch = append(batch, obj)
|
||||
batch = append(batch, obj.Item)
|
||||
|
||||
if len(batch) < *r.Source.Snowball.Batch {
|
||||
continue
|
||||
@@ -1154,8 +1168,13 @@ func (r *BatchJobReplicateV1) Start(ctx context.Context, api ObjectLayer, job Ba
|
||||
prevObj := ""
|
||||
|
||||
skipReplicate := false
|
||||
for result := range slowCh {
|
||||
result := result
|
||||
for res := range slowCh {
|
||||
if res.Err != nil {
|
||||
ri.Failed = true
|
||||
batchLogIf(ctx, res.Err)
|
||||
continue
|
||||
}
|
||||
result := res.Item
|
||||
if result.Name != prevObj {
|
||||
prevObj = result.Name
|
||||
skipReplicate = result.DeleteMarker && s3Type
|
||||
@@ -1179,15 +1198,15 @@ func (r *BatchJobReplicateV1) Start(ctx context.Context, api ObjectLayer, job Ba
|
||||
return
|
||||
}
|
||||
stopFn(result, err)
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
success = false
|
||||
} else {
|
||||
stopFn(result, nil)
|
||||
}
|
||||
ri.trackCurrentBucketObject(r.Source.Bucket, result, success)
|
||||
ri.trackCurrentBucketObject(r.Source.Bucket, result, success, attempts)
|
||||
globalBatchJobsMetrics.save(job.ID, ri)
|
||||
// persist in-memory state to disk after every 10secs.
|
||||
logger.LogIf(ctx, ri.updateAfter(ctx, api, 10*time.Second, job))
|
||||
batchLogIf(ctx, ri.updateAfter(ctx, api, 10*time.Second, job))
|
||||
|
||||
if wait := globalBatchConfig.ReplicationWait(); wait > 0 {
|
||||
time.Sleep(wait)
|
||||
@@ -1202,10 +1221,10 @@ func (r *BatchJobReplicateV1) Start(ctx context.Context, api ObjectLayer, job Ba
|
||||
|
||||
globalBatchJobsMetrics.save(job.ID, ri)
|
||||
// persist in-memory state to disk.
|
||||
logger.LogIf(ctx, ri.updateAfter(ctx, api, 0, job))
|
||||
batchLogIf(ctx, ri.updateAfter(ctx, api, 0, job))
|
||||
|
||||
if err := r.Notify(ctx, ri); err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to notify %v", err))
|
||||
batchLogIf(ctx, fmt.Errorf("unable to notify %v", err))
|
||||
}
|
||||
|
||||
cancel()
|
||||
@@ -1232,6 +1251,7 @@ type batchReplicationJobError struct {
|
||||
Code string
|
||||
Description string
|
||||
HTTPStatusCode int
|
||||
ObjectSize int64
|
||||
}
|
||||
|
||||
func (e batchReplicationJobError) Error() string {
|
||||
@@ -1248,9 +1268,18 @@ func (r *BatchJobReplicateV1) Validate(ctx context.Context, job BatchJobRequest,
|
||||
return errInvalidArgument
|
||||
}
|
||||
|
||||
if r.Source.Bucket == "" {
|
||||
if r.Source.Endpoint != "" && r.Target.Endpoint != "" {
|
||||
return errInvalidArgument
|
||||
}
|
||||
|
||||
if r.Source.Creds.Empty() && r.Target.Creds.Empty() {
|
||||
return errInvalidArgument
|
||||
}
|
||||
|
||||
if r.Source.Bucket == "" || r.Target.Bucket == "" {
|
||||
return errInvalidArgument
|
||||
}
|
||||
|
||||
var isRemoteToLocal bool
|
||||
localBkt := r.Source.Bucket
|
||||
if r.Source.Endpoint != "" {
|
||||
@@ -1275,9 +1304,6 @@ func (r *BatchJobReplicateV1) Validate(ctx context.Context, job BatchJobRequest,
|
||||
if err := r.Source.Snowball.Validate(); err != nil {
|
||||
return err
|
||||
}
|
||||
if r.Source.Creds.Empty() && r.Target.Creds.Empty() {
|
||||
return errInvalidArgument
|
||||
}
|
||||
|
||||
if !r.Source.Creds.Empty() {
|
||||
if err := r.Source.Creds.Validate(); err != nil {
|
||||
@@ -1299,9 +1325,6 @@ func (r *BatchJobReplicateV1) Validate(ctx context.Context, job BatchJobRequest,
|
||||
if r.Target.Endpoint != "" && !r.Target.Type.isMinio() && !r.Target.ValidPath() {
|
||||
return errInvalidArgument
|
||||
}
|
||||
if r.Target.Bucket == "" {
|
||||
return errInvalidArgument
|
||||
}
|
||||
|
||||
if !r.Target.Creds.Empty() {
|
||||
if err := r.Target.Creds.Validate(); err != nil {
|
||||
@@ -1309,10 +1332,6 @@ func (r *BatchJobReplicateV1) Validate(ctx context.Context, job BatchJobRequest,
|
||||
}
|
||||
}
|
||||
|
||||
if r.Source.Creds.Empty() && r.Target.Creds.Empty() {
|
||||
return errInvalidArgument
|
||||
}
|
||||
|
||||
if err := r.Target.Type.Validate(); err != nil {
|
||||
return err
|
||||
}
|
||||
@@ -1354,7 +1373,7 @@ func (r *BatchJobReplicateV1) Validate(ctx context.Context, job BatchJobRequest,
|
||||
c, err := miniogo.NewCore(u.Host, &miniogo.Options{
|
||||
Creds: credentials.NewStaticV4(cred.AccessKey, cred.SecretKey, cred.SessionToken),
|
||||
Secure: u.Scheme == "https",
|
||||
Transport: getRemoteInstanceTransport,
|
||||
Transport: getRemoteInstanceTransport(),
|
||||
BucketLookup: lookupStyle(pathStyle),
|
||||
})
|
||||
if err != nil {
|
||||
@@ -1485,7 +1504,7 @@ func (a adminAPIHandlers) ListBatchJobs(w http.ResponseWriter, r *http.Request)
|
||||
jobType = string(madmin.BatchJobReplicate)
|
||||
}
|
||||
|
||||
resultCh := make(chan ObjectInfo)
|
||||
resultCh := make(chan itemOrErr[ObjectInfo])
|
||||
|
||||
ctx, cancel := context.WithCancel(ctx)
|
||||
defer cancel()
|
||||
@@ -1497,10 +1516,14 @@ func (a adminAPIHandlers) ListBatchJobs(w http.ResponseWriter, r *http.Request)
|
||||
|
||||
listResult := madmin.ListBatchJobsResult{}
|
||||
for result := range resultCh {
|
||||
if result.Err != nil {
|
||||
writeErrorResponseJSON(ctx, w, toAPIError(ctx, result.Err), r.URL)
|
||||
return
|
||||
}
|
||||
req := &BatchJobRequest{}
|
||||
if err := req.load(ctx, objectAPI, result.Name); err != nil {
|
||||
if err := req.load(ctx, objectAPI, result.Item.Name); err != nil {
|
||||
if !errors.Is(err, errNoSuchJob) {
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
}
|
||||
continue
|
||||
}
|
||||
@@ -1516,7 +1539,7 @@ func (a adminAPIHandlers) ListBatchJobs(w http.ResponseWriter, r *http.Request)
|
||||
}
|
||||
}
|
||||
|
||||
logger.LogIf(ctx, json.NewEncoder(w).Encode(&listResult))
|
||||
batchLogIf(ctx, json.NewEncoder(w).Encode(&listResult))
|
||||
}
|
||||
|
||||
var errNoSuchJob = errors.New("no such job")
|
||||
@@ -1539,7 +1562,7 @@ func (a adminAPIHandlers) DescribeBatchJob(w http.ResponseWriter, r *http.Reques
|
||||
req := &BatchJobRequest{}
|
||||
if err := req.load(ctx, objectAPI, pathJoin(batchJobPrefix, jobID)); err != nil {
|
||||
if !errors.Is(err, errNoSuchJob) {
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
}
|
||||
|
||||
writeErrorResponseJSON(ctx, w, toAPIError(ctx, err), r.URL)
|
||||
@@ -1548,7 +1571,7 @@ func (a adminAPIHandlers) DescribeBatchJob(w http.ResponseWriter, r *http.Reques
|
||||
|
||||
buf, err := yaml.Marshal(req)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
writeErrorResponseJSON(ctx, w, toAPIError(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -1703,21 +1726,25 @@ func newBatchJobPool(ctx context.Context, o ObjectLayer, workers int) *BatchJobP
|
||||
}
|
||||
|
||||
func (j *BatchJobPool) resume() {
|
||||
results := make(chan ObjectInfo, 100)
|
||||
results := make(chan itemOrErr[ObjectInfo], 100)
|
||||
ctx, cancel := context.WithCancel(j.ctx)
|
||||
defer cancel()
|
||||
if err := j.objLayer.Walk(ctx, minioMetaBucket, batchJobPrefix, results, WalkOptions{}); err != nil {
|
||||
logger.LogIf(j.ctx, err)
|
||||
batchLogIf(j.ctx, err)
|
||||
return
|
||||
}
|
||||
for result := range results {
|
||||
if result.Err != nil {
|
||||
batchLogIf(j.ctx, result.Err)
|
||||
continue
|
||||
}
|
||||
// ignore batch-replicate.bin and batch-rotate.bin entries
|
||||
if strings.HasSuffix(result.Name, slashSeparator) {
|
||||
if strings.HasSuffix(result.Item.Name, slashSeparator) {
|
||||
continue
|
||||
}
|
||||
req := &BatchJobRequest{}
|
||||
if err := req.load(ctx, j.objLayer, result.Name); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
if err := req.load(ctx, j.objLayer, result.Item.Name); err != nil {
|
||||
batchLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
_, nodeIdx := parseRequestToken(req.ID)
|
||||
@@ -1726,7 +1753,7 @@ func (j *BatchJobPool) resume() {
|
||||
continue
|
||||
}
|
||||
if err := j.queueJob(req); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
}
|
||||
@@ -1750,7 +1777,7 @@ func (j *BatchJobPool) AddWorker() {
|
||||
if job.Replicate.RemoteToLocal() {
|
||||
if err := job.Replicate.StartFromSource(job.ctx, j.objLayer, *job); err != nil {
|
||||
if !isErrBucketNotFound(err) {
|
||||
logger.LogIf(j.ctx, err)
|
||||
batchLogIf(j.ctx, err)
|
||||
j.canceler(job.ID, false)
|
||||
continue
|
||||
}
|
||||
@@ -1759,7 +1786,7 @@ func (j *BatchJobPool) AddWorker() {
|
||||
} else {
|
||||
if err := job.Replicate.Start(job.ctx, j.objLayer, *job); err != nil {
|
||||
if !isErrBucketNotFound(err) {
|
||||
logger.LogIf(j.ctx, err)
|
||||
batchLogIf(j.ctx, err)
|
||||
j.canceler(job.ID, false)
|
||||
continue
|
||||
}
|
||||
@@ -1769,14 +1796,14 @@ func (j *BatchJobPool) AddWorker() {
|
||||
case job.KeyRotate != nil:
|
||||
if err := job.KeyRotate.Start(job.ctx, j.objLayer, *job); err != nil {
|
||||
if !isErrBucketNotFound(err) {
|
||||
logger.LogIf(j.ctx, err)
|
||||
batchLogIf(j.ctx, err)
|
||||
continue
|
||||
}
|
||||
}
|
||||
case job.Expire != nil:
|
||||
if err := job.Expire.Start(job.ctx, j.objLayer, *job); err != nil {
|
||||
if !isErrBucketNotFound(err) {
|
||||
logger.LogIf(j.ctx, err)
|
||||
batchLogIf(j.ctx, err)
|
||||
continue
|
||||
}
|
||||
}
|
||||
|
||||
@@ -419,6 +419,12 @@ func (z *batchJobInfo) DecodeMsg(dc *msgp.Reader) (err error) {
|
||||
err = msgp.WrapError(err, "RetryAttempts")
|
||||
return
|
||||
}
|
||||
case "at":
|
||||
z.Attempts, err = dc.ReadInt()
|
||||
if err != nil {
|
||||
err = msgp.WrapError(err, "Attempts")
|
||||
return
|
||||
}
|
||||
case "cmp":
|
||||
z.Complete, err = dc.ReadBool()
|
||||
if err != nil {
|
||||
@@ -492,9 +498,9 @@ func (z *batchJobInfo) DecodeMsg(dc *msgp.Reader) (err error) {
|
||||
|
||||
// EncodeMsg implements msgp.Encodable
|
||||
func (z *batchJobInfo) EncodeMsg(en *msgp.Writer) (err error) {
|
||||
// map header, size 16
|
||||
// map header, size 17
|
||||
// write "v"
|
||||
err = en.Append(0xde, 0x0, 0x10, 0xa1, 0x76)
|
||||
err = en.Append(0xde, 0x0, 0x11, 0xa1, 0x76)
|
||||
if err != nil {
|
||||
return
|
||||
}
|
||||
@@ -553,6 +559,16 @@ func (z *batchJobInfo) EncodeMsg(en *msgp.Writer) (err error) {
|
||||
err = msgp.WrapError(err, "RetryAttempts")
|
||||
return
|
||||
}
|
||||
// write "at"
|
||||
err = en.Append(0xa2, 0x61, 0x74)
|
||||
if err != nil {
|
||||
return
|
||||
}
|
||||
err = en.WriteInt(z.Attempts)
|
||||
if err != nil {
|
||||
err = msgp.WrapError(err, "Attempts")
|
||||
return
|
||||
}
|
||||
// write "cmp"
|
||||
err = en.Append(0xa3, 0x63, 0x6d, 0x70)
|
||||
if err != nil {
|
||||
@@ -659,9 +675,9 @@ func (z *batchJobInfo) EncodeMsg(en *msgp.Writer) (err error) {
|
||||
// MarshalMsg implements msgp.Marshaler
|
||||
func (z *batchJobInfo) MarshalMsg(b []byte) (o []byte, err error) {
|
||||
o = msgp.Require(b, z.Msgsize())
|
||||
// map header, size 16
|
||||
// map header, size 17
|
||||
// string "v"
|
||||
o = append(o, 0xde, 0x0, 0x10, 0xa1, 0x76)
|
||||
o = append(o, 0xde, 0x0, 0x11, 0xa1, 0x76)
|
||||
o = msgp.AppendInt(o, z.Version)
|
||||
// string "jid"
|
||||
o = append(o, 0xa3, 0x6a, 0x69, 0x64)
|
||||
@@ -678,6 +694,9 @@ func (z *batchJobInfo) MarshalMsg(b []byte) (o []byte, err error) {
|
||||
// string "ra"
|
||||
o = append(o, 0xa2, 0x72, 0x61)
|
||||
o = msgp.AppendInt(o, z.RetryAttempts)
|
||||
// string "at"
|
||||
o = append(o, 0xa2, 0x61, 0x74)
|
||||
o = msgp.AppendInt(o, z.Attempts)
|
||||
// string "cmp"
|
||||
o = append(o, 0xa3, 0x63, 0x6d, 0x70)
|
||||
o = msgp.AppendBool(o, z.Complete)
|
||||
@@ -765,6 +784,12 @@ func (z *batchJobInfo) UnmarshalMsg(bts []byte) (o []byte, err error) {
|
||||
err = msgp.WrapError(err, "RetryAttempts")
|
||||
return
|
||||
}
|
||||
case "at":
|
||||
z.Attempts, bts, err = msgp.ReadIntBytes(bts)
|
||||
if err != nil {
|
||||
err = msgp.WrapError(err, "Attempts")
|
||||
return
|
||||
}
|
||||
case "cmp":
|
||||
z.Complete, bts, err = msgp.ReadBoolBytes(bts)
|
||||
if err != nil {
|
||||
@@ -839,6 +864,6 @@ func (z *batchJobInfo) UnmarshalMsg(bts []byte) (o []byte, err error) {
|
||||
|
||||
// Msgsize returns an upper bound estimate of the number of bytes occupied by the serialized message
|
||||
func (z *batchJobInfo) Msgsize() (s int) {
|
||||
s = 3 + 2 + msgp.IntSize + 4 + msgp.StringPrefixSize + len(z.JobID) + 3 + msgp.StringPrefixSize + len(z.JobType) + 3 + msgp.TimeSize + 3 + msgp.TimeSize + 3 + msgp.IntSize + 4 + msgp.BoolSize + 4 + msgp.BoolSize + 5 + msgp.StringPrefixSize + len(z.Bucket) + 5 + msgp.StringPrefixSize + len(z.Object) + 3 + msgp.Int64Size + 3 + msgp.Int64Size + 4 + msgp.Int64Size + 4 + msgp.Int64Size + 3 + msgp.Int64Size + 3 + msgp.Int64Size
|
||||
s = 3 + 2 + msgp.IntSize + 4 + msgp.StringPrefixSize + len(z.JobID) + 3 + msgp.StringPrefixSize + len(z.JobType) + 3 + msgp.TimeSize + 3 + msgp.TimeSize + 3 + msgp.IntSize + 3 + msgp.IntSize + 4 + msgp.BoolSize + 4 + msgp.BoolSize + 5 + msgp.StringPrefixSize + len(z.Bucket) + 5 + msgp.StringPrefixSize + len(z.Object) + 3 + msgp.Int64Size + 3 + msgp.Int64Size + 4 + msgp.Int64Size + 4 + msgp.Int64Size + 3 + msgp.Int64Size + 3 + msgp.Int64Size
|
||||
return
|
||||
}
|
||||
|
||||
+19
-19
@@ -33,7 +33,6 @@ import (
|
||||
"github.com/minio/minio/internal/crypto"
|
||||
xhttp "github.com/minio/minio/internal/http"
|
||||
"github.com/minio/minio/internal/kms"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/env"
|
||||
"github.com/minio/pkg/v2/workers"
|
||||
)
|
||||
@@ -96,6 +95,7 @@ func (e BatchJobKeyRotateEncryption) Validate() error {
|
||||
if e.Type == ssekms && spaces {
|
||||
return crypto.ErrInvalidEncryptionKeyID
|
||||
}
|
||||
|
||||
if e.Type == ssekms && GlobalKMS != nil {
|
||||
ctx := kms.Context{}
|
||||
if e.Context != "" {
|
||||
@@ -114,7 +114,7 @@ func (e BatchJobKeyRotateEncryption) Validate() error {
|
||||
e.kmsContext[k] = v
|
||||
}
|
||||
ctx["MinIO batch API"] = "batchrotate" // Context for a test key operation
|
||||
if _, err := GlobalKMS.GenerateKey(GlobalContext, e.Key, ctx); err != nil {
|
||||
if _, err := GlobalKMS.GenerateKey(GlobalContext, &kms.GenerateKeyRequest{Name: e.Key, AssociatedData: ctx}); err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
@@ -357,7 +357,7 @@ func (r *BatchJobKeyRotateV1) Start(ctx context.Context, api ObjectLayer, job Ba
|
||||
retryAttempts := ri.RetryAttempts
|
||||
ctx, cancel := context.WithCancel(ctx)
|
||||
|
||||
results := make(chan ObjectInfo, 100)
|
||||
results := make(chan itemOrErr[ObjectInfo], 100)
|
||||
if err := api.Walk(ctx, r.Bucket, r.Prefix, results, WalkOptions{
|
||||
Marker: lastObject,
|
||||
Filter: selectObj,
|
||||
@@ -366,9 +366,14 @@ func (r *BatchJobKeyRotateV1) Start(ctx context.Context, api ObjectLayer, job Ba
|
||||
// Do not need to retry if we can't list objects on source.
|
||||
return err
|
||||
}
|
||||
|
||||
for result := range results {
|
||||
result := result
|
||||
failed := false
|
||||
for res := range results {
|
||||
if res.Err != nil {
|
||||
failed = true
|
||||
batchLogIf(ctx, res.Err)
|
||||
break
|
||||
}
|
||||
result := res.Item
|
||||
sseKMS := crypto.S3KMS.IsEncrypted(result.UserDefined)
|
||||
sseS3 := crypto.S3.IsEncrypted(result.UserDefined)
|
||||
if !sseKMS && !sseS3 { // neither sse-s3 nor sse-kms disallowed
|
||||
@@ -378,21 +383,19 @@ func (r *BatchJobKeyRotateV1) Start(ctx context.Context, api ObjectLayer, job Ba
|
||||
go func() {
|
||||
defer wk.Give()
|
||||
for attempts := 1; attempts <= retryAttempts; attempts++ {
|
||||
attempts := attempts
|
||||
stopFn := globalBatchJobsMetrics.trace(batchJobMetricKeyRotation, job.ID, attempts)
|
||||
success := true
|
||||
if err := r.KeyRotate(ctx, api, result); err != nil {
|
||||
stopFn(result, err)
|
||||
logger.LogIf(ctx, err)
|
||||
batchLogIf(ctx, err)
|
||||
success = false
|
||||
} else {
|
||||
stopFn(result, nil)
|
||||
}
|
||||
ri.trackCurrentBucketObject(r.Bucket, result, success)
|
||||
ri.RetryAttempts = attempts
|
||||
ri.trackCurrentBucketObject(r.Bucket, result, success, attempts)
|
||||
globalBatchJobsMetrics.save(job.ID, ri)
|
||||
// persist in-memory state to disk after every 10secs.
|
||||
logger.LogIf(ctx, ri.updateAfter(ctx, api, 10*time.Second, job))
|
||||
batchLogIf(ctx, ri.updateAfter(ctx, api, 10*time.Second, job))
|
||||
if success {
|
||||
break
|
||||
}
|
||||
@@ -408,14 +411,14 @@ func (r *BatchJobKeyRotateV1) Start(ctx context.Context, api ObjectLayer, job Ba
|
||||
}
|
||||
wk.Wait()
|
||||
|
||||
ri.Complete = ri.ObjectsFailed == 0
|
||||
ri.Failed = ri.ObjectsFailed > 0
|
||||
ri.Complete = !failed && ri.ObjectsFailed == 0
|
||||
ri.Failed = failed || ri.ObjectsFailed > 0
|
||||
globalBatchJobsMetrics.save(job.ID, ri)
|
||||
// persist in-memory state to disk.
|
||||
logger.LogIf(ctx, ri.updateAfter(ctx, api, 0, job))
|
||||
batchLogIf(ctx, ri.updateAfter(ctx, api, 0, job))
|
||||
|
||||
if err := r.Notify(ctx, ri); err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to notify %v", err))
|
||||
batchLogIf(ctx, fmt.Errorf("unable to notify %v", err))
|
||||
}
|
||||
|
||||
cancel()
|
||||
@@ -476,8 +479,5 @@ func (r *BatchJobKeyRotateV1) Validate(ctx context.Context, job BatchJobRequest,
|
||||
}
|
||||
}
|
||||
|
||||
if err := r.Flags.Retry.Validate(); err != nil {
|
||||
return err
|
||||
}
|
||||
return nil
|
||||
return r.Flags.Retry.Validate()
|
||||
}
|
||||
|
||||
@@ -198,7 +198,7 @@ func verifyServerSystemConfig(ctx context.Context, endpointServerPools EndpointS
|
||||
if err != nil {
|
||||
bootstrapTraceMsg(fmt.Sprintf("clnt.Verify: %v, endpoint: %s", err, clnt))
|
||||
if !isNetworkError(err) {
|
||||
logger.LogOnceIf(context.Background(), fmt.Errorf("%s has incorrect configuration: %w", clnt, err), "incorrect_"+clnt.String())
|
||||
bootLogOnceIf(context.Background(), fmt.Errorf("%s has incorrect configuration: %w", clnt, err), "incorrect_"+clnt.String())
|
||||
incorrectConfigs = append(incorrectConfigs, fmt.Errorf("%s has incorrect configuration: %w", clnt, err))
|
||||
} else {
|
||||
offlineEndpoints = append(offlineEndpoints, fmt.Errorf("%s is unreachable: %w", clnt, err))
|
||||
|
||||
@@ -85,7 +85,7 @@ func (api objectAPIHandlers) PutBucketEncryptionHandler(w http.ResponseWriter, r
|
||||
kmsKey := encConfig.KeyID()
|
||||
if kmsKey != "" {
|
||||
kmsContext := kms.Context{"MinIO admin API": "ServerInfoHandler"} // Context for a test key operation
|
||||
_, err := GlobalKMS.GenerateKey(ctx, kmsKey, kmsContext)
|
||||
_, err := GlobalKMS.GenerateKey(ctx, &kms.GenerateKeyRequest{Name: kmsKey, AssociatedData: kmsContext})
|
||||
if err != nil {
|
||||
if errors.Is(err, kes.ErrKeyNotFound) {
|
||||
writeErrorResponse(ctx, w, toAPIError(ctx, errKMSKeyNotFound), r.URL)
|
||||
@@ -114,7 +114,7 @@ func (api objectAPIHandlers) PutBucketEncryptionHandler(w http.ResponseWriter, r
|
||||
// We encode the xml bytes as base64 to ensure there are no encoding
|
||||
// errors.
|
||||
cfgStr := base64.StdEncoding.EncodeToString(configData)
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
replLogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
Type: madmin.SRBucketMetaTypeSSEConfig,
|
||||
Bucket: bucket,
|
||||
SSEConfig: &cfgStr,
|
||||
@@ -203,7 +203,7 @@ func (api objectAPIHandlers) DeleteBucketEncryptionHandler(w http.ResponseWriter
|
||||
}
|
||||
|
||||
// Call site replication hook.
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
replLogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
Type: madmin.SRBucketMetaTypeSSEConfig,
|
||||
Bucket: bucket,
|
||||
SSEConfig: nil,
|
||||
|
||||
+12
-17
@@ -98,7 +98,7 @@ func initFederatorBackend(buckets []BucketInfo, objLayer ObjectLayer) {
|
||||
// Get buckets in the DNS
|
||||
dnsBuckets, err := globalDNSConfig.List()
|
||||
if err != nil && !IsErrIgnored(err, dns.ErrNoEntriesFound, dns.ErrNotImplemented, dns.ErrDomainMissing) {
|
||||
logger.LogIf(GlobalContext, err)
|
||||
dnsLogIf(GlobalContext, err)
|
||||
return
|
||||
}
|
||||
|
||||
@@ -160,13 +160,13 @@ func initFederatorBackend(buckets []BucketInfo, objLayer ObjectLayer) {
|
||||
ctx := GlobalContext
|
||||
for _, err := range g.Wait() {
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
dnsLogIf(ctx, err)
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
for _, bucket := range bucketsInConflict.ToSlice() {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to add bucket DNS entry for bucket %s, an entry exists for the same bucket by a different tenant. This local bucket will be ignored. Bucket names are globally unique in federated deployments. Use path style requests on following addresses '%v' to access this bucket", bucket, globalDomainIPs.ToSlice()))
|
||||
dnsLogIf(ctx, fmt.Errorf("Unable to add bucket DNS entry for bucket %s, an entry exists for the same bucket by a different tenant. This local bucket will be ignored. Bucket names are globally unique in federated deployments. Use path style requests on following addresses '%v' to access this bucket", bucket, globalDomainIPs.ToSlice()))
|
||||
}
|
||||
|
||||
var wg sync.WaitGroup
|
||||
@@ -187,7 +187,7 @@ func initFederatorBackend(buckets []BucketInfo, objLayer ObjectLayer) {
|
||||
// We go to here, so we know the bucket no longer exists,
|
||||
// but is registered in DNS to this server
|
||||
if err := globalDNSConfig.Delete(bucket); err != nil {
|
||||
logger.LogIf(GlobalContext, fmt.Errorf("Failed to remove DNS entry for %s due to %w",
|
||||
dnsLogIf(GlobalContext, fmt.Errorf("Failed to remove DNS entry for %s due to %w",
|
||||
bucket, err))
|
||||
}
|
||||
}(bucket)
|
||||
@@ -790,7 +790,7 @@ func (api objectAPIHandlers) PutBucketHandler(w http.ResponseWriter, r *http.Req
|
||||
|
||||
// check if client is attempting to create more buckets, complain about it.
|
||||
if currBuckets := globalBucketMetadataSys.Count(); currBuckets+1 > maxBuckets {
|
||||
logger.LogIf(ctx, fmt.Errorf("Please avoid creating more buckets %d beyond recommended %d", currBuckets+1, maxBuckets))
|
||||
internalLogIf(ctx, fmt.Errorf("Please avoid creating more buckets %d beyond recommended %d", currBuckets+1, maxBuckets), logger.WarningKind)
|
||||
}
|
||||
|
||||
opts := MakeBucketOptions{
|
||||
@@ -871,7 +871,7 @@ func (api objectAPIHandlers) PutBucketHandler(w http.ResponseWriter, r *http.Req
|
||||
globalNotificationSys.LoadBucketMetadata(GlobalContext, bucket)
|
||||
|
||||
// Call site replication hook
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.MakeBucketHook(ctx, bucket, opts))
|
||||
replLogIf(ctx, globalSiteReplicationSys.MakeBucketHook(ctx, bucket, opts))
|
||||
|
||||
// Make sure to add Location information here only for bucket
|
||||
w.Header().Set(xhttp.Location, pathJoin(SlashSeparator, bucket))
|
||||
@@ -1218,11 +1218,6 @@ func (api objectAPIHandlers) PostPolicyBucketHandler(w http.ResponseWriter, r *h
|
||||
return
|
||||
}
|
||||
|
||||
if crypto.SSEC.IsRequested(r.Header) && isReplicationEnabled(ctx, bucket) {
|
||||
writeErrorResponse(ctx, w, toAPIError(ctx, errInvalidEncryptionParametersSSEC), r.URL)
|
||||
return
|
||||
}
|
||||
|
||||
var (
|
||||
reader io.Reader
|
||||
keyID string
|
||||
@@ -1666,7 +1661,7 @@ func (api objectAPIHandlers) DeleteBucketHandler(w http.ResponseWriter, r *http.
|
||||
writeErrorResponse(ctx, w, errorCodes.ToAPIErr(ErrMethodNotAllowed), r.URL)
|
||||
return
|
||||
}
|
||||
case rcfg.HasActiveRules("", true):
|
||||
case rcfg != nil && rcfg.HasActiveRules("", true):
|
||||
writeErrorResponse(ctx, w, errorCodes.ToAPIErr(ErrMethodNotAllowed), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -1698,7 +1693,7 @@ func (api objectAPIHandlers) DeleteBucketHandler(w http.ResponseWriter, r *http.
|
||||
|
||||
if globalDNSConfig != nil {
|
||||
if err := globalDNSConfig.Delete(bucket); err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to delete bucket DNS entry %w, please delete it manually, bucket on MinIO no longer exists", err))
|
||||
dnsLogIf(ctx, fmt.Errorf("Unable to delete bucket DNS entry %w, please delete it manually, bucket on MinIO no longer exists", err))
|
||||
writeErrorResponse(ctx, w, toAPIError(ctx, err), r.URL)
|
||||
return
|
||||
}
|
||||
@@ -1708,7 +1703,7 @@ func (api objectAPIHandlers) DeleteBucketHandler(w http.ResponseWriter, r *http.
|
||||
globalReplicationPool.deleteResyncMetadata(ctx, bucket)
|
||||
|
||||
// Call site replication hook.
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.DeleteBucketHook(ctx, bucket, forceDelete))
|
||||
replLogIf(ctx, globalSiteReplicationSys.DeleteBucketHook(ctx, bucket, forceDelete))
|
||||
|
||||
// Write success response.
|
||||
writeSuccessNoContent(w)
|
||||
@@ -1781,7 +1776,7 @@ func (api objectAPIHandlers) PutBucketObjectLockConfigHandler(w http.ResponseWri
|
||||
// We encode the xml bytes as base64 to ensure there are no encoding
|
||||
// errors.
|
||||
cfgStr := base64.StdEncoding.EncodeToString(configData)
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
replLogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
Type: madmin.SRBucketMetaTypeObjectLockConfig,
|
||||
Bucket: bucket,
|
||||
ObjectLockConfig: &cfgStr,
|
||||
@@ -1885,7 +1880,7 @@ func (api objectAPIHandlers) PutBucketTaggingHandler(w http.ResponseWriter, r *h
|
||||
// We encode the xml bytes as base64 to ensure there are no encoding
|
||||
// errors.
|
||||
cfgStr := base64.StdEncoding.EncodeToString(configData)
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
replLogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
Type: madmin.SRBucketMetaTypeTags,
|
||||
Bucket: bucket,
|
||||
Tags: &cfgStr,
|
||||
@@ -1961,7 +1956,7 @@ func (api objectAPIHandlers) DeleteBucketTaggingHandler(w http.ResponseWriter, r
|
||||
return
|
||||
}
|
||||
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
replLogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
Type: madmin.SRBucketMetaTypeTags,
|
||||
Bucket: bucket,
|
||||
UpdatedAt: updatedAt,
|
||||
|
||||
@@ -336,7 +336,7 @@ func (es *expiryState) Worker(input <-chan expiryOp) {
|
||||
case newerNoncurrentTask:
|
||||
deleteObjectVersions(es.ctx, es.objAPI, v.bucket, v.versions, v.event)
|
||||
case jentry:
|
||||
logger.LogIf(es.ctx, deleteObjectFromRemoteTier(es.ctx, v.ObjName, v.VersionID, v.TierName))
|
||||
transitionLogIf(es.ctx, deleteObjectFromRemoteTier(es.ctx, v.ObjName, v.VersionID, v.TierName))
|
||||
case freeVersionTask:
|
||||
oi := v.ObjectInfo
|
||||
traceFn := globalLifecycleSys.trace(oi)
|
||||
@@ -355,7 +355,7 @@ func (es *expiryState) Worker(input <-chan expiryOp) {
|
||||
// Remove the remote object
|
||||
err := deleteObjectFromRemoteTier(es.ctx, oi.TransitionedObject.Name, oi.TransitionedObject.VersionID, oi.TransitionedObject.Tier)
|
||||
if ignoreNotFoundErr(err) != nil {
|
||||
logger.LogIf(es.ctx, err)
|
||||
transitionLogIf(es.ctx, err)
|
||||
return
|
||||
}
|
||||
|
||||
@@ -368,10 +368,10 @@ func (es *expiryState) Worker(input <-chan expiryOp) {
|
||||
auditLogLifecycle(es.ctx, oi, ILMFreeVersionDelete, nil, traceFn)
|
||||
}
|
||||
if ignoreNotFoundErr(err) != nil {
|
||||
logger.LogIf(es.ctx, err)
|
||||
transitionLogIf(es.ctx, err)
|
||||
}
|
||||
default:
|
||||
logger.LogIf(es.ctx, fmt.Errorf("Invalid work type - %v", v))
|
||||
bugLogIf(es.ctx, fmt.Errorf("Invalid work type - %v", v))
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -486,7 +486,7 @@ func (t *transitionState) worker(objectAPI ObjectLayer) {
|
||||
if err := transitionObject(t.ctx, objectAPI, task.objInfo, newLifecycleAuditEvent(task.src, task.event)); err != nil {
|
||||
if !isErrVersionNotFound(err) && !isErrObjectNotFound(err) && !xnet.IsNetworkOrHostDown(err, false) {
|
||||
if !strings.Contains(err.Error(), "use of closed network connection") {
|
||||
logger.LogIf(t.ctx, fmt.Errorf("Transition to %s failed for %s/%s version:%s with %w",
|
||||
transitionLogIf(t.ctx, fmt.Errorf("Transition to %s failed for %s/%s version:%s with %w",
|
||||
task.event.StorageClass, task.objInfo.Bucket, task.objInfo.Name, task.objInfo.VersionID, err))
|
||||
}
|
||||
}
|
||||
@@ -614,7 +614,7 @@ func expireTransitionedObject(ctx context.Context, objectAPI ObjectLayer, oi *Ob
|
||||
// remote object
|
||||
opts.SkipFreeVersion = true
|
||||
} else {
|
||||
logger.LogIf(ctx, err)
|
||||
transitionLogIf(ctx, err)
|
||||
}
|
||||
|
||||
// Now, delete object from hot-tier namespace
|
||||
@@ -721,9 +721,9 @@ func auditTierActions(ctx context.Context, tier string, bytes int64) func(err er
|
||||
|
||||
// getTransitionedObjectReader returns a reader from the transitioned tier.
|
||||
func getTransitionedObjectReader(ctx context.Context, bucket, object string, rs *HTTPRangeSpec, h http.Header, oi ObjectInfo, opts ObjectOptions) (gr *GetObjectReader, err error) {
|
||||
tgtClient, err := globalTierConfigMgr.getDriver(oi.TransitionedObject.Tier)
|
||||
tgtClient, err := globalTierConfigMgr.getDriver(ctx, oi.TransitionedObject.Tier)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("transition storage class not configured")
|
||||
return nil, fmt.Errorf("transition storage class not configured: %w", err)
|
||||
}
|
||||
|
||||
fn, off, length, err := NewGetObjectReader(rs, oi, opts)
|
||||
@@ -879,7 +879,7 @@ func postRestoreOpts(ctx context.Context, r *http.Request, bucket, object string
|
||||
if vid != "" && vid != nullVersionID {
|
||||
_, err := uuid.Parse(vid)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
s3LogIf(ctx, err)
|
||||
return opts, InvalidVersionID{
|
||||
Bucket: bucket,
|
||||
Object: object,
|
||||
|
||||
@@ -46,6 +46,7 @@ type BucketMetadataSys struct {
|
||||
objAPI ObjectLayer
|
||||
|
||||
sync.RWMutex
|
||||
initialized bool
|
||||
metadataMap map[string]BucketMetadata
|
||||
}
|
||||
|
||||
@@ -433,6 +434,8 @@ func (sys *BucketMetadataSys) GetConfigFromDisk(ctx context.Context, bucket stri
|
||||
return loadBucketMetadata(ctx, objAPI, bucket)
|
||||
}
|
||||
|
||||
var errBucketMetadataNotInitialized = errors.New("bucket metadata not initialized yet")
|
||||
|
||||
// GetConfig returns a specific configuration from the bucket metadata.
|
||||
// The returned object may not be modified.
|
||||
// reloaded will be true if metadata refreshed from disk
|
||||
@@ -454,6 +457,10 @@ func (sys *BucketMetadataSys) GetConfig(ctx context.Context, bucket string) (met
|
||||
}
|
||||
meta, err = loadBucketMetadata(ctx, objAPI, bucket)
|
||||
if err != nil {
|
||||
if !sys.Initialized() {
|
||||
// bucket metadata not yet initialized
|
||||
return newBucketMetadata(bucket), reloaded, errBucketMetadataNotInitialized
|
||||
}
|
||||
return meta, reloaded, err
|
||||
}
|
||||
sys.Lock()
|
||||
@@ -498,9 +505,10 @@ func (sys *BucketMetadataSys) concurrentLoad(ctx context.Context, buckets []Buck
|
||||
}
|
||||
|
||||
errs := g.Wait()
|
||||
for _, err := range errs {
|
||||
for index, err := range errs {
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
internalLogOnceIf(ctx, fmt.Errorf("Unable to load bucket metadata, will be retried: %w", err),
|
||||
"load-bucket-metadata-"+buckets[index].Name, logger.WarningKind)
|
||||
}
|
||||
}
|
||||
|
||||
@@ -542,7 +550,7 @@ func (sys *BucketMetadataSys) refreshBucketsMetadataLoop(ctx context.Context, fa
|
||||
case <-t.C:
|
||||
buckets, err := sys.objAPI.ListBuckets(ctx, BucketOptions{})
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
internalLogIf(ctx, err, logger.WarningKind)
|
||||
break
|
||||
}
|
||||
|
||||
@@ -560,7 +568,7 @@ func (sys *BucketMetadataSys) refreshBucketsMetadataLoop(ctx context.Context, fa
|
||||
|
||||
meta, err := loadBucketMetadata(ctx, sys.objAPI, buckets[i].Name)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
internalLogIf(ctx, err, logger.WarningKind)
|
||||
wait() // wait to proceed to next entry.
|
||||
continue
|
||||
}
|
||||
@@ -583,6 +591,14 @@ func (sys *BucketMetadataSys) refreshBucketsMetadataLoop(ctx context.Context, fa
|
||||
}
|
||||
}
|
||||
|
||||
// Initialized indicates if bucket metadata sys is initialized atleast once.
|
||||
func (sys *BucketMetadataSys) Initialized() bool {
|
||||
sys.RLock()
|
||||
defer sys.RUnlock()
|
||||
|
||||
return sys.initialized
|
||||
}
|
||||
|
||||
// Loads bucket metadata for all buckets into BucketMetadataSys.
|
||||
func (sys *BucketMetadataSys) init(ctx context.Context, buckets []BucketInfo) {
|
||||
count := 100 // load 100 bucket metadata at a time.
|
||||
@@ -596,6 +612,10 @@ func (sys *BucketMetadataSys) init(ctx context.Context, buckets []BucketInfo) {
|
||||
buckets = buckets[count:]
|
||||
}
|
||||
|
||||
sys.Lock()
|
||||
sys.initialized = true
|
||||
sys.Unlock()
|
||||
|
||||
if globalIsDistErasure {
|
||||
go sys.refreshBucketsMetadataLoop(ctx, failedBuckets)
|
||||
}
|
||||
|
||||
@@ -145,7 +145,7 @@ func (b *BucketMetadata) SetCreatedAt(createdAt time.Time) {
|
||||
// If an error is returned the returned metadata will be default initialized.
|
||||
func readBucketMetadata(ctx context.Context, api ObjectLayer, name string) (BucketMetadata, error) {
|
||||
if name == "" {
|
||||
logger.LogIf(ctx, errors.New("bucket name cannot be empty"))
|
||||
internalLogIf(ctx, errors.New("bucket name cannot be empty"), logger.WarningKind)
|
||||
return BucketMetadata{}, errInvalidArgument
|
||||
}
|
||||
b := newBucketMetadata(name)
|
||||
@@ -400,7 +400,7 @@ func (b *BucketMetadata) convertLegacyConfigs(ctx context.Context, objectAPI Obj
|
||||
for legacyFile := range configs {
|
||||
configFile := path.Join(bucketMetaPrefix, b.Name, legacyFile)
|
||||
if err := deleteConfig(ctx, objectAPI, configFile); err != nil && !errors.Is(err, errConfigNotFound) {
|
||||
logger.LogIf(ctx, err)
|
||||
internalLogIf(ctx, err, logger.WarningKind)
|
||||
}
|
||||
}
|
||||
|
||||
@@ -490,7 +490,7 @@ func encryptBucketMetadata(ctx context.Context, bucket string, input []byte, kms
|
||||
}
|
||||
|
||||
metadata := make(map[string]string)
|
||||
key, err := GlobalKMS.GenerateKey(ctx, "", kmsContext)
|
||||
key, err := GlobalKMS.GenerateKey(ctx, &kms.GenerateKeyRequest{AssociatedData: kmsContext})
|
||||
if err != nil {
|
||||
return
|
||||
}
|
||||
@@ -519,7 +519,11 @@ func decryptBucketMetadata(input []byte, bucket string, meta map[string]string,
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
extKey, err := GlobalKMS.DecryptKey(keyID, kmsKey, kmsContext)
|
||||
extKey, err := GlobalKMS.Decrypt(context.TODO(), &kms.DecryptRequest{
|
||||
Name: keyID,
|
||||
Ciphertext: kmsKey,
|
||||
AssociatedData: kmsContext,
|
||||
})
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
@@ -44,7 +44,6 @@ func (sys *BucketObjectLockSys) Get(bucketName string) (r objectlock.Retention,
|
||||
if errors.Is(err, errInvalidArgument) {
|
||||
return r, err
|
||||
}
|
||||
logger.CriticalIf(context.Background(), err)
|
||||
return r, err
|
||||
}
|
||||
return config.ToRetention(), nil
|
||||
@@ -66,7 +65,7 @@ func enforceRetentionForDeletion(ctx context.Context, objInfo ObjectInfo) (locke
|
||||
if ret.Mode.Valid() && (ret.Mode == objectlock.RetCompliance || ret.Mode == objectlock.RetGovernance) {
|
||||
t, err := objectlock.UTCNowNTP()
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
internalLogIf(ctx, err, logger.WarningKind)
|
||||
return true
|
||||
}
|
||||
if ret.RetainUntilDate.After(t) {
|
||||
@@ -114,7 +113,7 @@ func enforceRetentionBypassForDelete(ctx context.Context, r *http.Request, bucke
|
||||
// duration of the retention period.
|
||||
t, err := objectlock.UTCNowNTP()
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
internalLogIf(ctx, err, logger.WarningKind)
|
||||
return ObjectLocked{}
|
||||
}
|
||||
|
||||
@@ -140,7 +139,7 @@ func enforceRetentionBypassForDelete(ctx context.Context, r *http.Request, bucke
|
||||
if !byPassSet {
|
||||
t, err := objectlock.UTCNowNTP()
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
internalLogIf(ctx, err, logger.WarningKind)
|
||||
return ObjectLocked{}
|
||||
}
|
||||
|
||||
@@ -170,7 +169,7 @@ func enforceRetentionBypassForPut(ctx context.Context, r *http.Request, oi Objec
|
||||
|
||||
t, err := objectlock.UTCNowNTP()
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
internalLogIf(ctx, err, logger.WarningKind)
|
||||
return ObjectLocked{Bucket: oi.Bucket, Object: oi.Name, VersionID: oi.VersionID}
|
||||
}
|
||||
|
||||
@@ -277,7 +276,7 @@ func checkPutObjectLockAllowed(ctx context.Context, rq *http.Request, bucket, ob
|
||||
r := objectlock.GetObjectRetentionMeta(objInfo.UserDefined)
|
||||
t, err := objectlock.UTCNowNTP()
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
internalLogIf(ctx, err, logger.WarningKind)
|
||||
return mode, retainDate, legalHold, ErrObjectLocked
|
||||
}
|
||||
if r.Mode == objectlock.RetCompliance && r.RetainUntilDate.After(t) {
|
||||
@@ -324,7 +323,7 @@ func checkPutObjectLockAllowed(ctx context.Context, rq *http.Request, bucket, ob
|
||||
|
||||
t, err := objectlock.UTCNowNTP()
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
internalLogIf(ctx, err, logger.WarningKind)
|
||||
return mode, retainDate, legalHold, ErrObjectLocked
|
||||
}
|
||||
|
||||
|
||||
@@ -113,7 +113,7 @@ func (api objectAPIHandlers) PutBucketPolicyHandler(w http.ResponseWriter, r *ht
|
||||
}
|
||||
|
||||
// Call site replication hook.
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
replLogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
Type: madmin.SRBucketMetaTypePolicy,
|
||||
Bucket: bucket,
|
||||
Policy: bucketPolicyBytes,
|
||||
@@ -157,7 +157,7 @@ func (api objectAPIHandlers) DeleteBucketPolicyHandler(w http.ResponseWriter, r
|
||||
}
|
||||
|
||||
// Call site replication hook.
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
replLogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
Type: madmin.SRBucketMetaTypePolicy,
|
||||
Bucket: bucket,
|
||||
UpdatedAt: updatedAt,
|
||||
|
||||
@@ -53,7 +53,7 @@ func (sys *PolicySys) IsAllowed(args policy.BucketPolicyArgs) bool {
|
||||
|
||||
// Log unhandled errors.
|
||||
if _, ok := err.(BucketPolicyNotFound); !ok {
|
||||
logger.LogIf(GlobalContext, err)
|
||||
internalLogIf(GlobalContext, err, logger.WarningKind)
|
||||
}
|
||||
|
||||
// As policy is not available for given bucket name, returns IsOwner i.e.
|
||||
|
||||
+8
-8
@@ -49,8 +49,8 @@ var bucketStorageCache = cachevalue.New[DataUsageInfo]()
|
||||
func (sys *BucketQuotaSys) Init(objAPI ObjectLayer) {
|
||||
bucketStorageCache.InitOnce(10*time.Second,
|
||||
cachevalue.Opts{ReturnLastGood: true, NoWait: true},
|
||||
func() (DataUsageInfo, error) {
|
||||
ctx, done := context.WithTimeout(context.Background(), 2*time.Second)
|
||||
func(ctx context.Context) (DataUsageInfo, error) {
|
||||
ctx, done := context.WithTimeout(ctx, 2*time.Second)
|
||||
defer done()
|
||||
|
||||
return loadDataUsageFromBackend(ctx, objAPI)
|
||||
@@ -59,14 +59,14 @@ func (sys *BucketQuotaSys) Init(objAPI ObjectLayer) {
|
||||
}
|
||||
|
||||
// GetBucketUsageInfo return bucket usage info for a given bucket
|
||||
func (sys *BucketQuotaSys) GetBucketUsageInfo(bucket string) (BucketUsageInfo, error) {
|
||||
dui, err := bucketStorageCache.Get()
|
||||
func (sys *BucketQuotaSys) GetBucketUsageInfo(ctx context.Context, bucket string) (BucketUsageInfo, error) {
|
||||
dui, err := bucketStorageCache.GetWithCtx(ctx)
|
||||
timedout := OperationTimedOut{}
|
||||
if err != nil && !errors.Is(err, context.DeadlineExceeded) && !errors.As(err, &timedout) {
|
||||
if len(dui.BucketsUsage) > 0 {
|
||||
logger.LogOnceIf(GlobalContext, fmt.Errorf("unable to retrieve usage information for bucket: %s, relying on older value cached in-memory: err(%v)", bucket, err), "bucket-usage-cache-"+bucket)
|
||||
internalLogOnceIf(GlobalContext, fmt.Errorf("unable to retrieve usage information for bucket: %s, relying on older value cached in-memory: err(%v)", bucket, err), "bucket-usage-cache-"+bucket)
|
||||
} else {
|
||||
logger.LogOnceIf(GlobalContext, errors.New("unable to retrieve usage information for bucket: %s, no reliable usage value available - quota will not be enforced"), "bucket-usage-empty-"+bucket)
|
||||
internalLogOnceIf(GlobalContext, errors.New("unable to retrieve usage information for bucket: %s, no reliable usage value available - quota will not be enforced"), "bucket-usage-empty-"+bucket)
|
||||
}
|
||||
}
|
||||
|
||||
@@ -87,7 +87,7 @@ func parseBucketQuota(bucket string, data []byte) (quotaCfg *madmin.BucketQuota,
|
||||
}
|
||||
if !quotaCfg.IsValid() {
|
||||
if quotaCfg.Type == "fifo" {
|
||||
logger.LogIf(GlobalContext, errors.New("Detected older 'fifo' quota config, 'fifo' feature is removed and not supported anymore. Please clear your quota configs using 'mc admin bucket quota alias/bucket --clear' and use 'mc ilm add' for expiration of objects"))
|
||||
internalLogIf(GlobalContext, errors.New("Detected older 'fifo' quota config, 'fifo' feature is removed and not supported anymore. Please clear your quota configs using 'mc admin bucket quota alias/bucket --clear' and use 'mc ilm add' for expiration of objects"), logger.WarningKind)
|
||||
return quotaCfg, fmt.Errorf("invalid quota type 'fifo'")
|
||||
}
|
||||
return quotaCfg, fmt.Errorf("Invalid quota config %#v", quotaCfg)
|
||||
@@ -118,7 +118,7 @@ func (sys *BucketQuotaSys) enforceQuotaHard(ctx context.Context, bucket string,
|
||||
return BucketQuotaExceeded{Bucket: bucket}
|
||||
}
|
||||
|
||||
bui, err := sys.GetBucketUsageInfo(bucket)
|
||||
bui, err := sys.GetBucketUsageInfo(ctx, bucket)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
+146
-112
@@ -51,6 +51,8 @@ import (
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/tinylib/msgp/msgp"
|
||||
"github.com/zeebo/xxh3"
|
||||
"golang.org/x/exp/maps"
|
||||
"golang.org/x/exp/slices"
|
||||
)
|
||||
|
||||
const (
|
||||
@@ -76,21 +78,13 @@ const (
|
||||
ReplicationWorkerMultiplier = 1.5
|
||||
)
|
||||
|
||||
func isReplicationEnabled(ctx context.Context, bucketName string) bool {
|
||||
rc, _ := getReplicationConfig(ctx, bucketName)
|
||||
return rc != nil
|
||||
}
|
||||
|
||||
// gets replication config associated to a given bucket name.
|
||||
func getReplicationConfig(ctx context.Context, bucketName string) (rc *replication.Config, err error) {
|
||||
rCfg, _, err := globalBucketMetadataSys.GetReplicationConfig(ctx, bucketName)
|
||||
if err != nil {
|
||||
if errors.Is(err, BucketReplicationConfigNotFound{Bucket: bucketName}) || errors.Is(err, errInvalidArgument) {
|
||||
return rCfg, err
|
||||
}
|
||||
logger.CriticalIf(ctx, err)
|
||||
if err != nil && !errors.Is(err, BucketReplicationConfigNotFound{Bucket: bucketName}) {
|
||||
return rCfg, err
|
||||
}
|
||||
return rCfg, err
|
||||
return rCfg, nil
|
||||
}
|
||||
|
||||
// validateReplicationDestination returns error if replication destination bucket missing or not configured
|
||||
@@ -264,10 +258,16 @@ func mustReplicate(ctx context.Context, bucket, object string, mopts mustReplica
|
||||
if mopts.replicationRequest { // incoming replication request on target cluster
|
||||
return
|
||||
}
|
||||
|
||||
cfg, err := getReplicationConfig(ctx, bucket)
|
||||
if err != nil {
|
||||
replLogOnceIf(ctx, err, bucket)
|
||||
return
|
||||
}
|
||||
if cfg == nil {
|
||||
return
|
||||
}
|
||||
|
||||
opts := replication.ObjectOpts{
|
||||
Name: object,
|
||||
SSEC: crypto.SSEC.IsEncrypted(mopts.meta),
|
||||
@@ -315,6 +315,7 @@ var standardHeaders = []string{
|
||||
func hasReplicationRules(ctx context.Context, bucket string, objects []ObjectToDelete) bool {
|
||||
c, err := getReplicationConfig(ctx, bucket)
|
||||
if err != nil || c == nil {
|
||||
replLogOnceIf(ctx, err, bucket)
|
||||
return false
|
||||
}
|
||||
for _, obj := range objects {
|
||||
@@ -334,6 +335,7 @@ func isStandardHeader(matchHeaderKey string) bool {
|
||||
func checkReplicateDelete(ctx context.Context, bucket string, dobj ObjectToDelete, oi ObjectInfo, delOpts ObjectOptions, gerr error) (dsc ReplicateDecision) {
|
||||
rcfg, err := getReplicationConfig(ctx, bucket)
|
||||
if err != nil || rcfg == nil {
|
||||
replLogOnceIf(ctx, err, bucket)
|
||||
return
|
||||
}
|
||||
// If incoming request is a replication request, it does not need to be re-replicated.
|
||||
@@ -426,7 +428,7 @@ func replicateDelete(ctx context.Context, dobj DeletedObjectReplicationInfo, obj
|
||||
|
||||
rcfg, err := getReplicationConfig(ctx, bucket)
|
||||
if err != nil || rcfg == nil {
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("unable to obtain replication config for bucket: %s: err: %s", bucket, err), bucket)
|
||||
replLogOnceIf(ctx, fmt.Errorf("unable to obtain replication config for bucket: %s: err: %s", bucket, err), bucket)
|
||||
sendEvent(eventArgs{
|
||||
BucketName: bucket,
|
||||
Object: ObjectInfo{
|
||||
@@ -443,7 +445,7 @@ func replicateDelete(ctx context.Context, dobj DeletedObjectReplicationInfo, obj
|
||||
}
|
||||
dsc, err := parseReplicateDecision(ctx, bucket, dobj.ReplicationState.ReplicateDecisionStr)
|
||||
if err != nil {
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("unable to parse replication decision parameters for bucket: %s, err: %s, decision: %s",
|
||||
replLogOnceIf(ctx, fmt.Errorf("unable to parse replication decision parameters for bucket: %s, err: %s, decision: %s",
|
||||
bucket, err, dobj.ReplicationState.ReplicateDecisionStr), dobj.ReplicationState.ReplicateDecisionStr)
|
||||
sendEvent(eventArgs{
|
||||
BucketName: bucket,
|
||||
@@ -497,7 +499,7 @@ func replicateDelete(ctx context.Context, dobj DeletedObjectReplicationInfo, obj
|
||||
tgtClnt := globalBucketTargetSys.GetRemoteTargetClient(bucket, tgtEntry.Arn)
|
||||
if tgtClnt == nil {
|
||||
// Skip stale targets if any and log them to be missing at least once.
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("failed to get target for bucket:%s arn:%s", bucket, tgtEntry.Arn), tgtEntry.Arn)
|
||||
replLogOnceIf(ctx, fmt.Errorf("failed to get target for bucket:%s arn:%s", bucket, tgtEntry.Arn), tgtEntry.Arn)
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
BucketName: bucket,
|
||||
@@ -609,7 +611,7 @@ func replicateDeleteToTarget(ctx context.Context, dobj DeletedObjectReplicationI
|
||||
return
|
||||
}
|
||||
if globalBucketTargetSys.isOffline(tgt.EndpointURL()) {
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("remote target is offline for bucket:%s arn:%s", dobj.Bucket, tgt.ARN), "replication-target-offline-delete-"+tgt.ARN)
|
||||
replLogOnceIf(ctx, fmt.Errorf("remote target is offline for bucket:%s arn:%s", dobj.Bucket, tgt.ARN), "replication-target-offline-delete-"+tgt.ARN)
|
||||
sendEvent(eventArgs{
|
||||
BucketName: dobj.Bucket,
|
||||
Object: ObjectInfo{
|
||||
@@ -684,7 +686,7 @@ func replicateDeleteToTarget(ctx context.Context, dobj DeletedObjectReplicationI
|
||||
} else {
|
||||
rinfo.VersionPurgeStatus = Failed
|
||||
}
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to replicate delete marker to %s: %s/%s(%s): %w", tgt.EndpointURL(), tgt.Bucket, dobj.ObjectName, versionID, rmErr))
|
||||
replLogIf(ctx, fmt.Errorf("unable to replicate delete marker to %s: %s/%s(%s): %w", tgt.EndpointURL(), tgt.Bucket, dobj.ObjectName, versionID, rmErr))
|
||||
if rmErr != nil && minio.IsNetworkOrHostDown(rmErr, true) && !globalBucketTargetSys.isOffline(tgt.EndpointURL()) {
|
||||
globalBucketTargetSys.markOffline(tgt.EndpointURL())
|
||||
}
|
||||
@@ -764,13 +766,20 @@ func (m caseInsensitiveMap) Lookup(key string) (string, bool) {
|
||||
func putReplicationOpts(ctx context.Context, sc string, objInfo ObjectInfo) (putOpts minio.PutObjectOptions, err error) {
|
||||
meta := make(map[string]string)
|
||||
for k, v := range objInfo.UserDefined {
|
||||
if stringsHasPrefixFold(k, ReservedMetadataPrefixLower) {
|
||||
continue
|
||||
// In case of SSE-C objects copy the allowed internal headers as well
|
||||
if !crypto.SSEC.IsEncrypted(objInfo.UserDefined) || !slices.Contains(maps.Keys(validSSEReplicationHeaders), k) {
|
||||
if stringsHasPrefixFold(k, ReservedMetadataPrefixLower) {
|
||||
continue
|
||||
}
|
||||
if isStandardHeader(k) {
|
||||
continue
|
||||
}
|
||||
}
|
||||
if isStandardHeader(k) {
|
||||
continue
|
||||
if slices.Contains(maps.Keys(validSSEReplicationHeaders), k) {
|
||||
meta[validSSEReplicationHeaders[k]] = v
|
||||
} else {
|
||||
meta[k] = v
|
||||
}
|
||||
meta[k] = v
|
||||
}
|
||||
|
||||
if sc == "" && (objInfo.StorageClass == storageclass.STANDARD || objInfo.StorageClass == storageclass.RRS) {
|
||||
@@ -989,8 +998,8 @@ func replicateObject(ctx context.Context, ri ReplicateObjectInfo, objectAPI Obje
|
||||
object := ri.Name
|
||||
|
||||
cfg, err := getReplicationConfig(ctx, bucket)
|
||||
if err != nil {
|
||||
logger.LogOnceIf(ctx, err, "get-replication-config-"+bucket)
|
||||
if err != nil || cfg == nil {
|
||||
replLogOnceIf(ctx, err, "get-replication-config-"+bucket)
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
BucketName: bucket,
|
||||
@@ -1029,7 +1038,7 @@ func replicateObject(ctx context.Context, ri ReplicateObjectInfo, objectAPI Obje
|
||||
for _, tgtArn := range tgtArns {
|
||||
tgt := globalBucketTargetSys.GetRemoteTargetClient(bucket, tgtArn)
|
||||
if tgt == nil {
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("failed to get target for bucket:%s arn:%s", bucket, tgtArn), tgtArn)
|
||||
replLogOnceIf(ctx, fmt.Errorf("failed to get target for bucket:%s arn:%s", bucket, tgtArn), tgtArn)
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
BucketName: bucket,
|
||||
@@ -1151,7 +1160,7 @@ func (ri ReplicateObjectInfo) replicateObject(ctx context.Context, objectAPI Obj
|
||||
}
|
||||
|
||||
if globalBucketTargetSys.isOffline(tgt.EndpointURL()) {
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("remote target is offline for bucket:%s arn:%s retry:%d", bucket, tgt.ARN, ri.RetryCount), "replication-target-offline"+tgt.ARN)
|
||||
replLogOnceIf(ctx, fmt.Errorf("remote target is offline for bucket:%s arn:%s retry:%d", bucket, tgt.ARN, ri.RetryCount), "replication-target-offline"+tgt.ARN)
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
BucketName: bucket,
|
||||
@@ -1166,9 +1175,10 @@ func (ri ReplicateObjectInfo) replicateObject(ctx context.Context, objectAPI Obj
|
||||
versionSuspended := globalBucketVersioningSys.PrefixSuspended(bucket, object)
|
||||
|
||||
gr, err := objectAPI.GetObjectNInfo(ctx, bucket, object, nil, http.Header{}, ObjectOptions{
|
||||
VersionID: ri.VersionID,
|
||||
Versioned: versioned,
|
||||
VersionSuspended: versionSuspended,
|
||||
VersionID: ri.VersionID,
|
||||
Versioned: versioned,
|
||||
VersionSuspended: versionSuspended,
|
||||
ReplicationRequest: true,
|
||||
})
|
||||
if err != nil {
|
||||
if !isErrVersionNotFound(err) && !isErrObjectNotFound(err) {
|
||||
@@ -1180,7 +1190,7 @@ func (ri ReplicateObjectInfo) replicateObject(ctx context.Context, objectAPI Obj
|
||||
UserAgent: "Internal: [Replication]",
|
||||
Host: globalLocalNodeName,
|
||||
})
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("unable to read source object %s/%s(%s): %w", bucket, object, objInfo.VersionID, err), object+":"+objInfo.VersionID)
|
||||
replLogOnceIf(ctx, fmt.Errorf("unable to read source object %s/%s(%s): %w", bucket, object, objInfo.VersionID, err), object+":"+objInfo.VersionID)
|
||||
}
|
||||
return
|
||||
}
|
||||
@@ -1193,7 +1203,7 @@ func (ri ReplicateObjectInfo) replicateObject(ctx context.Context, objectAPI Obj
|
||||
|
||||
size, err := objInfo.GetActualSize()
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
replLogIf(ctx, err)
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
BucketName: bucket,
|
||||
@@ -1205,7 +1215,7 @@ func (ri ReplicateObjectInfo) replicateObject(ctx context.Context, objectAPI Obj
|
||||
}
|
||||
|
||||
if tgt.Bucket == "" {
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to replicate object %s(%s), bucket is empty for target %s", objInfo.Name, objInfo.VersionID, tgt.EndpointURL()))
|
||||
replLogIf(ctx, fmt.Errorf("unable to replicate object %s(%s), bucket is empty for target %s", objInfo.Name, objInfo.VersionID, tgt.EndpointURL()))
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
BucketName: bucket,
|
||||
@@ -1231,7 +1241,7 @@ func (ri ReplicateObjectInfo) replicateObject(ctx context.Context, objectAPI Obj
|
||||
|
||||
putOpts, err := putReplicationOpts(ctx, tgt.StorageClass, objInfo)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("failure setting options for replication bucket:%s err:%w", bucket, err))
|
||||
replLogIf(ctx, fmt.Errorf("failure setting options for replication bucket:%s err:%w", bucket, err))
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
BucketName: bucket,
|
||||
@@ -1262,23 +1272,19 @@ func (ri ReplicateObjectInfo) replicateObject(ctx context.Context, objectAPI Obj
|
||||
}
|
||||
r := bandwidth.NewMonitoredReader(newCtx, globalBucketMonitor, gr, opts)
|
||||
if objInfo.isMultipart() {
|
||||
if rinfo.Err = replicateObjectWithMultipart(ctx, c, tgt.Bucket, object,
|
||||
r, objInfo, putOpts); rinfo.Err != nil {
|
||||
if minio.ToErrorResponse(rinfo.Err).Code != "PreconditionFailed" {
|
||||
rinfo.ReplicationStatus = replication.Failed
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to replicate for object %s/%s(%s): %s (target: %s)", bucket, objInfo.Name, objInfo.VersionID, rinfo.Err, tgt.EndpointURL()))
|
||||
}
|
||||
}
|
||||
rinfo.Err = replicateObjectWithMultipart(ctx, c, tgt.Bucket, object, r, objInfo, putOpts)
|
||||
} else {
|
||||
if _, rinfo.Err = c.PutObject(ctx, tgt.Bucket, object, r, size, "", "", putOpts); rinfo.Err != nil {
|
||||
if minio.ToErrorResponse(rinfo.Err).Code != "PreconditionFailed" {
|
||||
rinfo.ReplicationStatus = replication.Failed
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to replicate for object %s/%s(%s): %s (target: %s)", bucket, objInfo.Name, objInfo.VersionID, rinfo.Err, tgt.EndpointURL()))
|
||||
}
|
||||
}
|
||||
_, rinfo.Err = c.PutObject(ctx, tgt.Bucket, object, r, size, "", "", putOpts)
|
||||
}
|
||||
if rinfo.Err != nil && minio.IsNetworkOrHostDown(rinfo.Err, true) && !globalBucketTargetSys.isOffline(tgt.EndpointURL()) {
|
||||
globalBucketTargetSys.markOffline(tgt.EndpointURL())
|
||||
if rinfo.Err != nil {
|
||||
if minio.ToErrorResponse(rinfo.Err).Code != "PreconditionFailed" {
|
||||
rinfo.ReplicationStatus = replication.Failed
|
||||
replLogIf(ctx, fmt.Errorf("unable to replicate for object %s/%s(%s): to (target: %s): %w",
|
||||
bucket, objInfo.Name, objInfo.VersionID, tgt.EndpointURL(), rinfo.Err))
|
||||
}
|
||||
if minio.IsNetworkOrHostDown(rinfo.Err, true) && !globalBucketTargetSys.isOffline(tgt.EndpointURL()) {
|
||||
globalBucketTargetSys.markOffline(tgt.EndpointURL())
|
||||
}
|
||||
}
|
||||
return
|
||||
}
|
||||
@@ -1308,7 +1314,7 @@ func (ri ReplicateObjectInfo) replicateAll(ctx context.Context, objectAPI Object
|
||||
}
|
||||
|
||||
if globalBucketTargetSys.isOffline(tgt.EndpointURL()) {
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("remote target is offline for bucket:%s arn:%s retry:%d", bucket, tgt.ARN, ri.RetryCount), "replication-target-offline-heal"+tgt.ARN)
|
||||
replLogOnceIf(ctx, fmt.Errorf("remote target is offline for bucket:%s arn:%s retry:%d", bucket, tgt.ARN, ri.RetryCount), "replication-target-offline-heal"+tgt.ARN)
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
BucketName: bucket,
|
||||
@@ -1322,11 +1328,13 @@ func (ri ReplicateObjectInfo) replicateAll(ctx context.Context, objectAPI Object
|
||||
versioned := globalBucketVersioningSys.PrefixEnabled(bucket, object)
|
||||
versionSuspended := globalBucketVersioningSys.PrefixSuspended(bucket, object)
|
||||
|
||||
gr, err := objectAPI.GetObjectNInfo(ctx, bucket, object, nil, http.Header{}, ObjectOptions{
|
||||
VersionID: ri.VersionID,
|
||||
Versioned: versioned,
|
||||
VersionSuspended: versionSuspended,
|
||||
})
|
||||
gr, err := objectAPI.GetObjectNInfo(ctx, bucket, object, nil, http.Header{},
|
||||
ObjectOptions{
|
||||
VersionID: ri.VersionID,
|
||||
Versioned: versioned,
|
||||
VersionSuspended: versionSuspended,
|
||||
ReplicationRequest: true,
|
||||
})
|
||||
if err != nil {
|
||||
if !isErrVersionNotFound(err) && !isErrObjectNotFound(err) {
|
||||
objInfo := ri.ToObjectInfo()
|
||||
@@ -1337,13 +1345,14 @@ func (ri ReplicateObjectInfo) replicateAll(ctx context.Context, objectAPI Object
|
||||
UserAgent: "Internal: [Replication]",
|
||||
Host: globalLocalNodeName,
|
||||
})
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to replicate to target %s for %s/%s(%s): %w", tgt.EndpointURL(), bucket, object, objInfo.VersionID, err))
|
||||
replLogIf(ctx, fmt.Errorf("unable to replicate to target %s for %s/%s(%s): %w", tgt.EndpointURL(), bucket, object, objInfo.VersionID, err))
|
||||
}
|
||||
return
|
||||
}
|
||||
defer gr.Close()
|
||||
|
||||
objInfo := gr.ObjInfo
|
||||
|
||||
// make sure we have the latest metadata for metrics calculation
|
||||
rinfo.PrevReplicationStatus = objInfo.TargetReplicationStatus(tgt.ARN)
|
||||
|
||||
@@ -1356,7 +1365,7 @@ func (ri ReplicateObjectInfo) replicateAll(ctx context.Context, objectAPI Object
|
||||
|
||||
size, err := objInfo.GetActualSize()
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
replLogIf(ctx, err)
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
BucketName: bucket,
|
||||
@@ -1367,8 +1376,13 @@ func (ri ReplicateObjectInfo) replicateAll(ctx context.Context, objectAPI Object
|
||||
return
|
||||
}
|
||||
|
||||
// Set the encrypted size for SSE-C objects
|
||||
if crypto.SSEC.IsEncrypted(objInfo.UserDefined) {
|
||||
size = objInfo.Size
|
||||
}
|
||||
|
||||
if tgt.Bucket == "" {
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to replicate object %s(%s) to %s, target bucket is missing", objInfo.Name, objInfo.VersionID, tgt.EndpointURL()))
|
||||
replLogIf(ctx, fmt.Errorf("unable to replicate object %s(%s) to %s, target bucket is missing", objInfo.Name, objInfo.VersionID, tgt.EndpointURL()))
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
BucketName: bucket,
|
||||
@@ -1398,7 +1412,7 @@ func (ri ReplicateObjectInfo) replicateAll(ctx context.Context, objectAPI Object
|
||||
if rAction == replicateNone {
|
||||
if ri.OpType == replication.ExistingObjectReplicationType &&
|
||||
objInfo.ModTime.Unix() > oi.LastModified.Unix() && objInfo.VersionID == nullVersionID {
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to replicate %s/%s (null). Newer version exists on target %s", bucket, object, tgt.EndpointURL()))
|
||||
replLogIf(ctx, fmt.Errorf("unable to replicate %s/%s (null). Newer version exists on target %s", bucket, object, tgt.EndpointURL()))
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
BucketName: bucket,
|
||||
@@ -1438,7 +1452,7 @@ func (ri ReplicateObjectInfo) replicateAll(ctx context.Context, objectAPI Object
|
||||
rAction = replicateAll
|
||||
default:
|
||||
rinfo.Err = cerr
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to replicate %s/%s (%s). Target (%s) returned %s error on HEAD",
|
||||
replLogIf(ctx, fmt.Errorf("unable to replicate %s/%s (%s). Target (%s) returned %s error on HEAD",
|
||||
bucket, object, objInfo.VersionID, tgt.EndpointURL(), cerr))
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
@@ -1488,13 +1502,13 @@ func (ri ReplicateObjectInfo) replicateAll(ctx context.Context, objectAPI Object
|
||||
}
|
||||
if _, rinfo.Err = c.CopyObject(ctx, tgt.Bucket, object, tgt.Bucket, object, getCopyObjMetadata(objInfo, tgt.StorageClass), srcOpts, dstOpts); rinfo.Err != nil {
|
||||
rinfo.ReplicationStatus = replication.Failed
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to replicate metadata for object %s/%s(%s) to target %s: %w", bucket, objInfo.Name, objInfo.VersionID, tgt.EndpointURL(), rinfo.Err))
|
||||
replLogIf(ctx, fmt.Errorf("unable to replicate metadata for object %s/%s(%s) to target %s: %w", bucket, objInfo.Name, objInfo.VersionID, tgt.EndpointURL(), rinfo.Err))
|
||||
}
|
||||
} else {
|
||||
var putOpts minio.PutObjectOptions
|
||||
putOpts, err = putReplicationOpts(ctx, tgt.StorageClass, objInfo)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("failed to set replicate options for object %s/%s(%s) (target %s) err:%w", bucket, objInfo.Name, objInfo.VersionID, tgt.EndpointURL(), err))
|
||||
replLogIf(ctx, fmt.Errorf("failed to set replicate options for object %s/%s(%s) (target %s) err:%w", bucket, objInfo.Name, objInfo.VersionID, tgt.EndpointURL(), err))
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectReplicationNotTracked,
|
||||
BucketName: bucket,
|
||||
@@ -1524,24 +1538,14 @@ func (ri ReplicateObjectInfo) replicateAll(ctx context.Context, objectAPI Object
|
||||
}
|
||||
r := bandwidth.NewMonitoredReader(newCtx, globalBucketMonitor, gr, opts)
|
||||
if objInfo.isMultipart() {
|
||||
if rinfo.Err = replicateObjectWithMultipart(ctx, c, tgt.Bucket, object,
|
||||
r, objInfo, putOpts); rinfo.Err != nil {
|
||||
if minio.ToErrorResponse(rinfo.Err).Code != "PreconditionFailed" {
|
||||
rinfo.ReplicationStatus = replication.Failed
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to replicate for object %s/%s(%s) to target %s: %w", bucket, objInfo.Name, objInfo.VersionID, tgt.EndpointURL(), rinfo.Err))
|
||||
} else {
|
||||
rinfo.ReplicationStatus = replication.Completed
|
||||
}
|
||||
}
|
||||
rinfo.Err = replicateObjectWithMultipart(ctx, c, tgt.Bucket, object, r, objInfo, putOpts)
|
||||
} else {
|
||||
if _, rinfo.Err = c.PutObject(ctx, tgt.Bucket, object, r, size, "", "", putOpts); rinfo.Err != nil {
|
||||
if minio.ToErrorResponse(rinfo.Err).Code != "PreconditionFailed" {
|
||||
rinfo.ReplicationStatus = replication.Failed
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to replicate for object %s/%s(%s) to target %s: %w", bucket, objInfo.Name, objInfo.VersionID, tgt.EndpointURL(), rinfo.Err))
|
||||
} else {
|
||||
rinfo.ReplicationStatus = replication.Completed
|
||||
}
|
||||
}
|
||||
_, rinfo.Err = c.PutObject(ctx, tgt.Bucket, object, r, size, "", "", putOpts)
|
||||
}
|
||||
if rinfo.Err != nil && minio.ToErrorResponse(rinfo.Err).Code != "PreconditionFailed" {
|
||||
rinfo.ReplicationStatus = replication.Failed
|
||||
replLogIf(ctx, fmt.Errorf("unable to replicate for object %s/%s(%s) to target %s: %w",
|
||||
bucket, objInfo.Name, objInfo.VersionID, tgt.EndpointURL(), rinfo.Err))
|
||||
}
|
||||
if rinfo.Err != nil && minio.IsNetworkOrHostDown(rinfo.Err, true) && !globalBucketTargetSys.isOffline(tgt.EndpointURL()) {
|
||||
globalBucketTargetSys.markOffline(tgt.EndpointURL())
|
||||
@@ -1580,14 +1584,10 @@ func replicateObjectWithMultipart(ctx context.Context, c *minio.Core, bucket, ob
|
||||
for attempts <= 3 {
|
||||
actx, acancel := context.WithTimeout(ctx, time.Minute)
|
||||
aerr := c.AbortMultipartUpload(actx, bucket, object, uploadID)
|
||||
acancel()
|
||||
if aerr == nil {
|
||||
acancel()
|
||||
return
|
||||
}
|
||||
acancel()
|
||||
logger.LogIf(actx,
|
||||
fmt.Errorf("trying %s: Unable to cleanup failed multipart replication %s on remote %s/%s: %w - this may consume space on remote cluster",
|
||||
humanize.Ordinal(attempts), uploadID, bucket, object, aerr))
|
||||
attempts++
|
||||
time.Sleep(time.Duration(rand.Int63n(int64(time.Second))))
|
||||
}
|
||||
@@ -1599,21 +1599,35 @@ func replicateObjectWithMultipart(ctx context.Context, c *minio.Core, bucket, ob
|
||||
pInfo minio.ObjectPart
|
||||
)
|
||||
|
||||
var objectSize int64
|
||||
for _, partInfo := range objInfo.Parts {
|
||||
hr, err = hash.NewReader(ctx, io.LimitReader(r, partInfo.ActualSize), partInfo.ActualSize, "", "", partInfo.ActualSize)
|
||||
if crypto.SSEC.IsEncrypted(objInfo.UserDefined) {
|
||||
hr, err = hash.NewReader(ctx, io.LimitReader(r, partInfo.Size), partInfo.Size, "", "", partInfo.ActualSize)
|
||||
} else {
|
||||
hr, err = hash.NewReader(ctx, io.LimitReader(r, partInfo.ActualSize), partInfo.ActualSize, "", "", partInfo.ActualSize)
|
||||
}
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
cHeader := http.Header{}
|
||||
cHeader.Add(xhttp.MinIOSourceReplicationRequest, "true")
|
||||
popts := minio.PutObjectPartOptions{
|
||||
SSE: opts.ServerSideEncryption,
|
||||
SSE: opts.ServerSideEncryption,
|
||||
CustomHeader: cHeader,
|
||||
}
|
||||
|
||||
pInfo, err = c.PutObjectPart(ctx, bucket, object, uploadID, partInfo.Number, hr, partInfo.ActualSize, popts)
|
||||
if crypto.SSEC.IsEncrypted(objInfo.UserDefined) {
|
||||
objectSize += partInfo.Size
|
||||
pInfo, err = c.PutObjectPart(ctx, bucket, object, uploadID, partInfo.Number, hr, partInfo.Size, popts)
|
||||
} else {
|
||||
objectSize += partInfo.ActualSize
|
||||
pInfo, err = c.PutObjectPart(ctx, bucket, object, uploadID, partInfo.Number, hr, partInfo.ActualSize, popts)
|
||||
}
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
if pInfo.Size != partInfo.ActualSize {
|
||||
if !crypto.SSEC.IsEncrypted(objInfo.UserDefined) && pInfo.Size != partInfo.ActualSize {
|
||||
return fmt.Errorf("Part size mismatch: got %d, want %d", pInfo.Size, partInfo.ActualSize)
|
||||
}
|
||||
uploadedParts = append(uploadedParts, minio.CompletePart{
|
||||
@@ -1621,9 +1635,12 @@ func replicateObjectWithMultipart(ctx context.Context, c *minio.Core, bucket, ob
|
||||
ETag: pInfo.ETag,
|
||||
})
|
||||
}
|
||||
|
||||
// really big value but its okay on heavily loaded systems. This is just tail end timeout.
|
||||
cctx, ccancel := context.WithTimeout(ctx, 10*time.Minute)
|
||||
defer ccancel()
|
||||
_, err = c.CompleteMultipartUpload(cctx, bucket, object, uploadID, uploadedParts, minio.PutObjectOptions{
|
||||
UserMetadata: map[string]string{validSSEReplicationHeaders[ReservedMetadataPrefix+"Actual-Object-Size"]: objInfo.UserDefined[ReservedMetadataPrefix+"actual-size"]},
|
||||
Internal: minio.AdvancedPutOptions{
|
||||
SourceMTime: objInfo.ModTime,
|
||||
// always set this to distinguish between `mc mirror` replication and serverside
|
||||
@@ -1838,7 +1855,7 @@ func (p *ReplicationPool) AddMRFWorker() {
|
||||
globalReplicationStats.decQ(v.Bucket, v.Size, v.DeleteMarker, v.OpType)
|
||||
|
||||
default:
|
||||
logger.LogOnceIf(p.ctx, fmt.Errorf("unknown mrf replication type: %T", oi), "unknown-mrf-replicate-type")
|
||||
bugLogIf(p.ctx, fmt.Errorf("unknown mrf replication type: %T", oi), "unknown-mrf-replicate-type")
|
||||
}
|
||||
case <-p.mrfWorkerKillCh:
|
||||
return
|
||||
@@ -1882,7 +1899,7 @@ func (p *ReplicationPool) AddWorker(input <-chan ReplicationWorkerOperation, opT
|
||||
atomic.AddInt32(opTracker, -1)
|
||||
}
|
||||
default:
|
||||
logger.LogOnceIf(p.ctx, fmt.Errorf("unknown replication type: %T", oi), "unknown-replicate-type")
|
||||
bugLogIf(p.ctx, fmt.Errorf("unknown replication type: %T", oi), "unknown-replicate-type")
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -1921,7 +1938,7 @@ func (p *ReplicationPool) AddLargeWorker(input <-chan ReplicationWorkerOperation
|
||||
case DeletedObjectReplicationInfo:
|
||||
replicateDelete(p.ctx, v, p.objLayer)
|
||||
default:
|
||||
logger.LogOnceIf(p.ctx, fmt.Errorf("unknown replication type: %T", oi), "unknown-replicate-type")
|
||||
bugLogIf(p.ctx, fmt.Errorf("unknown replication type: %T", oi), "unknown-replicate-type")
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -2068,9 +2085,9 @@ func (p *ReplicationPool) queueReplicaTask(ri ReplicateObjectInfo) {
|
||||
p.mu.RUnlock()
|
||||
switch prio {
|
||||
case "fast":
|
||||
logger.LogOnceIf(GlobalContext, fmt.Errorf("WARNING: Unable to keep up with incoming traffic"), string(replicationSubsystem))
|
||||
replLogOnceIf(GlobalContext, fmt.Errorf("Unable to keep up with incoming traffic"), string(replicationSubsystem), logger.WarningKind)
|
||||
case "slow":
|
||||
logger.LogOnceIf(GlobalContext, fmt.Errorf("WARNING: Unable to keep up with incoming traffic - we recommend increasing replication priority with `mc admin config set api replication_priority=auto`"), string(replicationSubsystem))
|
||||
replLogOnceIf(GlobalContext, fmt.Errorf("Unable to keep up with incoming traffic - we recommend increasing replication priority with `mc admin config set api replication_priority=auto`"), string(replicationSubsystem), logger.WarningKind)
|
||||
default:
|
||||
maxWorkers = min(maxWorkers, WorkerMaxLimit)
|
||||
if p.ActiveWorkers() < maxWorkers {
|
||||
@@ -2125,9 +2142,9 @@ func (p *ReplicationPool) queueReplicaDeleteTask(doi DeletedObjectReplicationInf
|
||||
p.mu.RUnlock()
|
||||
switch prio {
|
||||
case "fast":
|
||||
logger.LogOnceIf(GlobalContext, fmt.Errorf("WARNING: Unable to keep up with incoming deletes"), string(replicationSubsystem))
|
||||
replLogOnceIf(GlobalContext, fmt.Errorf("Unable to keep up with incoming deletes"), string(replicationSubsystem), logger.WarningKind)
|
||||
case "slow":
|
||||
logger.LogOnceIf(GlobalContext, fmt.Errorf("WARNING: Unable to keep up with incoming deletes - we recommend increasing replication priority with `mc admin config set api replication_priority=auto`"), string(replicationSubsystem))
|
||||
replLogOnceIf(GlobalContext, fmt.Errorf("Unable to keep up with incoming deletes - we recommend increasing replication priority with `mc admin config set api replication_priority=auto`"), string(replicationSubsystem), logger.WarningKind)
|
||||
default:
|
||||
maxWorkers = min(maxWorkers, WorkerMaxLimit)
|
||||
if p.ActiveWorkers() < maxWorkers {
|
||||
@@ -2219,6 +2236,8 @@ func getProxyTargets(ctx context.Context, bucket, object string, opts ObjectOpti
|
||||
}
|
||||
cfg, err := getReplicationConfig(ctx, bucket)
|
||||
if err != nil || cfg == nil {
|
||||
replLogOnceIf(ctx, err, bucket)
|
||||
|
||||
return &madmin.BucketTargets{}
|
||||
}
|
||||
topts := replication.ObjectOpts{Name: object}
|
||||
@@ -2260,7 +2279,7 @@ func proxyHeadToRepTarget(ctx context.Context, bucket, object string, rs *HTTPRa
|
||||
if rs != nil {
|
||||
h, err := rs.ToHeader()
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("invalid range header for %s/%s(%s) - %w", bucket, object, opts.VersionID, err))
|
||||
replLogIf(ctx, fmt.Errorf("invalid range header for %s/%s(%s) - %w", bucket, object, opts.VersionID, err))
|
||||
continue
|
||||
}
|
||||
gopts.Set(xhttp.Range, h)
|
||||
@@ -2628,7 +2647,7 @@ func (s *replicationResyncer) PersistToDisk(ctx context.Context, objectAPI Objec
|
||||
}
|
||||
if updt {
|
||||
if err := saveResyncStatus(ctx, bucket, brs, objectAPI); err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("could not save resync metadata to drive for %s - %w", bucket, err))
|
||||
replLogIf(ctx, fmt.Errorf("could not save resync metadata to drive for %s - %w", bucket, err))
|
||||
} else {
|
||||
lastResyncStatusSave[bucket] = brs.LastUpdate
|
||||
}
|
||||
@@ -2713,15 +2732,15 @@ func (s *replicationResyncer) resyncBucket(ctx context.Context, objectAPI Object
|
||||
s.workerCh <- struct{}{}
|
||||
}()
|
||||
// Allocate new results channel to receive ObjectInfo.
|
||||
objInfoCh := make(chan ObjectInfo)
|
||||
objInfoCh := make(chan itemOrErr[ObjectInfo])
|
||||
cfg, err := getReplicationConfig(ctx, opts.bucket)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("replication resync of %s for arn %s failed with %w", opts.bucket, opts.arn, err))
|
||||
replLogIf(ctx, fmt.Errorf("replication resync of %s for arn %s failed with %w", opts.bucket, opts.arn, err))
|
||||
return
|
||||
}
|
||||
tgts, err := globalBucketTargetSys.ListBucketTargets(ctx, opts.bucket)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("replication resync of %s for arn %s failed %w", opts.bucket, opts.arn, err))
|
||||
replLogIf(ctx, fmt.Errorf("replication resync of %s for arn %s failed %w", opts.bucket, opts.arn, err))
|
||||
return
|
||||
}
|
||||
rcfg := replicationConfig{
|
||||
@@ -2734,12 +2753,12 @@ func (s *replicationResyncer) resyncBucket(ctx context.Context, objectAPI Object
|
||||
TargetArn: opts.arn,
|
||||
})
|
||||
if len(tgtArns) != 1 {
|
||||
logger.LogIf(ctx, fmt.Errorf("replication resync failed for %s - arn specified %s is missing in the replication config", opts.bucket, opts.arn))
|
||||
replLogIf(ctx, fmt.Errorf("replication resync failed for %s - arn specified %s is missing in the replication config", opts.bucket, opts.arn))
|
||||
return
|
||||
}
|
||||
tgt := globalBucketTargetSys.GetRemoteTargetClient(opts.bucket, opts.arn)
|
||||
if tgt == nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("replication resync failed for %s - target could not be created for arn %s", opts.bucket, opts.arn))
|
||||
replLogIf(ctx, fmt.Errorf("replication resync failed for %s - target could not be created for arn %s", opts.bucket, opts.arn))
|
||||
return
|
||||
}
|
||||
// mark resync status as resync started
|
||||
@@ -2750,7 +2769,7 @@ func (s *replicationResyncer) resyncBucket(ctx context.Context, objectAPI Object
|
||||
// Walk through all object versions - Walk() is always in ascending order needed to ensure
|
||||
// delete marker replicated to target after object version is first created.
|
||||
if err := objectAPI.Walk(ctx, opts.bucket, "", objInfoCh, WalkOptions{}); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
replLogIf(ctx, err)
|
||||
return
|
||||
}
|
||||
|
||||
@@ -2848,7 +2867,12 @@ func (s *replicationResyncer) resyncBucket(ctx context.Context, objectAPI Object
|
||||
}
|
||||
}(ctx, i)
|
||||
}
|
||||
for obj := range objInfoCh {
|
||||
for res := range objInfoCh {
|
||||
if res.Err != nil {
|
||||
resyncStatus = ResyncFailed
|
||||
replLogIf(ctx, res.Err)
|
||||
return
|
||||
}
|
||||
select {
|
||||
case <-s.resyncCancelCh:
|
||||
resyncStatus = ResyncCanceled
|
||||
@@ -2857,11 +2881,11 @@ func (s *replicationResyncer) resyncBucket(ctx context.Context, objectAPI Object
|
||||
return
|
||||
default:
|
||||
}
|
||||
if heal && lastCheckpoint != "" && lastCheckpoint != obj.Name {
|
||||
if heal && lastCheckpoint != "" && lastCheckpoint != res.Item.Name {
|
||||
continue
|
||||
}
|
||||
lastCheckpoint = ""
|
||||
roi := getHealReplicateObjectInfo(obj, rcfg)
|
||||
roi := getHealReplicateObjectInfo(res.Item, rcfg)
|
||||
if !roi.ExistingObjResync.mustResync() {
|
||||
continue
|
||||
}
|
||||
@@ -3025,7 +3049,7 @@ func (p *ReplicationPool) loadResync(ctx context.Context, buckets []BucketInfo,
|
||||
meta, err := loadBucketResyncMetadata(ctx, bucket, objAPI)
|
||||
if err != nil {
|
||||
if !errors.Is(err, errVolumeNotFound) {
|
||||
logger.LogIf(ctx, err)
|
||||
replLogIf(ctx, err)
|
||||
}
|
||||
continue
|
||||
}
|
||||
@@ -3112,18 +3136,18 @@ func saveResyncStatus(ctx context.Context, bucket string, brs BucketReplicationR
|
||||
func getReplicationDiff(ctx context.Context, objAPI ObjectLayer, bucket string, opts madmin.ReplDiffOpts) (chan madmin.DiffInfo, error) {
|
||||
cfg, err := getReplicationConfig(ctx, bucket)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
replLogOnceIf(ctx, err, bucket)
|
||||
return nil, err
|
||||
}
|
||||
tgts, err := globalBucketTargetSys.ListBucketTargets(ctx, bucket)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
replLogIf(ctx, err)
|
||||
return nil, err
|
||||
}
|
||||
|
||||
objInfoCh := make(chan ObjectInfo, 10)
|
||||
objInfoCh := make(chan itemOrErr[ObjectInfo], 10)
|
||||
if err := objAPI.Walk(ctx, bucket, opts.Prefix, objInfoCh, WalkOptions{}); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
replLogIf(ctx, err)
|
||||
return nil, err
|
||||
}
|
||||
rcfg := replicationConfig{
|
||||
@@ -3133,11 +3157,17 @@ func getReplicationDiff(ctx context.Context, objAPI ObjectLayer, bucket string,
|
||||
diffCh := make(chan madmin.DiffInfo, 4000)
|
||||
go func() {
|
||||
defer xioutil.SafeClose(diffCh)
|
||||
for obj := range objInfoCh {
|
||||
for res := range objInfoCh {
|
||||
if res.Err != nil {
|
||||
diffCh <- madmin.DiffInfo{Err: res.Err}
|
||||
return
|
||||
}
|
||||
if contextCanceled(ctx) {
|
||||
// Just consume input...
|
||||
continue
|
||||
}
|
||||
obj := res.Item
|
||||
|
||||
// Ignore object prefixes which are excluded
|
||||
// from versioning via the MinIO bucket versioning extension.
|
||||
if globalBucketVersioningSys.PrefixSuspended(bucket, obj.Name) {
|
||||
@@ -3205,7 +3235,11 @@ func QueueReplicationHeal(ctx context.Context, bucket string, oi ObjectInfo, ret
|
||||
if oi.ModTime.IsZero() {
|
||||
return
|
||||
}
|
||||
rcfg, _ := getReplicationConfig(ctx, bucket)
|
||||
rcfg, err := getReplicationConfig(ctx, bucket)
|
||||
if err != nil {
|
||||
replLogOnceIf(ctx, err, bucket)
|
||||
return
|
||||
}
|
||||
tgts, _ := globalBucketTargetSys.ListBucketTargets(ctx, bucket)
|
||||
queueReplicationHeal(ctx, bucket, oi, replicationConfig{
|
||||
Config: rcfg,
|
||||
@@ -3507,7 +3541,7 @@ func (p *ReplicationPool) processMRF() {
|
||||
continue
|
||||
}
|
||||
if err := p.queueMRFHeal(); err != nil && !osIsNotExist(err) {
|
||||
logger.LogIf(p.ctx, err)
|
||||
replLogIf(p.ctx, err)
|
||||
}
|
||||
pTimer.Reset(mrfQueueInterval)
|
||||
case <-p.ctx.Done():
|
||||
|
||||
@@ -20,7 +20,6 @@ package cmd
|
||||
import (
|
||||
"context"
|
||||
"errors"
|
||||
"fmt"
|
||||
"net/url"
|
||||
"sync"
|
||||
"time"
|
||||
@@ -32,7 +31,6 @@ import (
|
||||
"github.com/minio/minio/internal/bucket/replication"
|
||||
"github.com/minio/minio/internal/crypto"
|
||||
"github.com/minio/minio/internal/kms"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
)
|
||||
|
||||
const (
|
||||
@@ -131,7 +129,7 @@ func (sys *BucketTargetSys) initHC(ep *url.URL) {
|
||||
func newHCClient() *madmin.AnonymousClient {
|
||||
clnt, e := madmin.NewAnonymousClientNoEndpoint()
|
||||
if e != nil {
|
||||
logger.LogOnceIf(GlobalContext, fmt.Errorf("WARNING: Unable to initialize health check client"), string(replicationSubsystem))
|
||||
bugLogIf(GlobalContext, errors.New("Unable to initialize health check client"))
|
||||
return nil
|
||||
}
|
||||
clnt.SetCustomTransport(globalRemoteTargetTransport)
|
||||
@@ -430,7 +428,7 @@ func (sys *BucketTargetSys) RemoveTarget(ctx context.Context, bucket, arnStr str
|
||||
if arn.Type == madmin.ReplicationService {
|
||||
// reject removal of remote target if replication configuration is present
|
||||
rcfg, err := getReplicationConfig(ctx, bucket)
|
||||
if err == nil {
|
||||
if err == nil && rcfg != nil {
|
||||
for _, tgtArn := range rcfg.FilterTargetArns(replication.ObjectOpts{OpType: replication.AllReplicationType}) {
|
||||
if err == nil && (tgtArn == arnStr || rcfg.RoleArn == arnStr) {
|
||||
sys.RLock()
|
||||
@@ -624,7 +622,7 @@ func (sys *BucketTargetSys) set(bucket BucketInfo, meta BucketMetadata) {
|
||||
for _, tgt := range cfg.Targets {
|
||||
tgtClient, err := sys.getRemoteTargetClient(&tgt)
|
||||
if err != nil {
|
||||
logger.LogIf(GlobalContext, err)
|
||||
replLogIf(GlobalContext, err)
|
||||
continue
|
||||
}
|
||||
sys.arnRemotesMap[tgt.Arn] = arnTarget{Client: tgtClient}
|
||||
|
||||
@@ -82,7 +82,7 @@ func (api objectAPIHandlers) PutBucketVersioningHandler(w http.ResponseWriter, r
|
||||
}, r.URL)
|
||||
return
|
||||
}
|
||||
if _, err := getReplicationConfig(ctx, bucket); err == nil && v.Suspended() {
|
||||
if rc, _ := getReplicationConfig(ctx, bucket); rc != nil && v.Suspended() {
|
||||
writeErrorResponse(ctx, w, APIError{
|
||||
Code: "InvalidBucketState",
|
||||
Description: "A replication configuration is present on this bucket, bucket wide versioning cannot be suspended.",
|
||||
@@ -108,7 +108,7 @@ func (api objectAPIHandlers) PutBucketVersioningHandler(w http.ResponseWriter, r
|
||||
// We encode the xml bytes as base64 to ensure there are no encoding
|
||||
// errors.
|
||||
cfgStr := base64.StdEncoding.EncodeToString(configData)
|
||||
logger.LogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
replLogIf(ctx, globalSiteReplicationSys.BucketMetaHook(ctx, madmin.SRBucketMeta{
|
||||
Type: madmin.SRBucketMetaTypeVersionConfig,
|
||||
Bucket: bucket,
|
||||
Versioning: &cfgStr,
|
||||
|
||||
@@ -65,5 +65,5 @@ var (
|
||||
MinioBannerName = "MinIO Object Storage Server"
|
||||
|
||||
// MinioLicense - MinIO server license.
|
||||
MinioLicense = "GNU AGPLv3 <https://www.gnu.org/licenses/agpl-3.0.html>"
|
||||
MinioLicense = "GNU AGPLv3 - https://www.gnu.org/licenses/agpl-3.0.html"
|
||||
)
|
||||
|
||||
+4
-5
@@ -29,7 +29,6 @@ import (
|
||||
"time"
|
||||
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
)
|
||||
|
||||
var callhomeLeaderLockTimeout = newDynamicTimeout(30*time.Second, 10*time.Second)
|
||||
@@ -112,7 +111,7 @@ func performCallhome(ctx context.Context) {
|
||||
deadline := 10 * time.Second // Default deadline is 10secs for callhome
|
||||
objectAPI := newObjectLayerFn()
|
||||
if objectAPI == nil {
|
||||
logger.LogIf(ctx, errors.New("Callhome: object layer not ready"))
|
||||
internalLogIf(ctx, errors.New("Callhome: object layer not ready"))
|
||||
return
|
||||
}
|
||||
|
||||
@@ -145,7 +144,7 @@ func performCallhome(ctx context.Context) {
|
||||
// Received all data. Send to SUBNET and return
|
||||
err := sendHealthInfo(ctx, healthInfo)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to perform callhome: %w", err))
|
||||
internalLogIf(ctx, fmt.Errorf("Unable to perform callhome: %w", err))
|
||||
}
|
||||
return
|
||||
}
|
||||
@@ -180,12 +179,12 @@ func createHealthJSONGzip(ctx context.Context, healthInfo madmin.HealthInfo) []b
|
||||
|
||||
enc := json.NewEncoder(gzWriter)
|
||||
if e := enc.Encode(header); e != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Could not encode health info header: %w", e))
|
||||
internalLogIf(ctx, fmt.Errorf("Could not encode health info header: %w", e))
|
||||
return nil
|
||||
}
|
||||
|
||||
if e := enc.Encode(healthInfo); e != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Could not encode health info: %w", e))
|
||||
internalLogIf(ctx, fmt.Errorf("Could not encode health info: %w", e))
|
||||
return nil
|
||||
}
|
||||
|
||||
|
||||
+31
-119
@@ -21,10 +21,8 @@ import (
|
||||
"bufio"
|
||||
"bytes"
|
||||
"context"
|
||||
"crypto/tls"
|
||||
"crypto/x509"
|
||||
"encoding/gob"
|
||||
"encoding/pem"
|
||||
"errors"
|
||||
"fmt"
|
||||
"net"
|
||||
@@ -49,7 +47,6 @@ import (
|
||||
"github.com/minio/console/api/operations"
|
||||
consoleoauth2 "github.com/minio/console/pkg/auth/idp/oauth2"
|
||||
consoleCerts "github.com/minio/console/pkg/certs"
|
||||
"github.com/minio/kms-go/kes"
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio-go/v7"
|
||||
"github.com/minio/minio-go/v7/pkg/set"
|
||||
@@ -60,9 +57,9 @@ import (
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/certs"
|
||||
"github.com/minio/pkg/v2/console"
|
||||
"github.com/minio/pkg/v2/ellipses"
|
||||
"github.com/minio/pkg/v2/env"
|
||||
xnet "github.com/minio/pkg/v2/net"
|
||||
"golang.org/x/term"
|
||||
)
|
||||
|
||||
// serverDebugLog will enable debug printing
|
||||
@@ -73,6 +70,13 @@ var (
|
||||
)
|
||||
|
||||
func init() {
|
||||
if !term.IsTerminal(int(os.Stdout.Fd())) || !term.IsTerminal(int(os.Stderr.Fd())) {
|
||||
color.TurnOff()
|
||||
}
|
||||
if env.Get("NO_COLOR", "") != "" || env.Get("TERM", "") == "dumb" {
|
||||
color.TurnOff()
|
||||
}
|
||||
|
||||
if runtime.GOOS == "windows" {
|
||||
if mousetrap.StartedByExplorer() {
|
||||
fmt.Printf("Don't double-click %s\n", os.Args[0])
|
||||
@@ -131,6 +135,9 @@ func minioConfigToConsoleFeatures() {
|
||||
os.Setenv("CONSOLE_LOG_QUERY_AUTH_TOKEN", value)
|
||||
}
|
||||
}
|
||||
if value := env.Get(config.EnvBrowserRedirectURL, ""); value != "" {
|
||||
os.Setenv("CONSOLE_BROWSER_REDIRECT_URL", value)
|
||||
}
|
||||
// pass the console subpath configuration
|
||||
if globalBrowserRedirectURL != nil {
|
||||
subPath := path.Clean(pathJoin(strings.TrimSpace(globalBrowserRedirectURL.Path), SlashSeparator))
|
||||
@@ -401,6 +408,8 @@ func buildServerCtxt(ctx *cli.Context, ctxt *serverCtxt) (err error) {
|
||||
ctxt.ConnWriteDeadline = ctx.Duration("conn-write-deadline")
|
||||
ctxt.ConnClientReadDeadline = ctx.Duration("conn-client-read-deadline")
|
||||
ctxt.ConnClientWriteDeadline = ctx.Duration("conn-client-write-deadline")
|
||||
ctxt.SendBufSize = ctx.Int("send-buf-size")
|
||||
ctxt.RecvBufSize = ctx.Int("recv-buf-size")
|
||||
|
||||
ctxt.ShutdownTimeout = ctx.Duration("shutdown-timeout")
|
||||
ctxt.IdleTimeout = ctx.Duration("idle-timeout")
|
||||
@@ -852,125 +861,28 @@ func loadRootCredentials() {
|
||||
// Initialize KMS global variable after valiadating and loading the configuration.
|
||||
// It depends on KMS env variables and global cli flags.
|
||||
func handleKMSConfig() {
|
||||
if env.IsSet(kms.EnvKMSSecretKey) && env.IsSet(kms.EnvKESEndpoint) {
|
||||
logger.Fatal(errors.New("ambiguous KMS configuration"), fmt.Sprintf("The environment contains %q as well as %q", kms.EnvKMSSecretKey, kms.EnvKESEndpoint))
|
||||
present, err := kms.IsPresent()
|
||||
if err != nil {
|
||||
logger.Fatal(err, "Invalid KMS configuration specified")
|
||||
}
|
||||
if !present {
|
||||
return
|
||||
}
|
||||
|
||||
if env.IsSet(kms.EnvKMSSecretKey) {
|
||||
KMS, err := kms.Parse(env.Get(kms.EnvKMSSecretKey, ""))
|
||||
if err != nil {
|
||||
logger.Fatal(err, "Unable to parse the KMS secret key inherited from the shell environment")
|
||||
}
|
||||
GlobalKMS = KMS
|
||||
KMS, err := kms.Connect(GlobalContext, &kms.ConnectionOptions{
|
||||
CADir: globalCertsCADir.Get(),
|
||||
})
|
||||
if err != nil {
|
||||
logger.Fatal(err, "Failed to connect to KMS")
|
||||
}
|
||||
if env.IsSet(kms.EnvKESEndpoint) {
|
||||
if env.IsSet(kms.EnvKESAPIKey) {
|
||||
if env.IsSet(kms.EnvKESClientKey) {
|
||||
logger.Fatal(errors.New("ambiguous KMS configuration"), fmt.Sprintf("The environment contains %q as well as %q", kms.EnvKESAPIKey, kms.EnvKESClientKey))
|
||||
}
|
||||
if env.IsSet(kms.EnvKESClientCert) {
|
||||
logger.Fatal(errors.New("ambiguous KMS configuration"), fmt.Sprintf("The environment contains %q as well as %q", kms.EnvKESAPIKey, kms.EnvKESClientCert))
|
||||
}
|
||||
}
|
||||
if !env.IsSet(kms.EnvKESKeyName) {
|
||||
logger.Fatal(errors.New("Invalid KES configuration"), fmt.Sprintf("The mandatory environment variable %q not set", kms.EnvKESKeyName))
|
||||
}
|
||||
|
||||
var endpoints []string
|
||||
for _, endpoint := range strings.Split(env.Get(kms.EnvKESEndpoint, ""), ",") {
|
||||
if strings.TrimSpace(endpoint) == "" {
|
||||
continue
|
||||
}
|
||||
if !ellipses.HasEllipses(endpoint) {
|
||||
endpoints = append(endpoints, endpoint)
|
||||
continue
|
||||
}
|
||||
patterns, err := ellipses.FindEllipsesPatterns(endpoint)
|
||||
if err != nil {
|
||||
logger.Fatal(err, fmt.Sprintf("Invalid KES endpoint %q", endpoint))
|
||||
}
|
||||
for _, lbls := range patterns.Expand() {
|
||||
endpoints = append(endpoints, strings.Join(lbls, ""))
|
||||
}
|
||||
}
|
||||
rootCAs, err := certs.GetRootCAs(env.Get(kms.EnvKESServerCA, globalCertsCADir.Get()))
|
||||
if err != nil {
|
||||
logger.Fatal(err, fmt.Sprintf("Unable to load X.509 root CAs for KES from %q", env.Get(kms.EnvKESServerCA, globalCertsCADir.Get())))
|
||||
}
|
||||
|
||||
var kmsConf kms.Config
|
||||
if env.IsSet(kms.EnvKESAPIKey) {
|
||||
key, err := kes.ParseAPIKey(env.Get(kms.EnvKESAPIKey, ""))
|
||||
if err != nil {
|
||||
logger.Fatal(err, fmt.Sprintf("Failed to parse KES API key from %q", env.Get(kms.EnvKESAPIKey, "")))
|
||||
}
|
||||
kmsConf = kms.Config{
|
||||
Endpoints: endpoints,
|
||||
DefaultKeyID: env.Get(kms.EnvKESKeyName, ""),
|
||||
APIKey: key,
|
||||
RootCAs: rootCAs,
|
||||
}
|
||||
} else {
|
||||
loadX509KeyPair := func(certFile, keyFile string) (tls.Certificate, error) {
|
||||
// Manually load the certificate and private key into memory.
|
||||
// We need to check whether the private key is encrypted, and
|
||||
// if so, decrypt it using the user-provided password.
|
||||
certBytes, err := os.ReadFile(certFile)
|
||||
if err != nil {
|
||||
return tls.Certificate{}, fmt.Errorf("Unable to load KES client certificate as specified by the shell environment: %v", err)
|
||||
}
|
||||
keyBytes, err := os.ReadFile(keyFile)
|
||||
if err != nil {
|
||||
return tls.Certificate{}, fmt.Errorf("Unable to load KES client private key as specified by the shell environment: %v", err)
|
||||
}
|
||||
privateKeyPEM, rest := pem.Decode(bytes.TrimSpace(keyBytes))
|
||||
if len(rest) != 0 {
|
||||
return tls.Certificate{}, errors.New("Unable to load KES client private key as specified by the shell environment: private key contains additional data")
|
||||
}
|
||||
if x509.IsEncryptedPEMBlock(privateKeyPEM) {
|
||||
keyBytes, err = x509.DecryptPEMBlock(privateKeyPEM, []byte(env.Get(kms.EnvKESClientPassword, "")))
|
||||
if err != nil {
|
||||
return tls.Certificate{}, fmt.Errorf("Unable to decrypt KES client private key as specified by the shell environment: %v", err)
|
||||
}
|
||||
keyBytes = pem.EncodeToMemory(&pem.Block{Type: privateKeyPEM.Type, Bytes: keyBytes})
|
||||
}
|
||||
certificate, err := tls.X509KeyPair(certBytes, keyBytes)
|
||||
if err != nil {
|
||||
return tls.Certificate{}, fmt.Errorf("Unable to load KES client certificate as specified by the shell environment: %v", err)
|
||||
}
|
||||
return certificate, nil
|
||||
}
|
||||
|
||||
reloadCertEvents := make(chan tls.Certificate, 1)
|
||||
certificate, err := certs.NewCertificate(env.Get(kms.EnvKESClientCert, ""), env.Get(kms.EnvKESClientKey, ""), loadX509KeyPair)
|
||||
if err != nil {
|
||||
logger.Fatal(err, "Failed to load KES client certificate")
|
||||
}
|
||||
certificate.Watch(context.Background(), 15*time.Minute, syscall.SIGHUP)
|
||||
certificate.Notify(reloadCertEvents)
|
||||
|
||||
kmsConf = kms.Config{
|
||||
Endpoints: endpoints,
|
||||
DefaultKeyID: env.Get(kms.EnvKESKeyName, ""),
|
||||
Certificate: certificate,
|
||||
ReloadCertEvents: reloadCertEvents,
|
||||
RootCAs: rootCAs,
|
||||
}
|
||||
}
|
||||
|
||||
KMS, err := kms.NewWithConfig(kmsConf)
|
||||
if err != nil {
|
||||
logger.Fatal(err, "Unable to initialize a connection to KES as specified by the shell environment")
|
||||
}
|
||||
// We check that the default key ID exists or try to create it otherwise.
|
||||
// This implicitly checks that we can communicate to KES. We don't treat
|
||||
// a policy error as failure condition since MinIO may not have the permission
|
||||
// to create keys - just to generate/decrypt data encryption keys.
|
||||
if err = KMS.CreateKey(context.Background(), env.Get(kms.EnvKESKeyName, "")); err != nil && !errors.Is(err, kes.ErrKeyExists) && !errors.Is(err, kes.ErrNotAllowed) {
|
||||
logger.Fatal(err, "Unable to initialize a connection to KES as specified by the shell environment")
|
||||
}
|
||||
GlobalKMS = KMS
|
||||
if _, err = KMS.GenerateKey(GlobalContext, &kms.GenerateKeyRequest{}); errors.Is(err, kms.ErrKeyNotFound) {
|
||||
err = KMS.CreateKey(GlobalContext, &kms.CreateKeyRequest{Name: KMS.DefaultKey})
|
||||
}
|
||||
if err != nil && !errors.Is(err, kms.ErrKeyExists) && !errors.Is(err, kms.ErrPermission) {
|
||||
logger.Fatal(err, "Failed to connect to KMS")
|
||||
}
|
||||
GlobalKMS = KMS
|
||||
}
|
||||
|
||||
func getTLSConfig() (x509Certs []*x509.Certificate, manager *certs.Manager, secureConn bool, err error) {
|
||||
@@ -1044,7 +956,7 @@ func getTLSConfig() (x509Certs []*x509.Certificate, manager *certs.Manager, secu
|
||||
}
|
||||
if err = manager.AddCertificate(certFile, keyFile); err != nil {
|
||||
err = fmt.Errorf("Unable to load TLS certificate '%s,%s': %w", certFile, keyFile, err)
|
||||
logger.LogIf(GlobalContext, err, logger.ErrorKind)
|
||||
bootLogIf(GlobalContext, err, logger.ErrorKind)
|
||||
}
|
||||
}
|
||||
secureConn = true
|
||||
|
||||
+87
-92
@@ -479,7 +479,7 @@ func lookupConfigs(s config.Config, objAPI ObjectLayer) {
|
||||
|
||||
dnsURL, dnsUser, dnsPass, err := env.LookupEnv(config.EnvDNSWebhook)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to initialize remote webhook DNS config %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to initialize remote webhook DNS config %w", err))
|
||||
}
|
||||
if err == nil && dnsURL != "" {
|
||||
bootstrapTraceMsg("initialize remote bucket DNS store")
|
||||
@@ -487,27 +487,27 @@ func lookupConfigs(s config.Config, objAPI ObjectLayer) {
|
||||
dns.Authentication(dnsUser, dnsPass),
|
||||
dns.RootCAs(globalRootCAs))
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to initialize remote webhook DNS config %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to initialize remote webhook DNS config %w", err))
|
||||
}
|
||||
}
|
||||
|
||||
etcdCfg, err := etcd.LookupConfig(s[config.EtcdSubSys][config.Default], globalRootCAs)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to initialize etcd config: %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to initialize etcd config: %w", err))
|
||||
}
|
||||
|
||||
if etcdCfg.Enabled {
|
||||
bootstrapTraceMsg("initialize etcd store")
|
||||
globalEtcdClient, err = etcd.New(etcdCfg)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to initialize etcd config: %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to initialize etcd config: %w", err))
|
||||
}
|
||||
|
||||
if len(globalDomainNames) != 0 && !globalDomainIPs.IsEmpty() && globalEtcdClient != nil {
|
||||
if globalDNSConfig != nil {
|
||||
// if global DNS is already configured, indicate with a warning, in case
|
||||
// users are confused.
|
||||
logger.LogIf(ctx, fmt.Errorf("DNS store is already configured with %s, etcd is not used for DNS store", globalDNSConfig))
|
||||
configLogIf(ctx, fmt.Errorf("DNS store is already configured with %s, etcd is not used for DNS store", globalDNSConfig))
|
||||
} else {
|
||||
globalDNSConfig, err = dns.NewCoreDNS(etcdCfg.Config,
|
||||
dns.DomainNames(globalDomainNames),
|
||||
@@ -516,7 +516,7 @@ func lookupConfigs(s config.Config, objAPI ObjectLayer) {
|
||||
dns.CoreDNSPath(etcdCfg.CoreDNSPath),
|
||||
)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to initialize DNS config for %s: %w",
|
||||
configLogIf(ctx, fmt.Errorf("Unable to initialize DNS config for %s: %w",
|
||||
globalDomainNames, err))
|
||||
}
|
||||
}
|
||||
@@ -532,7 +532,7 @@ func lookupConfigs(s config.Config, objAPI ObjectLayer) {
|
||||
|
||||
globalSite, err = config.LookupSite(s[config.SiteSubSys][config.Default], s[config.RegionSubSys][config.Default])
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Invalid site configuration: %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Invalid site configuration: %w", err))
|
||||
}
|
||||
|
||||
globalAutoEncryption = crypto.LookupAutoEncryption() // Enable auto-encryption if enabled
|
||||
@@ -545,19 +545,19 @@ func lookupConfigs(s config.Config, objAPI ObjectLayer) {
|
||||
bootstrapTraceMsg("initialize the event notification targets")
|
||||
globalNotifyTargetList, err = notify.FetchEnabledTargets(GlobalContext, s, transport)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to initialize notification target(s): %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to initialize notification target(s): %w", err))
|
||||
}
|
||||
|
||||
bootstrapTraceMsg("initialize the lambda targets")
|
||||
globalLambdaTargetList, err = lambda.FetchEnabledTargets(GlobalContext, s, transport)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to initialize lambda target(s): %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to initialize lambda target(s): %w", err))
|
||||
}
|
||||
|
||||
bootstrapTraceMsg("applying the dynamic configuration")
|
||||
// Apply dynamic config values
|
||||
if err := applyDynamicConfig(ctx, objAPI, s); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
configLogIf(ctx, err)
|
||||
}
|
||||
}
|
||||
|
||||
@@ -566,21 +566,18 @@ func applyDynamicConfigForSubSys(ctx context.Context, objAPI ObjectLayer, s conf
|
||||
return errServerNotInitialized
|
||||
}
|
||||
|
||||
var errs []error
|
||||
setDriveCounts := objAPI.SetDriveCounts()
|
||||
switch subSys {
|
||||
case config.APISubSys:
|
||||
apiConfig, err := api.LookupConfig(s[config.APISubSys][config.Default])
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Invalid api configuration: %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Invalid api configuration: %w", err))
|
||||
}
|
||||
|
||||
globalAPIConfig.init(apiConfig, setDriveCounts)
|
||||
globalAPIConfig.init(apiConfig, setDriveCounts, objAPI.Legacy())
|
||||
autoGenerateRootCredentials() // Generate the KMS root credentials here since we don't know whether API root access is disabled until now.
|
||||
|
||||
// Initialize remote instance transport once.
|
||||
getRemoteInstanceTransportOnce.Do(func() {
|
||||
getRemoteInstanceTransport = NewHTTPTransportWithTimeout(apiConfig.RemoteTransportDeadline)
|
||||
})
|
||||
setRemoteInstanceTransport(NewHTTPTransportWithTimeout(apiConfig.RemoteTransportDeadline))
|
||||
case config.CompressionSubSys:
|
||||
cmpCfg, err := compress.LookupConfig(s[config.CompressionSubSys][config.Default])
|
||||
if err != nil {
|
||||
@@ -592,52 +589,55 @@ func applyDynamicConfigForSubSys(ctx context.Context, objAPI ObjectLayer, s conf
|
||||
case config.HealSubSys:
|
||||
healCfg, err := heal.LookupConfig(s[config.HealSubSys][config.Default])
|
||||
if err != nil {
|
||||
return fmt.Errorf("Unable to apply heal config: %w", err)
|
||||
errs = append(errs, fmt.Errorf("Unable to apply heal config: %w", err))
|
||||
} else {
|
||||
globalHealConfig.Update(healCfg)
|
||||
}
|
||||
globalHealConfig.Update(healCfg)
|
||||
case config.BatchSubSys:
|
||||
batchCfg, err := batch.LookupConfig(s[config.BatchSubSys][config.Default])
|
||||
if err != nil {
|
||||
return fmt.Errorf("Unable to apply batch config: %w", err)
|
||||
errs = append(errs, fmt.Errorf("Unable to apply batch config: %w", err))
|
||||
} else {
|
||||
globalBatchConfig.Update(batchCfg)
|
||||
}
|
||||
globalBatchConfig.Update(batchCfg)
|
||||
case config.ScannerSubSys:
|
||||
scannerCfg, err := scanner.LookupConfig(s[config.ScannerSubSys][config.Default])
|
||||
if err != nil {
|
||||
return fmt.Errorf("Unable to apply scanner config: %w", err)
|
||||
errs = append(errs, fmt.Errorf("Unable to apply scanner config: %w", err))
|
||||
} else {
|
||||
// update dynamic scanner values.
|
||||
scannerIdleMode.Store(scannerCfg.IdleMode)
|
||||
scannerCycle.Store(scannerCfg.Cycle)
|
||||
scannerExcessObjectVersions.Store(scannerCfg.ExcessVersions)
|
||||
scannerExcessFolders.Store(scannerCfg.ExcessFolders)
|
||||
configLogIf(ctx, scannerSleeper.Update(scannerCfg.Delay, scannerCfg.MaxWait))
|
||||
}
|
||||
// update dynamic scanner values.
|
||||
scannerIdleMode.Store(scannerCfg.IdleMode)
|
||||
scannerCycle.Store(scannerCfg.Cycle)
|
||||
scannerExcessObjectVersions.Store(scannerCfg.ExcessVersions)
|
||||
scannerExcessFolders.Store(scannerCfg.ExcessFolders)
|
||||
logger.LogIf(ctx, scannerSleeper.Update(scannerCfg.Delay, scannerCfg.MaxWait))
|
||||
case config.LoggerWebhookSubSys:
|
||||
loggerCfg, err := logger.LookupConfigForSubSys(ctx, s, config.LoggerWebhookSubSys)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to load logger webhook config: %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to load logger webhook config: %w", err))
|
||||
}
|
||||
userAgent := getUserAgent(getMinioMode())
|
||||
for n, l := range loggerCfg.HTTP {
|
||||
if l.Enabled {
|
||||
l.LogOnceIf = logger.LogOnceConsoleIf
|
||||
l.LogOnceIf = configLogOnceConsoleIf
|
||||
l.UserAgent = userAgent
|
||||
l.Transport = NewHTTPTransportWithClientCerts(l.ClientCert, l.ClientKey)
|
||||
}
|
||||
loggerCfg.HTTP[n] = l
|
||||
}
|
||||
if errs := logger.UpdateHTTPWebhooks(ctx, loggerCfg.HTTP); len(errs) > 0 {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to update logger webhook config: %v", errs))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to update logger webhook config: %v", errs))
|
||||
}
|
||||
case config.AuditWebhookSubSys:
|
||||
loggerCfg, err := logger.LookupConfigForSubSys(ctx, s, config.AuditWebhookSubSys)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to load audit webhook config: %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to load audit webhook config: %w", err))
|
||||
}
|
||||
userAgent := getUserAgent(getMinioMode())
|
||||
for n, l := range loggerCfg.AuditWebhook {
|
||||
if l.Enabled {
|
||||
l.LogOnceIf = logger.LogOnceConsoleIf
|
||||
l.LogOnceIf = configLogOnceConsoleIf
|
||||
l.UserAgent = userAgent
|
||||
l.Transport = NewHTTPTransportWithClientCerts(l.ClientCert, l.ClientKey)
|
||||
}
|
||||
@@ -645,42 +645,40 @@ func applyDynamicConfigForSubSys(ctx context.Context, objAPI ObjectLayer, s conf
|
||||
}
|
||||
|
||||
if errs := logger.UpdateAuditWebhooks(ctx, loggerCfg.AuditWebhook); len(errs) > 0 {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to update audit webhook targets: %v", errs))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to update audit webhook targets: %v", errs))
|
||||
}
|
||||
case config.AuditKafkaSubSys:
|
||||
loggerCfg, err := logger.LookupConfigForSubSys(ctx, s, config.AuditKafkaSubSys)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to load audit kafka config: %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to load audit kafka config: %w", err))
|
||||
}
|
||||
for n, l := range loggerCfg.AuditKafka {
|
||||
if l.Enabled {
|
||||
if l.TLS.Enable {
|
||||
l.TLS.RootCAs = globalRootCAs
|
||||
}
|
||||
l.LogOnce = logger.LogOnceIf
|
||||
l.LogOnce = configLogOnceIf
|
||||
loggerCfg.AuditKafka[n] = l
|
||||
}
|
||||
}
|
||||
if errs := logger.UpdateAuditKafkaTargets(ctx, loggerCfg); len(errs) > 0 {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to update audit kafka targets: %v", errs))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to update audit kafka targets: %v", errs))
|
||||
}
|
||||
case config.StorageClassSubSys:
|
||||
for i, setDriveCount := range setDriveCounts {
|
||||
sc, err := storageclass.LookupConfig(s[config.StorageClassSubSys][config.Default], setDriveCount)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to initialize storage class config: %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to initialize storage class config: %w", err))
|
||||
break
|
||||
}
|
||||
// if we validated all setDriveCounts and it was successful
|
||||
// proceed to store the correct storage class globally.
|
||||
if i == len(setDriveCounts)-1 {
|
||||
if i == 0 {
|
||||
globalStorageClass.Update(sc)
|
||||
}
|
||||
}
|
||||
case config.SubnetSubSys:
|
||||
subnetConfig, err := subnet.LookupConfig(s[config.SubnetSubSys][config.Default], globalProxyTransport)
|
||||
subnetConfig, err := subnet.LookupConfig(s[config.SubnetSubSys][config.Default], globalRemoteTargetTransport)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to parse subnet configuration: %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to parse subnet configuration: %w", err))
|
||||
} else {
|
||||
globalSubnetConfig.Update(subnetConfig, globalIsCICD)
|
||||
globalSubnetConfig.ApplyEnv() // update environment settings for Console UI
|
||||
@@ -688,7 +686,7 @@ func applyDynamicConfigForSubSys(ctx context.Context, objAPI ObjectLayer, s conf
|
||||
case config.CallhomeSubSys:
|
||||
callhomeCfg, err := callhome.LookupConfig(s[config.CallhomeSubSys][config.Default])
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to load callhome config: %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to load callhome config: %w", err))
|
||||
} else {
|
||||
enable := callhomeCfg.Enable && !globalCallhomeConfig.Enabled()
|
||||
globalCallhomeConfig.Update(callhomeCfg)
|
||||
@@ -697,45 +695,50 @@ func applyDynamicConfigForSubSys(ctx context.Context, objAPI ObjectLayer, s conf
|
||||
}
|
||||
}
|
||||
case config.DriveSubSys:
|
||||
if driveConfig, err := drive.LookupConfig(s[config.DriveSubSys][config.Default]); err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to load drive config: %w", err))
|
||||
driveConfig, err := drive.LookupConfig(s[config.DriveSubSys][config.Default])
|
||||
if err != nil {
|
||||
configLogIf(ctx, fmt.Errorf("Unable to load drive config: %w", err))
|
||||
} else {
|
||||
err := globalDriveConfig.Update(driveConfig)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to update drive config: %v", err))
|
||||
if err = globalDriveConfig.Update(driveConfig); err != nil {
|
||||
configLogIf(ctx, fmt.Errorf("Unable to update drive config: %v", err))
|
||||
}
|
||||
}
|
||||
case config.CacheSubSys:
|
||||
cacheCfg, err := cache.LookupConfig(s[config.CacheSubSys][config.Default], globalRemoteTargetTransport)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to load cache config: %w", err))
|
||||
configLogIf(ctx, fmt.Errorf("Unable to load cache config: %w", err))
|
||||
} else {
|
||||
globalCacheConfig.Update(cacheCfg)
|
||||
}
|
||||
case config.BrowserSubSys:
|
||||
browserCfg, err := browser.LookupConfig(s[config.BrowserSubSys][config.Default])
|
||||
if err != nil {
|
||||
return fmt.Errorf("Unable to apply browser config: %w", err)
|
||||
errs = append(errs, fmt.Errorf("Unable to apply browser config: %w", err))
|
||||
} else {
|
||||
globalBrowserConfig.Update(browserCfg)
|
||||
}
|
||||
globalBrowserConfig.Update(browserCfg)
|
||||
case config.ILMSubSys:
|
||||
ilmCfg, err := ilm.LookupConfig(s[config.ILMSubSys][config.Default])
|
||||
if err != nil {
|
||||
return fmt.Errorf("Unable to apply ilm config: %w", err)
|
||||
errs = append(errs, fmt.Errorf("Unable to apply ilm config: %w", err))
|
||||
} else {
|
||||
if globalTransitionState != nil {
|
||||
globalTransitionState.UpdateWorkers(ilmCfg.TransitionWorkers)
|
||||
}
|
||||
if globalExpiryState != nil {
|
||||
globalExpiryState.ResizeWorkers(ilmCfg.ExpirationWorkers)
|
||||
}
|
||||
globalILMConfig.update(ilmCfg)
|
||||
}
|
||||
if globalTransitionState != nil {
|
||||
globalTransitionState.UpdateWorkers(ilmCfg.TransitionWorkers)
|
||||
}
|
||||
if globalExpiryState != nil {
|
||||
globalExpiryState.ResizeWorkers(ilmCfg.ExpirationWorkers)
|
||||
}
|
||||
globalILMConfig.update(ilmCfg)
|
||||
}
|
||||
globalServerConfigMu.Lock()
|
||||
defer globalServerConfigMu.Unlock()
|
||||
if globalServerConfig != nil {
|
||||
globalServerConfig[subSys] = s[subSys]
|
||||
}
|
||||
if len(errs) > 0 {
|
||||
return errors.Join(errs...)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
@@ -750,41 +753,33 @@ func autoGenerateRootCredentials() {
|
||||
return
|
||||
}
|
||||
|
||||
if manager, ok := GlobalKMS.(kms.KeyManager); ok {
|
||||
stat, err := GlobalKMS.Stat(GlobalContext)
|
||||
if err != nil {
|
||||
logger.LogIf(GlobalContext, err, "Unable to generate root credentials using KMS")
|
||||
return
|
||||
}
|
||||
aKey, err := GlobalKMS.MAC(GlobalContext, &kms.MACRequest{Message: []byte("root access key")})
|
||||
if errors.Is(err, kes.ErrNotAllowed) || errors.Is(err, errors.ErrUnsupported) {
|
||||
return // If we don't have permission to compute the HMAC, don't change the cred.
|
||||
}
|
||||
if err != nil {
|
||||
logger.Fatal(err, "Unable to generate root access key using KMS")
|
||||
}
|
||||
|
||||
aKey, err := manager.HMAC(GlobalContext, stat.DefaultKey, []byte("root access key"))
|
||||
if errors.Is(err, kes.ErrNotAllowed) {
|
||||
return // If we don't have permission to compute the HMAC, don't change the cred.
|
||||
}
|
||||
if err != nil {
|
||||
logger.Fatal(err, "Unable to generate root access key using KMS")
|
||||
}
|
||||
sKey, err := GlobalKMS.MAC(GlobalContext, &kms.MACRequest{Message: []byte("root secret key")})
|
||||
if err != nil {
|
||||
// Here, we must have permission. Otherwise, we would have failed earlier.
|
||||
logger.Fatal(err, "Unable to generate root secret key using KMS")
|
||||
}
|
||||
|
||||
sKey, err := manager.HMAC(GlobalContext, stat.DefaultKey, []byte("root secret key"))
|
||||
if err != nil {
|
||||
// Here, we must have permission. Otherwise, we would have failed earlier.
|
||||
logger.Fatal(err, "Unable to generate root secret key using KMS")
|
||||
}
|
||||
accessKey, err := auth.GenerateAccessKey(20, bytes.NewReader(aKey))
|
||||
if err != nil {
|
||||
logger.Fatal(err, "Unable to generate root access key")
|
||||
}
|
||||
secretKey, err := auth.GenerateSecretKey(32, bytes.NewReader(sKey))
|
||||
if err != nil {
|
||||
logger.Fatal(err, "Unable to generate root secret key")
|
||||
}
|
||||
|
||||
logger.Info("Automatically generated root access key and secret key with the KMS")
|
||||
globalActiveCred = auth.Credentials{
|
||||
AccessKey: accessKey,
|
||||
SecretKey: secretKey,
|
||||
}
|
||||
logger.Info("Automatically generated root access key and secret key with the KMS")
|
||||
globalActiveCred = auth.Credentials{
|
||||
AccessKey: accessKey,
|
||||
SecretKey: secretKey,
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
// Copyright (c) 2015-2021 MinIO, Inc.
|
||||
// Copyright (c) 2015-2024 MinIO, Inc.
|
||||
//
|
||||
// This file is part of MinIO Object Storage stack
|
||||
//
|
||||
@@ -20,6 +20,7 @@ package cmd
|
||||
import (
|
||||
"container/ring"
|
||||
"context"
|
||||
"io"
|
||||
"sync"
|
||||
"sync/atomic"
|
||||
|
||||
@@ -49,10 +50,10 @@ type HTTPConsoleLoggerSys struct {
|
||||
|
||||
// NewConsoleLogger - creates new HTTPConsoleLoggerSys with all nodes subscribed to
|
||||
// the console logging pub sub system
|
||||
func NewConsoleLogger(ctx context.Context) *HTTPConsoleLoggerSys {
|
||||
func NewConsoleLogger(ctx context.Context, w io.Writer) *HTTPConsoleLoggerSys {
|
||||
return &HTTPConsoleLoggerSys{
|
||||
pubsub: pubsub.New[log.Info, madmin.LogMask](8),
|
||||
console: console.New(),
|
||||
console: console.New(w),
|
||||
logBuf: ring.New(defaultLogBufferCount),
|
||||
}
|
||||
}
|
||||
|
||||
+99
-80
@@ -36,12 +36,13 @@ import (
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio/internal/bucket/lifecycle"
|
||||
"github.com/minio/minio/internal/bucket/object/lock"
|
||||
objectlock "github.com/minio/minio/internal/bucket/object/lock"
|
||||
"github.com/minio/minio/internal/bucket/replication"
|
||||
"github.com/minio/minio/internal/bucket/versioning"
|
||||
"github.com/minio/minio/internal/color"
|
||||
"github.com/minio/minio/internal/config/heal"
|
||||
"github.com/minio/minio/internal/event"
|
||||
xioutil "github.com/minio/minio/internal/ioutil"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/console"
|
||||
uatomic "go.uber.org/atomic"
|
||||
)
|
||||
@@ -63,11 +64,12 @@ var (
|
||||
globalHealConfig heal.Config
|
||||
|
||||
// Sleeper values are updated when config is loaded.
|
||||
scannerSleeper = newDynamicSleeper(2, time.Second, true) // Keep defaults same as config defaults
|
||||
scannerCycle = uatomic.NewDuration(dataScannerStartDelay)
|
||||
scannerIdleMode = uatomic.NewInt32(0) // default is throttled when idle
|
||||
scannerExcessObjectVersions = uatomic.NewInt64(100)
|
||||
scannerExcessFolders = uatomic.NewInt64(50000)
|
||||
scannerSleeper = newDynamicSleeper(2, time.Second, true) // Keep defaults same as config defaults
|
||||
scannerCycle = uatomic.NewDuration(dataScannerStartDelay)
|
||||
scannerIdleMode = uatomic.NewInt32(0) // default is throttled when idle
|
||||
scannerExcessObjectVersions = uatomic.NewInt64(100)
|
||||
scannerExcessObjectVersionsTotalSize = uatomic.NewInt64(1024 * 1024 * 1024 * 1024) // 1 TB
|
||||
scannerExcessFolders = uatomic.NewInt64(50000)
|
||||
)
|
||||
|
||||
// initDataScanner will start the scanner in the background.
|
||||
@@ -122,13 +124,13 @@ func readBackgroundHealInfo(ctx context.Context, objAPI ObjectLayer) backgroundH
|
||||
buf, err := readConfig(ctx, objAPI, backgroundHealInfoPath)
|
||||
if err != nil {
|
||||
if !errors.Is(err, errConfigNotFound) {
|
||||
logger.LogOnceIf(ctx, err, backgroundHealInfoPath)
|
||||
internalLogOnceIf(ctx, err, backgroundHealInfoPath)
|
||||
}
|
||||
return backgroundHealInfo{}
|
||||
}
|
||||
var info backgroundHealInfo
|
||||
if err = json.Unmarshal(buf, &info); err != nil {
|
||||
logger.LogOnceIf(ctx, err, backgroundHealInfoPath)
|
||||
bugLogIf(ctx, err, backgroundHealInfoPath)
|
||||
}
|
||||
return info
|
||||
}
|
||||
@@ -140,13 +142,13 @@ func saveBackgroundHealInfo(ctx context.Context, objAPI ObjectLayer, info backgr
|
||||
|
||||
b, err := json.Marshal(info)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
bugLogIf(ctx, err)
|
||||
return
|
||||
}
|
||||
// Get last healing information
|
||||
err = saveConfig(ctx, objAPI, backgroundHealInfoPath, b)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
internalLogIf(ctx, err)
|
||||
}
|
||||
}
|
||||
|
||||
@@ -167,7 +169,7 @@ func runDataScanner(ctx context.Context, objAPI ObjectLayer) {
|
||||
cycleInfo.next = binary.LittleEndian.Uint64(buf[:8])
|
||||
buf = buf[8:]
|
||||
_, err := cycleInfo.UnmarshalMsg(buf)
|
||||
logger.LogIf(ctx, err)
|
||||
bugLogIf(ctx, err)
|
||||
}
|
||||
|
||||
scannerTimer := time.NewTimer(scannerCycle.Load())
|
||||
@@ -204,7 +206,7 @@ func runDataScanner(ctx context.Context, objAPI ObjectLayer) {
|
||||
results := make(chan DataUsageInfo, 1)
|
||||
go storeDataUsageInBackend(ctx, objAPI, results)
|
||||
err := objAPI.NSScanner(ctx, results, uint32(cycleInfo.current), scanMode)
|
||||
logger.LogOnceIf(ctx, err, "ns-scanner")
|
||||
scannerLogIf(ctx, err)
|
||||
res := map[string]string{"cycle": strconv.FormatUint(cycleInfo.current, 10)}
|
||||
if err != nil {
|
||||
res["error"] = err.Error()
|
||||
@@ -224,7 +226,7 @@ func runDataScanner(ctx context.Context, objAPI ObjectLayer) {
|
||||
binary.LittleEndian.PutUint64(tmp, cycleInfo.next)
|
||||
tmp, _ = cycleInfo.MarshalMsg(tmp)
|
||||
err = saveConfig(ctx, objAPI, dataUsageBloomNamePath, tmp)
|
||||
logger.LogOnceIf(ctx, err, dataUsageBloomNamePath)
|
||||
scannerLogIf(ctx, err, dataUsageBloomNamePath)
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -752,7 +754,7 @@ func (f *folderScanner) scanFolder(ctx context.Context, folder cachedFolder, int
|
||||
versionID: "",
|
||||
}, madmin.HealItemObject)
|
||||
if !isErrObjectNotFound(err) && !isErrVersionNotFound(err) {
|
||||
logger.LogOnceIf(ctx, err, entry.name)
|
||||
scannerLogIf(ctx, err)
|
||||
}
|
||||
foundObjs = foundObjs || err == nil
|
||||
return
|
||||
@@ -769,7 +771,7 @@ func (f *folderScanner) scanFolder(ctx context.Context, folder cachedFolder, int
|
||||
}, madmin.HealItemObject)
|
||||
stopFn(int(ver.Size))
|
||||
if !isErrObjectNotFound(err) && !isErrVersionNotFound(err) {
|
||||
logger.LogOnceIf(ctx, err, fiv.Name)
|
||||
scannerLogIf(ctx, err, fiv.Name)
|
||||
}
|
||||
if err == nil {
|
||||
successVersions++
|
||||
@@ -945,17 +947,39 @@ func (i *scannerItem) applyHealing(ctx context.Context, o ObjectLayer, oi Object
|
||||
func (i *scannerItem) applyLifecycle(ctx context.Context, o ObjectLayer, oi ObjectInfo) (action lifecycle.Action, size int64) {
|
||||
size, err := oi.GetActualSize()
|
||||
if i.debug {
|
||||
logger.LogIf(ctx, err)
|
||||
scannerLogIf(ctx, err)
|
||||
}
|
||||
if i.lifeCycle == nil {
|
||||
return action, size
|
||||
}
|
||||
|
||||
versionID := oi.VersionID
|
||||
vcfg, _ := globalBucketVersioningSys.Get(i.bucket)
|
||||
rCfg, _ := globalBucketObjectLockSys.Get(i.bucket)
|
||||
replcfg, _ := getReplicationConfig(ctx, i.bucket)
|
||||
lcEvt := evalActionFromLifecycle(ctx, *i.lifeCycle, rCfg, replcfg, oi)
|
||||
|
||||
var vc *versioning.Versioning
|
||||
var lr objectlock.Retention
|
||||
var rcfg *replication.Config
|
||||
if !isMinioMetaBucketName(i.bucket) {
|
||||
vc, err = globalBucketVersioningSys.Get(i.bucket)
|
||||
if err != nil {
|
||||
scannerLogOnceIf(ctx, err, i.bucket)
|
||||
return
|
||||
}
|
||||
|
||||
// Check if bucket is object locked.
|
||||
lr, err = globalBucketObjectLockSys.Get(i.bucket)
|
||||
if err != nil {
|
||||
scannerLogOnceIf(ctx, err, i.bucket)
|
||||
return
|
||||
}
|
||||
|
||||
rcfg, err = getReplicationConfig(ctx, i.bucket)
|
||||
if err != nil {
|
||||
scannerLogOnceIf(ctx, err, i.bucket)
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
lcEvt := evalActionFromLifecycle(ctx, *i.lifeCycle, lr, rcfg, oi)
|
||||
if i.debug {
|
||||
if versionID != "" {
|
||||
console.Debugf(applyActionsLogPrefix+" lifecycle: %q (version-id=%s), Initial scan: %v\n", i.objectPath(), versionID, lcEvt.Action)
|
||||
@@ -969,11 +993,11 @@ func (i *scannerItem) applyLifecycle(ctx context.Context, o ObjectLayer, oi Obje
|
||||
// This can happen when,
|
||||
// - ExpireObjectAllVersions flag is enabled
|
||||
// - NoncurrentVersionExpiration is applicable
|
||||
case lifecycle.DeleteVersionAction, lifecycle.DeleteAllVersionsAction:
|
||||
case lifecycle.DeleteVersionAction, lifecycle.DeleteAllVersionsAction, lifecycle.DelMarkerDeleteAllVersionsAction:
|
||||
size = 0
|
||||
case lifecycle.DeleteAction:
|
||||
// On a non-versioned bucket, DeleteObject removes the only version permanently.
|
||||
if !vcfg.PrefixEnabled(oi.Name) {
|
||||
if !vc.PrefixEnabled(oi.Name) {
|
||||
size = 0
|
||||
}
|
||||
}
|
||||
@@ -1066,7 +1090,7 @@ func (i *scannerItem) applyVersionActions(ctx context.Context, o ObjectLayer, fi
|
||||
}
|
||||
|
||||
// Check if we have many versions after applyNewerNoncurrentVersionLimit.
|
||||
if len(objInfos) > int(scannerExcessObjectVersions.Load()) {
|
||||
if len(objInfos) >= int(scannerExcessObjectVersions.Load()) {
|
||||
// Notify object accessed via a GET request.
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectManyVersions,
|
||||
@@ -1090,6 +1114,39 @@ func (i *scannerItem) applyVersionActions(ctx context.Context, o ObjectLayer, fi
|
||||
})
|
||||
}
|
||||
|
||||
cumulativeSize := int64(0)
|
||||
for _, objInfo := range objInfos {
|
||||
cumulativeSize += objInfo.Size
|
||||
}
|
||||
// Check if the cumulative size of all versions of this object is high.
|
||||
if cumulativeSize >= scannerExcessObjectVersionsTotalSize.Load() {
|
||||
// Notify object accessed via a GET request.
|
||||
sendEvent(eventArgs{
|
||||
EventName: event.ObjectLargeVersions,
|
||||
BucketName: i.bucket,
|
||||
Object: ObjectInfo{
|
||||
Name: i.objectPath(),
|
||||
},
|
||||
UserAgent: "Scanner",
|
||||
Host: globalLocalNodeName,
|
||||
RespElements: map[string]string{
|
||||
"x-minio-versions-count": strconv.Itoa(len(objInfos)),
|
||||
"x-minio-versions-size": strconv.FormatInt(cumulativeSize, 10),
|
||||
},
|
||||
})
|
||||
|
||||
auditLogInternal(context.Background(), AuditLogOptions{
|
||||
Event: "scanner:largeversions",
|
||||
APIName: "Scanner",
|
||||
Bucket: i.bucket,
|
||||
Object: i.objectPath(),
|
||||
Tags: map[string]interface{}{
|
||||
"x-minio-versions-count": strconv.Itoa(len(objInfos)),
|
||||
"x-minio-versions-size": strconv.FormatInt(cumulativeSize, 10),
|
||||
},
|
||||
})
|
||||
}
|
||||
|
||||
return objInfos, nil
|
||||
}
|
||||
|
||||
@@ -1105,7 +1162,7 @@ func (i *scannerItem) applyActions(ctx context.Context, o ObjectLayer, oi Object
|
||||
|
||||
// Note: objDeleted is true if and only if action ==
|
||||
// lifecycle.DeleteAllVersionsAction
|
||||
if action == lifecycle.DeleteAllVersionsAction {
|
||||
if action.DeleteAll() {
|
||||
return true, 0
|
||||
}
|
||||
|
||||
@@ -1123,7 +1180,7 @@ func (i *scannerItem) applyActions(ctx context.Context, o ObjectLayer, oi Object
|
||||
err := o.CheckAbandonedParts(ctx, i.bucket, i.objectPath(), madmin.HealOpts{Remove: healDeleteDangling})
|
||||
done()
|
||||
if err != nil {
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("unable to check object %s/%s for abandoned data: %w", i.bucket, i.objectPath(), err), i.objectPath())
|
||||
healingLogIf(ctx, fmt.Errorf("unable to check object %s/%s for abandoned data: %w", i.bucket, i.objectPath(), err), i.objectPath())
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -1142,17 +1199,15 @@ func evalActionFromLifecycle(ctx context.Context, lc lifecycle.Lifecycle, lr loc
|
||||
console.Debugf(applyActionsLogPrefix+" lifecycle: Secondary scan: %v\n", event.Action)
|
||||
}
|
||||
|
||||
if event.Action == lifecycle.NoneAction {
|
||||
return event
|
||||
}
|
||||
|
||||
if obj.IsLatest && event.Action == lifecycle.DeleteAllVersionsAction {
|
||||
if lr.LockEnabled && enforceRetentionForDeletion(ctx, obj) {
|
||||
switch event.Action {
|
||||
case lifecycle.DeleteAllVersionsAction, lifecycle.DelMarkerDeleteAllVersionsAction:
|
||||
// Skip if bucket has object locking enabled; To prevent the
|
||||
// possibility of violating an object retention on one of the
|
||||
// noncurrent versions of this object.
|
||||
if lr.LockEnabled {
|
||||
return lifecycle.Event{Action: lifecycle.NoneAction}
|
||||
}
|
||||
}
|
||||
|
||||
switch event.Action {
|
||||
case lifecycle.DeleteVersionAction, lifecycle.DeleteRestoredVersionAction:
|
||||
// Defensive code, should never happen
|
||||
if obj.VersionID == "" {
|
||||
@@ -1199,7 +1254,7 @@ func applyExpiryOnTransitionedObject(ctx context.Context, objLayer ObjectLayer,
|
||||
if isErrObjectNotFound(err) || isErrVersionNotFound(err) {
|
||||
return false
|
||||
}
|
||||
logger.LogOnceIf(ctx, err, obj.Name)
|
||||
ilmLogIf(ctx, err)
|
||||
return false
|
||||
}
|
||||
// Notification already sent in *expireTransitionedObject*, just return 'true' here.
|
||||
@@ -1221,6 +1276,8 @@ func applyExpiryOnNonTransitionedObjects(ctx context.Context, objLayer ObjectLay
|
||||
|
||||
if lcEvent.Action.DeleteAll() {
|
||||
opts.DeletePrefix = true
|
||||
// use prefix delete on exact object (this is an optimization to avoid fan-out calls)
|
||||
opts.DeletePrefixObject = true
|
||||
}
|
||||
var (
|
||||
dobj ObjectInfo
|
||||
@@ -1233,7 +1290,7 @@ func applyExpiryOnNonTransitionedObjects(ctx context.Context, objLayer ObjectLay
|
||||
|
||||
if lcEvent.Action != lifecycle.NoneAction {
|
||||
numVersions := uint64(1)
|
||||
if lcEvent.Action == lifecycle.DeleteAllVersionsAction {
|
||||
if lcEvent.Action.DeleteAll() {
|
||||
numVersions = uint64(obj.NumVersions)
|
||||
}
|
||||
globalScannerMetrics.timeILM(lcEvent.Action)(numVersions)
|
||||
@@ -1246,7 +1303,7 @@ func applyExpiryOnNonTransitionedObjects(ctx context.Context, objLayer ObjectLay
|
||||
return false
|
||||
}
|
||||
// Assume it is still there.
|
||||
logger.LogOnceIf(ctx, err, "non-transition-expiry")
|
||||
ilmLogOnceIf(ctx, err, "non-transition-expiry")
|
||||
return false
|
||||
}
|
||||
if dobj.Name == "" {
|
||||
@@ -1261,8 +1318,11 @@ func applyExpiryOnNonTransitionedObjects(ctx context.Context, objLayer ObjectLay
|
||||
if obj.DeleteMarker {
|
||||
eventName = event.ObjectRemovedDeleteMarkerCreated
|
||||
}
|
||||
if lcEvent.Action.DeleteAll() {
|
||||
switch lcEvent.Action {
|
||||
case lifecycle.DeleteAllVersionsAction:
|
||||
eventName = event.ObjectRemovedDeleteAllVersions
|
||||
case lifecycle.DelMarkerDeleteAllVersionsAction:
|
||||
eventName = event.ILMDelMarkerExpirationDelete
|
||||
}
|
||||
// Notify object deleted event.
|
||||
sendEvent(eventArgs{
|
||||
@@ -1287,7 +1347,7 @@ func applyLifecycleAction(event lifecycle.Event, src lcEventSrc, obj ObjectInfo)
|
||||
switch action := event.Action; action {
|
||||
case lifecycle.DeleteVersionAction, lifecycle.DeleteAction,
|
||||
lifecycle.DeleteRestoredAction, lifecycle.DeleteRestoredVersionAction,
|
||||
lifecycle.DeleteAllVersionsAction:
|
||||
lifecycle.DeleteAllVersionsAction, lifecycle.DelMarkerDeleteAllVersionsAction:
|
||||
success = applyExpiryRule(event, src, obj)
|
||||
case lifecycle.TransitionAction, lifecycle.TransitionVersionAction:
|
||||
success = applyTransitionRule(event, src, obj)
|
||||
@@ -1387,48 +1447,7 @@ func (d *dynamicSleeper) Timer(ctx context.Context) func() {
|
||||
t := time.Now()
|
||||
return func() {
|
||||
doneAt := time.Now()
|
||||
for {
|
||||
// Grab current values
|
||||
d.mu.RLock()
|
||||
minWait, maxWait := d.minSleep, d.maxSleep
|
||||
factor := d.factor
|
||||
cycle := d.cycle
|
||||
d.mu.RUnlock()
|
||||
elapsed := doneAt.Sub(t)
|
||||
// Don't sleep for really small amount of time
|
||||
wantSleep := time.Duration(float64(elapsed) * factor)
|
||||
if wantSleep <= minWait {
|
||||
return
|
||||
}
|
||||
if maxWait > 0 && wantSleep > maxWait {
|
||||
wantSleep = maxWait
|
||||
}
|
||||
timer := time.NewTimer(wantSleep)
|
||||
select {
|
||||
case <-ctx.Done():
|
||||
if !timer.Stop() {
|
||||
<-timer.C
|
||||
}
|
||||
if d.isScanner {
|
||||
globalScannerMetrics.incTime(scannerMetricYield, wantSleep)
|
||||
}
|
||||
return
|
||||
case <-timer.C:
|
||||
if d.isScanner {
|
||||
globalScannerMetrics.incTime(scannerMetricYield, wantSleep)
|
||||
}
|
||||
return
|
||||
case <-cycle:
|
||||
if !timer.Stop() {
|
||||
// We expired.
|
||||
<-timer.C
|
||||
if d.isScanner {
|
||||
globalScannerMetrics.incTime(scannerMetricYield, wantSleep)
|
||||
}
|
||||
return
|
||||
}
|
||||
}
|
||||
}
|
||||
d.Sleep(ctx, doneAt.Sub(t))
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
@@ -20,12 +20,15 @@ package cmd
|
||||
import (
|
||||
"context"
|
||||
"encoding/xml"
|
||||
"fmt"
|
||||
"strings"
|
||||
"sync"
|
||||
"testing"
|
||||
"time"
|
||||
|
||||
"github.com/google/uuid"
|
||||
"github.com/minio/minio/internal/bucket/lifecycle"
|
||||
"github.com/minio/minio/internal/bucket/object/lock"
|
||||
"github.com/minio/minio/internal/bucket/versioning"
|
||||
)
|
||||
|
||||
@@ -141,3 +144,96 @@ func TestApplyNewerNoncurrentVersionsLimit(t *testing.T) {
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
func TestEvalActionFromLifecycle(t *testing.T) {
|
||||
// Tests cover only ExpiredObjectDeleteAllVersions and DelMarkerExpiration actions
|
||||
obj := ObjectInfo{
|
||||
Name: "foo",
|
||||
ModTime: time.Now().Add(-31 * 24 * time.Hour),
|
||||
Size: 100 << 20,
|
||||
VersionID: uuid.New().String(),
|
||||
IsLatest: true,
|
||||
NumVersions: 4,
|
||||
}
|
||||
delMarker := ObjectInfo{
|
||||
Name: "foo-deleted",
|
||||
ModTime: time.Now().Add(-61 * 24 * time.Hour),
|
||||
Size: 0,
|
||||
VersionID: uuid.New().String(),
|
||||
IsLatest: true,
|
||||
DeleteMarker: true,
|
||||
NumVersions: 4,
|
||||
}
|
||||
deleteAllILM := `<LifecycleConfiguration>
|
||||
<Rule>
|
||||
<Expiration>
|
||||
<Days>30</Days>
|
||||
<ExpiredObjectAllVersions>true</ExpiredObjectAllVersions>
|
||||
</Expiration>
|
||||
<Filter></Filter>
|
||||
<Status>Enabled</Status>
|
||||
<ID>DeleteAllVersions</ID>
|
||||
</Rule>
|
||||
</LifecycleConfiguration>`
|
||||
delMarkerILM := `<LifecycleConfiguration>
|
||||
<Rule>
|
||||
<ID>DelMarkerExpiration</ID>
|
||||
<Filter></Filter>
|
||||
<Status>Enabled</Status>
|
||||
<DelMarkerExpiration>
|
||||
<Days>60</Days>
|
||||
</DelMarkerExpiration>
|
||||
</Rule>
|
||||
</LifecycleConfiguration>`
|
||||
deleteAllLc, err := lifecycle.ParseLifecycleConfig(strings.NewReader(deleteAllILM))
|
||||
if err != nil {
|
||||
t.Fatalf("Failed to parse deleteAllILM test ILM policy %v", err)
|
||||
}
|
||||
delMarkerLc, err := lifecycle.ParseLifecycleConfig(strings.NewReader(delMarkerILM))
|
||||
if err != nil {
|
||||
t.Fatalf("Failed to parse delMarkerILM test ILM policy %v", err)
|
||||
}
|
||||
tests := []struct {
|
||||
ilm lifecycle.Lifecycle
|
||||
retention lock.Retention
|
||||
obj ObjectInfo
|
||||
want lifecycle.Action
|
||||
}{
|
||||
{
|
||||
// with object locking
|
||||
ilm: *deleteAllLc,
|
||||
retention: lock.Retention{LockEnabled: true},
|
||||
obj: obj,
|
||||
want: lifecycle.NoneAction,
|
||||
},
|
||||
{
|
||||
// without object locking
|
||||
ilm: *deleteAllLc,
|
||||
retention: lock.Retention{},
|
||||
obj: obj,
|
||||
want: lifecycle.DeleteAllVersionsAction,
|
||||
},
|
||||
{
|
||||
// with object locking
|
||||
ilm: *delMarkerLc,
|
||||
retention: lock.Retention{LockEnabled: true},
|
||||
obj: delMarker,
|
||||
want: lifecycle.NoneAction,
|
||||
},
|
||||
{
|
||||
// without object locking
|
||||
ilm: *delMarkerLc,
|
||||
retention: lock.Retention{},
|
||||
obj: delMarker,
|
||||
want: lifecycle.DelMarkerDeleteAllVersionsAction,
|
||||
},
|
||||
}
|
||||
|
||||
for i, test := range tests {
|
||||
t.Run(fmt.Sprintf("TestEvalAction-%d", i), func(t *testing.T) {
|
||||
if got := evalActionFromLifecycle(context.TODO(), test.ilm, test.retention, nil, test.obj); got.Action != test.want {
|
||||
t.Fatalf("Expected %v but got %v", test.want, got)
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
+44
-31
@@ -18,7 +18,6 @@
|
||||
package cmd
|
||||
|
||||
import (
|
||||
"bytes"
|
||||
"context"
|
||||
"errors"
|
||||
"fmt"
|
||||
@@ -36,8 +35,6 @@ import (
|
||||
"github.com/klauspost/compress/zstd"
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio/internal/bucket/lifecycle"
|
||||
"github.com/minio/minio/internal/hash"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/tinylib/msgp/msgp"
|
||||
"github.com/valyala/bytebufferpool"
|
||||
)
|
||||
@@ -191,6 +188,22 @@ type replicationAllStatsV1 struct {
|
||||
ReplicaCount uint64 `msg:"ReplicaCount,omitempty"`
|
||||
}
|
||||
|
||||
// empty returns true if the replicationAllStats is empty (contains no entries).
|
||||
func (r *replicationAllStats) empty() bool {
|
||||
if r == nil {
|
||||
return true
|
||||
}
|
||||
if r.ReplicaSize != 0 || r.ReplicaCount != 0 {
|
||||
return false
|
||||
}
|
||||
for _, v := range r.Targets {
|
||||
if !v.Empty() {
|
||||
return false
|
||||
}
|
||||
}
|
||||
return true
|
||||
}
|
||||
|
||||
// clone creates a deep-copy clone.
|
||||
func (r *replicationAllStats) clone() *replicationAllStats {
|
||||
if r == nil {
|
||||
@@ -523,20 +536,18 @@ func (d *dataUsageCache) searchParent(h dataUsageHash) *dataUsageHash {
|
||||
want := h.Key()
|
||||
if idx := strings.LastIndexByte(want, '/'); idx >= 0 {
|
||||
if v := d.find(want[:idx]); v != nil {
|
||||
for child := range v.Children {
|
||||
if child == want {
|
||||
found := hashPath(want[:idx])
|
||||
return &found
|
||||
}
|
||||
_, ok := v.Children[want]
|
||||
if ok {
|
||||
found := hashPath(want[:idx])
|
||||
return &found
|
||||
}
|
||||
}
|
||||
}
|
||||
for k, v := range d.Cache {
|
||||
for child := range v.Children {
|
||||
if child == want {
|
||||
found := dataUsageHash(k)
|
||||
return &found
|
||||
}
|
||||
_, ok := v.Children[want]
|
||||
if ok {
|
||||
found := dataUsageHash(k)
|
||||
return &found
|
||||
}
|
||||
}
|
||||
return nil
|
||||
@@ -621,7 +632,7 @@ func (d *dataUsageCache) copyWithChildren(src *dataUsageCache, hash dataUsageHas
|
||||
d.Cache[hash.Key()] = e
|
||||
for ch := range e.Children {
|
||||
if ch == hash.Key() {
|
||||
logger.LogIf(GlobalContext, errors.New("dataUsageCache.copyWithChildren: Circular reference"))
|
||||
scannerLogIf(GlobalContext, errors.New("dataUsageCache.copyWithChildren: Circular reference"))
|
||||
return
|
||||
}
|
||||
d.copyWithChildren(src, dataUsageHash(ch), &hash)
|
||||
@@ -901,6 +912,9 @@ func (d *dataUsageCache) sizeRecursive(path string) *dataUsageEntry {
|
||||
return root
|
||||
}
|
||||
flat := d.flatten(*root)
|
||||
if flat.ReplicationStats.empty() {
|
||||
flat.ReplicationStats = nil
|
||||
}
|
||||
return &flat
|
||||
}
|
||||
|
||||
@@ -989,11 +1003,23 @@ func (d *dataUsageCache) load(ctx context.Context, store objectIO, name string)
|
||||
ctx, cancel := context.WithTimeout(ctx, timeout)
|
||||
defer cancel()
|
||||
|
||||
r, err := store.GetObjectNInfo(ctx, dataUsageBucket, name, nil, http.Header{}, ObjectOptions{NoLock: true})
|
||||
r, err := store.GetObjectNInfo(ctx, minioMetaBucket, pathJoin(bucketMetaPrefix, name), nil, http.Header{}, ObjectOptions{NoLock: true})
|
||||
if err != nil {
|
||||
switch err.(type) {
|
||||
case ObjectNotFound, BucketNotFound:
|
||||
return false, nil
|
||||
r, err = store.GetObjectNInfo(ctx, dataUsageBucket, name, nil, http.Header{}, ObjectOptions{NoLock: true})
|
||||
if err != nil {
|
||||
switch err.(type) {
|
||||
case ObjectNotFound, BucketNotFound:
|
||||
return false, nil
|
||||
case InsufficientReadQuorum, StorageErr:
|
||||
return true, nil
|
||||
}
|
||||
return false, err
|
||||
}
|
||||
err = d.deserialize(r)
|
||||
r.Close()
|
||||
return err != nil, nil
|
||||
case InsufficientReadQuorum, StorageErr:
|
||||
return true, nil
|
||||
}
|
||||
@@ -1024,7 +1050,7 @@ func (d *dataUsageCache) load(ctx context.Context, store objectIO, name string)
|
||||
}
|
||||
|
||||
if retries == 5 {
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("maximum retry reached to load the data usage cache `%s`", name), "retry-loading-data-usage-cache")
|
||||
scannerLogOnceIf(ctx, fmt.Errorf("maximum retry reached to load the data usage cache `%s`", name), "retry-loading-data-usage-cache")
|
||||
}
|
||||
|
||||
return nil
|
||||
@@ -1054,24 +1080,11 @@ func (d *dataUsageCache) save(ctx context.Context, store objectIO, name string)
|
||||
}
|
||||
|
||||
save := func(name string, timeout time.Duration) error {
|
||||
hr, err := hash.NewReader(ctx, bytes.NewReader(buf.Bytes()), int64(buf.Len()), "", "", int64(buf.Len()))
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
// Abandon if more than a minute, so we don't hold up scanner.
|
||||
ctx, cancel := context.WithTimeout(ctx, timeout)
|
||||
defer cancel()
|
||||
|
||||
_, err = store.PutObject(ctx,
|
||||
dataUsageBucket,
|
||||
name,
|
||||
NewPutObjReader(hr),
|
||||
ObjectOptions{NoLock: true})
|
||||
if isErrBucketNotFound(err) {
|
||||
return nil
|
||||
}
|
||||
return err
|
||||
return saveConfig(ctx, store, pathJoin(bucketMetaPrefix, name), buf.Bytes())
|
||||
}
|
||||
defer save(name+".bkp", 5*time.Second) // Keep a backup as well
|
||||
|
||||
|
||||
+5
-6
@@ -25,7 +25,6 @@ import (
|
||||
|
||||
jsoniter "github.com/json-iterator/go"
|
||||
"github.com/minio/minio/internal/cachevalue"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
)
|
||||
|
||||
const (
|
||||
@@ -49,7 +48,7 @@ func storeDataUsageInBackend(ctx context.Context, objAPI ObjectLayer, dui <-chan
|
||||
json := jsoniter.ConfigCompatibleWithStandardLibrary
|
||||
dataUsageJSON, err := json.Marshal(dataUsageInfo)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
scannerLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
if attempts > 10 {
|
||||
@@ -57,7 +56,7 @@ func storeDataUsageInBackend(ctx context.Context, objAPI ObjectLayer, dui <-chan
|
||||
attempts = 1
|
||||
}
|
||||
if err = saveConfig(ctx, objAPI, dataUsageObjNamePath, dataUsageJSON); err != nil {
|
||||
logger.LogOnceIf(ctx, err, dataUsageObjNamePath)
|
||||
scannerLogOnceIf(ctx, err, dataUsageObjNamePath)
|
||||
}
|
||||
attempts++
|
||||
}
|
||||
@@ -80,12 +79,12 @@ func loadPrefixUsageFromBackend(ctx context.Context, objAPI ObjectLayer, bucket
|
||||
prefixUsageCache.InitOnce(30*time.Second,
|
||||
// No need to fail upon Update() error, fallback to old value.
|
||||
cachevalue.Opts{ReturnLastGood: true, NoWait: true},
|
||||
func() (map[string]uint64, error) {
|
||||
func(ctx context.Context) (map[string]uint64, error) {
|
||||
m := make(map[string]uint64)
|
||||
for _, pool := range z.serverPools {
|
||||
for _, er := range pool.sets {
|
||||
// Load bucket usage prefixes
|
||||
ctx, done := context.WithTimeout(context.Background(), 2*time.Second)
|
||||
ctx, done := context.WithTimeout(ctx, 2*time.Second)
|
||||
ok := cache.load(ctx, er, bucket+slashSeparator+dataUsageCacheName) == nil
|
||||
done()
|
||||
if ok {
|
||||
@@ -108,7 +107,7 @@ func loadPrefixUsageFromBackend(ctx context.Context, objAPI ObjectLayer, bucket
|
||||
},
|
||||
)
|
||||
|
||||
return prefixUsageCache.Get()
|
||||
return prefixUsageCache.GetWithCtx(ctx)
|
||||
}
|
||||
|
||||
func loadDataUsageFromBackend(ctx context.Context, objAPI ObjectLayer) (DataUsageInfo, error) {
|
||||
|
||||
@@ -364,6 +364,7 @@ func TestDataUsageUpdatePrefix(t *testing.T) {
|
||||
}
|
||||
if e == nil {
|
||||
t.Fatal("got nil result")
|
||||
return
|
||||
}
|
||||
if e.Size != int64(w.size) {
|
||||
t.Error("got size", e.Size, "want", w.size)
|
||||
|
||||
+25
-11
@@ -110,7 +110,7 @@ func kmsKeyIDFromMetadata(metadata map[string]string) string {
|
||||
//
|
||||
// DecryptETags uses a KMS bulk decryption API, if available, which
|
||||
// is more efficient than decrypting ETags sequentually.
|
||||
func DecryptETags(ctx context.Context, k kms.KMS, objects []ObjectInfo) error {
|
||||
func DecryptETags(ctx context.Context, k *kms.KMS, objects []ObjectInfo) error {
|
||||
const BatchSize = 250 // We process the objects in batches - 250 is a reasonable default.
|
||||
var (
|
||||
metadata = make([]map[string]string, 0, BatchSize)
|
||||
@@ -267,7 +267,11 @@ func rotateKey(ctx context.Context, oldKey []byte, newKeyID string, newKey []byt
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
oldKey, err := GlobalKMS.DecryptKey(keyID, kmsKey, kms.Context{bucket: path.Join(bucket, object)})
|
||||
oldKey, err := GlobalKMS.Decrypt(ctx, &kms.DecryptRequest{
|
||||
Name: keyID,
|
||||
Ciphertext: kmsKey,
|
||||
AssociatedData: kms.Context{bucket: path.Join(bucket, object)},
|
||||
})
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
@@ -276,7 +280,10 @@ func rotateKey(ctx context.Context, oldKey []byte, newKeyID string, newKey []byt
|
||||
return err
|
||||
}
|
||||
|
||||
newKey, err := GlobalKMS.GenerateKey(ctx, "", kms.Context{bucket: path.Join(bucket, object)})
|
||||
newKey, err := GlobalKMS.GenerateKey(ctx, &kms.GenerateKeyRequest{
|
||||
Name: GlobalKMS.DefaultKey,
|
||||
AssociatedData: kms.Context{bucket: path.Join(bucket, object)},
|
||||
})
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
@@ -312,7 +319,10 @@ func rotateKey(ctx context.Context, oldKey []byte, newKeyID string, newKey []byt
|
||||
if _, ok := kmsCtx[bucket]; !ok {
|
||||
kmsCtx[bucket] = path.Join(bucket, object)
|
||||
}
|
||||
newKey, err := GlobalKMS.GenerateKey(ctx, newKeyID, kmsCtx)
|
||||
newKey, err := GlobalKMS.GenerateKey(ctx, &kms.GenerateKeyRequest{
|
||||
Name: newKeyID,
|
||||
AssociatedData: kmsCtx,
|
||||
})
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
@@ -352,7 +362,9 @@ func newEncryptMetadata(ctx context.Context, kind crypto.Type, keyID string, key
|
||||
if GlobalKMS == nil {
|
||||
return crypto.ObjectKey{}, errKMSNotConfigured
|
||||
}
|
||||
key, err := GlobalKMS.GenerateKey(ctx, "", kms.Context{bucket: path.Join(bucket, object)})
|
||||
key, err := GlobalKMS.GenerateKey(ctx, &kms.GenerateKeyRequest{
|
||||
AssociatedData: kms.Context{bucket: path.Join(bucket, object)},
|
||||
})
|
||||
if err != nil {
|
||||
return crypto.ObjectKey{}, err
|
||||
}
|
||||
@@ -379,7 +391,10 @@ func newEncryptMetadata(ctx context.Context, kind crypto.Type, keyID string, key
|
||||
if _, ok := kmsCtx[bucket]; !ok {
|
||||
kmsCtx[bucket] = path.Join(bucket, object)
|
||||
}
|
||||
key, err := GlobalKMS.GenerateKey(ctx, keyID, kmsCtx)
|
||||
key, err := GlobalKMS.GenerateKey(ctx, &kms.GenerateKeyRequest{
|
||||
Name: keyID,
|
||||
AssociatedData: kmsCtx,
|
||||
})
|
||||
if err != nil {
|
||||
if errors.Is(err, kes.ErrKeyNotFound) {
|
||||
return crypto.ObjectKey{}, errKMSKeyNotFound
|
||||
@@ -475,11 +490,10 @@ func EncryptRequest(content io.Reader, r *http.Request, bucket, object string, m
|
||||
func decryptObjectMeta(key []byte, bucket, object string, metadata map[string]string) ([]byte, error) {
|
||||
switch kind, _ := crypto.IsEncrypted(metadata); kind {
|
||||
case crypto.S3:
|
||||
KMS := GlobalKMS
|
||||
if KMS == nil {
|
||||
if GlobalKMS == nil {
|
||||
return nil, errKMSNotConfigured
|
||||
}
|
||||
objectKey, err := crypto.S3.UnsealObjectKey(KMS, metadata, bucket, object)
|
||||
objectKey, err := crypto.S3.UnsealObjectKey(GlobalKMS, metadata, bucket, object)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
@@ -1089,7 +1103,7 @@ func (o *ObjectInfo) decryptPartsChecksums() {
|
||||
if _, encrypted := crypto.IsEncrypted(o.UserDefined); encrypted {
|
||||
decrypted, err := o.metadataDecrypter()("object-checksum", data)
|
||||
if err != nil {
|
||||
logger.LogIf(GlobalContext, err)
|
||||
encLogIf(GlobalContext, err)
|
||||
return
|
||||
}
|
||||
data = decrypted
|
||||
@@ -1151,7 +1165,7 @@ func (o *ObjectInfo) decryptChecksums(part int) map[string]string {
|
||||
if _, encrypted := crypto.IsEncrypted(o.UserDefined); encrypted {
|
||||
decrypted, err := o.metadataDecrypter()("object-checksum", data)
|
||||
if err != nil {
|
||||
logger.LogIf(GlobalContext, err)
|
||||
encLogIf(GlobalContext, err)
|
||||
return nil
|
||||
}
|
||||
data = decrypted
|
||||
|
||||
+27
-29
@@ -23,7 +23,6 @@ import (
|
||||
"net/url"
|
||||
"runtime"
|
||||
"sort"
|
||||
"strconv"
|
||||
"strings"
|
||||
|
||||
"github.com/cespare/xxhash/v2"
|
||||
@@ -134,7 +133,7 @@ func possibleSetCountsWithSymmetry(setCounts []uint64, argPatterns []ellipses.Ar
|
||||
// on each index, this function also determines the final set size
|
||||
// The final set size has the affinity towards choosing smaller
|
||||
// indexes (total sets)
|
||||
func getSetIndexes(args []string, totalSizes []uint64, customSetDriveCount uint64, argPatterns []ellipses.ArgPattern) (setIndexes [][]uint64, err error) {
|
||||
func getSetIndexes(args []string, totalSizes []uint64, setDriveCount uint64, argPatterns []ellipses.ArgPattern) (setIndexes [][]uint64, err error) {
|
||||
if len(totalSizes) == 0 || len(args) == 0 {
|
||||
return nil, errInvalidArgument
|
||||
}
|
||||
@@ -142,7 +141,7 @@ func getSetIndexes(args []string, totalSizes []uint64, customSetDriveCount uint6
|
||||
setIndexes = make([][]uint64, len(totalSizes))
|
||||
for _, totalSize := range totalSizes {
|
||||
// Check if totalSize has minimum range upto setSize
|
||||
if totalSize < setSizes[0] || totalSize < customSetDriveCount {
|
||||
if totalSize < setSizes[0] || totalSize < setDriveCount {
|
||||
msg := fmt.Sprintf("Incorrect number of endpoints provided %s", args)
|
||||
return nil, config.ErrInvalidNumberOfErasureEndpoints(nil).Msg(msg)
|
||||
}
|
||||
@@ -167,11 +166,11 @@ func getSetIndexes(args []string, totalSizes []uint64, customSetDriveCount uint6
|
||||
var setSize uint64
|
||||
// Custom set drive count allows to override automatic distribution.
|
||||
// only meant if you want to further optimize drive distribution.
|
||||
if customSetDriveCount > 0 {
|
||||
if setDriveCount > 0 {
|
||||
msg := fmt.Sprintf("Invalid set drive count. Acceptable values for %d number drives are %d", commonSize, setCounts)
|
||||
var found bool
|
||||
for _, ss := range setCounts {
|
||||
if ss == customSetDriveCount {
|
||||
if ss == setDriveCount {
|
||||
found = true
|
||||
}
|
||||
}
|
||||
@@ -180,8 +179,7 @@ func getSetIndexes(args []string, totalSizes []uint64, customSetDriveCount uint6
|
||||
}
|
||||
|
||||
// No automatic symmetry calculation expected, user is on their own
|
||||
setSize = customSetDriveCount
|
||||
globalCustomErasureDriveCount = true
|
||||
setSize = setDriveCount
|
||||
} else {
|
||||
// Returns possible set counts with symmetry.
|
||||
setCounts = possibleSetCountsWithSymmetry(setCounts, argPatterns)
|
||||
@@ -256,7 +254,7 @@ func getTotalSizes(argPatterns []ellipses.ArgPattern) []uint64 {
|
||||
// Parses all arguments and returns an endpointSet which is a collection
|
||||
// of endpoints following the ellipses pattern, this is what is used
|
||||
// by the object layer for initializing itself.
|
||||
func parseEndpointSet(customSetDriveCount uint64, args ...string) (ep endpointSet, err error) {
|
||||
func parseEndpointSet(setDriveCount uint64, args ...string) (ep endpointSet, err error) {
|
||||
argPatterns := make([]ellipses.ArgPattern, len(args))
|
||||
for i, arg := range args {
|
||||
patterns, perr := ellipses.FindEllipsesPatterns(arg)
|
||||
@@ -266,7 +264,7 @@ func parseEndpointSet(customSetDriveCount uint64, args ...string) (ep endpointSe
|
||||
argPatterns[i] = patterns
|
||||
}
|
||||
|
||||
ep.setIndexes, err = getSetIndexes(args, getTotalSizes(argPatterns), customSetDriveCount, argPatterns)
|
||||
ep.setIndexes, err = getSetIndexes(args, getTotalSizes(argPatterns), setDriveCount, argPatterns)
|
||||
if err != nil {
|
||||
return endpointSet{}, config.ErrInvalidErasureEndpoints(nil).Msg(err.Error())
|
||||
}
|
||||
@@ -281,23 +279,14 @@ func parseEndpointSet(customSetDriveCount uint64, args ...string) (ep endpointSe
|
||||
// specific set size.
|
||||
// For example: {1...64} is divided into 4 sets each of size 16.
|
||||
// This applies to even distributed setup syntax as well.
|
||||
func GetAllSets(args ...string) ([][]string, error) {
|
||||
var customSetDriveCount uint64
|
||||
if v := env.Get(EnvErasureSetDriveCount, ""); v != "" {
|
||||
driveCount, err := strconv.Atoi(v)
|
||||
if err != nil {
|
||||
return nil, config.ErrInvalidErasureSetSize(err)
|
||||
}
|
||||
customSetDriveCount = uint64(driveCount)
|
||||
}
|
||||
|
||||
func GetAllSets(setDriveCount uint64, args ...string) ([][]string, error) {
|
||||
var setArgs [][]string
|
||||
if !ellipses.HasEllipses(args...) {
|
||||
var setIndexes [][]uint64
|
||||
// Check if we have more one args.
|
||||
if len(args) > 1 {
|
||||
var err error
|
||||
setIndexes, err = getSetIndexes(args, []uint64{uint64(len(args))}, customSetDriveCount, nil)
|
||||
setIndexes, err = getSetIndexes(args, []uint64{uint64(len(args))}, setDriveCount, nil)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
@@ -311,7 +300,7 @@ func GetAllSets(args ...string) ([][]string, error) {
|
||||
}
|
||||
setArgs = s.Get()
|
||||
} else {
|
||||
s, err := parseEndpointSet(customSetDriveCount, args...)
|
||||
s, err := parseEndpointSet(setDriveCount, args...)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
@@ -336,8 +325,6 @@ const (
|
||||
EnvErasureSetDriveCount = "MINIO_ERASURE_SET_DRIVE_COUNT"
|
||||
)
|
||||
|
||||
var globalCustomErasureDriveCount = false
|
||||
|
||||
type node struct {
|
||||
nodeName string
|
||||
disks []string
|
||||
@@ -366,8 +353,13 @@ func (el *endpointsList) add(arg string) error {
|
||||
return nil
|
||||
}
|
||||
|
||||
type poolArgs struct {
|
||||
args []string
|
||||
setDriveCount uint64
|
||||
}
|
||||
|
||||
// buildDisksLayoutFromConfFile supports with and without ellipses transparently.
|
||||
func buildDisksLayoutFromConfFile(pools [][]string) (layout disksLayout, err error) {
|
||||
func buildDisksLayoutFromConfFile(pools []poolArgs) (layout disksLayout, err error) {
|
||||
if len(pools) == 0 {
|
||||
return layout, errInvalidArgument
|
||||
}
|
||||
@@ -375,7 +367,7 @@ func buildDisksLayoutFromConfFile(pools [][]string) (layout disksLayout, err err
|
||||
for _, list := range pools {
|
||||
var endpointsList endpointsList
|
||||
|
||||
for _, arg := range list {
|
||||
for _, arg := range list.args {
|
||||
switch {
|
||||
case ellipses.HasList(arg):
|
||||
patterns, err := ellipses.FindListPatterns(arg)
|
||||
@@ -436,7 +428,7 @@ func buildDisksLayoutFromConfFile(pools [][]string) (layout disksLayout, err err
|
||||
}
|
||||
}
|
||||
|
||||
setArgs, err := GetAllSets(eps...)
|
||||
setArgs, err := GetAllSets(list.setDriveCount, eps...)
|
||||
if err != nil {
|
||||
return layout, err
|
||||
}
|
||||
@@ -469,15 +461,21 @@ func mergeDisksLayoutFromArgs(args []string, ctxt *serverCtxt) (err error) {
|
||||
|
||||
var setArgs [][]string
|
||||
|
||||
v, err := env.GetInt(EnvErasureSetDriveCount, 0)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
setDriveCount := uint64(v)
|
||||
|
||||
// None of the args have ellipses use the old style.
|
||||
if ok {
|
||||
setArgs, err = GetAllSets(args...)
|
||||
setArgs, err = GetAllSets(setDriveCount, args...)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
ctxt.Layout = disksLayout{
|
||||
legacy: true,
|
||||
pools: []poolDisksLayout{{layout: setArgs}},
|
||||
pools: []poolDisksLayout{{layout: setArgs, cmdline: strings.Join(args, " ")}},
|
||||
}
|
||||
return
|
||||
}
|
||||
@@ -487,7 +485,7 @@ func mergeDisksLayoutFromArgs(args []string, ctxt *serverCtxt) (err error) {
|
||||
// TODO: support SNSD deployments to be decommissioned in future
|
||||
return fmt.Errorf("all args must have ellipses for pool expansion (%w) args: %s", errInvalidArgument, args)
|
||||
}
|
||||
setArgs, err = GetAllSets(arg)
|
||||
setArgs, err = GetAllSets(setDriveCount, arg)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
+7
-7
@@ -514,7 +514,7 @@ func (l EndpointServerPools) hostsSorted() []*xnet.Host {
|
||||
}
|
||||
host, err := xnet.ParseHost(hostStr)
|
||||
if err != nil {
|
||||
logger.LogIf(GlobalContext, err)
|
||||
internalLogIf(GlobalContext, err)
|
||||
continue
|
||||
}
|
||||
hosts[i] = host
|
||||
@@ -645,7 +645,7 @@ func (endpoints Endpoints) UpdateIsLocal() error {
|
||||
))
|
||||
ctx := logger.SetReqInfo(GlobalContext,
|
||||
reqInfo)
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("%s resolves to localhost in a containerized deployment, waiting for it to resolve to a valid IP",
|
||||
bootLogOnceIf(ctx, fmt.Errorf("%s resolves to localhost in a containerized deployment, waiting for it to resolve to a valid IP",
|
||||
endpoints[i].Hostname()), endpoints[i].Hostname(), logger.ErrorKind)
|
||||
}
|
||||
|
||||
@@ -675,7 +675,7 @@ func (endpoints Endpoints) UpdateIsLocal() error {
|
||||
))
|
||||
ctx := logger.SetReqInfo(GlobalContext,
|
||||
reqInfo)
|
||||
logger.LogOnceIf(ctx, err, endpoints[i].Hostname(), logger.ErrorKind)
|
||||
bootLogOnceIf(ctx, err, endpoints[i].Hostname(), logger.ErrorKind)
|
||||
}
|
||||
} else {
|
||||
resolvedList[i] = true
|
||||
@@ -807,7 +807,7 @@ func (p PoolEndpointList) UpdateIsLocal() error {
|
||||
continue
|
||||
}
|
||||
|
||||
if endpoint.Host == "" {
|
||||
if endpoint.Host == "" || (orchestrated && env.Get("_MINIO_SERVER_LOCAL", "") == endpoint.Host) {
|
||||
if !foundLocal {
|
||||
foundLocal = true
|
||||
}
|
||||
@@ -837,7 +837,7 @@ func (p PoolEndpointList) UpdateIsLocal() error {
|
||||
))
|
||||
ctx := logger.SetReqInfo(GlobalContext,
|
||||
reqInfo)
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("%s resolves to localhost in a containerized deployment, waiting for it to resolve to a valid IP",
|
||||
bootLogOnceIf(ctx, fmt.Errorf("%s resolves to localhost in a containerized deployment, waiting for it to resolve to a valid IP",
|
||||
endpoint.Hostname()), endpoint.Hostname(), logger.ErrorKind)
|
||||
}
|
||||
continue
|
||||
@@ -866,7 +866,7 @@ func (p PoolEndpointList) UpdateIsLocal() error {
|
||||
))
|
||||
ctx := logger.SetReqInfo(GlobalContext,
|
||||
reqInfo)
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("Unable to resolve DNS for %s: %w", endpoint, err), endpoint.Hostname(), logger.ErrorKind)
|
||||
bootLogOnceIf(ctx, fmt.Errorf("Unable to resolve DNS for %s: %w", endpoint, err), endpoint.Hostname(), logger.ErrorKind)
|
||||
}
|
||||
} else {
|
||||
resolvedList[endpoint] = true
|
||||
@@ -1205,7 +1205,7 @@ func GetProxyEndpoints(endpointServerPools EndpointServerPools) []ProxyEndpoint
|
||||
|
||||
proxyEps = append(proxyEps, ProxyEndpoint{
|
||||
Endpoint: endpoint,
|
||||
Transport: globalProxyTransport,
|
||||
Transport: globalRemoteTargetTransport,
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
@@ -25,7 +25,6 @@ import (
|
||||
"sync"
|
||||
"time"
|
||||
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/sync/errgroup"
|
||||
)
|
||||
|
||||
@@ -154,6 +153,8 @@ func readMultipleFiles(ctx context.Context, disks []StorageAPI, req ReadMultiple
|
||||
errFileVersionNotFound,
|
||||
io.ErrUnexpectedEOF, // some times we would read without locks, ignore these errors
|
||||
io.EOF, // some times we would read without locks, ignore these errors
|
||||
context.DeadlineExceeded,
|
||||
context.Canceled,
|
||||
}
|
||||
ignoredErrs = append(ignoredErrs, objectOpIgnoredErrs...)
|
||||
|
||||
@@ -163,7 +164,7 @@ func readMultipleFiles(ctx context.Context, disks []StorageAPI, req ReadMultiple
|
||||
continue
|
||||
}
|
||||
if !IsErr(err, ignoredErrs...) {
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("Drive %s, path (%s/%s) returned an error (%w)",
|
||||
storageLogOnceIf(ctx, fmt.Errorf("Drive %s, path (%s/%s) returned an error (%w)",
|
||||
disks[index], req.Bucket, req.Prefix, err),
|
||||
disks[index].String())
|
||||
}
|
||||
|
||||
@@ -38,6 +38,7 @@ type parallelReader struct {
|
||||
shardFileSize int64
|
||||
buf [][]byte
|
||||
readerToBuf []int
|
||||
stashBuffer []byte
|
||||
}
|
||||
|
||||
// newParallelReader returns parallelReader.
|
||||
@@ -46,6 +47,21 @@ func newParallelReader(readers []io.ReaderAt, e Erasure, offset, totalLength int
|
||||
for i := range r2b {
|
||||
r2b[i] = i
|
||||
}
|
||||
bufs := make([][]byte, len(readers))
|
||||
// Fill buffers
|
||||
b := globalBytePoolCap.Load().Get()
|
||||
shardSize := int(e.ShardSize())
|
||||
if cap(b) < len(readers)*shardSize {
|
||||
// We should always have enough capacity, but older objects may be bigger.
|
||||
globalBytePoolCap.Load().Put(b)
|
||||
b = nil
|
||||
} else {
|
||||
// Seed the buffers.
|
||||
for i := range bufs {
|
||||
bufs[i] = b[i*shardSize : (i+1)*shardSize]
|
||||
}
|
||||
}
|
||||
|
||||
return ¶llelReader{
|
||||
readers: readers,
|
||||
orgReaders: readers,
|
||||
@@ -55,6 +71,15 @@ func newParallelReader(readers []io.ReaderAt, e Erasure, offset, totalLength int
|
||||
shardFileSize: e.ShardFileSize(totalLength),
|
||||
buf: make([][]byte, len(readers)),
|
||||
readerToBuf: r2b,
|
||||
stashBuffer: b,
|
||||
}
|
||||
}
|
||||
|
||||
// Done will release any resources used by the parallelReader.
|
||||
func (p *parallelReader) Done() {
|
||||
if p.stashBuffer != nil {
|
||||
globalBytePoolCap.Load().Put(p.stashBuffer)
|
||||
p.stashBuffer = nil
|
||||
}
|
||||
}
|
||||
|
||||
@@ -224,6 +249,7 @@ func (e Erasure) Decode(ctx context.Context, writer io.Writer, readers []io.Read
|
||||
if len(prefer) == len(readers) {
|
||||
reader.preferReaders(prefer)
|
||||
}
|
||||
defer reader.Done()
|
||||
|
||||
startBlock := offset / e.blockSize
|
||||
endBlock := (offset + length) / e.blockSize
|
||||
@@ -294,6 +320,7 @@ func (e Erasure) Heal(ctx context.Context, writers []io.Writer, readers []io.Rea
|
||||
if len(readers) == len(prefer) {
|
||||
reader.preferReaders(prefer)
|
||||
}
|
||||
defer reader.Done()
|
||||
|
||||
startBlock := int64(0)
|
||||
endBlock := totalLength / e.blockSize
|
||||
|
||||
+78
-54
@@ -29,6 +29,7 @@ import (
|
||||
"time"
|
||||
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio/internal/grid"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/sync/errgroup"
|
||||
)
|
||||
@@ -43,8 +44,8 @@ const (
|
||||
healingMetricCheckAbandonedParts
|
||||
)
|
||||
|
||||
func (er erasureObjects) listAndHeal(bucket, prefix string, scanMode madmin.HealScanMode, healEntry func(string, metaCacheEntry, madmin.HealScanMode) error) error {
|
||||
ctx, cancel := context.WithCancel(context.Background())
|
||||
func (er erasureObjects) listAndHeal(ctx context.Context, bucket, prefix string, scanMode madmin.HealScanMode, healEntry func(string, metaCacheEntry, madmin.HealScanMode) error) error {
|
||||
ctx, cancel := context.WithCancel(ctx)
|
||||
defer cancel()
|
||||
|
||||
disks, _ := er.getOnlineDisksWithHealing(false)
|
||||
@@ -52,6 +53,10 @@ func (er erasureObjects) listAndHeal(bucket, prefix string, scanMode madmin.Heal
|
||||
return errors.New("listAndHeal: No non-healing drives found")
|
||||
}
|
||||
|
||||
expectedDisks := len(disks)/2 + 1
|
||||
fallbackDisks := disks[expectedDisks:]
|
||||
disks = disks[:expectedDisks]
|
||||
|
||||
// How to resolve partial results.
|
||||
resolver := metadataResolutionParams{
|
||||
dirQuorum: 1,
|
||||
@@ -68,6 +73,7 @@ func (er erasureObjects) listAndHeal(bucket, prefix string, scanMode madmin.Heal
|
||||
|
||||
lopts := listPathRawOptions{
|
||||
disks: disks,
|
||||
fallbackDisks: fallbackDisks,
|
||||
bucket: bucket,
|
||||
path: path,
|
||||
filterPrefix: filterPrefix,
|
||||
@@ -115,10 +121,6 @@ func listAllBuckets(ctx context.Context, storageDisks []StorageAPI, healBuckets
|
||||
// we ignore disk not found errors
|
||||
return nil
|
||||
}
|
||||
if storageDisks[index].Healing() != nil {
|
||||
// we ignore disks under healing
|
||||
return nil
|
||||
}
|
||||
volsInfo, err := storageDisks[index].ListVols(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
@@ -210,6 +212,34 @@ func (fi FileInfo) DataMov() bool {
|
||||
return ok
|
||||
}
|
||||
|
||||
func (er *erasureObjects) auditHealObject(ctx context.Context, bucket, object, versionID string, result madmin.HealResultItem, err error) {
|
||||
if len(logger.AuditTargets()) == 0 {
|
||||
return
|
||||
}
|
||||
|
||||
opts := AuditLogOptions{
|
||||
Event: "HealObject",
|
||||
Bucket: bucket,
|
||||
Object: object,
|
||||
VersionID: versionID,
|
||||
}
|
||||
if err != nil {
|
||||
opts.Error = err.Error()
|
||||
}
|
||||
|
||||
opts.Tags = map[string]interface{}{
|
||||
"healResult": result,
|
||||
"objectLocation": auditObjectOp{
|
||||
Name: decodeDirObject(object),
|
||||
Pool: er.poolIndex + 1,
|
||||
Set: er.setIndex + 1,
|
||||
Drives: er.getEndpointStrings(),
|
||||
},
|
||||
}
|
||||
|
||||
auditLogInternal(ctx, opts)
|
||||
}
|
||||
|
||||
// Heals an object by re-writing corrupt/missing erasure blocks.
|
||||
func (er *erasureObjects) healObject(ctx context.Context, bucket string, object string, versionID string, opts madmin.HealOpts) (result madmin.HealResultItem, err error) {
|
||||
dryRun := opts.DryRun
|
||||
@@ -218,6 +248,10 @@ func (er *erasureObjects) healObject(ctx context.Context, bucket string, object
|
||||
storageDisks := er.getDisks()
|
||||
storageEndpoints := er.getEndpoints()
|
||||
|
||||
defer func() {
|
||||
er.auditHealObject(ctx, bucket, object, versionID, result, err)
|
||||
}()
|
||||
|
||||
if globalTrace.NumSubscribers(madmin.TraceHealing) > 0 {
|
||||
startTime := time.Now()
|
||||
defer func() {
|
||||
@@ -257,21 +291,18 @@ func (er *erasureObjects) healObject(ctx context.Context, bucket string, object
|
||||
|
||||
readQuorum, _, err := objectQuorumFromMeta(ctx, partsMetadata, errs, er.defaultParityCount)
|
||||
if err != nil {
|
||||
m, err := er.deleteIfDangling(ctx, bucket, object, partsMetadata, errs, nil, ObjectOptions{
|
||||
m, derr := er.deleteIfDangling(ctx, bucket, object, partsMetadata, errs, nil, ObjectOptions{
|
||||
VersionID: versionID,
|
||||
})
|
||||
errs = make([]error, len(errs))
|
||||
for i := range errs {
|
||||
errs[i] = err
|
||||
}
|
||||
if err == nil {
|
||||
// Dangling object successfully purged, size is '0'
|
||||
m.Size = 0
|
||||
}
|
||||
// Generate file/version not found with default heal result
|
||||
err = errFileNotFound
|
||||
if versionID != "" {
|
||||
err = errFileVersionNotFound
|
||||
if derr == nil {
|
||||
derr = errFileNotFound
|
||||
if versionID != "" {
|
||||
derr = errFileVersionNotFound
|
||||
}
|
||||
// We did find a new danging object
|
||||
return er.defaultHealResult(m, storageDisks, storageEndpoints,
|
||||
errs, bucket, object, versionID), derr
|
||||
}
|
||||
return er.defaultHealResult(m, storageDisks, storageEndpoints,
|
||||
errs, bucket, object, versionID), err
|
||||
@@ -328,32 +359,16 @@ func (er *erasureObjects) healObject(ctx context.Context, bucket string, object
|
||||
switch {
|
||||
case v != nil:
|
||||
driveState = madmin.DriveStateOk
|
||||
case errs[i] == errDiskNotFound, dataErrs[i] == errDiskNotFound:
|
||||
case errors.Is(errs[i], errDiskNotFound), errors.Is(dataErrs[i], errDiskNotFound):
|
||||
driveState = madmin.DriveStateOffline
|
||||
case errs[i] == errFileNotFound, errs[i] == errFileVersionNotFound, errs[i] == errVolumeNotFound:
|
||||
fallthrough
|
||||
case dataErrs[i] == errFileNotFound, dataErrs[i] == errFileVersionNotFound, dataErrs[i] == errVolumeNotFound:
|
||||
case IsErr(errs[i], errFileNotFound, errFileVersionNotFound, errVolumeNotFound),
|
||||
IsErr(dataErrs[i], errFileNotFound, errFileVersionNotFound, errVolumeNotFound):
|
||||
driveState = madmin.DriveStateMissing
|
||||
default:
|
||||
// all remaining cases imply corrupt data/metadata
|
||||
driveState = madmin.DriveStateCorrupt
|
||||
}
|
||||
|
||||
if shouldHealObjectOnDisk(errs[i], dataErrs[i], partsMetadata[i], latestMeta) {
|
||||
outDatedDisks[i] = storageDisks[i]
|
||||
disksToHealCount++
|
||||
result.Before.Drives = append(result.Before.Drives, madmin.HealDriveInfo{
|
||||
UUID: "",
|
||||
Endpoint: storageEndpoints[i].String(),
|
||||
State: driveState,
|
||||
})
|
||||
result.After.Drives = append(result.After.Drives, madmin.HealDriveInfo{
|
||||
UUID: "",
|
||||
Endpoint: storageEndpoints[i].String(),
|
||||
State: driveState,
|
||||
})
|
||||
continue
|
||||
}
|
||||
result.Before.Drives = append(result.Before.Drives, madmin.HealDriveInfo{
|
||||
UUID: "",
|
||||
Endpoint: storageEndpoints[i].String(),
|
||||
@@ -364,6 +379,12 @@ func (er *erasureObjects) healObject(ctx context.Context, bucket string, object
|
||||
Endpoint: storageEndpoints[i].String(),
|
||||
State: driveState,
|
||||
})
|
||||
|
||||
if shouldHealObjectOnDisk(errs[i], dataErrs[i], partsMetadata[i], latestMeta) {
|
||||
outDatedDisks[i] = storageDisks[i]
|
||||
disksToHealCount++
|
||||
continue
|
||||
}
|
||||
}
|
||||
|
||||
if isAllNotFound(errs) {
|
||||
@@ -394,18 +415,18 @@ func (er *erasureObjects) healObject(ctx context.Context, bucket string, object
|
||||
VersionID: versionID,
|
||||
})
|
||||
errs = make([]error, len(errs))
|
||||
if err == nil {
|
||||
err = errFileNotFound
|
||||
if versionID != "" {
|
||||
err = errFileVersionNotFound
|
||||
}
|
||||
// We did find a new danging object
|
||||
return er.defaultHealResult(m, storageDisks, storageEndpoints,
|
||||
errs, bucket, object, versionID), err
|
||||
}
|
||||
for i := range errs {
|
||||
errs[i] = err
|
||||
}
|
||||
if err == nil {
|
||||
// Dangling object successfully purged, size is '0'
|
||||
m.Size = 0
|
||||
}
|
||||
// Generate file/version not found with default heal result
|
||||
err = errFileNotFound
|
||||
if versionID != "" {
|
||||
err = errFileVersionNotFound
|
||||
}
|
||||
return er.defaultHealResult(m, storageDisks, storageEndpoints,
|
||||
errs, bucket, object, versionID), err
|
||||
}
|
||||
@@ -429,7 +450,7 @@ func (er *erasureObjects) healObject(ctx context.Context, bucket string, object
|
||||
if !latestMeta.Deleted && len(latestMeta.Erasure.Distribution) != len(availableDisks) {
|
||||
err := fmt.Errorf("unexpected file distribution (%v) from available disks (%v), looks like backend disks have been manually modified refusing to heal %s/%s(%s)",
|
||||
latestMeta.Erasure.Distribution, availableDisks, bucket, object, versionID)
|
||||
logger.LogOnceIf(ctx, err, "heal-object-available-disks")
|
||||
healingLogOnceIf(ctx, err, "heal-object-available-disks")
|
||||
return er.defaultHealResult(latestMeta, storageDisks, storageEndpoints, errs,
|
||||
bucket, object, versionID), err
|
||||
}
|
||||
@@ -439,7 +460,7 @@ func (er *erasureObjects) healObject(ctx context.Context, bucket string, object
|
||||
if !latestMeta.Deleted && len(latestMeta.Erasure.Distribution) != len(outDatedDisks) {
|
||||
err := fmt.Errorf("unexpected file distribution (%v) from outdated disks (%v), looks like backend disks have been manually modified refusing to heal %s/%s(%s)",
|
||||
latestMeta.Erasure.Distribution, outDatedDisks, bucket, object, versionID)
|
||||
logger.LogOnceIf(ctx, err, "heal-object-outdated-disks")
|
||||
healingLogOnceIf(ctx, err, "heal-object-outdated-disks")
|
||||
return er.defaultHealResult(latestMeta, storageDisks, storageEndpoints, errs,
|
||||
bucket, object, versionID), err
|
||||
}
|
||||
@@ -449,7 +470,7 @@ func (er *erasureObjects) healObject(ctx context.Context, bucket string, object
|
||||
if !latestMeta.Deleted && len(latestMeta.Erasure.Distribution) != len(partsMetadata) {
|
||||
err := fmt.Errorf("unexpected file distribution (%v) from metadata entries (%v), looks like backend disks have been manually modified refusing to heal %s/%s(%s)",
|
||||
latestMeta.Erasure.Distribution, len(partsMetadata), bucket, object, versionID)
|
||||
logger.LogOnceIf(ctx, err, "heal-object-metadata-entries")
|
||||
healingLogOnceIf(ctx, err, "heal-object-metadata-entries")
|
||||
return er.defaultHealResult(latestMeta, storageDisks, storageEndpoints, errs,
|
||||
bucket, object, versionID), err
|
||||
}
|
||||
@@ -519,7 +540,10 @@ func (er *erasureObjects) healObject(ctx context.Context, bucket string, object
|
||||
}
|
||||
partPath := pathJoin(tmpID, dstDataDir, fmt.Sprintf("part.%d", partNumber))
|
||||
if len(inlineBuffers) > 0 {
|
||||
inlineBuffers[i] = bytes.NewBuffer(make([]byte, 0, erasure.ShardFileSize(latestMeta.Size)+32))
|
||||
buf := grid.GetByteBufferCap(int(erasure.ShardFileSize(latestMeta.Size)) + 64)
|
||||
inlineBuffers[i] = bytes.NewBuffer(buf[:0])
|
||||
defer grid.PutByteBuffer(buf)
|
||||
|
||||
writers[i] = newStreamingBitrotWriterBuffer(inlineBuffers[i], DefaultBitrotAlgorithm, erasure.ShardSize())
|
||||
} else {
|
||||
writers[i] = newBitrotWriter(disk, bucket, minioMetaTmpBucket, partPath,
|
||||
@@ -615,6 +639,7 @@ func (er *erasureObjects) checkAbandonedParts(ctx context.Context, bucket string
|
||||
if !opts.Remove || opts.DryRun {
|
||||
return nil
|
||||
}
|
||||
|
||||
if globalTrace.NumSubscribers(madmin.TraceHealing) > 0 {
|
||||
startTime := time.Now()
|
||||
defer func() {
|
||||
@@ -957,12 +982,12 @@ func isObjectDangling(metaArr []FileInfo, errs []error, dataErrs []error) (valid
|
||||
// However this requires a bit of a rewrite, leave this up for
|
||||
// future work.
|
||||
if notFoundMetaErrs > 0 && notFoundMetaErrs > validMeta.Erasure.ParityBlocks {
|
||||
// All xl.meta is beyond data blocks missing, this is dangling
|
||||
// All xl.meta is beyond parity blocks missing, this is dangling
|
||||
return validMeta, true
|
||||
}
|
||||
|
||||
if !validMeta.IsRemote() && notFoundPartsErrs > 0 && notFoundPartsErrs > validMeta.Erasure.ParityBlocks {
|
||||
// All data-dir is beyond data blocks missing, this is dangling
|
||||
// All data-dir is beyond parity blocks missing, this is dangling
|
||||
return validMeta, true
|
||||
}
|
||||
|
||||
@@ -1043,8 +1068,7 @@ func healTrace(funcName healingMetric, startTime time.Time, bucket, object strin
|
||||
}
|
||||
if err != nil {
|
||||
tr.Error = err.Error()
|
||||
} else {
|
||||
tr.HealResult = result
|
||||
}
|
||||
tr.HealResult = result
|
||||
globalTrace.Publish(tr)
|
||||
}
|
||||
|
||||
@@ -634,7 +634,7 @@ func TestHealingDanglingObject(t *testing.T) {
|
||||
defer removeRoots(fsDirs)
|
||||
|
||||
// Everything is fine, should return nil
|
||||
objLayer, disks, err := initObjectLayer(ctx, mustGetPoolEndpoints(0, fsDirs...))
|
||||
objLayer, _, err := initObjectLayer(ctx, mustGetPoolEndpoints(0, fsDirs...))
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
@@ -650,7 +650,7 @@ func TestHealingDanglingObject(t *testing.T) {
|
||||
t.Fatalf("Failed to make a bucket - %v", err)
|
||||
}
|
||||
|
||||
disks = objLayer.(*erasureServerPools).serverPools[0].erasureDisks[0]
|
||||
disks := objLayer.(*erasureServerPools).serverPools[0].erasureDisks[0]
|
||||
orgDisks := append([]StorageAPI{}, disks...)
|
||||
|
||||
// Enable versioning.
|
||||
@@ -1497,7 +1497,13 @@ func TestHealObjectErasure(t *testing.T) {
|
||||
er.getDisks = func() []StorageAPI {
|
||||
// Nil more than half the disks, to remove write quorum.
|
||||
for i := 0; i <= len(erasureDisks)/2; i++ {
|
||||
erasureDisks[i] = nil
|
||||
err := erasureDisks[i].Delete(context.Background(), bucket, object, DeleteOptions{
|
||||
Recursive: true,
|
||||
Immediate: false,
|
||||
})
|
||||
if err != nil {
|
||||
t.Fatalf("Failed to delete a file - %v", err)
|
||||
}
|
||||
}
|
||||
return erasureDisks
|
||||
}
|
||||
|
||||
@@ -19,22 +19,25 @@ package cmd
|
||||
|
||||
import (
|
||||
"context"
|
||||
"encoding/binary"
|
||||
"errors"
|
||||
"hash/crc32"
|
||||
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/sync/errgroup"
|
||||
)
|
||||
|
||||
// figure out the most commonVersions across disk that satisfies
|
||||
// the 'writeQuorum' this function returns '0' if quorum cannot
|
||||
// the 'writeQuorum' this function returns "" if quorum cannot
|
||||
// be achieved and disks have too many inconsistent versions.
|
||||
func reduceCommonVersions(diskVersions []uint64, writeQuorum int) (commonVersions uint64) {
|
||||
func reduceCommonVersions(diskVersions [][]byte, writeQuorum int) (versions []byte) {
|
||||
diskVersionsCount := make(map[uint64]int)
|
||||
for _, versions := range diskVersions {
|
||||
diskVersionsCount[versions]++
|
||||
if len(versions) > 0 {
|
||||
diskVersionsCount[binary.BigEndian.Uint64(versions)]++
|
||||
}
|
||||
}
|
||||
|
||||
var commonVersions uint64
|
||||
max := 0
|
||||
for versions, count := range diskVersionsCount {
|
||||
if max < count {
|
||||
@@ -44,10 +47,38 @@ func reduceCommonVersions(diskVersions []uint64, writeQuorum int) (commonVersion
|
||||
}
|
||||
|
||||
if max >= writeQuorum {
|
||||
return commonVersions
|
||||
for _, versions := range diskVersions {
|
||||
if binary.BigEndian.Uint64(versions) == commonVersions {
|
||||
return versions
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
return 0
|
||||
return []byte{}
|
||||
}
|
||||
|
||||
// figure out the most commonVersions across disk that satisfies
|
||||
// the 'writeQuorum' this function returns '0' if quorum cannot
|
||||
// be achieved and disks have too many inconsistent versions.
|
||||
func reduceCommonDataDir(dataDirs []string, writeQuorum int) (dataDir string) {
|
||||
dataDirsCount := make(map[string]int)
|
||||
for _, ddir := range dataDirs {
|
||||
dataDirsCount[ddir]++
|
||||
}
|
||||
|
||||
max := 0
|
||||
for ddir, count := range dataDirsCount {
|
||||
if max < count {
|
||||
max = count
|
||||
dataDir = ddir
|
||||
}
|
||||
}
|
||||
|
||||
if max >= writeQuorum {
|
||||
return dataDir
|
||||
}
|
||||
|
||||
return ""
|
||||
}
|
||||
|
||||
// Returns number of errors that occurred the most (incl. nil) and the
|
||||
@@ -284,7 +315,7 @@ func shuffleDisks(disks []StorageAPI, distribution []int) (shuffledDisks []Stora
|
||||
// the corresponding error in errs slice is not nil
|
||||
func evalDisks(disks []StorageAPI, errs []error) []StorageAPI {
|
||||
if len(errs) != len(disks) {
|
||||
logger.LogIf(GlobalContext, errors.New("unexpected drives/errors slice length"))
|
||||
bugLogIf(GlobalContext, errors.New("unexpected drives/errors slice length"))
|
||||
return nil
|
||||
}
|
||||
newDisks := make([]StorageAPI, len(disks))
|
||||
|
||||
@@ -30,7 +30,6 @@ import (
|
||||
"github.com/minio/minio/internal/crypto"
|
||||
"github.com/minio/minio/internal/hash/sha256"
|
||||
xhttp "github.com/minio/minio/internal/http"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/sync/errgroup"
|
||||
)
|
||||
|
||||
@@ -268,7 +267,7 @@ func (fi FileInfo) ObjectToPartOffset(ctx context.Context, offset int64) (partIn
|
||||
// Continue to towards the next part.
|
||||
partOffset -= part.Size
|
||||
}
|
||||
logger.LogIf(ctx, InvalidRange{})
|
||||
internalLogIf(ctx, InvalidRange{})
|
||||
// Offset beyond the size of the object return InvalidRange.
|
||||
return 0, 0, InvalidRange{}
|
||||
}
|
||||
@@ -276,7 +275,7 @@ func (fi FileInfo) ObjectToPartOffset(ctx context.Context, offset int64) (partIn
|
||||
func findFileInfoInQuorum(ctx context.Context, metaArr []FileInfo, modTime time.Time, etag string, quorum int) (FileInfo, error) {
|
||||
// with less quorum return error.
|
||||
if quorum < 1 {
|
||||
return FileInfo{}, errErasureReadQuorum
|
||||
return FileInfo{}, InsufficientReadQuorum{Err: errErasureReadQuorum, Type: RQInsufficientOnlineDrives}
|
||||
}
|
||||
metaHashes := make([]string, len(metaArr))
|
||||
h := sha256.New()
|
||||
@@ -342,7 +341,7 @@ func findFileInfoInQuorum(ctx context.Context, metaArr []FileInfo, modTime time.
|
||||
}
|
||||
|
||||
if maxCount < quorum {
|
||||
return FileInfo{}, errErasureReadQuorum
|
||||
return FileInfo{}, InsufficientReadQuorum{Err: errErasureReadQuorum, Type: RQInconsistentMeta}
|
||||
}
|
||||
|
||||
// Find the successor mod time in quorum, otherwise leave the
|
||||
@@ -378,7 +377,7 @@ func findFileInfoInQuorum(ctx context.Context, metaArr []FileInfo, modTime time.
|
||||
}
|
||||
return candidate, nil
|
||||
}
|
||||
return FileInfo{}, errErasureReadQuorum
|
||||
return FileInfo{}, InsufficientReadQuorum{Err: errErasureReadQuorum, Type: RQInconsistentMeta}
|
||||
}
|
||||
|
||||
// pickValidFileInfo - picks one valid FileInfo content and returns from a
|
||||
@@ -404,7 +403,7 @@ func writeUniqueFileInfo(ctx context.Context, disks []StorageAPI, origbucket, bu
|
||||
if fi.IsValid() {
|
||||
return disks[index].WriteMetadata(ctx, origbucket, bucket, prefix, fi)
|
||||
}
|
||||
return errCorruptedFormat
|
||||
return errFileCorrupt
|
||||
}, index)
|
||||
}
|
||||
|
||||
@@ -499,7 +498,7 @@ func objectQuorumFromMeta(ctx context.Context, partsMetaData []FileInfo, errs []
|
||||
parities := listObjectParities(partsMetaData, errs)
|
||||
parityBlocks := commonParity(parities, defaultParityCount)
|
||||
if parityBlocks < 0 {
|
||||
return -1, -1, errErasureReadQuorum
|
||||
return -1, -1, InsufficientReadQuorum{Err: errErasureReadQuorum, Type: RQInsufficientOnlineDrives}
|
||||
}
|
||||
|
||||
dataBlocks := len(partsMetaData) - parityBlocks
|
||||
|
||||
@@ -210,13 +210,13 @@ func TestFindFileInfoInQuorum(t *testing.T) {
|
||||
{
|
||||
fis: getNFInfo(16, 7, 1603863445, "36a21454-a2ca-11eb-bbaa-93a81c686f21", nil),
|
||||
modTime: time.Unix(1603863445, 0),
|
||||
expectedErr: errErasureReadQuorum,
|
||||
expectedErr: InsufficientReadQuorum{},
|
||||
expectedQuorum: 8,
|
||||
},
|
||||
{
|
||||
fis: getNFInfo(16, 16, 1603863445, "36a21454-a2ca-11eb-bbaa-93a81c686f21", nil),
|
||||
modTime: time.Unix(1603863445, 0),
|
||||
expectedErr: errErasureReadQuorum,
|
||||
expectedErr: InsufficientReadQuorum{},
|
||||
expectedQuorum: 0,
|
||||
},
|
||||
{
|
||||
@@ -241,7 +241,9 @@ func TestFindFileInfoInQuorum(t *testing.T) {
|
||||
test := test
|
||||
t.Run("", func(t *testing.T) {
|
||||
fi, err := findFileInfoInQuorum(context.Background(), test.fis, test.modTime, "", test.expectedQuorum)
|
||||
if err != test.expectedErr {
|
||||
_, ok1 := err.(InsufficientReadQuorum)
|
||||
_, ok2 := test.expectedErr.(InsufficientReadQuorum)
|
||||
if ok1 != ok2 {
|
||||
t.Errorf("Expected %s, got %s", test.expectedErr, err)
|
||||
}
|
||||
if test.succmodTimes != nil {
|
||||
|
||||
+66
-39
@@ -194,11 +194,10 @@ func (er erasureObjects) deleteAll(ctx context.Context, bucket, prefix string) {
|
||||
|
||||
// Remove the old multipart uploads on the given disk.
|
||||
func (er erasureObjects) cleanupStaleUploadsOnDisk(ctx context.Context, disk StorageAPI, expiry time.Duration) {
|
||||
now := time.Now()
|
||||
diskPath := disk.Endpoint().Path
|
||||
drivePath := disk.Endpoint().Path
|
||||
|
||||
readDirFn(pathJoin(diskPath, minioMetaMultipartBucket), func(shaDir string, typ os.FileMode) error {
|
||||
readDirFn(pathJoin(diskPath, minioMetaMultipartBucket, shaDir), func(uploadIDDir string, typ os.FileMode) error {
|
||||
readDirFn(pathJoin(drivePath, minioMetaMultipartBucket), func(shaDir string, typ os.FileMode) error {
|
||||
readDirFn(pathJoin(drivePath, minioMetaMultipartBucket, shaDir), func(uploadIDDir string, typ os.FileMode) error {
|
||||
uploadIDPath := pathJoin(shaDir, uploadIDDir)
|
||||
fi, err := disk.ReadVersion(ctx, "", minioMetaMultipartBucket, uploadIDPath, "", ReadOptions{})
|
||||
if err != nil {
|
||||
@@ -206,9 +205,12 @@ func (er erasureObjects) cleanupStaleUploadsOnDisk(ctx context.Context, disk Sto
|
||||
}
|
||||
w := xioutil.NewDeadlineWorker(globalDriveConfig.GetMaxTimeout())
|
||||
return w.Run(func() error {
|
||||
wait := deletedCleanupSleeper.Timer(ctx)
|
||||
if now.Sub(fi.ModTime) > expiry {
|
||||
removeAll(pathJoin(diskPath, minioMetaMultipartBucket, uploadIDPath))
|
||||
wait := deleteMultipartCleanupSleeper.Timer(ctx)
|
||||
if time.Since(fi.ModTime) > expiry {
|
||||
pathUUID := mustGetUUID()
|
||||
targetPath := pathJoin(drivePath, minioMetaTmpDeletedBucket, pathUUID)
|
||||
|
||||
renameAll(pathJoin(drivePath, minioMetaMultipartBucket, uploadIDPath), targetPath, pathJoin(drivePath, minioMetaBucket))
|
||||
}
|
||||
wait()
|
||||
return nil
|
||||
@@ -220,19 +222,23 @@ func (er erasureObjects) cleanupStaleUploadsOnDisk(ctx context.Context, disk Sto
|
||||
}
|
||||
w := xioutil.NewDeadlineWorker(globalDriveConfig.GetMaxTimeout())
|
||||
return w.Run(func() error {
|
||||
wait := deletedCleanupSleeper.Timer(ctx)
|
||||
if now.Sub(vi.Created) > expiry {
|
||||
wait := deleteMultipartCleanupSleeper.Timer(ctx)
|
||||
if time.Since(vi.Created) > expiry {
|
||||
pathUUID := mustGetUUID()
|
||||
targetPath := pathJoin(drivePath, minioMetaTmpDeletedBucket, pathUUID)
|
||||
|
||||
// We are not deleting shaDir recursively here, if shaDir is empty
|
||||
// and its older then we can happily delete it.
|
||||
Remove(pathJoin(diskPath, minioMetaMultipartBucket, shaDir))
|
||||
Rename(pathJoin(drivePath, minioMetaMultipartBucket, shaDir), targetPath)
|
||||
}
|
||||
wait()
|
||||
return nil
|
||||
})
|
||||
})
|
||||
|
||||
readDirFn(pathJoin(diskPath, minioMetaTmpBucket), func(tmpDir string, typ os.FileMode) error {
|
||||
if tmpDir == ".trash/" { // do not remove .trash/ here, it has its own routines
|
||||
readDirFn(pathJoin(drivePath, minioMetaTmpBucket), func(tmpDir string, typ os.FileMode) error {
|
||||
if strings.HasPrefix(tmpDir, ".trash") {
|
||||
// do not remove .trash/ here, it has its own routines
|
||||
return nil
|
||||
}
|
||||
vi, err := disk.StatVol(ctx, pathJoin(minioMetaTmpBucket, tmpDir))
|
||||
@@ -241,9 +247,12 @@ func (er erasureObjects) cleanupStaleUploadsOnDisk(ctx context.Context, disk Sto
|
||||
}
|
||||
w := xioutil.NewDeadlineWorker(globalDriveConfig.GetMaxTimeout())
|
||||
return w.Run(func() error {
|
||||
wait := deletedCleanupSleeper.Timer(ctx)
|
||||
if now.Sub(vi.Created) > expiry {
|
||||
removeAll(pathJoin(diskPath, minioMetaTmpBucket, tmpDir))
|
||||
wait := deleteMultipartCleanupSleeper.Timer(ctx)
|
||||
if time.Since(vi.Created) > expiry {
|
||||
pathUUID := mustGetUUID()
|
||||
targetPath := pathJoin(drivePath, minioMetaTmpDeletedBucket, pathUUID)
|
||||
|
||||
renameAll(pathJoin(drivePath, minioMetaTmpBucket, tmpDir), targetPath, pathJoin(drivePath, minioMetaBucket))
|
||||
}
|
||||
wait()
|
||||
return nil
|
||||
@@ -590,7 +599,7 @@ func (er erasureObjects) PutObjectPart(ctx context.Context, bucket, object, uplo
|
||||
data := r.Reader
|
||||
// Validate input data size and it can never be less than zero.
|
||||
if data.Size() < -1 {
|
||||
logger.LogIf(ctx, errInvalidArgument, logger.ErrorKind)
|
||||
bugLogIf(ctx, errInvalidArgument, logger.ErrorKind)
|
||||
return pi, toObjectErr(errInvalidArgument)
|
||||
}
|
||||
|
||||
@@ -670,12 +679,12 @@ func (er erasureObjects) PutObjectPart(ctx context.Context, bucket, object, uplo
|
||||
// Account for padding and forced compression overhead and encryption.
|
||||
buffer = make([]byte, data.ActualSize()+256+32+32, data.ActualSize()*2+512)
|
||||
} else {
|
||||
buffer = globalBytePoolCap.Get()
|
||||
defer globalBytePoolCap.Put(buffer)
|
||||
buffer = globalBytePoolCap.Load().Get()
|
||||
defer globalBytePoolCap.Load().Put(buffer)
|
||||
}
|
||||
case size >= fi.Erasure.BlockSize:
|
||||
buffer = globalBytePoolCap.Get()
|
||||
defer globalBytePoolCap.Put(buffer)
|
||||
buffer = globalBytePoolCap.Load().Get()
|
||||
defer globalBytePoolCap.Load().Put(buffer)
|
||||
case size < fi.Erasure.BlockSize:
|
||||
// No need to allocate fully fi.Erasure.BlockSize buffer if the incoming data is smaller.
|
||||
buffer = make([]byte, size, 2*size+int64(fi.Erasure.ParityBlocks+fi.Erasure.DataBlocks-1))
|
||||
@@ -696,10 +705,11 @@ func (er erasureObjects) PutObjectPart(ctx context.Context, bucket, object, uplo
|
||||
if data.Size() > bigFileThreshold {
|
||||
// Add input readahead.
|
||||
// We use 2 buffers, so we always have a full buffer of input.
|
||||
bufA := globalBytePoolCap.Get()
|
||||
bufB := globalBytePoolCap.Get()
|
||||
defer globalBytePoolCap.Put(bufA)
|
||||
defer globalBytePoolCap.Put(bufB)
|
||||
pool := globalBytePoolCap.Load()
|
||||
bufA := pool.Get()
|
||||
bufB := pool.Get()
|
||||
defer pool.Put(bufA)
|
||||
defer pool.Put(bufB)
|
||||
ra, err := readahead.NewReaderBuffer(data, [][]byte{bufA[:fi.Erasure.BlockSize], bufB[:fi.Erasure.BlockSize]})
|
||||
if err == nil {
|
||||
toEncode = ra
|
||||
@@ -729,6 +739,15 @@ func (er erasureObjects) PutObjectPart(ctx context.Context, bucket, object, uplo
|
||||
partPath := pathJoin(uploadIDPath, fi.DataDir, partSuffix)
|
||||
onlineDisks, err = renamePart(ctx, onlineDisks, minioMetaTmpBucket, tmpPartPath, minioMetaMultipartBucket, partPath, writeQuorum)
|
||||
if err != nil {
|
||||
if errors.Is(err, errFileNotFound) {
|
||||
// An in-quorum errFileNotFound means that client stream
|
||||
// prematurely closed and we do not find any xl.meta or
|
||||
// part.1's - in such a scenario we must return as if client
|
||||
// disconnected. This means that erasure.Encode() CreateFile()
|
||||
// did not do anything.
|
||||
return pi, IncompleteBody{Bucket: bucket, Object: object}
|
||||
}
|
||||
|
||||
return pi, toObjectErr(err, minioMetaMultipartBucket, partPath)
|
||||
}
|
||||
|
||||
@@ -1026,7 +1045,7 @@ func (er erasureObjects) CompleteMultipartUpload(ctx context.Context, bucket str
|
||||
if len(partInfoFiles) != len(parts) {
|
||||
// Should only happen through internal error
|
||||
err := fmt.Errorf("unexpected part result count: %d, want %d", len(partInfoFiles), len(parts))
|
||||
logger.LogIf(ctx, err)
|
||||
bugLogIf(ctx, err)
|
||||
return oi, toObjectErr(err, bucket, object)
|
||||
}
|
||||
|
||||
@@ -1096,7 +1115,7 @@ func (er erasureObjects) CompleteMultipartUpload(ctx context.Context, bucket str
|
||||
_, err := pfi.UnmarshalMsg(part.Data)
|
||||
if err != nil {
|
||||
// Maybe crash or similar.
|
||||
logger.LogIf(ctx, err)
|
||||
bugLogIf(ctx, err)
|
||||
return oi, InvalidPart{
|
||||
PartNumber: partID,
|
||||
}
|
||||
@@ -1105,7 +1124,7 @@ func (er erasureObjects) CompleteMultipartUpload(ctx context.Context, bucket str
|
||||
partI := pfi.Parts[0]
|
||||
partNumber := partI.Number
|
||||
if partID != partNumber {
|
||||
logger.LogIf(ctx, fmt.Errorf("part.%d.meta has incorrect corresponding part number: expected %d, got %d", partID, partID, partI.Number))
|
||||
internalLogIf(ctx, fmt.Errorf("part.%d.meta has incorrect corresponding part number: expected %d, got %d", partID, partID, partI.Number))
|
||||
return oi, InvalidPart{
|
||||
PartNumber: partID,
|
||||
}
|
||||
@@ -1212,7 +1231,7 @@ func (er erasureObjects) CompleteMultipartUpload(ctx context.Context, bucket str
|
||||
}
|
||||
|
||||
if opts.WantChecksum != nil {
|
||||
err := opts.WantChecksum.Matches(checksumCombined)
|
||||
err := opts.WantChecksum.Matches(checksumCombined, len(parts))
|
||||
if err != nil {
|
||||
return oi, err
|
||||
}
|
||||
@@ -1255,7 +1274,11 @@ func (er erasureObjects) CompleteMultipartUpload(ctx context.Context, bucket str
|
||||
}
|
||||
|
||||
// Save the consolidated actual size.
|
||||
fi.Metadata[ReservedMetadataPrefix+"actual-size"] = strconv.FormatInt(objectActualSize, 10)
|
||||
if opts.ReplicationRequest {
|
||||
fi.Metadata[ReservedMetadataPrefix+"actual-size"] = opts.UserDefined["X-Minio-Internal-Actual-Object-Size"]
|
||||
} else {
|
||||
fi.Metadata[ReservedMetadataPrefix+"actual-size"] = strconv.FormatInt(objectActualSize, 10)
|
||||
}
|
||||
|
||||
if opts.DataMovement {
|
||||
fi.SetDataMov()
|
||||
@@ -1297,24 +1320,28 @@ func (er erasureObjects) CompleteMultipartUpload(ctx context.Context, bucket str
|
||||
}()
|
||||
|
||||
// Rename the multipart object to final location.
|
||||
onlineDisks, versionsDisparity, err := renameData(ctx, onlineDisks, minioMetaMultipartBucket, uploadIDPath,
|
||||
onlineDisks, versions, oldDataDir, err := renameData(ctx, onlineDisks, minioMetaMultipartBucket, uploadIDPath,
|
||||
partsMetadata, bucket, object, writeQuorum)
|
||||
if err != nil {
|
||||
return oi, toObjectErr(err, bucket, object)
|
||||
return oi, toObjectErr(err, bucket, object, uploadID)
|
||||
}
|
||||
|
||||
if !opts.Speedtest && versionsDisparity {
|
||||
if err = er.commitRenameDataDir(ctx, bucket, object, oldDataDir, onlineDisks); err != nil {
|
||||
return ObjectInfo{}, toObjectErr(err, bucket, object, uploadID)
|
||||
}
|
||||
|
||||
if !opts.Speedtest && len(versions) > 0 {
|
||||
globalMRFState.addPartialOp(partialOperation{
|
||||
bucket: bucket,
|
||||
object: object,
|
||||
queued: time.Now(),
|
||||
allVersions: true,
|
||||
setIndex: er.setIndex,
|
||||
poolIndex: er.poolIndex,
|
||||
bucket: bucket,
|
||||
object: object,
|
||||
queued: time.Now(),
|
||||
versions: versions,
|
||||
setIndex: er.setIndex,
|
||||
poolIndex: er.poolIndex,
|
||||
})
|
||||
}
|
||||
|
||||
if !opts.Speedtest && !versionsDisparity {
|
||||
if !opts.Speedtest && len(versions) == 0 {
|
||||
// Check if there is any offline disk and add it to the MRF list
|
||||
for _, disk := range onlineDisks {
|
||||
if disk != nil && disk.IsOnline() {
|
||||
|
||||
+286
-191
@@ -41,13 +41,13 @@ import (
|
||||
"github.com/minio/minio/internal/config/storageclass"
|
||||
"github.com/minio/minio/internal/crypto"
|
||||
"github.com/minio/minio/internal/event"
|
||||
"github.com/minio/minio/internal/grid"
|
||||
"github.com/minio/minio/internal/hash"
|
||||
xhttp "github.com/minio/minio/internal/http"
|
||||
xioutil "github.com/minio/minio/internal/ioutil"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/mimedb"
|
||||
"github.com/minio/pkg/v2/sync/errgroup"
|
||||
"github.com/minio/pkg/v2/wildcard"
|
||||
)
|
||||
|
||||
// list all errors which can be ignored in object operations.
|
||||
@@ -103,8 +103,12 @@ func (er erasureObjects) CopyObject(ctx context.Context, srcBucket, srcObject, d
|
||||
if err != nil {
|
||||
if errors.Is(err, errErasureReadQuorum) && !strings.HasPrefix(srcBucket, minioMetaBucket) {
|
||||
_, derr := er.deleteIfDangling(context.Background(), srcBucket, srcObject, metaArr, errs, nil, srcOpts)
|
||||
if derr != nil {
|
||||
err = derr
|
||||
if derr == nil {
|
||||
if srcOpts.VersionID != "" {
|
||||
err = errFileVersionNotFound
|
||||
} else {
|
||||
err = errFileNotFound
|
||||
}
|
||||
}
|
||||
}
|
||||
return ObjectInfo{}, toObjectErr(err, srcBucket, srcObject)
|
||||
@@ -146,11 +150,12 @@ func (er erasureObjects) CopyObject(ctx context.Context, srcBucket, srcObject, d
|
||||
modTime = dstOpts.MTime
|
||||
fi.ModTime = dstOpts.MTime
|
||||
}
|
||||
// check inline before overwriting metadata.
|
||||
inlineData := fi.InlineData()
|
||||
|
||||
fi.Metadata = srcInfo.UserDefined
|
||||
srcInfo.UserDefined["etag"] = srcInfo.ETag
|
||||
|
||||
inlineData := fi.InlineData()
|
||||
freeVersionID := fi.TierFreeVersionID()
|
||||
freeVersionMarker := fi.TierFreeVersion()
|
||||
|
||||
@@ -245,6 +250,23 @@ func (er erasureObjects) GetObjectNInfo(ctx context.Context, bucket, object stri
|
||||
}, toObjectErr(errMethodNotAllowed, bucket, object)
|
||||
}
|
||||
|
||||
// Set NoDecryption for SSE-C objects and if replication request
|
||||
if crypto.SSEC.IsEncrypted(objInfo.UserDefined) && opts.ReplicationRequest {
|
||||
opts.NoDecryption = true
|
||||
}
|
||||
|
||||
if objInfo.Size == 0 {
|
||||
if _, _, err := rs.GetOffsetLength(objInfo.Size); err != nil {
|
||||
// Make sure to return object info to provide extra information.
|
||||
return &GetObjectReader{
|
||||
ObjInfo: objInfo,
|
||||
}, err
|
||||
}
|
||||
|
||||
// Zero byte objects don't even need to further initialize pipes etc.
|
||||
return NewGetObjectReaderFromReader(bytes.NewReader(nil), objInfo, opts)
|
||||
}
|
||||
|
||||
if objInfo.IsRemote() {
|
||||
gr, err := getTransitionedObjectReader(ctx, bucket, object, rs, h, objInfo, opts)
|
||||
if err != nil {
|
||||
@@ -254,11 +276,6 @@ func (er erasureObjects) GetObjectNInfo(ctx context.Context, bucket, object stri
|
||||
return gr.WithCleanupFuncs(nsUnlocker), nil
|
||||
}
|
||||
|
||||
if objInfo.Size == 0 {
|
||||
// Zero byte objects don't even need to further initialize pipes etc.
|
||||
return NewGetObjectReaderFromReader(bytes.NewReader(nil), objInfo, opts)
|
||||
}
|
||||
|
||||
fn, off, length, err := NewGetObjectReader(rs, objInfo, opts)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
@@ -472,91 +489,88 @@ func joinErrs(errs []error) []string {
|
||||
}
|
||||
|
||||
func (er erasureObjects) deleteIfDangling(ctx context.Context, bucket, object string, metaArr []FileInfo, errs []error, dataErrs []error, opts ObjectOptions) (FileInfo, error) {
|
||||
var err error
|
||||
m, ok := isObjectDangling(metaArr, errs, dataErrs)
|
||||
if ok {
|
||||
tags := make(map[string]interface{}, 4)
|
||||
tags["set"] = er.setIndex
|
||||
tags["pool"] = er.poolIndex
|
||||
tags["merrs"] = joinErrs(errs)
|
||||
tags["derrs"] = joinErrs(dataErrs)
|
||||
if m.IsValid() {
|
||||
tags["size"] = m.Size
|
||||
tags["mtime"] = m.ModTime.Format(http.TimeFormat)
|
||||
tags["data"] = m.Erasure.DataBlocks
|
||||
tags["parity"] = m.Erasure.ParityBlocks
|
||||
} else {
|
||||
tags["invalid-meta"] = true
|
||||
tags["data"] = er.setDriveCount - er.defaultParityCount
|
||||
tags["parity"] = er.defaultParityCount
|
||||
}
|
||||
|
||||
// count the number of offline disks
|
||||
offline := 0
|
||||
for i := 0; i < max(len(errs), len(dataErrs)); i++ {
|
||||
if i < len(errs) && errors.Is(errs[i], errDiskNotFound) || i < len(dataErrs) && errors.Is(dataErrs[i], errDiskNotFound) {
|
||||
offline++
|
||||
}
|
||||
}
|
||||
if offline > 0 {
|
||||
tags["offline"] = offline
|
||||
}
|
||||
|
||||
_, file, line, cok := runtime.Caller(1)
|
||||
if cok {
|
||||
tags["caller"] = fmt.Sprintf("%s:%d", file, line)
|
||||
}
|
||||
|
||||
defer auditDanglingObjectDeletion(ctx, bucket, object, m.VersionID, tags)
|
||||
|
||||
err = errFileNotFound
|
||||
if opts.VersionID != "" {
|
||||
err = errFileVersionNotFound
|
||||
}
|
||||
|
||||
fi := FileInfo{
|
||||
VersionID: m.VersionID,
|
||||
}
|
||||
if opts.VersionID != "" {
|
||||
fi.VersionID = opts.VersionID
|
||||
}
|
||||
fi.SetTierFreeVersionID(mustGetUUID())
|
||||
disks := er.getDisks()
|
||||
g := errgroup.WithNErrs(len(disks))
|
||||
for index := range disks {
|
||||
index := index
|
||||
g.Go(func() error {
|
||||
if disks[index] == nil {
|
||||
return errDiskNotFound
|
||||
}
|
||||
return disks[index].DeleteVersion(ctx, bucket, object, fi, false, DeleteOptions{})
|
||||
}, index)
|
||||
}
|
||||
|
||||
rmDisks := make(map[string]string, len(disks))
|
||||
for index, err := range g.Wait() {
|
||||
var errStr, diskName string
|
||||
if err != nil {
|
||||
errStr = err.Error()
|
||||
} else {
|
||||
errStr = "<nil>"
|
||||
}
|
||||
if disks[index] != nil {
|
||||
diskName = disks[index].String()
|
||||
} else {
|
||||
diskName = fmt.Sprintf("disk-%d", index)
|
||||
}
|
||||
rmDisks[diskName] = errStr
|
||||
}
|
||||
tags["cleanupResult"] = rmDisks
|
||||
if !ok {
|
||||
// We only come here if we cannot figure out if the object
|
||||
// can be deleted safely, in such a scenario return ReadQuorum error.
|
||||
return FileInfo{}, errErasureReadQuorum
|
||||
}
|
||||
return m, err
|
||||
tags := make(map[string]interface{}, 4)
|
||||
tags["set"] = er.setIndex
|
||||
tags["pool"] = er.poolIndex
|
||||
tags["merrs"] = joinErrs(errs)
|
||||
tags["derrs"] = joinErrs(dataErrs)
|
||||
if m.IsValid() {
|
||||
tags["size"] = m.Size
|
||||
tags["mtime"] = m.ModTime.Format(http.TimeFormat)
|
||||
tags["data"] = m.Erasure.DataBlocks
|
||||
tags["parity"] = m.Erasure.ParityBlocks
|
||||
} else {
|
||||
tags["invalid-meta"] = true
|
||||
tags["data"] = er.setDriveCount - er.defaultParityCount
|
||||
tags["parity"] = er.defaultParityCount
|
||||
}
|
||||
|
||||
// count the number of offline disks
|
||||
offline := 0
|
||||
for i := 0; i < max(len(errs), len(dataErrs)); i++ {
|
||||
if i < len(errs) && errors.Is(errs[i], errDiskNotFound) || i < len(dataErrs) && errors.Is(dataErrs[i], errDiskNotFound) {
|
||||
offline++
|
||||
}
|
||||
}
|
||||
if offline > 0 {
|
||||
tags["offline"] = offline
|
||||
}
|
||||
|
||||
_, file, line, cok := runtime.Caller(1)
|
||||
if cok {
|
||||
tags["caller"] = fmt.Sprintf("%s:%d", file, line)
|
||||
}
|
||||
|
||||
defer auditDanglingObjectDeletion(ctx, bucket, object, m.VersionID, tags)
|
||||
|
||||
fi := FileInfo{
|
||||
VersionID: m.VersionID,
|
||||
}
|
||||
if opts.VersionID != "" {
|
||||
fi.VersionID = opts.VersionID
|
||||
}
|
||||
fi.SetTierFreeVersionID(mustGetUUID())
|
||||
disks := er.getDisks()
|
||||
g := errgroup.WithNErrs(len(disks))
|
||||
for index := range disks {
|
||||
index := index
|
||||
g.Go(func() error {
|
||||
if disks[index] == nil {
|
||||
return errDiskNotFound
|
||||
}
|
||||
return disks[index].DeleteVersion(ctx, bucket, object, fi, false, DeleteOptions{})
|
||||
}, index)
|
||||
}
|
||||
|
||||
rmDisks := make(map[string]string, len(disks))
|
||||
for index, err := range g.Wait() {
|
||||
var errStr, diskName string
|
||||
if err != nil {
|
||||
errStr = err.Error()
|
||||
} else {
|
||||
errStr = "<nil>"
|
||||
}
|
||||
if disks[index] != nil {
|
||||
diskName = disks[index].String()
|
||||
} else {
|
||||
diskName = fmt.Sprintf("disk-%d", index)
|
||||
}
|
||||
rmDisks[diskName] = errStr
|
||||
}
|
||||
tags["cleanupResult"] = rmDisks
|
||||
return m, nil
|
||||
}
|
||||
|
||||
func fileInfoFromRaw(ri RawFileInfo, bucket, object string, readData, inclFreeVers, allParts bool) (FileInfo, error) {
|
||||
var xl xlMetaV2
|
||||
if err := xl.LoadOrConvert(ri.Buf); err != nil {
|
||||
return FileInfo{}, err
|
||||
return FileInfo{}, errFileCorrupt
|
||||
}
|
||||
|
||||
fi, err := xl.ToFileInfo(bucket, object, "", inclFreeVers, allParts)
|
||||
@@ -565,7 +579,7 @@ func fileInfoFromRaw(ri RawFileInfo, bucket, object string, readData, inclFreeVe
|
||||
}
|
||||
|
||||
if !fi.IsValid() {
|
||||
return FileInfo{}, errCorruptedFormat
|
||||
return FileInfo{}, errFileCorrupt
|
||||
}
|
||||
|
||||
versionID := fi.VersionID
|
||||
@@ -655,7 +669,7 @@ func pickLatestQuorumFilesInfo(ctx context.Context, rawFileInfos []RawFileInfo,
|
||||
if !lfi.IsValid() {
|
||||
for i := range errs {
|
||||
if errs[i] == nil {
|
||||
errs[i] = errCorruptedFormat
|
||||
errs[i] = errFileCorrupt
|
||||
}
|
||||
}
|
||||
return metaFileInfos, errs
|
||||
@@ -912,8 +926,12 @@ func (er erasureObjects) getObjectFileInfo(ctx context.Context, bucket, object s
|
||||
// not we simply ignore it, since we can't tell for sure if its dangling object.
|
||||
if totalResp == er.setDriveCount && shouldCheckForDangling(err, errs, bucket) {
|
||||
_, derr := er.deleteIfDangling(context.Background(), bucket, object, metaArr, errs, nil, opts)
|
||||
if derr != nil {
|
||||
err = derr
|
||||
if derr == nil {
|
||||
if opts.VersionID != "" {
|
||||
err = errFileVersionNotFound
|
||||
} else {
|
||||
err = errFileNotFound
|
||||
}
|
||||
}
|
||||
}
|
||||
return fi, nil, nil, toObjectErr(err, bucket, object)
|
||||
@@ -922,7 +940,7 @@ func (er erasureObjects) getObjectFileInfo(ctx context.Context, bucket, object s
|
||||
if !fi.Deleted && len(fi.Erasure.Distribution) != len(onlineDisks) {
|
||||
err := fmt.Errorf("unexpected file distribution (%v) from online disks (%v), looks like backend disks have been manually modified refusing to heal %s/%s(%s)",
|
||||
fi.Erasure.Distribution, onlineDisks, bucket, object, opts.VersionID)
|
||||
logger.LogOnceIf(ctx, err, "get-object-file-info-manually-modified")
|
||||
storageLogOnceIf(ctx, err, "get-object-file-info-manually-modified")
|
||||
return fi, nil, nil, toObjectErr(err, bucket, object, opts.VersionID)
|
||||
}
|
||||
|
||||
@@ -999,7 +1017,7 @@ func (er erasureObjects) getObjectInfoAndQuorum(ctx context.Context, bucket, obj
|
||||
}
|
||||
|
||||
// Similar to rename but renames data from srcEntry to dstEntry at dataDir
|
||||
func renameData(ctx context.Context, disks []StorageAPI, srcBucket, srcEntry string, metadata []FileInfo, dstBucket, dstEntry string, writeQuorum int) ([]StorageAPI, bool, error) {
|
||||
func renameData(ctx context.Context, disks []StorageAPI, srcBucket, srcEntry string, metadata []FileInfo, dstBucket, dstEntry string, writeQuorum int) ([]StorageAPI, []byte, string, error) {
|
||||
g := errgroup.WithNErrs(len(disks))
|
||||
|
||||
fvID := mustGetUUID()
|
||||
@@ -1007,7 +1025,8 @@ func renameData(ctx context.Context, disks []StorageAPI, srcBucket, srcEntry str
|
||||
metadata[index].SetTierFreeVersionID(fvID)
|
||||
}
|
||||
|
||||
diskVersions := make([]uint64, len(disks))
|
||||
diskVersions := make([][]byte, len(disks))
|
||||
dataDirs := make([]string, len(disks))
|
||||
// Rename file on all underlying storage disks.
|
||||
for index := range disks {
|
||||
index := index
|
||||
@@ -1026,11 +1045,12 @@ func renameData(ctx context.Context, disks []StorageAPI, srcBucket, srcEntry str
|
||||
if !fi.IsValid() {
|
||||
return errFileCorrupt
|
||||
}
|
||||
sign, err := disks[index].RenameData(ctx, srcBucket, srcEntry, fi, dstBucket, dstEntry, RenameOptions{})
|
||||
resp, err := disks[index].RenameData(ctx, srcBucket, srcEntry, fi, dstBucket, dstEntry, RenameOptions{})
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
diskVersions[index] = sign
|
||||
diskVersions[index] = resp.Sign
|
||||
dataDirs[index] = resp.OldDataDir
|
||||
return nil
|
||||
}, index)
|
||||
}
|
||||
@@ -1038,8 +1058,6 @@ func renameData(ctx context.Context, disks []StorageAPI, srcBucket, srcEntry str
|
||||
// Wait for all renames to finish.
|
||||
errs := g.Wait()
|
||||
|
||||
var versionsDisparity bool
|
||||
|
||||
err := reduceWriteQuorumErrs(ctx, errs, objectOpIgnoredErrs, writeQuorum)
|
||||
if err != nil {
|
||||
dg := errgroup.WithNErrs(len(disks))
|
||||
@@ -1053,27 +1071,35 @@ func renameData(ctx context.Context, disks []StorageAPI, srcBucket, srcEntry str
|
||||
// caller this dangling object will be now scheduled to be removed
|
||||
// via active healing.
|
||||
dg.Go(func() error {
|
||||
return disks[index].DeleteVersion(context.Background(), dstBucket, dstEntry, metadata[index], false, DeleteOptions{UndoWrite: true})
|
||||
return disks[index].DeleteVersion(context.Background(), dstBucket, dstEntry, metadata[index], false, DeleteOptions{
|
||||
UndoWrite: true,
|
||||
OldDataDir: dataDirs[index],
|
||||
})
|
||||
}, index)
|
||||
}
|
||||
dg.Wait()
|
||||
}
|
||||
var dataDir string
|
||||
var versions []byte
|
||||
if err == nil {
|
||||
versions := reduceCommonVersions(diskVersions, writeQuorum)
|
||||
versions = reduceCommonVersions(diskVersions, writeQuorum)
|
||||
for index, dversions := range diskVersions {
|
||||
if errs[index] != nil {
|
||||
continue
|
||||
}
|
||||
if versions != dversions {
|
||||
versionsDisparity = true
|
||||
if !bytes.Equal(dversions, versions) {
|
||||
if len(dversions) > len(versions) {
|
||||
versions = dversions
|
||||
}
|
||||
break
|
||||
}
|
||||
}
|
||||
dataDir = reduceCommonDataDir(dataDirs, writeQuorum)
|
||||
}
|
||||
|
||||
// We can safely allow RenameData errors up to len(er.getDisks()) - writeQuorum
|
||||
// otherwise return failure.
|
||||
return evalDisks(disks, errs), versionsDisparity, err
|
||||
return evalDisks(disks, errs), versions, dataDir, err
|
||||
}
|
||||
|
||||
func (er erasureObjects) putMetacacheObject(ctx context.Context, key string, r *PutObjReader, opts ObjectOptions) (objInfo ObjectInfo, err error) {
|
||||
@@ -1101,7 +1127,7 @@ func (er erasureObjects) putMetacacheObject(ctx context.Context, key string, r *
|
||||
|
||||
// Validate input data size and it can never be less than zero.
|
||||
if data.Size() < -1 {
|
||||
logger.LogIf(ctx, errInvalidArgument, logger.ErrorKind)
|
||||
bugLogIf(ctx, errInvalidArgument, logger.ErrorKind)
|
||||
return ObjectInfo{}, toObjectErr(errInvalidArgument)
|
||||
}
|
||||
|
||||
@@ -1131,8 +1157,8 @@ func (er erasureObjects) putMetacacheObject(ctx context.Context, key string, r *
|
||||
case size == 0:
|
||||
buffer = make([]byte, 1) // Allocate at least a byte to reach EOF
|
||||
case size >= fi.Erasure.BlockSize:
|
||||
buffer = globalBytePoolCap.Get()
|
||||
defer globalBytePoolCap.Put(buffer)
|
||||
buffer = globalBytePoolCap.Load().Get()
|
||||
defer globalBytePoolCap.Load().Put(buffer)
|
||||
case size < fi.Erasure.BlockSize:
|
||||
// No need to allocate fully blockSizeV1 buffer if the incoming data is smaller.
|
||||
buffer = make([]byte, size, 2*size+int64(fi.Erasure.ParityBlocks+fi.Erasure.DataBlocks-1))
|
||||
@@ -1142,7 +1168,6 @@ func (er erasureObjects) putMetacacheObject(ctx context.Context, key string, r *
|
||||
buffer = buffer[:fi.Erasure.BlockSize]
|
||||
}
|
||||
|
||||
shardFileSize := erasure.ShardFileSize(data.Size())
|
||||
writers := make([]io.Writer, len(onlineDisks))
|
||||
inlineBuffers := make([]*bytes.Buffer, len(onlineDisks))
|
||||
for i, disk := range onlineDisks {
|
||||
@@ -1150,7 +1175,9 @@ func (er erasureObjects) putMetacacheObject(ctx context.Context, key string, r *
|
||||
continue
|
||||
}
|
||||
if disk.IsOnline() {
|
||||
inlineBuffers[i] = bytes.NewBuffer(make([]byte, 0, shardFileSize))
|
||||
buf := grid.GetByteBufferCap(int(erasure.ShardFileSize(data.Size())) + 64)
|
||||
inlineBuffers[i] = bytes.NewBuffer(buf[:0])
|
||||
defer grid.PutByteBuffer(buf)
|
||||
writers[i] = newStreamingBitrotWriterBuffer(inlineBuffers[i], DefaultBitrotAlgorithm, erasure.ShardSize())
|
||||
}
|
||||
}
|
||||
@@ -1221,44 +1248,6 @@ func (er erasureObjects) PutObject(ctx context.Context, bucket string, object st
|
||||
return er.putObject(ctx, bucket, object, data, opts)
|
||||
}
|
||||
|
||||
// Heal up to two versions of one object when there is disparity between disks
|
||||
func healObjectVersionsDisparity(bucket string, entry metaCacheEntry, scanMode madmin.HealScanMode) error {
|
||||
if entry.isDir() {
|
||||
return nil
|
||||
}
|
||||
// We might land at .metacache, .trash, .multipart
|
||||
// no need to heal them skip, only when bucket
|
||||
// is '.minio.sys'
|
||||
if bucket == minioMetaBucket {
|
||||
if wildcard.Match("buckets/*/.metacache/*", entry.name) {
|
||||
return nil
|
||||
}
|
||||
if wildcard.Match("tmp/*", entry.name) {
|
||||
return nil
|
||||
}
|
||||
if wildcard.Match("multipart/*", entry.name) {
|
||||
return nil
|
||||
}
|
||||
if wildcard.Match("tmp-old/*", entry.name) {
|
||||
return nil
|
||||
}
|
||||
}
|
||||
|
||||
fivs, err := entry.fileInfoVersions(bucket)
|
||||
if err != nil {
|
||||
healObject(bucket, entry.name, "", madmin.HealDeepScan)
|
||||
return err
|
||||
}
|
||||
|
||||
if len(fivs.Versions) <= 2 {
|
||||
for _, version := range fivs.Versions {
|
||||
healObject(bucket, entry.name, version.VersionID, scanMode)
|
||||
}
|
||||
}
|
||||
|
||||
return nil
|
||||
}
|
||||
|
||||
// putObject wrapper for erasureObjects PutObject
|
||||
func (er erasureObjects) putObject(ctx context.Context, bucket string, object string, r *PutObjReader, opts ObjectOptions) (objInfo ObjectInfo, err error) {
|
||||
if !opts.NoAuditLog {
|
||||
@@ -1290,7 +1279,7 @@ func (er erasureObjects) putObject(ctx context.Context, bucket string, object st
|
||||
|
||||
// Validate input data size and it can never be less than -1.
|
||||
if data.Size() < -1 {
|
||||
logger.LogIf(ctx, errInvalidArgument, logger.ErrorKind)
|
||||
bugLogIf(ctx, errInvalidArgument, logger.ErrorKind)
|
||||
return ObjectInfo{}, toObjectErr(errInvalidArgument)
|
||||
}
|
||||
|
||||
@@ -1380,8 +1369,8 @@ func (er erasureObjects) putObject(ctx context.Context, bucket string, object st
|
||||
case size == 0:
|
||||
buffer = make([]byte, 1) // Allocate at least a byte to reach EOF
|
||||
case size >= fi.Erasure.BlockSize || size == -1:
|
||||
buffer = globalBytePoolCap.Get()
|
||||
defer globalBytePoolCap.Put(buffer)
|
||||
buffer = globalBytePoolCap.Load().Get()
|
||||
defer globalBytePoolCap.Load().Put(buffer)
|
||||
case size < fi.Erasure.BlockSize:
|
||||
// No need to allocate fully blockSizeV1 buffer if the incoming data is smaller.
|
||||
buffer = make([]byte, size, 2*size+int64(fi.Erasure.ParityBlocks+fi.Erasure.DataBlocks-1))
|
||||
@@ -1430,11 +1419,9 @@ func (er erasureObjects) putObject(ctx context.Context, bucket string, object st
|
||||
}
|
||||
|
||||
if len(inlineBuffers) > 0 {
|
||||
sz := shardFileSize
|
||||
if sz < 0 {
|
||||
sz = data.ActualSize()
|
||||
}
|
||||
inlineBuffers[i] = bytes.NewBuffer(make([]byte, 0, sz))
|
||||
buf := grid.GetByteBufferCap(int(shardFileSize) + 64)
|
||||
inlineBuffers[i] = bytes.NewBuffer(buf[:0])
|
||||
defer grid.PutByteBuffer(buf)
|
||||
writers[i] = newStreamingBitrotWriterBuffer(inlineBuffers[i], DefaultBitrotAlgorithm, erasure.ShardSize())
|
||||
continue
|
||||
}
|
||||
@@ -1443,18 +1430,19 @@ func (er erasureObjects) putObject(ctx context.Context, bucket string, object st
|
||||
}
|
||||
|
||||
toEncode := io.Reader(data)
|
||||
if data.Size() > bigFileThreshold {
|
||||
if data.Size() >= bigFileThreshold {
|
||||
// We use 2 buffers, so we always have a full buffer of input.
|
||||
bufA := globalBytePoolCap.Get()
|
||||
bufB := globalBytePoolCap.Get()
|
||||
defer globalBytePoolCap.Put(bufA)
|
||||
defer globalBytePoolCap.Put(bufB)
|
||||
pool := globalBytePoolCap.Load()
|
||||
bufA := pool.Get()
|
||||
bufB := pool.Get()
|
||||
defer pool.Put(bufA)
|
||||
defer pool.Put(bufB)
|
||||
ra, err := readahead.NewReaderBuffer(data, [][]byte{bufA[:fi.Erasure.BlockSize], bufB[:fi.Erasure.BlockSize]})
|
||||
if err == nil {
|
||||
toEncode = ra
|
||||
defer ra.Close()
|
||||
}
|
||||
logger.LogIf(ctx, err)
|
||||
bugLogIf(ctx, err)
|
||||
}
|
||||
n, erasureErr := erasure.Encode(ctx, toEncode, writers, buffer, writeQuorum)
|
||||
closeBitrotWriters(writers)
|
||||
@@ -1540,14 +1528,23 @@ func (er erasureObjects) putObject(ctx context.Context, bucket string, object st
|
||||
}
|
||||
|
||||
// Rename the successfully written temporary object to final location.
|
||||
onlineDisks, versionsDisparity, err := renameData(ctx, onlineDisks, minioMetaTmpBucket, tempObj, partsMetadata, bucket, object, writeQuorum)
|
||||
onlineDisks, versions, oldDataDir, err := renameData(ctx, onlineDisks, minioMetaTmpBucket, tempObj, partsMetadata, bucket, object, writeQuorum)
|
||||
if err != nil {
|
||||
if errors.Is(err, errFileNotFound) {
|
||||
return ObjectInfo{}, toObjectErr(errErasureWriteQuorum, bucket, object)
|
||||
// An in-quorum errFileNotFound means that client stream
|
||||
// prematurely closed and we do not find any xl.meta or
|
||||
// part.1's - in such a scenario we must return as if client
|
||||
// disconnected. This means that erasure.Encode() CreateFile()
|
||||
// did not do anything.
|
||||
return ObjectInfo{}, IncompleteBody{Bucket: bucket, Object: object}
|
||||
}
|
||||
return ObjectInfo{}, toObjectErr(err, bucket, object)
|
||||
}
|
||||
|
||||
if err = er.commitRenameDataDir(ctx, bucket, object, oldDataDir, onlineDisks); err != nil {
|
||||
return ObjectInfo{}, toObjectErr(err, bucket, object)
|
||||
}
|
||||
|
||||
for i := 0; i < len(onlineDisks); i++ {
|
||||
if onlineDisks[i] != nil && onlineDisks[i].IsOnline() {
|
||||
// Object info is the same in all disks, so we can pick
|
||||
@@ -1562,7 +1559,7 @@ func (er erasureObjects) putObject(ctx context.Context, bucket string, object st
|
||||
// When there is versions disparity we are healing
|
||||
// the content implicitly for all versions, we can
|
||||
// avoid triggering another MRF heal for offline drives.
|
||||
if !versionsDisparity {
|
||||
if len(versions) == 0 {
|
||||
// Whether a disk was initially or becomes offline
|
||||
// during this upload, send it to the MRF list.
|
||||
for i := 0; i < len(onlineDisks); i++ {
|
||||
@@ -1575,12 +1572,12 @@ func (er erasureObjects) putObject(ctx context.Context, bucket string, object st
|
||||
}
|
||||
} else {
|
||||
globalMRFState.addPartialOp(partialOperation{
|
||||
bucket: bucket,
|
||||
object: object,
|
||||
queued: time.Now(),
|
||||
allVersions: true,
|
||||
setIndex: er.setIndex,
|
||||
poolIndex: er.poolIndex,
|
||||
bucket: bucket,
|
||||
object: object,
|
||||
queued: time.Now(),
|
||||
versions: versions,
|
||||
setIndex: er.setIndex,
|
||||
poolIndex: er.poolIndex,
|
||||
})
|
||||
}
|
||||
}
|
||||
@@ -1790,8 +1787,40 @@ func (er erasureObjects) DeleteObjects(ctx context.Context, bucket string, objec
|
||||
return dobjects, errs
|
||||
}
|
||||
|
||||
func (er erasureObjects) commitRenameDataDir(ctx context.Context, bucket, object, dataDir string, onlineDisks []StorageAPI) error {
|
||||
if dataDir == "" {
|
||||
return nil
|
||||
}
|
||||
g := errgroup.WithNErrs(len(onlineDisks))
|
||||
for index := range onlineDisks {
|
||||
index := index
|
||||
g.Go(func() error {
|
||||
if onlineDisks[index] == nil {
|
||||
return nil
|
||||
}
|
||||
return onlineDisks[index].Delete(ctx, bucket, pathJoin(object, dataDir), DeleteOptions{
|
||||
Recursive: true,
|
||||
})
|
||||
}, index)
|
||||
}
|
||||
for _, err := range g.Wait() {
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
func (er erasureObjects) deletePrefix(ctx context.Context, bucket, prefix string) error {
|
||||
disks := er.getDisks()
|
||||
// Assume (N/2 + 1) quorum for Delete()
|
||||
// this is a theoretical assumption such that
|
||||
// for delete's we do not need to honor storage
|
||||
// class for objects that have reduced quorum
|
||||
// due to storage class - this only needs to be honored
|
||||
// for Read() requests alone that we already do.
|
||||
writeQuorum := len(disks)/2 + 1
|
||||
|
||||
g := errgroup.WithNErrs(len(disks))
|
||||
for index := range disks {
|
||||
index := index
|
||||
@@ -1805,12 +1834,9 @@ func (er erasureObjects) deletePrefix(ctx context.Context, bucket, prefix string
|
||||
})
|
||||
}, index)
|
||||
}
|
||||
for _, err := range g.Wait() {
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
return nil
|
||||
|
||||
// return errors if any during deletion
|
||||
return reduceWriteQuorumErrs(ctx, g.Wait(), objectOpIgnoredErrs, writeQuorum)
|
||||
}
|
||||
|
||||
// DeleteObject - deletes an object, this call doesn't necessary reply
|
||||
@@ -1821,18 +1847,23 @@ func (er erasureObjects) DeleteObject(ctx context.Context, bucket, object string
|
||||
auditObjectErasureSet(ctx, object, &er)
|
||||
}
|
||||
|
||||
if opts.DeletePrefix {
|
||||
return ObjectInfo{}, toObjectErr(er.deletePrefix(ctx, bucket, object), bucket, object)
|
||||
}
|
||||
|
||||
var lc *lifecycle.Lifecycle
|
||||
var rcfg lock.Retention
|
||||
var replcfg *replication.Config
|
||||
if opts.Expiration.Expire {
|
||||
// Check if the current bucket has a configured lifecycle policy
|
||||
lc, _ = globalLifecycleSys.Get(bucket)
|
||||
rcfg, _ = globalBucketObjectLockSys.Get(bucket)
|
||||
replcfg, _ = getReplicationConfig(ctx, bucket)
|
||||
lc, err = globalLifecycleSys.Get(bucket)
|
||||
if err != nil && !errors.Is(err, BucketLifecycleNotFound{Bucket: bucket}) {
|
||||
return objInfo, err
|
||||
}
|
||||
rcfg, err = globalBucketObjectLockSys.Get(bucket)
|
||||
if err != nil {
|
||||
return objInfo, err
|
||||
}
|
||||
replcfg, err = getReplicationConfig(ctx, bucket)
|
||||
if err != nil {
|
||||
return objInfo, err
|
||||
}
|
||||
}
|
||||
|
||||
// expiration attempted on a bucket with no lifecycle
|
||||
@@ -1851,23 +1882,79 @@ func (er erasureObjects) DeleteObject(ctx context.Context, bucket, object string
|
||||
}
|
||||
}
|
||||
|
||||
if opts.DeletePrefix {
|
||||
if opts.Expiration.Expire {
|
||||
// Expire all versions expiration must still verify the state() on disk
|
||||
// via a getObjectInfo() call as follows, any read quorum issues we
|
||||
// must not proceed further for safety reasons. attempt a MRF heal
|
||||
// while we see such quorum errors.
|
||||
goi, _, gerr := er.getObjectInfoAndQuorum(ctx, bucket, object, opts)
|
||||
if gerr != nil && goi.Name == "" {
|
||||
if _, ok := gerr.(InsufficientReadQuorum); ok {
|
||||
// Add an MRF heal for next time.
|
||||
er.addPartial(bucket, object, opts.VersionID)
|
||||
|
||||
return objInfo, InsufficientWriteQuorum{}
|
||||
}
|
||||
return objInfo, gerr
|
||||
}
|
||||
|
||||
// Add protection and re-verify the ILM rules for qualification
|
||||
// based on the latest objectInfo and see if the object still
|
||||
// qualifies for deletion.
|
||||
if gerr == nil {
|
||||
var isErr bool
|
||||
evt := evalActionFromLifecycle(ctx, *lc, rcfg, replcfg, goi)
|
||||
switch evt.Action {
|
||||
case lifecycle.DeleteAllVersionsAction, lifecycle.DelMarkerDeleteAllVersionsAction:
|
||||
// opts.DeletePrefix is used only in the above lifecycle Expiration actions.
|
||||
default:
|
||||
// object has been modified since lifecycle action was previously evaluated
|
||||
isErr = true
|
||||
}
|
||||
if isErr {
|
||||
if goi.VersionID != "" {
|
||||
return goi, VersionNotFound{
|
||||
Bucket: bucket,
|
||||
Object: object,
|
||||
VersionID: goi.VersionID,
|
||||
}
|
||||
}
|
||||
return goi, ObjectNotFound{
|
||||
Bucket: bucket,
|
||||
Object: object,
|
||||
}
|
||||
}
|
||||
}
|
||||
} // Delete marker and any latest that qualifies shall be expired permanently.
|
||||
|
||||
return ObjectInfo{}, toObjectErr(er.deletePrefix(ctx, bucket, object), bucket, object)
|
||||
}
|
||||
|
||||
storageDisks := er.getDisks()
|
||||
versionFound := true
|
||||
objInfo = ObjectInfo{VersionID: opts.VersionID} // version id needed in Delete API response.
|
||||
goi, _, gerr := er.getObjectInfoAndQuorum(ctx, bucket, object, opts)
|
||||
tryDel := false
|
||||
if gerr != nil && goi.Name == "" {
|
||||
if _, ok := gerr.(InsufficientReadQuorum); ok {
|
||||
return objInfo, InsufficientWriteQuorum{}
|
||||
if opts.Versioned || opts.VersionSuspended || countOnlineDisks(storageDisks) < len(storageDisks)/2+1 {
|
||||
// Add an MRF heal for next time.
|
||||
er.addPartial(bucket, object, opts.VersionID)
|
||||
return objInfo, InsufficientWriteQuorum{}
|
||||
}
|
||||
tryDel = true // only for unversioned objects if there is write quorum
|
||||
}
|
||||
// For delete marker replication, versionID being replicated will not exist on disk
|
||||
if opts.DeleteMarker {
|
||||
versionFound = false
|
||||
} else {
|
||||
} else if !tryDel {
|
||||
return objInfo, gerr
|
||||
}
|
||||
}
|
||||
|
||||
if opts.EvalMetadataFn != nil {
|
||||
dsc, err := opts.EvalMetadataFn(&goi, err)
|
||||
dsc, err := opts.EvalMetadataFn(&goi, gerr)
|
||||
if err != nil {
|
||||
return ObjectInfo{}, err
|
||||
}
|
||||
@@ -2059,8 +2146,12 @@ func (er erasureObjects) PutObjectMetadata(ctx context.Context, bucket, object s
|
||||
if err != nil {
|
||||
if errors.Is(err, errErasureReadQuorum) && !strings.HasPrefix(bucket, minioMetaBucket) {
|
||||
_, derr := er.deleteIfDangling(context.Background(), bucket, object, metaArr, errs, nil, opts)
|
||||
if derr != nil {
|
||||
err = derr
|
||||
if derr == nil {
|
||||
if opts.VersionID != "" {
|
||||
err = errFileVersionNotFound
|
||||
} else {
|
||||
err = errFileNotFound
|
||||
}
|
||||
}
|
||||
}
|
||||
return ObjectInfo{}, toObjectErr(err, bucket, object)
|
||||
@@ -2132,8 +2223,12 @@ func (er erasureObjects) PutObjectTags(ctx context.Context, bucket, object strin
|
||||
if err != nil {
|
||||
if errors.Is(err, errErasureReadQuorum) && !strings.HasPrefix(bucket, minioMetaBucket) {
|
||||
_, derr := er.deleteIfDangling(context.Background(), bucket, object, metaArr, errs, nil, opts)
|
||||
if derr != nil {
|
||||
err = derr
|
||||
if derr == nil {
|
||||
if opts.VersionID != "" {
|
||||
err = errFileVersionNotFound
|
||||
} else {
|
||||
err = errFileNotFound
|
||||
}
|
||||
}
|
||||
}
|
||||
return ObjectInfo{}, toObjectErr(err, bucket, object)
|
||||
@@ -2216,7 +2311,7 @@ func (er erasureObjects) GetObjectTags(ctx context.Context, bucket, object strin
|
||||
|
||||
// TransitionObject - transition object content to target tier.
|
||||
func (er erasureObjects) TransitionObject(ctx context.Context, bucket, object string, opts ObjectOptions) error {
|
||||
tgtClient, err := globalTierConfigMgr.getDriver(opts.Transition.Tier)
|
||||
tgtClient, err := globalTierConfigMgr.getDriver(ctx, opts.Transition.Tier)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
@@ -2336,7 +2431,7 @@ func (er erasureObjects) updateRestoreMetadata(ctx context.Context, bucket, obje
|
||||
}, ObjectOptions{
|
||||
VersionID: oi.VersionID,
|
||||
}); err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to update transition restore metadata for %s/%s(%s): %s", bucket, object, oi.VersionID, err))
|
||||
storageLogIf(ctx, fmt.Errorf("Unable to update transition restore metadata for %s/%s(%s): %s", bucket, object, oi.VersionID, err))
|
||||
return err
|
||||
}
|
||||
return nil
|
||||
|
||||
@@ -31,6 +31,10 @@ import (
|
||||
|
||||
"github.com/dustin/go-humanize"
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio/internal/bucket/lifecycle"
|
||||
objectlock "github.com/minio/minio/internal/bucket/object/lock"
|
||||
"github.com/minio/minio/internal/bucket/replication"
|
||||
"github.com/minio/minio/internal/bucket/versioning"
|
||||
"github.com/minio/minio/internal/hash"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/console"
|
||||
@@ -467,7 +471,7 @@ func (p poolMeta) save(ctx context.Context, pools []*erasureSets) error {
|
||||
for i, eset := range pools {
|
||||
if err = saveConfig(ctx, eset, poolMetaName, buf); err != nil {
|
||||
if !errors.Is(err, context.Canceled) {
|
||||
logger.LogIf(ctx, fmt.Errorf("saving pool.bin for pool index %d failed with: %v", i, err))
|
||||
storageLogIf(ctx, fmt.Errorf("saving pool.bin for pool index %d failed with: %v", i, err))
|
||||
}
|
||||
return err
|
||||
}
|
||||
@@ -531,6 +535,10 @@ func (z *erasureServerPools) Init(ctx context.Context) error {
|
||||
|
||||
if len(poolIndices) > 0 && globalEndpoints[poolIndices[0]].Endpoints[0].IsLocal {
|
||||
go func() {
|
||||
// Resume decommissioning of pools, but wait 3 minutes for cluster to stabilize.
|
||||
if err := sleepContext(ctx, 3*time.Minute); err != nil {
|
||||
return
|
||||
}
|
||||
r := rand.New(rand.NewSource(time.Now().UnixNano()))
|
||||
for {
|
||||
if err := z.Decommission(ctx, poolIndices...); err != nil {
|
||||
@@ -542,11 +550,11 @@ func (z *erasureServerPools) Init(ctx context.Context) error {
|
||||
return
|
||||
}
|
||||
if configRetriableErrors(err) {
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to resume decommission of pools %v: %w: retrying..", pools, err))
|
||||
decomLogIf(ctx, fmt.Errorf("Unable to resume decommission of pools %v: %w: retrying..", pools, err))
|
||||
time.Sleep(time.Second + time.Duration(r.Float64()*float64(5*time.Second)))
|
||||
continue
|
||||
}
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to resume decommission of pool %v: %w", pools, err))
|
||||
decomLogIf(ctx, fmt.Errorf("Unable to resume decommission of pool %v: %w", pools, err))
|
||||
return
|
||||
}
|
||||
}
|
||||
@@ -741,7 +749,7 @@ func (z *erasureServerPools) decommissionPool(ctx context.Context, idx int, pool
|
||||
const envDecomWorkers = "_MINIO_DECOMMISSION_WORKERS"
|
||||
workerSize, err := env.GetInt(envDecomWorkers, len(pool.sets))
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("invalid workers value err: %v, defaulting to %d", err, len(pool.sets)))
|
||||
decomLogIf(ctx, fmt.Errorf("invalid workers value err: %v, defaulting to %d", err, len(pool.sets)))
|
||||
workerSize = len(pool.sets)
|
||||
}
|
||||
|
||||
@@ -754,14 +762,33 @@ func (z *erasureServerPools) decommissionPool(ctx context.Context, idx int, pool
|
||||
return err
|
||||
}
|
||||
|
||||
vc, _ := globalBucketVersioningSys.Get(bi.Name)
|
||||
var vc *versioning.Versioning
|
||||
var lc *lifecycle.Lifecycle
|
||||
var lr objectlock.Retention
|
||||
var rcfg *replication.Config
|
||||
if bi.Name != minioMetaBucket {
|
||||
vc, err = globalBucketVersioningSys.Get(bi.Name)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
// Check if the current bucket has a configured lifecycle policy
|
||||
lc, _ := globalLifecycleSys.Get(bi.Name)
|
||||
// Check if the current bucket has a configured lifecycle policy
|
||||
lc, err = globalLifecycleSys.Get(bi.Name)
|
||||
if err != nil && !errors.Is(err, BucketLifecycleNotFound{Bucket: bi.Name}) {
|
||||
return err
|
||||
}
|
||||
|
||||
// Check if bucket is object locked.
|
||||
lr, _ := globalBucketObjectLockSys.Get(bi.Name)
|
||||
rcfg, _ := getReplicationConfig(ctx, bi.Name)
|
||||
// Check if bucket is object locked.
|
||||
lr, err = globalBucketObjectLockSys.Get(bi.Name)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
rcfg, err = getReplicationConfig(ctx, bi.Name)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
|
||||
for setIdx, set := range pool.sets {
|
||||
set := set
|
||||
@@ -852,7 +879,7 @@ func (z *erasureServerPools) decommissionPool(ctx context.Context, idx int, pool
|
||||
}
|
||||
stopFn(err)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
decomLogIf(ctx, err)
|
||||
failure = true
|
||||
}
|
||||
z.poolMetaMutex.Lock()
|
||||
@@ -877,7 +904,7 @@ func (z *erasureServerPools) decommissionPool(ctx context.Context, idx int, pool
|
||||
}); err != nil {
|
||||
stopFn(err)
|
||||
failure = true
|
||||
logger.LogIf(ctx, err)
|
||||
decomLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
stopFn(nil)
|
||||
@@ -906,20 +933,20 @@ func (z *erasureServerPools) decommissionPool(ctx context.Context, idx int, pool
|
||||
if bi.Name == minioMetaBucket && strings.Contains(version.Name, dataUsageCacheName) {
|
||||
ignore = true
|
||||
stopFn(err)
|
||||
logger.LogIf(ctx, err)
|
||||
decomLogIf(ctx, err)
|
||||
break
|
||||
}
|
||||
}
|
||||
if err != nil {
|
||||
failure = true
|
||||
logger.LogIf(ctx, err)
|
||||
decomLogIf(ctx, err)
|
||||
stopFn(err)
|
||||
continue
|
||||
}
|
||||
if err = z.decommissionObject(ctx, bi.Name, gr); err != nil {
|
||||
stopFn(err)
|
||||
failure = true
|
||||
logger.LogIf(ctx, err)
|
||||
decomLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
stopFn(nil)
|
||||
@@ -953,13 +980,13 @@ func (z *erasureServerPools) decommissionPool(ctx context.Context, idx int, pool
|
||||
stopFn(err)
|
||||
auditLogDecom(ctx, "DecomDeleteObject", bi.Name, entry.name, "", err)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
decomLogIf(ctx, err)
|
||||
}
|
||||
}
|
||||
z.poolMetaMutex.Lock()
|
||||
z.poolMeta.TrackCurrentBucketObject(idx, bi.Name, entry.name)
|
||||
ok, err := z.poolMeta.updateAfter(ctx, idx, z.serverPools, 30*time.Second)
|
||||
logger.LogIf(ctx, err)
|
||||
decomLogIf(ctx, err)
|
||||
if ok {
|
||||
globalNotificationSys.ReloadPoolMeta(ctx)
|
||||
}
|
||||
@@ -987,7 +1014,7 @@ func (z *erasureServerPools) decommissionPool(ctx context.Context, idx int, pool
|
||||
}
|
||||
setN := humanize.Ordinal(setIdx + 1)
|
||||
retryDur := time.Duration(rand.Float64() * float64(5*time.Second))
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("listing objects from %s set failed with %v, retrying in %v", setN, err, retryDur), "decom-listing-failed"+setN)
|
||||
decomLogOnceIf(ctx, fmt.Errorf("listing objects from %s set failed with %v, retrying in %v", setN, err, retryDur), "decom-listing-failed"+setN)
|
||||
time.Sleep(retryDur)
|
||||
}
|
||||
}(setIdx)
|
||||
@@ -1055,7 +1082,7 @@ func (z *erasureServerPools) decommissionInBackground(ctx context.Context, idx i
|
||||
z.poolMetaMutex.Lock()
|
||||
if z.poolMeta.BucketDone(idx, bucket) {
|
||||
// remove from pendingBuckets and persist.
|
||||
logger.LogIf(ctx, z.poolMeta.save(ctx, z.serverPools))
|
||||
decomLogIf(ctx, z.poolMeta.save(ctx, z.serverPools))
|
||||
}
|
||||
z.poolMetaMutex.Unlock()
|
||||
continue
|
||||
@@ -1072,7 +1099,7 @@ func (z *erasureServerPools) decommissionInBackground(ctx context.Context, idx i
|
||||
|
||||
z.poolMetaMutex.Lock()
|
||||
if z.poolMeta.BucketDone(idx, bucket) {
|
||||
logger.LogIf(ctx, z.poolMeta.save(ctx, z.serverPools))
|
||||
decomLogIf(ctx, z.poolMeta.save(ctx, z.serverPools))
|
||||
}
|
||||
z.poolMetaMutex.Unlock()
|
||||
}
|
||||
@@ -1088,14 +1115,33 @@ func (z *erasureServerPools) checkAfterDecom(ctx context.Context, idx int) error
|
||||
pool := z.serverPools[idx]
|
||||
for _, set := range pool.sets {
|
||||
for _, bi := range buckets {
|
||||
vc, _ := globalBucketVersioningSys.Get(bi.Name)
|
||||
var vc *versioning.Versioning
|
||||
var lc *lifecycle.Lifecycle
|
||||
var lr objectlock.Retention
|
||||
var rcfg *replication.Config
|
||||
if bi.Name != minioMetaBucket {
|
||||
vc, err = globalBucketVersioningSys.Get(bi.Name)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
// Check if the current bucket has a configured lifecycle policy
|
||||
lc, _ := globalLifecycleSys.Get(bi.Name)
|
||||
// Check if the current bucket has a configured lifecycle policy
|
||||
lc, err = globalLifecycleSys.Get(bi.Name)
|
||||
if err != nil && !errors.Is(err, BucketLifecycleNotFound{Bucket: bi.Name}) {
|
||||
return err
|
||||
}
|
||||
|
||||
// Check if bucket is object locked.
|
||||
lr, _ := globalBucketObjectLockSys.Get(bi.Name)
|
||||
rcfg, _ := getReplicationConfig(ctx, bi.Name)
|
||||
// Check if bucket is object locked.
|
||||
lr, err = globalBucketObjectLockSys.Get(bi.Name)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
rcfg, err = getReplicationConfig(ctx, bi.Name)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
|
||||
filterLifecycle := func(bucket, object string, fi FileInfo) bool {
|
||||
if lc == nil {
|
||||
@@ -1118,7 +1164,7 @@ func (z *erasureServerPools) checkAfterDecom(ctx context.Context, idx int) error
|
||||
}
|
||||
|
||||
var versionsFound int
|
||||
err := set.listObjectsToDecommission(ctx, bi, func(entry metaCacheEntry) {
|
||||
if err = set.listObjectsToDecommission(ctx, bi, func(entry metaCacheEntry) {
|
||||
if !entry.isObject() {
|
||||
return
|
||||
}
|
||||
@@ -1146,8 +1192,7 @@ func (z *erasureServerPools) checkAfterDecom(ctx context.Context, idx int) error
|
||||
|
||||
versionsFound++
|
||||
}
|
||||
})
|
||||
if err != nil {
|
||||
}); err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
@@ -1170,8 +1215,8 @@ func (z *erasureServerPools) doDecommissionInRoutine(ctx context.Context, idx in
|
||||
dctx = logger.SetReqInfo(dctx, &logger.ReqInfo{})
|
||||
|
||||
if err := z.decommissionInBackground(dctx, idx); err != nil {
|
||||
logger.LogIf(GlobalContext, err)
|
||||
logger.LogIf(GlobalContext, z.DecommissionFailed(dctx, idx))
|
||||
decomLogIf(GlobalContext, err)
|
||||
decomLogIf(GlobalContext, z.DecommissionFailed(dctx, idx))
|
||||
return
|
||||
}
|
||||
|
||||
@@ -1181,20 +1226,20 @@ func (z *erasureServerPools) doDecommissionInRoutine(ctx context.Context, idx in
|
||||
z.poolMetaMutex.Unlock()
|
||||
|
||||
if !failed {
|
||||
logger.Event(dctx, "Decommissioning complete for pool '%s', verifying for any pending objects", poolCmdLine)
|
||||
decomLogEvent(dctx, "Decommissioning complete for pool '%s', verifying for any pending objects", poolCmdLine)
|
||||
err := z.checkAfterDecom(dctx, idx)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
decomLogIf(ctx, err)
|
||||
failed = true
|
||||
}
|
||||
}
|
||||
|
||||
if failed {
|
||||
// Decommission failed indicate as such.
|
||||
logger.LogIf(GlobalContext, z.DecommissionFailed(dctx, idx))
|
||||
decomLogIf(GlobalContext, z.DecommissionFailed(dctx, idx))
|
||||
} else {
|
||||
// Complete the decommission..
|
||||
logger.LogIf(GlobalContext, z.CompleteDecommission(dctx, idx))
|
||||
decomLogIf(GlobalContext, z.CompleteDecommission(dctx, idx))
|
||||
}
|
||||
}
|
||||
|
||||
@@ -1404,16 +1449,18 @@ func (z *erasureServerPools) getBucketsToDecommission(ctx context.Context) ([]de
|
||||
|
||||
// Buckets data are dispersed in multiple zones/sets, make
|
||||
// sure to decommission the necessary metadata.
|
||||
decomBuckets = append(decomBuckets, decomBucketInfo{
|
||||
Name: minioMetaBucket,
|
||||
Prefix: minioConfigPrefix,
|
||||
})
|
||||
decomBuckets = append(decomBuckets, decomBucketInfo{
|
||||
Name: minioMetaBucket,
|
||||
Prefix: bucketMetaPrefix,
|
||||
})
|
||||
decomMetaBuckets := []decomBucketInfo{
|
||||
{
|
||||
Name: minioMetaBucket,
|
||||
Prefix: minioConfigPrefix,
|
||||
},
|
||||
{
|
||||
Name: minioMetaBucket,
|
||||
Prefix: bucketMetaPrefix,
|
||||
},
|
||||
}
|
||||
|
||||
return decomBuckets, nil
|
||||
return append(decomMetaBuckets, decomBuckets...), nil
|
||||
}
|
||||
|
||||
func (z *erasureServerPools) StartDecommission(ctx context.Context, indices ...int) (err error) {
|
||||
|
||||
@@ -32,6 +32,10 @@ import (
|
||||
"github.com/dustin/go-humanize"
|
||||
"github.com/lithammer/shortuuid/v4"
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio/internal/bucket/lifecycle"
|
||||
objectlock "github.com/minio/minio/internal/bucket/object/lock"
|
||||
"github.com/minio/minio/internal/bucket/replication"
|
||||
"github.com/minio/minio/internal/bucket/versioning"
|
||||
"github.com/minio/minio/internal/hash"
|
||||
xioutil "github.com/minio/minio/internal/ioutil"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
@@ -146,7 +150,7 @@ func (z *erasureServerPools) updateRebalanceStats(ctx context.Context) error {
|
||||
lock := z.serverPools[0].NewNSLock(minioMetaBucket, rebalMetaName)
|
||||
lkCtx, err := lock.GetLock(ctx, globalOperationTimeout)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("failed to acquire write lock on %s/%s: %w", minioMetaBucket, rebalMetaName, err))
|
||||
rebalanceLogIf(ctx, fmt.Errorf("failed to acquire write lock on %s/%s: %w", minioMetaBucket, rebalMetaName, err))
|
||||
return err
|
||||
}
|
||||
defer lock.Unlock(lkCtx)
|
||||
@@ -372,7 +376,7 @@ func (z *erasureServerPools) IsPoolRebalancing(poolIndex int) bool {
|
||||
}
|
||||
|
||||
func (z *erasureServerPools) rebalanceBuckets(ctx context.Context, poolIdx int) (err error) {
|
||||
doneCh := make(chan struct{})
|
||||
doneCh := make(chan error, 1)
|
||||
defer xioutil.SafeClose(doneCh)
|
||||
|
||||
// Save rebalance.bin periodically.
|
||||
@@ -387,56 +391,59 @@ func (z *erasureServerPools) rebalanceBuckets(ctx context.Context, poolIdx int)
|
||||
|
||||
timer := time.NewTimer(randSleepFor())
|
||||
defer timer.Stop()
|
||||
var rebalDone bool
|
||||
var traceMsg string
|
||||
|
||||
var (
|
||||
quit bool
|
||||
traceMsg string
|
||||
)
|
||||
|
||||
for {
|
||||
select {
|
||||
case <-doneCh:
|
||||
// rebalance completed for poolIdx
|
||||
case rebalErr := <-doneCh:
|
||||
quit = true
|
||||
now := time.Now()
|
||||
var status rebalStatus
|
||||
|
||||
switch {
|
||||
case errors.Is(rebalErr, context.Canceled):
|
||||
status = rebalStopped
|
||||
traceMsg = fmt.Sprintf("stopped at %s", now)
|
||||
case rebalErr == nil:
|
||||
status = rebalCompleted
|
||||
traceMsg = fmt.Sprintf("completed at %s", now)
|
||||
default:
|
||||
status = rebalFailed
|
||||
traceMsg = fmt.Sprintf("stopped at %s with err: %v", now, rebalErr)
|
||||
}
|
||||
|
||||
z.rebalMu.Lock()
|
||||
z.rebalMeta.PoolStats[poolIdx].Info.Status = rebalCompleted
|
||||
z.rebalMeta.PoolStats[poolIdx].Info.Status = status
|
||||
z.rebalMeta.PoolStats[poolIdx].Info.EndTime = now
|
||||
z.rebalMu.Unlock()
|
||||
|
||||
rebalDone = true
|
||||
traceMsg = fmt.Sprintf("completed at %s", now)
|
||||
|
||||
case <-ctx.Done():
|
||||
|
||||
// rebalance stopped for poolIdx
|
||||
now := time.Now()
|
||||
z.rebalMu.Lock()
|
||||
z.rebalMeta.PoolStats[poolIdx].Info.Status = rebalStopped
|
||||
z.rebalMeta.PoolStats[poolIdx].Info.EndTime = now
|
||||
z.rebalMeta.cancel = nil // remove the already used context.CancelFunc
|
||||
z.rebalMu.Unlock()
|
||||
|
||||
rebalDone = true
|
||||
traceMsg = fmt.Sprintf("stopped at %s", now)
|
||||
|
||||
case <-timer.C:
|
||||
traceMsg = fmt.Sprintf("saved at %s", time.Now())
|
||||
}
|
||||
|
||||
stopFn := globalRebalanceMetrics.log(rebalanceMetricSaveMetadata, poolIdx, traceMsg)
|
||||
err := z.saveRebalanceStats(ctx, poolIdx, rebalSaveStats)
|
||||
err := z.saveRebalanceStats(GlobalContext, poolIdx, rebalSaveStats)
|
||||
stopFn(err)
|
||||
logger.LogIf(ctx, err)
|
||||
timer.Reset(randSleepFor())
|
||||
rebalanceLogIf(GlobalContext, err)
|
||||
|
||||
if rebalDone {
|
||||
if quit {
|
||||
return
|
||||
}
|
||||
|
||||
timer.Reset(randSleepFor())
|
||||
}
|
||||
}()
|
||||
|
||||
logger.Event(ctx, "Pool %d rebalancing is started", poolIdx+1)
|
||||
rebalanceLogEvent(ctx, "Pool %d rebalancing is started", poolIdx+1)
|
||||
|
||||
for {
|
||||
select {
|
||||
case <-ctx.Done():
|
||||
doneCh <- ctx.Err()
|
||||
return
|
||||
default:
|
||||
}
|
||||
@@ -448,17 +455,20 @@ func (z *erasureServerPools) rebalanceBuckets(ctx context.Context, poolIdx int)
|
||||
}
|
||||
|
||||
stopFn := globalRebalanceMetrics.log(rebalanceMetricRebalanceBucket, poolIdx, bucket)
|
||||
err = z.rebalanceBucket(ctx, bucket, poolIdx)
|
||||
if err != nil {
|
||||
if err = z.rebalanceBucket(ctx, bucket, poolIdx); err != nil {
|
||||
stopFn(err)
|
||||
logger.LogIf(ctx, err)
|
||||
if errors.Is(err, errServerNotInitialized) || errors.Is(err, errBucketMetadataNotInitialized) {
|
||||
continue
|
||||
}
|
||||
rebalanceLogIf(GlobalContext, err)
|
||||
doneCh <- err
|
||||
return
|
||||
}
|
||||
stopFn(nil)
|
||||
z.bucketRebalanceDone(bucket, poolIdx)
|
||||
}
|
||||
|
||||
logger.Event(ctx, "Pool %d rebalancing is done", poolIdx+1)
|
||||
rebalanceLogEvent(GlobalContext, "Pool %d rebalancing is done", poolIdx+1)
|
||||
|
||||
return err
|
||||
}
|
||||
@@ -521,21 +531,43 @@ func (set *erasureObjects) listObjectsToRebalance(ctx context.Context, bucketNam
|
||||
}
|
||||
|
||||
// rebalanceBucket rebalances objects under bucket in poolIdx pool
|
||||
func (z *erasureServerPools) rebalanceBucket(ctx context.Context, bucket string, poolIdx int) error {
|
||||
func (z *erasureServerPools) rebalanceBucket(ctx context.Context, bucket string, poolIdx int) (err error) {
|
||||
ctx = logger.SetReqInfo(ctx, &logger.ReqInfo{})
|
||||
vc, _ := globalBucketVersioningSys.Get(bucket)
|
||||
// Check if the current bucket has a configured lifecycle policy
|
||||
lc, _ := globalLifecycleSys.Get(bucket)
|
||||
// Check if bucket is object locked.
|
||||
lr, _ := globalBucketObjectLockSys.Get(bucket)
|
||||
rcfg, _ := getReplicationConfig(ctx, bucket)
|
||||
|
||||
var vc *versioning.Versioning
|
||||
var lc *lifecycle.Lifecycle
|
||||
var lr objectlock.Retention
|
||||
var rcfg *replication.Config
|
||||
if bucket != minioMetaBucket {
|
||||
vc, err = globalBucketVersioningSys.Get(bucket)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
// Check if the current bucket has a configured lifecycle policy
|
||||
lc, err = globalLifecycleSys.Get(bucket)
|
||||
if err != nil && !errors.Is(err, BucketLifecycleNotFound{Bucket: bucket}) {
|
||||
return err
|
||||
}
|
||||
|
||||
// Check if bucket is object locked.
|
||||
lr, err = globalBucketObjectLockSys.Get(bucket)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
rcfg, err = getReplicationConfig(ctx, bucket)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
|
||||
pool := z.serverPools[poolIdx]
|
||||
|
||||
const envRebalanceWorkers = "_MINIO_REBALANCE_WORKERS"
|
||||
workerSize, err := env.GetInt(envRebalanceWorkers, len(pool.sets))
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("invalid workers value err: %v, defaulting to %d", err, len(pool.sets)))
|
||||
rebalanceLogIf(ctx, fmt.Errorf("invalid workers value err: %v, defaulting to %d", err, len(pool.sets)))
|
||||
workerSize = len(pool.sets)
|
||||
}
|
||||
|
||||
@@ -630,7 +662,7 @@ func (z *erasureServerPools) rebalanceBucket(ctx context.Context, bucket string,
|
||||
})
|
||||
var failure bool
|
||||
if err != nil && !isErrObjectNotFound(err) && !isErrVersionNotFound(err) {
|
||||
logger.LogIf(ctx, err)
|
||||
rebalanceLogIf(ctx, err)
|
||||
failure = true
|
||||
}
|
||||
|
||||
@@ -665,14 +697,14 @@ func (z *erasureServerPools) rebalanceBucket(ctx context.Context, bucket string,
|
||||
}
|
||||
if err != nil {
|
||||
failure = true
|
||||
logger.LogIf(ctx, err)
|
||||
rebalanceLogIf(ctx, err)
|
||||
stopFn(err)
|
||||
continue
|
||||
}
|
||||
|
||||
if err = z.rebalanceObject(ctx, bucket, gr); err != nil {
|
||||
failure = true
|
||||
logger.LogIf(ctx, err)
|
||||
rebalanceLogIf(ctx, err)
|
||||
stopFn(err)
|
||||
continue
|
||||
}
|
||||
@@ -706,7 +738,7 @@ func (z *erasureServerPools) rebalanceBucket(ctx context.Context, bucket string,
|
||||
stopFn(err)
|
||||
auditLogRebalance(ctx, "Rebalance:DeleteObject", bucket, entry.name, "", err)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
rebalanceLogIf(ctx, err)
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -724,7 +756,7 @@ func (z *erasureServerPools) rebalanceBucket(ctx context.Context, bucket string,
|
||||
return
|
||||
}
|
||||
setN := humanize.Ordinal(setIdx + 1)
|
||||
logger.LogOnceIf(ctx, fmt.Errorf("listing objects from %s set failed with %v", setN, err), "rebalance-listing-failed"+setN)
|
||||
rebalanceLogIf(ctx, fmt.Errorf("listing objects from %s set failed with %v", setN, err), "rebalance-listing-failed"+setN)
|
||||
}(setIdx)
|
||||
}
|
||||
|
||||
@@ -743,7 +775,7 @@ func (z *erasureServerPools) saveRebalanceStats(ctx context.Context, poolIdx int
|
||||
lock := z.serverPools[0].NewNSLock(minioMetaBucket, rebalMetaName)
|
||||
lkCtx, err := lock.GetLock(ctx, globalOperationTimeout)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("failed to acquire write lock on %s/%s: %w", minioMetaBucket, rebalMetaName, err))
|
||||
rebalanceLogIf(ctx, fmt.Errorf("failed to acquire write lock on %s/%s: %w", minioMetaBucket, rebalMetaName, err))
|
||||
return err
|
||||
}
|
||||
defer lock.Unlock(lkCtx)
|
||||
|
||||
+280
-185
@@ -1,4 +1,4 @@
|
||||
// Copyright (c) 2015-2021 MinIO, Inc.
|
||||
// Copyright (c) 2015-2024 MinIO, Inc.
|
||||
//
|
||||
// This file is part of MinIO Object Storage stack
|
||||
//
|
||||
@@ -103,8 +103,9 @@ func newErasureServerPools(ctx context.Context, endpointServerPools EndpointServ
|
||||
|
||||
// Initialize byte pool once for all sets, bpool size is set to
|
||||
// setCount * setDriveCount with each memory upto blockSizeV2.
|
||||
globalBytePoolCap = bpool.NewBytePoolCap(n, blockSizeV2, blockSizeV2*2)
|
||||
globalBytePoolCap.Populate()
|
||||
buffers := bpool.NewBytePoolCap(n, blockSizeV2, blockSizeV2*2)
|
||||
buffers.Populate()
|
||||
globalBytePoolCap.Store(buffers)
|
||||
|
||||
var localDrives []StorageAPI
|
||||
local := endpointServerPools.FirstLocal()
|
||||
@@ -207,7 +208,7 @@ func newErasureServerPools(ctx context.Context, endpointServerPools EndpointServ
|
||||
logger.Fatal(err, "Unable to initialize backend")
|
||||
}
|
||||
retry := time.Duration(r.Float64() * float64(5*time.Second))
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to initialize backend: %w, retrying in %s", err, retry))
|
||||
storageLogIf(ctx, fmt.Errorf("Unable to initialize backend: %w, retrying in %s", err, retry))
|
||||
time.Sleep(retry)
|
||||
attempt++
|
||||
continue
|
||||
@@ -376,7 +377,7 @@ func (z *erasureServerPools) getAvailablePoolIdx(ctx context.Context, bucket, ob
|
||||
}
|
||||
}
|
||||
// Should not happen, but print values just in case.
|
||||
logger.LogIf(ctx, fmt.Errorf("reached end of serverPools (total: %v, atTotal: %v, choose: %v)", total, atTotal, choose))
|
||||
storageLogIf(ctx, fmt.Errorf("reached end of serverPools (total: %v, atTotal: %v, choose: %v)", total, atTotal, choose))
|
||||
return -1
|
||||
}
|
||||
|
||||
@@ -457,7 +458,13 @@ type PoolObjInfo struct {
|
||||
Err error
|
||||
}
|
||||
|
||||
func (z *erasureServerPools) getPoolInfoExistingWithOpts(ctx context.Context, bucket, object string, opts ObjectOptions) (PoolObjInfo, error) {
|
||||
type poolErrs struct {
|
||||
Index int
|
||||
Err error
|
||||
}
|
||||
|
||||
func (z *erasureServerPools) getPoolInfoExistingWithOpts(ctx context.Context, bucket, object string, opts ObjectOptions) (PoolObjInfo, []poolErrs, error) {
|
||||
var noReadQuorumPools []poolErrs
|
||||
poolObjInfos := make([]PoolObjInfo, len(z.serverPools))
|
||||
poolOpts := make([]ObjectOptions, len(z.serverPools))
|
||||
for i := range z.serverPools {
|
||||
@@ -507,8 +514,9 @@ func (z *erasureServerPools) getPoolInfoExistingWithOpts(ctx context.Context, bu
|
||||
}
|
||||
if pinfo.Err == nil {
|
||||
// found a pool
|
||||
return pinfo, nil
|
||||
return pinfo, z.poolsWithObject(poolObjInfos, opts), nil
|
||||
}
|
||||
|
||||
if isErrReadQuorum(pinfo.Err) && !opts.MetadataChg {
|
||||
// read quorum is returned when the object is visibly
|
||||
// present but its unreadable, we simply ask the writes to
|
||||
@@ -517,30 +525,49 @@ func (z *erasureServerPools) getPoolInfoExistingWithOpts(ctx context.Context, bu
|
||||
// with enough disks online but sufficiently inconsistent to
|
||||
// break parity threshold, allow them to be overwritten
|
||||
// or allow new versions to be added.
|
||||
return pinfo, nil
|
||||
|
||||
return pinfo, z.poolsWithObject(poolObjInfos, opts), nil
|
||||
}
|
||||
defPool = pinfo
|
||||
if !isErrObjectNotFound(pinfo.Err) {
|
||||
return pinfo, pinfo.Err
|
||||
return pinfo, noReadQuorumPools, pinfo.Err
|
||||
}
|
||||
|
||||
// No object exists or its a delete marker,
|
||||
// check objInfo to confirm.
|
||||
if pinfo.ObjInfo.DeleteMarker && pinfo.ObjInfo.Name != "" {
|
||||
return pinfo, nil
|
||||
return pinfo, noReadQuorumPools, nil
|
||||
}
|
||||
}
|
||||
if opts.ReplicationRequest && opts.DeleteMarker && defPool.Index >= 0 {
|
||||
// If the request is a delete marker replication request, return a default pool
|
||||
// in cases where the object does not exist.
|
||||
// This is to ensure that the delete marker is replicated to the destination.
|
||||
return defPool, nil
|
||||
return defPool, noReadQuorumPools, nil
|
||||
}
|
||||
return PoolObjInfo{}, toObjectErr(errFileNotFound, bucket, object)
|
||||
return PoolObjInfo{}, noReadQuorumPools, toObjectErr(errFileNotFound, bucket, object)
|
||||
}
|
||||
|
||||
// return all pools with read quorum error or no error for an object with given opts.Note that this array is
|
||||
// returned in the order of recency of object ModTime.
|
||||
func (z *erasureServerPools) poolsWithObject(pools []PoolObjInfo, opts ObjectOptions) (errs []poolErrs) {
|
||||
for _, pool := range pools {
|
||||
if opts.SkipDecommissioned && z.IsSuspended(pool.Index) {
|
||||
continue
|
||||
}
|
||||
// Skip object if it's from pools participating in a rebalance operation.
|
||||
if opts.SkipRebalancing && z.IsPoolRebalancing(pool.Index) {
|
||||
continue
|
||||
}
|
||||
if isErrReadQuorum(pool.Err) || pool.Err == nil {
|
||||
errs = append(errs, poolErrs{Err: pool.Err, Index: pool.Index})
|
||||
}
|
||||
}
|
||||
return errs
|
||||
}
|
||||
|
||||
func (z *erasureServerPools) getPoolIdxExistingWithOpts(ctx context.Context, bucket, object string, opts ObjectOptions) (idx int, err error) {
|
||||
pinfo, err := z.getPoolInfoExistingWithOpts(ctx, bucket, object, opts)
|
||||
pinfo, _, err := z.getPoolInfoExistingWithOpts(ctx, bucket, object, opts)
|
||||
if err != nil {
|
||||
return -1, err
|
||||
}
|
||||
@@ -610,13 +637,22 @@ func (z *erasureServerPools) Shutdown(ctx context.Context) error {
|
||||
|
||||
for _, err := range g.Wait() {
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
storageLogIf(ctx, err)
|
||||
}
|
||||
// let's the rest shutdown
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// Legacy returns 'true' if distribution algo is CRCMOD
|
||||
func (z *erasureServerPools) Legacy() (ok bool) {
|
||||
ok = true
|
||||
for _, set := range z.serverPools {
|
||||
ok = ok && set.Legacy()
|
||||
}
|
||||
return ok
|
||||
}
|
||||
|
||||
func (z *erasureServerPools) BackendInfo() (b madmin.BackendInfo) {
|
||||
b.Type = madmin.Erasure
|
||||
|
||||
@@ -688,12 +724,17 @@ func (z *erasureServerPools) NSScanner(ctx context.Context, updates chan<- DataU
|
||||
updates <- DataUsageInfo{} // no buckets found update data usage to reflect latest state
|
||||
return nil
|
||||
}
|
||||
|
||||
totalResults := 0
|
||||
resultIndex := -1
|
||||
for _, z := range z.serverPools {
|
||||
totalResults += len(z.sets)
|
||||
}
|
||||
results = make([]dataUsageCache, totalResults)
|
||||
// Collect for each set in serverPools.
|
||||
for _, z := range z.serverPools {
|
||||
for _, erObj := range z.sets {
|
||||
resultIndex++
|
||||
wg.Add(1)
|
||||
results = append(results, dataUsageCache{})
|
||||
go func(i int, erObj *erasureObjects) {
|
||||
updates := make(chan dataUsageCache, 1)
|
||||
defer xioutil.SafeClose(updates)
|
||||
@@ -709,7 +750,7 @@ func (z *erasureServerPools) NSScanner(ctx context.Context, updates chan<- DataU
|
||||
// Start scanner. Blocks until done.
|
||||
err := erObj.nsScanner(ctx, allBuckets, wantCycle, updates, healScanMode)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
scannerLogIf(ctx, err)
|
||||
mu.Lock()
|
||||
if firstErr == nil {
|
||||
firstErr = err
|
||||
@@ -719,7 +760,7 @@ func (z *erasureServerPools) NSScanner(ctx context.Context, updates chan<- DataU
|
||||
mu.Unlock()
|
||||
return
|
||||
}
|
||||
}(len(results)-1, erObj)
|
||||
}(resultIndex, erObj)
|
||||
}
|
||||
}
|
||||
updateCloser := make(chan chan struct{})
|
||||
@@ -1076,7 +1117,8 @@ func (z *erasureServerPools) DeleteObject(ctx context.Context, bucket string, ob
|
||||
|
||||
gopts := opts
|
||||
gopts.NoLock = true
|
||||
pinfo, err := z.getPoolInfoExistingWithOpts(ctx, bucket, object, gopts)
|
||||
|
||||
pinfo, noReadQuorumPools, err := z.getPoolInfoExistingWithOpts(ctx, bucket, object, gopts)
|
||||
if err != nil {
|
||||
if _, ok := err.(InsufficientReadQuorum); ok {
|
||||
return objInfo, InsufficientWriteQuorum{}
|
||||
@@ -1090,11 +1132,44 @@ func (z *erasureServerPools) DeleteObject(ctx context.Context, bucket string, ob
|
||||
return pinfo.ObjInfo, nil
|
||||
}
|
||||
|
||||
// Delete concurrently in all server pools with read quorum error for unversioned objects.
|
||||
if len(noReadQuorumPools) > 0 && !opts.Versioned && !opts.VersionSuspended {
|
||||
return z.deleteObjectFromAllPools(ctx, bucket, object, opts, noReadQuorumPools)
|
||||
}
|
||||
objInfo, err = z.serverPools[pinfo.Index].DeleteObject(ctx, bucket, object, opts)
|
||||
objInfo.Name = decodeDirObject(object)
|
||||
return objInfo, err
|
||||
}
|
||||
|
||||
func (z *erasureServerPools) deleteObjectFromAllPools(ctx context.Context, bucket string, object string, opts ObjectOptions, poolIndices []poolErrs) (objInfo ObjectInfo, err error) {
|
||||
derrs := make([]error, len(poolIndices))
|
||||
dobjects := make([]ObjectInfo, len(poolIndices))
|
||||
|
||||
// Delete concurrently in all server pools that reported no error or read quorum error
|
||||
// where the read quorum issue is from metadata inconsistency.
|
||||
var wg sync.WaitGroup
|
||||
for idx, pe := range poolIndices {
|
||||
if v, ok := pe.Err.(InsufficientReadQuorum); ok && v.Type != RQInconsistentMeta {
|
||||
derrs[idx] = InsufficientWriteQuorum{}
|
||||
continue
|
||||
}
|
||||
wg.Add(1)
|
||||
pool := z.serverPools[pe.Index]
|
||||
go func(idx int, pool *erasureSets) {
|
||||
defer wg.Done()
|
||||
dobjects[idx], derrs[idx] = pool.DeleteObject(ctx, bucket, object, opts)
|
||||
}(idx, pool)
|
||||
}
|
||||
wg.Wait()
|
||||
|
||||
// the poolIndices array is pre-sorted in order of latest ModTime, we care only about pool with latest object though
|
||||
// the delete call tries to clean up other pools during DeleteObject call.
|
||||
objInfo = dobjects[0]
|
||||
objInfo.Name = decodeDirObject(object)
|
||||
err = derrs[0]
|
||||
return objInfo, err
|
||||
}
|
||||
|
||||
func (z *erasureServerPools) DeleteObjects(ctx context.Context, bucket string, objects []ObjectToDelete, opts ObjectOptions) ([]DeletedObject, []error) {
|
||||
derrs := make([]error, len(objects))
|
||||
dobjects := make([]DeletedObject, len(objects))
|
||||
@@ -1136,7 +1211,7 @@ func (z *erasureServerPools) DeleteObjects(ctx context.Context, bucket string, o
|
||||
j := j
|
||||
obj := obj
|
||||
eg.Go(func() error {
|
||||
pinfo, err := z.getPoolInfoExistingWithOpts(ctx, bucket, obj.ObjectName, ObjectOptions{
|
||||
pinfo, _, err := z.getPoolInfoExistingWithOpts(ctx, bucket, obj.ObjectName, ObjectOptions{
|
||||
NoLock: true,
|
||||
})
|
||||
if err != nil {
|
||||
@@ -1324,7 +1399,7 @@ func (z *erasureServerPools) ListObjectVersions(ctx context.Context, bucket, pre
|
||||
merged, err := z.listPath(ctx, &opts)
|
||||
if err != nil && err != io.EOF {
|
||||
if !isErrBucketNotFound(err) {
|
||||
logger.LogOnceIf(ctx, err, "erasure-list-objects-path-"+bucket)
|
||||
storageLogOnceIf(ctx, err, "erasure-list-objects-path-"+bucket)
|
||||
}
|
||||
return loi, toObjectErr(err, bucket)
|
||||
}
|
||||
@@ -1518,7 +1593,7 @@ func (z *erasureServerPools) listObjectsGeneric(ctx context.Context, bucket, pre
|
||||
merged, err := z.listPath(ctx, &opts)
|
||||
if err != nil && err != io.EOF {
|
||||
if !isErrBucketNotFound(err) {
|
||||
logger.LogOnceIf(ctx, err, "erasure-list-objects-path-"+bucket)
|
||||
storageLogOnceIf(ctx, err, "erasure-list-objects-path-"+bucket)
|
||||
}
|
||||
return loi, toObjectErr(err, bucket)
|
||||
}
|
||||
@@ -1887,8 +1962,8 @@ func (z *erasureServerPools) ListBuckets(ctx context.Context, opts BucketOptions
|
||||
if opts.Cached {
|
||||
listBucketsCache.InitOnce(time.Second,
|
||||
cachevalue.Opts{ReturnLastGood: true, NoWait: true},
|
||||
func() ([]BucketInfo, error) {
|
||||
ctx, cancel := context.WithTimeout(context.Background(), 5*time.Second)
|
||||
func(ctx context.Context) ([]BucketInfo, error) {
|
||||
ctx, cancel := context.WithTimeout(ctx, 5*time.Second)
|
||||
defer cancel()
|
||||
|
||||
buckets, err = z.s3Peer.ListBuckets(ctx, opts)
|
||||
@@ -1905,7 +1980,7 @@ func (z *erasureServerPools) ListBuckets(ctx context.Context, opts BucketOptions
|
||||
},
|
||||
)
|
||||
|
||||
return listBucketsCache.Get()
|
||||
return listBucketsCache.GetWithCtx(ctx)
|
||||
}
|
||||
|
||||
buckets, err = z.s3Peer.ListBuckets(ctx, opts)
|
||||
@@ -1940,7 +2015,7 @@ func (z *erasureServerPools) HealFormat(ctx context.Context, dryRun bool) (madmi
|
||||
for _, pool := range z.serverPools {
|
||||
result, err := pool.HealFormat(ctx, dryRun)
|
||||
if err != nil && !errors.Is(err, errNoHealRequired) {
|
||||
logger.LogOnceIf(ctx, err, "erasure-heal-format")
|
||||
healingLogOnceIf(ctx, err, "erasure-heal-format")
|
||||
continue
|
||||
}
|
||||
// Count errNoHealRequired across all serverPools,
|
||||
@@ -1968,178 +2043,198 @@ func (z *erasureServerPools) HealBucket(ctx context.Context, bucket string, opts
|
||||
}
|
||||
|
||||
// Walk a bucket, optionally prefix recursively, until we have returned
|
||||
// all the content to objectInfo channel, it is callers responsibility
|
||||
// to allocate a receive channel for ObjectInfo, upon any unhandled
|
||||
// error walker returns error. Optionally if context.Done() is received
|
||||
// then Walk() stops the walker.
|
||||
func (z *erasureServerPools) Walk(ctx context.Context, bucket, prefix string, results chan<- ObjectInfo, opts WalkOptions) error {
|
||||
// all the contents of the provided bucket+prefix.
|
||||
// TODO: Note that most errors will result in a truncated listing.
|
||||
func (z *erasureServerPools) Walk(ctx context.Context, bucket, prefix string, results chan<- itemOrErr[ObjectInfo], opts WalkOptions) error {
|
||||
if err := checkListObjsArgs(ctx, bucket, prefix, ""); err != nil {
|
||||
// Upon error close the channel.
|
||||
xioutil.SafeClose(results)
|
||||
return err
|
||||
}
|
||||
parentCtx := ctx
|
||||
ctx, cancelCause := context.WithCancelCause(ctx)
|
||||
var entries []chan metaCacheEntry
|
||||
|
||||
vcfg, _ := globalBucketVersioningSys.Get(bucket)
|
||||
|
||||
ctx, cancel := context.WithCancel(ctx)
|
||||
go func() {
|
||||
defer cancel()
|
||||
defer xioutil.SafeClose(results)
|
||||
|
||||
for _, erasureSet := range z.serverPools {
|
||||
var wg sync.WaitGroup
|
||||
for _, set := range erasureSet.sets {
|
||||
set := set
|
||||
wg.Add(1)
|
||||
go func() {
|
||||
defer wg.Done()
|
||||
|
||||
disks, infos, _ := set.getOnlineDisksWithHealingAndInfo(true)
|
||||
if len(disks) == 0 {
|
||||
cancel()
|
||||
for poolIdx, erasureSet := range z.serverPools {
|
||||
for setIdx, set := range erasureSet.sets {
|
||||
set := set
|
||||
listOut := make(chan metaCacheEntry, 1)
|
||||
entries = append(entries, listOut)
|
||||
disks, infos, _ := set.getOnlineDisksWithHealingAndInfo(true)
|
||||
if len(disks) == 0 {
|
||||
xioutil.SafeClose(results)
|
||||
err := fmt.Errorf("Walk: no online disks found in pool %d, set %d", setIdx, poolIdx)
|
||||
cancelCause(err)
|
||||
return err
|
||||
}
|
||||
go func() {
|
||||
defer xioutil.SafeClose(listOut)
|
||||
send := func(e metaCacheEntry) {
|
||||
if e.isDir() {
|
||||
// Ignore directories.
|
||||
return
|
||||
}
|
||||
select {
|
||||
case listOut <- e:
|
||||
case <-ctx.Done():
|
||||
}
|
||||
}
|
||||
|
||||
send := func(objInfo ObjectInfo) bool {
|
||||
select {
|
||||
case <-ctx.Done():
|
||||
return false
|
||||
case results <- objInfo:
|
||||
return true
|
||||
askDisks := getListQuorum(opts.AskDisks, set.setDriveCount)
|
||||
if askDisks == -1 {
|
||||
newDisks := getQuorumDisks(disks, infos, (len(disks)+1)/2)
|
||||
if newDisks != nil {
|
||||
// If we found disks signature in quorum, we proceed to list
|
||||
// from a single drive, shuffling of the drives is subsequently.
|
||||
disks = newDisks
|
||||
askDisks = 1
|
||||
} else {
|
||||
// If we did not find suitable disks, perform strict quorum listing
|
||||
// as no disk agrees on quorum anymore.
|
||||
askDisks = getListQuorum("strict", set.setDriveCount)
|
||||
}
|
||||
}
|
||||
|
||||
// Special case: ask all disks if the drive count is 4
|
||||
if set.setDriveCount == 4 || askDisks > len(disks) {
|
||||
askDisks = len(disks) // use all available drives
|
||||
}
|
||||
|
||||
var fallbackDisks []StorageAPI
|
||||
if askDisks > 0 && len(disks) > askDisks {
|
||||
rand.Shuffle(len(disks), func(i, j int) {
|
||||
disks[i], disks[j] = disks[j], disks[i]
|
||||
})
|
||||
fallbackDisks = disks[askDisks:]
|
||||
disks = disks[:askDisks]
|
||||
}
|
||||
|
||||
requestedVersions := 0
|
||||
if opts.LatestOnly {
|
||||
requestedVersions = 1
|
||||
}
|
||||
|
||||
// However many we ask, versions must exist on ~50%
|
||||
listingQuorum := (askDisks + 1) / 2
|
||||
|
||||
// How to resolve partial results.
|
||||
resolver := metadataResolutionParams{
|
||||
dirQuorum: listingQuorum,
|
||||
objQuorum: listingQuorum,
|
||||
bucket: bucket,
|
||||
requestedVersions: requestedVersions,
|
||||
}
|
||||
|
||||
path := baseDirFromPrefix(prefix)
|
||||
filterPrefix := strings.Trim(strings.TrimPrefix(prefix, path), slashSeparator)
|
||||
if path == prefix {
|
||||
filterPrefix = ""
|
||||
}
|
||||
|
||||
lopts := listPathRawOptions{
|
||||
disks: disks,
|
||||
fallbackDisks: fallbackDisks,
|
||||
bucket: bucket,
|
||||
path: path,
|
||||
filterPrefix: filterPrefix,
|
||||
recursive: true,
|
||||
forwardTo: opts.Marker,
|
||||
minDisks: listingQuorum,
|
||||
reportNotFound: false,
|
||||
agreed: send,
|
||||
partial: func(entries metaCacheEntries, _ []error) {
|
||||
entry, ok := entries.resolve(&resolver)
|
||||
if ok {
|
||||
send(*entry)
|
||||
}
|
||||
}
|
||||
},
|
||||
finished: nil,
|
||||
}
|
||||
|
||||
askDisks := getListQuorum(opts.AskDisks, set.setDriveCount)
|
||||
if askDisks == -1 {
|
||||
newDisks := getQuorumDisks(disks, infos, (len(disks)+1)/2)
|
||||
if newDisks != nil {
|
||||
// If we found disks signature in quorum, we proceed to list
|
||||
// from a single drive, shuffling of the drives is subsequently.
|
||||
disks = newDisks
|
||||
askDisks = 1
|
||||
} else {
|
||||
// If we did not find suitable disks, perform strict quorum listing
|
||||
// as no disk agrees on quorum anymore.
|
||||
askDisks = getListQuorum("strict", set.setDriveCount)
|
||||
}
|
||||
}
|
||||
if err := listPathRaw(ctx, lopts); err != nil {
|
||||
cancelCause(fmt.Errorf("listPathRaw returned %w: opts(%#v)", err, lopts))
|
||||
return
|
||||
}
|
||||
}()
|
||||
}
|
||||
}
|
||||
|
||||
// Special case: ask all disks if the drive count is 4
|
||||
if set.setDriveCount == 4 || askDisks > len(disks) {
|
||||
askDisks = len(disks) // use all available drives
|
||||
}
|
||||
|
||||
var fallbackDisks []StorageAPI
|
||||
if askDisks > 0 && len(disks) > askDisks {
|
||||
rand.Shuffle(len(disks), func(i, j int) {
|
||||
disks[i], disks[j] = disks[j], disks[i]
|
||||
})
|
||||
fallbackDisks = disks[askDisks:]
|
||||
disks = disks[:askDisks]
|
||||
}
|
||||
|
||||
requestedVersions := 0
|
||||
if opts.LatestOnly {
|
||||
requestedVersions = 1
|
||||
}
|
||||
loadEntry := func(entry metaCacheEntry) {
|
||||
if entry.isDir() {
|
||||
// Convert and filter merged entries.
|
||||
merged := make(chan metaCacheEntry, 100)
|
||||
vcfg, _ := globalBucketVersioningSys.Get(bucket)
|
||||
go func() {
|
||||
defer cancelCause(nil)
|
||||
defer xioutil.SafeClose(results)
|
||||
sentErr := false
|
||||
sendErr := func(err error) {
|
||||
if !sentErr {
|
||||
select {
|
||||
case results <- itemOrErr[ObjectInfo]{Err: err}:
|
||||
sentErr = true
|
||||
case <-parentCtx.Done():
|
||||
}
|
||||
}
|
||||
}
|
||||
send := func(oi ObjectInfo) bool {
|
||||
select {
|
||||
case results <- itemOrErr[ObjectInfo]{Item: oi}:
|
||||
return true
|
||||
case <-ctx.Done():
|
||||
sendErr(context.Cause(ctx))
|
||||
return false
|
||||
}
|
||||
}
|
||||
for entry := range merged {
|
||||
if opts.LatestOnly {
|
||||
fi, err := entry.fileInfo(bucket)
|
||||
if err != nil {
|
||||
sendErr(err)
|
||||
return
|
||||
}
|
||||
if opts.Filter != nil {
|
||||
if opts.Filter(fi) {
|
||||
if !send(fi.ToObjectInfo(bucket, fi.Name, vcfg != nil && vcfg.Versioned(fi.Name))) {
|
||||
return
|
||||
}
|
||||
|
||||
if opts.LatestOnly {
|
||||
fi, err := entry.fileInfo(bucket)
|
||||
if err != nil {
|
||||
cancel()
|
||||
return
|
||||
}
|
||||
if opts.Filter != nil {
|
||||
if opts.Filter(fi) {
|
||||
if !send(fi.ToObjectInfo(bucket, fi.Name, vcfg != nil && vcfg.Versioned(fi.Name))) {
|
||||
return
|
||||
}
|
||||
}
|
||||
} else {
|
||||
if !send(fi.ToObjectInfo(bucket, fi.Name, vcfg != nil && vcfg.Versioned(fi.Name))) {
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
} else {
|
||||
fivs, err := entry.fileInfoVersions(bucket)
|
||||
if err != nil {
|
||||
cancel()
|
||||
return
|
||||
}
|
||||
|
||||
// Note: entry.fileInfoVersions returns versions sorted in reverse chronological order based on ModTime
|
||||
if opts.VersionsSort == WalkVersionsSortAsc {
|
||||
versionsSorter(fivs.Versions).reverse()
|
||||
}
|
||||
|
||||
for _, version := range fivs.Versions {
|
||||
if opts.Filter != nil {
|
||||
if opts.Filter(version) {
|
||||
if !send(version.ToObjectInfo(bucket, version.Name, vcfg != nil && vcfg.Versioned(version.Name))) {
|
||||
return
|
||||
}
|
||||
}
|
||||
} else {
|
||||
if !send(version.ToObjectInfo(bucket, version.Name, vcfg != nil && vcfg.Versioned(version.Name))) {
|
||||
return
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// However many we ask, versions must exist on ~50%
|
||||
listingQuorum := (askDisks + 1) / 2
|
||||
|
||||
// How to resolve partial results.
|
||||
resolver := metadataResolutionParams{
|
||||
dirQuorum: listingQuorum,
|
||||
objQuorum: listingQuorum,
|
||||
bucket: bucket,
|
||||
requestedVersions: requestedVersions,
|
||||
}
|
||||
|
||||
path := baseDirFromPrefix(prefix)
|
||||
filterPrefix := strings.Trim(strings.TrimPrefix(prefix, path), slashSeparator)
|
||||
if path == prefix {
|
||||
filterPrefix = ""
|
||||
}
|
||||
|
||||
lopts := listPathRawOptions{
|
||||
disks: disks,
|
||||
fallbackDisks: fallbackDisks,
|
||||
bucket: bucket,
|
||||
path: path,
|
||||
filterPrefix: filterPrefix,
|
||||
recursive: true,
|
||||
forwardTo: opts.Marker,
|
||||
minDisks: 1,
|
||||
reportNotFound: false,
|
||||
agreed: loadEntry,
|
||||
partial: func(entries metaCacheEntries, _ []error) {
|
||||
entry, ok := entries.resolve(&resolver)
|
||||
if ok {
|
||||
loadEntry(*entry)
|
||||
}
|
||||
},
|
||||
finished: nil,
|
||||
}
|
||||
|
||||
if err := listPathRaw(ctx, lopts); err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("listPathRaw returned %w: opts(%#v)", err, lopts))
|
||||
cancel()
|
||||
} else {
|
||||
if !send(fi.ToObjectInfo(bucket, fi.Name, vcfg != nil && vcfg.Versioned(fi.Name))) {
|
||||
return
|
||||
}
|
||||
}()
|
||||
}
|
||||
continue
|
||||
}
|
||||
fivs, err := entry.fileInfoVersions(bucket)
|
||||
if err != nil {
|
||||
sendErr(err)
|
||||
return
|
||||
}
|
||||
|
||||
// Note: entry.fileInfoVersions returns versions sorted in reverse chronological order based on ModTime
|
||||
if opts.VersionsSort == WalkVersionsSortAsc {
|
||||
versionsSorter(fivs.Versions).reverse()
|
||||
}
|
||||
|
||||
for _, version := range fivs.Versions {
|
||||
if opts.Filter != nil {
|
||||
if opts.Filter(version) {
|
||||
if !send(version.ToObjectInfo(bucket, version.Name, vcfg != nil && vcfg.Versioned(version.Name))) {
|
||||
return
|
||||
}
|
||||
}
|
||||
} else {
|
||||
if !send(version.ToObjectInfo(bucket, version.Name, vcfg != nil && vcfg.Versioned(version.Name))) {
|
||||
return
|
||||
}
|
||||
}
|
||||
}
|
||||
wg.Wait()
|
||||
}
|
||||
}()
|
||||
go func() {
|
||||
// Merge all entries from all disks.
|
||||
// We leave quorum at 1, since entries are already resolved to have the desired quorum.
|
||||
// mergeEntryChannels will close 'merged' channel upon completion or cancellation.
|
||||
storageLogIf(ctx, mergeEntryChannels(ctx, entries, merged, 1))
|
||||
}()
|
||||
|
||||
return nil
|
||||
}
|
||||
@@ -2176,7 +2271,7 @@ func (z *erasureServerPools) HealObjects(ctx context.Context, bucket, prefix str
|
||||
if opts.Remove && !opts.DryRun {
|
||||
err := z.CheckAbandonedParts(ctx, bucket, entry.name, opts)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to check object %s/%s for abandoned data: %w", bucket, entry.name, err))
|
||||
healingLogIf(ctx, fmt.Errorf("unable to check object %s/%s for abandoned data: %w", bucket, entry.name, err))
|
||||
}
|
||||
}
|
||||
for _, version := range fivs.Versions {
|
||||
@@ -2204,7 +2299,7 @@ func (z *erasureServerPools) HealObjects(ctx context.Context, bucket, prefix str
|
||||
go func(idx int, set *erasureObjects) {
|
||||
defer wg.Done()
|
||||
|
||||
errs[idx] = set.listAndHeal(bucket, prefix, opts.ScanMode, healEntry)
|
||||
errs[idx] = set.listAndHeal(ctx, bucket, prefix, opts.ScanMode, healEntry)
|
||||
}(idx, set)
|
||||
}
|
||||
wg.Wait()
|
||||
@@ -2380,7 +2475,7 @@ func (z *erasureServerPools) Health(ctx context.Context, opts HealthOptions) Hea
|
||||
// Check if disks are healing on in-case of VMware vsphere deployments.
|
||||
if opts.Maintenance && opts.DeploymentType == vmware {
|
||||
if drivesHealing > 0 {
|
||||
logger.LogIf(logger.SetReqInfo(ctx, reqInfo), fmt.Errorf("Total drives to be healed %d", drivesHealing))
|
||||
healingLogIf(logger.SetReqInfo(ctx, reqInfo), fmt.Errorf("Total drives to be healed %d", drivesHealing))
|
||||
}
|
||||
}
|
||||
|
||||
@@ -2440,15 +2535,15 @@ func (z *erasureServerPools) Health(ctx context.Context, opts HealthOptions) Hea
|
||||
|
||||
healthy := erasureSetUpCount[poolIdx][setIdx].online >= poolWriteQuorums[poolIdx]
|
||||
if !healthy {
|
||||
logger.LogIf(logger.SetReqInfo(ctx, reqInfo),
|
||||
storageLogIf(logger.SetReqInfo(ctx, reqInfo),
|
||||
fmt.Errorf("Write quorum may be lost on pool: %d, set: %d, expected write quorum: %d",
|
||||
poolIdx, setIdx, poolWriteQuorums[poolIdx]))
|
||||
poolIdx, setIdx, poolWriteQuorums[poolIdx]), logger.FatalKind)
|
||||
}
|
||||
result.Healthy = result.Healthy && healthy
|
||||
|
||||
healthyRead := erasureSetUpCount[poolIdx][setIdx].online >= poolReadQuorums[poolIdx]
|
||||
if !healthyRead {
|
||||
logger.LogIf(logger.SetReqInfo(ctx, reqInfo),
|
||||
storageLogIf(logger.SetReqInfo(ctx, reqInfo),
|
||||
fmt.Errorf("Read quorum may be lost on pool: %d, set: %d, expected read quorum: %d",
|
||||
poolIdx, setIdx, poolReadQuorums[poolIdx]))
|
||||
}
|
||||
|
||||
+27
-38
@@ -31,7 +31,6 @@ import (
|
||||
"time"
|
||||
|
||||
"github.com/dchest/siphash"
|
||||
"github.com/dustin/go-humanize"
|
||||
"github.com/google/uuid"
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio-go/v7/pkg/set"
|
||||
@@ -115,26 +114,26 @@ func (s *erasureSets) getDiskMap() map[Endpoint]StorageAPI {
|
||||
|
||||
// Initializes a new StorageAPI from the endpoint argument, returns
|
||||
// StorageAPI and also `format` which exists on the disk.
|
||||
func connectEndpoint(endpoint Endpoint) (StorageAPI, *formatErasureV3, []byte, error) {
|
||||
func connectEndpoint(endpoint Endpoint) (StorageAPI, *formatErasureV3, error) {
|
||||
disk, err := newStorageAPI(endpoint, storageOpts{
|
||||
cleanUp: false,
|
||||
healthCheck: false,
|
||||
})
|
||||
if err != nil {
|
||||
return nil, nil, nil, err
|
||||
return nil, nil, err
|
||||
}
|
||||
|
||||
format, formatData, err := loadFormatErasureWithData(disk, false)
|
||||
format, err := loadFormatErasure(disk, false)
|
||||
if err != nil {
|
||||
if errors.Is(err, errUnformattedDisk) {
|
||||
info, derr := disk.DiskInfo(context.TODO(), DiskInfoOptions{})
|
||||
if derr != nil && info.RootDisk {
|
||||
disk.Close()
|
||||
return nil, nil, nil, fmt.Errorf("Drive: %s is a root drive", disk)
|
||||
return nil, nil, fmt.Errorf("Drive: %s is a root drive", disk)
|
||||
}
|
||||
}
|
||||
disk.Close()
|
||||
return nil, nil, nil, fmt.Errorf("Drive: %s returned %w", disk, err) // make sure to '%w' to wrap the error
|
||||
return nil, nil, fmt.Errorf("Drive: %s returned %w", disk, err) // make sure to '%w' to wrap the error
|
||||
}
|
||||
|
||||
disk.Close()
|
||||
@@ -143,10 +142,10 @@ func connectEndpoint(endpoint Endpoint) (StorageAPI, *formatErasureV3, []byte, e
|
||||
healthCheck: true,
|
||||
})
|
||||
if err != nil {
|
||||
return nil, nil, nil, err
|
||||
return nil, nil, err
|
||||
}
|
||||
|
||||
return disk, format, formatData, nil
|
||||
return disk, format, nil
|
||||
}
|
||||
|
||||
// findDiskIndex - returns the i,j'th position of the input `diskID` against the reference
|
||||
@@ -195,6 +194,11 @@ func findDiskIndex(refFormat, format *formatErasureV3) (int, int, error) {
|
||||
return -1, -1, fmt.Errorf("DriveID: %s not found", format.Erasure.This)
|
||||
}
|
||||
|
||||
// Legacy returns 'true' if distribution algo is CRCMOD
|
||||
func (s *erasureSets) Legacy() (ok bool) {
|
||||
return s.distributionAlgo == formatErasureVersionV2DistributionAlgoV1
|
||||
}
|
||||
|
||||
// connectDisks - attempt to connect all the endpoints, loads format
|
||||
// and re-arranges the disks in proper position.
|
||||
func (s *erasureSets) connectDisks() {
|
||||
@@ -227,7 +231,7 @@ func (s *erasureSets) connectDisks() {
|
||||
wg.Add(1)
|
||||
go func(endpoint Endpoint) {
|
||||
defer wg.Done()
|
||||
disk, format, formatData, err := connectEndpoint(endpoint)
|
||||
disk, format, err := connectEndpoint(endpoint)
|
||||
if err != nil {
|
||||
if endpoint.IsLocal && errors.Is(err, errUnformattedDisk) {
|
||||
globalBackgroundHealState.pushHealLocalDisks(endpoint)
|
||||
@@ -261,8 +265,6 @@ func (s *erasureSets) connectDisks() {
|
||||
}
|
||||
|
||||
disk.SetDiskID(format.Erasure.This)
|
||||
disk.SetDiskLoc(s.poolIndex, setIndex, diskIndex)
|
||||
disk.SetFormatData(formatData)
|
||||
s.erasureDisks[setIndex][diskIndex] = disk
|
||||
|
||||
if disk.IsLocal() {
|
||||
@@ -448,27 +450,17 @@ func newErasureSets(ctx context.Context, endpoints PoolEndpoints, storageDisks [
|
||||
diskID, err := disk.GetDiskID()
|
||||
if err != nil {
|
||||
if !errors.Is(err, errUnformattedDisk) {
|
||||
logger.LogIf(ctx, err)
|
||||
bootLogIf(ctx, err)
|
||||
}
|
||||
return
|
||||
}
|
||||
if diskID == "" {
|
||||
return
|
||||
}
|
||||
m, n, err := findDiskIndexByDiskID(format, diskID)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
return
|
||||
}
|
||||
if m != i || n != j {
|
||||
logger.LogIf(ctx, fmt.Errorf("Detected unexpected drive ordering refusing to use the drive - poolID: %s, found drive mounted at (set=%s, drive=%s) expected mount at (set=%s, drive=%s): %s(%s)", humanize.Ordinal(poolIdx+1), humanize.Ordinal(m+1), humanize.Ordinal(n+1), humanize.Ordinal(i+1), humanize.Ordinal(j+1), disk, diskID))
|
||||
s.erasureDisks[i][j] = &unrecognizedDisk{storage: disk}
|
||||
return
|
||||
}
|
||||
disk.SetDiskLoc(s.poolIndex, m, n)
|
||||
s.erasureDisks[m][n] = disk
|
||||
s.erasureDisks[i][j] = disk
|
||||
}(disk, i, j)
|
||||
}
|
||||
|
||||
innerWg.Wait()
|
||||
|
||||
// Initialize erasure objects for a given set.
|
||||
@@ -562,10 +554,10 @@ func (s *erasureSets) cleanupStaleUploads(ctx context.Context) {
|
||||
}
|
||||
|
||||
type auditObjectOp struct {
|
||||
Name string `json:"name"`
|
||||
Pool int `json:"poolId"`
|
||||
Set int `json:"setId"`
|
||||
Disks []string `json:"disks"`
|
||||
Name string `json:"name"`
|
||||
Pool int `json:"poolId"`
|
||||
Set int `json:"setId"`
|
||||
Drives []string `json:"drives"`
|
||||
}
|
||||
|
||||
// Add erasure set information to the current context
|
||||
@@ -575,10 +567,10 @@ func auditObjectErasureSet(ctx context.Context, object string, set *erasureObjec
|
||||
}
|
||||
|
||||
op := auditObjectOp{
|
||||
Name: decodeDirObject(object),
|
||||
Pool: set.poolIndex + 1,
|
||||
Set: set.setIndex + 1,
|
||||
Disks: set.getEndpointStrings(),
|
||||
Name: decodeDirObject(object),
|
||||
Pool: set.poolIndex + 1,
|
||||
Set: set.setIndex + 1,
|
||||
Drives: set.getEndpointStrings(),
|
||||
}
|
||||
|
||||
logger.GetReqInfo(ctx).AppendTags("objectLocation", op)
|
||||
@@ -1083,7 +1075,7 @@ func (s *erasureSets) HealFormat(ctx context.Context, dryRun bool) (res madmin.H
|
||||
|
||||
if !reflect.DeepEqual(s.format, refFormat) {
|
||||
// Format is corrupted and unrecognized by the running instance.
|
||||
logger.LogIf(ctx, fmt.Errorf("Unable to heal the newly replaced drives due to format.json inconsistencies, please engage MinIO support for further assistance: %w",
|
||||
healingLogIf(ctx, fmt.Errorf("Unable to heal the newly replaced drives due to format.json inconsistencies, please engage MinIO support for further assistance: %w",
|
||||
errCorruptedFormat))
|
||||
return res, errCorruptedFormat
|
||||
}
|
||||
@@ -1112,7 +1104,7 @@ func (s *erasureSets) HealFormat(ctx context.Context, dryRun bool) (res madmin.H
|
||||
continue
|
||||
}
|
||||
if err := saveFormatErasure(storageDisks[index], format, formatOpID); err != nil {
|
||||
logger.LogIf(ctx, fmt.Errorf("Drive %s failed to write updated 'format.json': %v", storageDisks[index], err))
|
||||
healingLogIf(ctx, fmt.Errorf("Drive %s failed to write updated 'format.json': %v", storageDisks[index], err))
|
||||
storageDisks[index].Close()
|
||||
tmpNewFormats[index] = nil // this disk failed to write new format
|
||||
}
|
||||
@@ -1127,7 +1119,7 @@ func (s *erasureSets) HealFormat(ctx context.Context, dryRun bool) (res madmin.H
|
||||
|
||||
m, n, err := findDiskIndexByDiskID(refFormat, format.Erasure.This)
|
||||
if err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
healingLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
|
||||
@@ -1137,8 +1129,6 @@ func (s *erasureSets) HealFormat(ctx context.Context, dryRun bool) (res madmin.H
|
||||
|
||||
if disk := storageDisks[index]; disk != nil {
|
||||
if disk.IsLocal() {
|
||||
disk.SetDiskLoc(s.poolIndex, m, n)
|
||||
|
||||
xldisk, ok := disk.(*xlStorageDiskIDCheck)
|
||||
if ok {
|
||||
_, commonDeletes := calcCommonWritesDeletes(currentDisksInfo[m], (s.setDriveCount+1)/2)
|
||||
@@ -1155,7 +1145,6 @@ func (s *erasureSets) HealFormat(ctx context.Context, dryRun bool) (res madmin.H
|
||||
if err != nil {
|
||||
continue
|
||||
}
|
||||
disk.SetDiskLoc(s.poolIndex, m, n)
|
||||
}
|
||||
|
||||
s.erasureDisks[m][n] = disk
|
||||
|
||||
+33
-30
@@ -31,7 +31,6 @@ import (
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio/internal/dsync"
|
||||
xioutil "github.com/minio/minio/internal/ioutil"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/sync/errgroup"
|
||||
)
|
||||
|
||||
@@ -273,11 +272,11 @@ func (er erasureObjects) LocalStorageInfo(ctx context.Context, metrics bool) Sto
|
||||
}
|
||||
|
||||
// getOnlineDisksWithHealingAndInfo - returns online disks and overall healing status.
|
||||
// Disks are randomly ordered, but in the following groups:
|
||||
// Disks are ordered in the following groups:
|
||||
// - Non-scanning disks
|
||||
// - Non-healing disks
|
||||
// - Healing disks (if inclHealing is true)
|
||||
func (er erasureObjects) getOnlineDisksWithHealingAndInfo(inclHealing bool) (newDisks []StorageAPI, newInfos []DiskInfo, healing bool) {
|
||||
func (er erasureObjects) getOnlineDisksWithHealingAndInfo(inclHealing bool) (newDisks []StorageAPI, newInfos []DiskInfo, healing int) {
|
||||
var wg sync.WaitGroup
|
||||
disks := er.getDisks()
|
||||
infos := make([]DiskInfo, len(disks))
|
||||
@@ -316,7 +315,7 @@ func (er erasureObjects) getOnlineDisksWithHealingAndInfo(inclHealing bool) (new
|
||||
continue
|
||||
}
|
||||
if info.Healing {
|
||||
healing = true
|
||||
healing++
|
||||
if inclHealing {
|
||||
healingDisks = append(healingDisks, disks[i])
|
||||
healingInfos = append(healingInfos, infos[i])
|
||||
@@ -344,32 +343,32 @@ func (er erasureObjects) getOnlineDisksWithHealingAndInfo(inclHealing bool) (new
|
||||
return newDisks, newInfos, healing
|
||||
}
|
||||
|
||||
func (er erasureObjects) getOnlineDisksWithHealing(inclHealing bool) (newDisks []StorageAPI, healing bool) {
|
||||
newDisks, _, healing = er.getOnlineDisksWithHealingAndInfo(inclHealing)
|
||||
return
|
||||
func (er erasureObjects) getOnlineDisksWithHealing(inclHealing bool) ([]StorageAPI, bool) {
|
||||
newDisks, _, healing := er.getOnlineDisksWithHealingAndInfo(inclHealing)
|
||||
return newDisks, healing > 0
|
||||
}
|
||||
|
||||
// Clean-up previously deleted objects. from .minio.sys/tmp/.trash/
|
||||
func (er erasureObjects) cleanupDeletedObjects(ctx context.Context) {
|
||||
// run multiple cleanup's local to this server.
|
||||
var wg sync.WaitGroup
|
||||
for _, disk := range er.getLocalDisks() {
|
||||
if disk != nil {
|
||||
wg.Add(1)
|
||||
go func(disk StorageAPI) {
|
||||
defer wg.Done()
|
||||
diskPath := disk.Endpoint().Path
|
||||
readDirFn(pathJoin(diskPath, minioMetaTmpDeletedBucket), func(ddir string, typ os.FileMode) error {
|
||||
w := xioutil.NewDeadlineWorker(globalDriveConfig.GetMaxTimeout())
|
||||
return w.Run(func() error {
|
||||
wait := deletedCleanupSleeper.Timer(ctx)
|
||||
removeAll(pathJoin(diskPath, minioMetaTmpDeletedBucket, ddir))
|
||||
wait()
|
||||
return nil
|
||||
})
|
||||
})
|
||||
}(disk)
|
||||
if disk == nil {
|
||||
continue
|
||||
}
|
||||
wg.Add(1)
|
||||
go func(disk StorageAPI) {
|
||||
defer wg.Done()
|
||||
drivePath := disk.Endpoint().Path
|
||||
readDirFn(pathJoin(drivePath, minioMetaTmpDeletedBucket), func(ddir string, typ os.FileMode) error {
|
||||
w := xioutil.NewDeadlineWorker(globalDriveConfig.GetMaxTimeout())
|
||||
return w.Run(func() error {
|
||||
wait := deleteCleanupSleeper.Timer(ctx)
|
||||
removeAll(pathJoin(drivePath, minioMetaTmpDeletedBucket, ddir))
|
||||
wait()
|
||||
return nil
|
||||
})
|
||||
})
|
||||
}(disk)
|
||||
}
|
||||
wg.Wait()
|
||||
}
|
||||
@@ -384,7 +383,7 @@ func (er erasureObjects) nsScanner(ctx context.Context, buckets []BucketInfo, wa
|
||||
// Collect disks we can use.
|
||||
disks, healing := er.getOnlineDisksWithHealing(false)
|
||||
if len(disks) == 0 {
|
||||
logger.LogIf(ctx, errors.New("data-scanner: all drives are offline or being healed, skipping scanner cycle"))
|
||||
scannerLogIf(ctx, errors.New("data-scanner: all drives are offline or being healed, skipping scanner cycle"))
|
||||
return nil
|
||||
}
|
||||
|
||||
@@ -449,7 +448,7 @@ func (er erasureObjects) nsScanner(ctx context.Context, buckets []BucketInfo, wa
|
||||
if cache.Info.LastUpdate.Equal(lastSave) {
|
||||
continue
|
||||
}
|
||||
logger.LogOnceIf(ctx, cache.save(ctx, er, dataUsageCacheName), "nsscanner-cache-update")
|
||||
scannerLogOnceIf(ctx, cache.save(ctx, er, dataUsageCacheName), "nsscanner-cache-update")
|
||||
updates <- cache.clone()
|
||||
|
||||
lastSave = cache.Info.LastUpdate
|
||||
@@ -458,7 +457,7 @@ func (er erasureObjects) nsScanner(ctx context.Context, buckets []BucketInfo, wa
|
||||
// Save final state...
|
||||
cache.Info.NextCycle = wantCycle
|
||||
cache.Info.LastUpdate = time.Now()
|
||||
logger.LogOnceIf(ctx, cache.save(ctx, er, dataUsageCacheName), "nsscanner-channel-closed")
|
||||
scannerLogOnceIf(ctx, cache.save(ctx, er, dataUsageCacheName), "nsscanner-channel-closed")
|
||||
updates <- cache.clone()
|
||||
return
|
||||
}
|
||||
@@ -494,7 +493,7 @@ func (er erasureObjects) nsScanner(ctx context.Context, buckets []BucketInfo, wa
|
||||
// Load cache for bucket
|
||||
cacheName := pathJoin(bucket.Name, dataUsageCacheName)
|
||||
cache := dataUsageCache{}
|
||||
logger.LogIf(ctx, cache.load(ctx, er, cacheName))
|
||||
scannerLogIf(ctx, cache.load(ctx, er, cacheName))
|
||||
if cache.Info.Name == "" {
|
||||
cache.Info.Name = bucket.Name
|
||||
}
|
||||
@@ -530,9 +529,9 @@ func (er erasureObjects) nsScanner(ctx context.Context, buckets []BucketInfo, wa
|
||||
cache, err = disk.NSScanner(ctx, cache, updates, healScanMode, nil)
|
||||
if err != nil {
|
||||
if !cache.Info.LastUpdate.IsZero() && cache.Info.LastUpdate.After(before) {
|
||||
logger.LogIf(ctx, cache.save(ctx, er, cacheName))
|
||||
scannerLogIf(ctx, cache.save(ctx, er, cacheName))
|
||||
} else {
|
||||
logger.LogIf(ctx, err)
|
||||
scannerLogIf(ctx, err)
|
||||
}
|
||||
// This ensures that we don't close
|
||||
// bucketResults channel while the
|
||||
@@ -543,9 +542,13 @@ func (er erasureObjects) nsScanner(ctx context.Context, buckets []BucketInfo, wa
|
||||
}
|
||||
|
||||
wg.Wait()
|
||||
// Flatten for upstream, but save full state.
|
||||
var root dataUsageEntry
|
||||
if r := cache.root(); r != nil {
|
||||
root = cache.flatten(*r)
|
||||
if root.ReplicationStats.empty() {
|
||||
root.ReplicationStats = nil
|
||||
}
|
||||
}
|
||||
select {
|
||||
case <-ctx.Done():
|
||||
@@ -558,7 +561,7 @@ func (er erasureObjects) nsScanner(ctx context.Context, buckets []BucketInfo, wa
|
||||
}
|
||||
|
||||
// Save cache
|
||||
logger.LogIf(ctx, cache.save(ctx, er, cacheName))
|
||||
scannerLogIf(ctx, cache.save(ctx, er, cacheName))
|
||||
}
|
||||
}(i)
|
||||
}
|
||||
|
||||
+4
-5
@@ -22,7 +22,6 @@ import (
|
||||
"errors"
|
||||
"fmt"
|
||||
|
||||
"github.com/minio/minio/internal/logger"
|
||||
etcd "go.etcd.io/etcd/client/v3"
|
||||
)
|
||||
|
||||
@@ -48,7 +47,7 @@ func saveKeyEtcdWithTTL(ctx context.Context, client *etcd.Client, key string, da
|
||||
return etcdErrToErr(err, client.Endpoints())
|
||||
}
|
||||
_, err = client.Put(timeoutCtx, key, string(data), etcd.WithLease(lease.ID))
|
||||
logger.LogIf(ctx, err)
|
||||
etcdLogIf(ctx, err)
|
||||
return etcdErrToErr(err, client.Endpoints())
|
||||
}
|
||||
|
||||
@@ -59,7 +58,7 @@ func saveKeyEtcd(ctx context.Context, client *etcd.Client, key string, data []by
|
||||
return saveKeyEtcdWithTTL(ctx, client, key, data, opts[0].ttl)
|
||||
}
|
||||
_, err := client.Put(timeoutCtx, key, string(data))
|
||||
logger.LogIf(ctx, err)
|
||||
etcdLogIf(ctx, err)
|
||||
return etcdErrToErr(err, client.Endpoints())
|
||||
}
|
||||
|
||||
@@ -68,7 +67,7 @@ func deleteKeyEtcd(ctx context.Context, client *etcd.Client, key string) error {
|
||||
defer cancel()
|
||||
|
||||
_, err := client.Delete(timeoutCtx, key)
|
||||
logger.LogIf(ctx, err)
|
||||
etcdLogIf(ctx, err)
|
||||
return etcdErrToErr(err, client.Endpoints())
|
||||
}
|
||||
|
||||
@@ -77,7 +76,7 @@ func readKeyEtcd(ctx context.Context, client *etcd.Client, key string) ([]byte,
|
||||
defer cancel()
|
||||
resp, err := client.Get(timeoutCtx, key)
|
||||
if err != nil {
|
||||
logger.LogOnceIf(ctx, err, "etcd-retrieve-keys")
|
||||
etcdLogOnceIf(ctx, err, "etcd-retrieve-keys")
|
||||
return nil, etcdErrToErr(err, client.Endpoints())
|
||||
}
|
||||
if resp.Count == 0 {
|
||||
|
||||
@@ -28,7 +28,6 @@ import (
|
||||
"github.com/minio/minio/internal/crypto"
|
||||
"github.com/minio/minio/internal/event"
|
||||
xhttp "github.com/minio/minio/internal/http"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/minio/internal/pubsub"
|
||||
"github.com/minio/pkg/v2/policy"
|
||||
)
|
||||
@@ -83,7 +82,7 @@ func (evnot *EventNotifier) set(bucket BucketInfo, meta BucketMetadata) {
|
||||
config.SetRegion(globalSite.Region)
|
||||
if err := config.Validate(globalSite.Region, globalEventNotifier.targetList); err != nil {
|
||||
if _, ok := err.(*event.ErrARNNotFound); !ok {
|
||||
logger.LogIf(GlobalContext, err)
|
||||
internalLogIf(GlobalContext, err)
|
||||
}
|
||||
}
|
||||
evnot.AddRulesMap(bucket.Name, config.ToRulesMap())
|
||||
|
||||
+16
-151
@@ -24,11 +24,9 @@ import (
|
||||
"fmt"
|
||||
"io/fs"
|
||||
"os"
|
||||
"reflect"
|
||||
"sync"
|
||||
|
||||
"github.com/dustin/go-humanize"
|
||||
jsoniter "github.com/json-iterator/go"
|
||||
"github.com/minio/minio/internal/color"
|
||||
"github.com/minio/minio/internal/config"
|
||||
"github.com/minio/minio/internal/config/storageclass"
|
||||
@@ -278,7 +276,7 @@ func formatErasureMigrateV2ToV3(data []byte, export, version string) ([]byte, er
|
||||
tmpOld := pathJoin(export, minioMetaTmpDeletedBucket, mustGetUUID())
|
||||
if err := renameAll(pathJoin(export, minioMetaMultipartBucket),
|
||||
tmpOld, export); err != nil && err != errFileNotFound {
|
||||
logger.LogIf(GlobalContext, fmt.Errorf("unable to rename (%s -> %s) %w, drive may be faulty please investigate",
|
||||
bootLogIf(GlobalContext, fmt.Errorf("unable to rename (%s -> %s) %w, drive may be faulty please investigate",
|
||||
pathJoin(export, minioMetaMultipartBucket),
|
||||
tmpOld,
|
||||
osErrToFileErr(err)))
|
||||
@@ -331,7 +329,7 @@ func loadFormatErasureAll(storageDisks []StorageAPI, heal bool) ([]*formatErasur
|
||||
if storageDisks[index] == nil {
|
||||
return errDiskNotFound
|
||||
}
|
||||
format, formatData, err := loadFormatErasureWithData(storageDisks[index], heal)
|
||||
format, err := loadFormatErasure(storageDisks[index], heal)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
@@ -340,7 +338,6 @@ func loadFormatErasureAll(storageDisks []StorageAPI, heal bool) ([]*formatErasur
|
||||
// If no healing required, make the disks valid and
|
||||
// online.
|
||||
storageDisks[index].SetDiskID(format.Erasure.This)
|
||||
storageDisks[index].SetFormatData(formatData)
|
||||
}
|
||||
return nil
|
||||
}, index)
|
||||
@@ -380,7 +377,6 @@ func saveFormatErasure(disk StorageAPI, format *formatErasureV3, healID string)
|
||||
}
|
||||
|
||||
disk.SetDiskID(format.Erasure.This)
|
||||
disk.SetFormatData(formatData)
|
||||
if healID != "" {
|
||||
ctx := context.Background()
|
||||
ht := initHealingTracker(disk, healID)
|
||||
@@ -389,56 +385,32 @@ func saveFormatErasure(disk StorageAPI, format *formatErasureV3, healID string)
|
||||
return nil
|
||||
}
|
||||
|
||||
// loadFormatErasureWithData - loads format.json from disk.
|
||||
func loadFormatErasureWithData(disk StorageAPI, heal bool) (format *formatErasureV3, data []byte, err error) {
|
||||
data, err = disk.ReadAll(context.TODO(), minioMetaBucket, formatConfigFile)
|
||||
// loadFormatErasure - loads format.json from disk.
|
||||
func loadFormatErasure(disk StorageAPI, heal bool) (format *formatErasureV3, err error) {
|
||||
data, err := disk.ReadAll(context.TODO(), minioMetaBucket, formatConfigFile)
|
||||
if err != nil {
|
||||
// 'file not found' and 'volume not found' as
|
||||
// same. 'volume not found' usually means its a fresh disk.
|
||||
if errors.Is(err, errFileNotFound) || errors.Is(err, errVolumeNotFound) {
|
||||
return nil, nil, errUnformattedDisk
|
||||
}
|
||||
return nil, nil, err
|
||||
}
|
||||
|
||||
// Try to decode format json into formatConfigV1 struct.
|
||||
format = &formatErasureV3{}
|
||||
if err = json.Unmarshal(data, format); err != nil {
|
||||
return nil, nil, err
|
||||
}
|
||||
|
||||
if heal {
|
||||
info, err := disk.DiskInfo(context.Background(), DiskInfoOptions{NoOp: heal})
|
||||
if err != nil {
|
||||
return nil, nil, err
|
||||
}
|
||||
format.Info = info
|
||||
}
|
||||
|
||||
// Success.
|
||||
return format, data, nil
|
||||
}
|
||||
|
||||
// loadFormatErasure - loads format.json from disk.
|
||||
func loadFormatErasure(disk StorageAPI) (format *formatErasureV3, err error) {
|
||||
buf, err := disk.ReadAll(context.TODO(), minioMetaBucket, formatConfigFile)
|
||||
if err != nil {
|
||||
// 'file not found' and 'volume not found' as
|
||||
// same. 'volume not found' usually means its a fresh disk.
|
||||
if err == errFileNotFound || err == errVolumeNotFound {
|
||||
return nil, errUnformattedDisk
|
||||
}
|
||||
return nil, err
|
||||
}
|
||||
|
||||
json := jsoniter.ConfigCompatibleWithStandardLibrary
|
||||
|
||||
// Try to decode format json into formatConfigV1 struct.
|
||||
format = &formatErasureV3{}
|
||||
if err = json.Unmarshal(buf, format); err != nil {
|
||||
if err = json.Unmarshal(data, format); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
if heal {
|
||||
info, err := disk.DiskInfo(context.Background(), DiskInfoOptions{NoOp: heal})
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
format.Info = info
|
||||
}
|
||||
|
||||
// Success.
|
||||
return format, nil
|
||||
}
|
||||
@@ -471,115 +443,8 @@ func checkFormatErasureValues(formats []*formatErasureV3, disks []StorageAPI, se
|
||||
return fmt.Errorf("%s drive is already being used in another erasure deployment. (Number of drives specified: %d but the number of drives found in the %s drive's format.json: %d)",
|
||||
disks[i], len(formats), humanize.Ordinal(i+1), len(formatErasure.Erasure.Sets)*len(formatErasure.Erasure.Sets[0]))
|
||||
}
|
||||
// Only if custom erasure drive count is set, verify if the
|
||||
// set_drive_count was manually set - we need to honor what is
|
||||
// present on the drives.
|
||||
if globalCustomErasureDriveCount && len(formatErasure.Erasure.Sets[0]) != setDriveCount {
|
||||
return fmt.Errorf("%s drive is already formatted with %d drives per erasure set. This cannot be changed to %d, please revert your MINIO_ERASURE_SET_DRIVE_COUNT setting", disks[i], len(formatErasure.Erasure.Sets[0]), setDriveCount)
|
||||
}
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// Get Deployment ID for the Erasure sets from format.json.
|
||||
// This need not be in quorum. Even if one of the format.json
|
||||
// file has this value, we assume it is valid.
|
||||
// If more than one format.json's have different id, it is considered a corrupt
|
||||
// backend format.
|
||||
func formatErasureGetDeploymentID(refFormat *formatErasureV3, formats []*formatErasureV3) (string, error) {
|
||||
var deploymentID string
|
||||
for _, format := range formats {
|
||||
if format == nil || format.ID == "" {
|
||||
continue
|
||||
}
|
||||
if reflect.DeepEqual(format.Erasure.Sets, refFormat.Erasure.Sets) {
|
||||
// Found an ID in one of the format.json file
|
||||
// Set deploymentID for the first time.
|
||||
if deploymentID == "" {
|
||||
deploymentID = format.ID
|
||||
} else if deploymentID != format.ID {
|
||||
// DeploymentID found earlier doesn't match with the
|
||||
// current format.json's ID.
|
||||
return "", fmt.Errorf("Deployment IDs do not match expected %s, got %s: %w",
|
||||
deploymentID, format.ID, errCorruptedFormat)
|
||||
}
|
||||
}
|
||||
}
|
||||
return deploymentID, nil
|
||||
}
|
||||
|
||||
// formatErasureFixDeploymentID - Add deployment id if it is not present.
|
||||
func formatErasureFixDeploymentID(endpoints Endpoints, storageDisks []StorageAPI, refFormat *formatErasureV3, formats []*formatErasureV3) (err error) {
|
||||
for index := range formats {
|
||||
// If the Erasure sets do not match, set those formats to nil,
|
||||
// We do not have to update the ID on those format.json file.
|
||||
if formats[index] != nil && !reflect.DeepEqual(formats[index].Erasure.Sets, refFormat.Erasure.Sets) {
|
||||
formats[index] = nil
|
||||
}
|
||||
}
|
||||
|
||||
refFormat.ID, err = formatErasureGetDeploymentID(refFormat, formats)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
|
||||
// If ID is set, then some other node got the lock
|
||||
// before this node could and generated an ID
|
||||
// for the deployment. No need to generate one.
|
||||
if refFormat.ID != "" {
|
||||
return nil
|
||||
}
|
||||
|
||||
// ID is generated for the first time,
|
||||
// We set the ID in all the formats and update.
|
||||
refFormat.ID = mustGetUUID()
|
||||
for _, format := range formats {
|
||||
if format != nil {
|
||||
format.ID = refFormat.ID
|
||||
}
|
||||
}
|
||||
// Deployment ID needs to be set on all the disks.
|
||||
// Save `format.json` across all disks.
|
||||
return saveFormatErasureAll(GlobalContext, storageDisks, formats)
|
||||
}
|
||||
|
||||
// Update only the valid local disks which have not been updated before.
|
||||
func formatErasureFixLocalDeploymentID(endpoints Endpoints, storageDisks []StorageAPI, refFormat *formatErasureV3) error {
|
||||
// If this server was down when the deploymentID was updated
|
||||
// then we make sure that we update the local disks with the deploymentID.
|
||||
|
||||
// Initialize errs to collect errors inside go-routine.
|
||||
g := errgroup.WithNErrs(len(storageDisks))
|
||||
|
||||
for index := range storageDisks {
|
||||
index := index
|
||||
g.Go(func() error {
|
||||
if endpoints[index].IsLocal && storageDisks[index] != nil && storageDisks[index].IsOnline() {
|
||||
format, err := loadFormatErasure(storageDisks[index])
|
||||
if err != nil {
|
||||
// Disk can be offline etc.
|
||||
// ignore the errors seen here.
|
||||
return nil
|
||||
}
|
||||
if format.ID != "" {
|
||||
return nil
|
||||
}
|
||||
if !reflect.DeepEqual(format.Erasure.Sets, refFormat.Erasure.Sets) {
|
||||
return nil
|
||||
}
|
||||
format.ID = refFormat.ID
|
||||
// Heal the drive if we fixed its deployment ID.
|
||||
if err := saveFormatErasure(storageDisks[index], format, mustGetUUID()); err != nil {
|
||||
logger.LogIf(GlobalContext, err)
|
||||
return fmt.Errorf("Unable to save format.json, %w", err)
|
||||
}
|
||||
}
|
||||
return nil
|
||||
}, index)
|
||||
}
|
||||
for _, err := range g.Wait() {
|
||||
if err != nil {
|
||||
return err
|
||||
if len(formatErasure.Erasure.Sets[0]) != setDriveCount {
|
||||
return fmt.Errorf("%s drive is already formatted with %d drives per erasure set. This cannot be changed to %d", disks[i], len(formatErasure.Erasure.Sets[0]), setDriveCount)
|
||||
}
|
||||
}
|
||||
return nil
|
||||
|
||||
@@ -21,7 +21,6 @@ import (
|
||||
"crypto/sha256"
|
||||
"encoding/hex"
|
||||
"encoding/json"
|
||||
"errors"
|
||||
"os"
|
||||
"reflect"
|
||||
"testing"
|
||||
@@ -431,62 +430,6 @@ func BenchmarkGetFormatErasureInQuorum(b *testing.B) {
|
||||
}
|
||||
}
|
||||
|
||||
// Tests formatErasureGetDeploymentID()
|
||||
func TestGetErasureID(t *testing.T) {
|
||||
setCount := 2
|
||||
setDriveCount := 8
|
||||
|
||||
format := newFormatErasureV3(setCount, setDriveCount)
|
||||
format.Erasure.DistributionAlgo = formatErasureVersionV2DistributionAlgoV1
|
||||
formats := make([]*formatErasureV3, 16)
|
||||
|
||||
for i := 0; i < setCount; i++ {
|
||||
for j := 0; j < setDriveCount; j++ {
|
||||
newFormat := format.Clone()
|
||||
newFormat.Erasure.This = format.Erasure.Sets[i][j]
|
||||
formats[i*setDriveCount+j] = newFormat
|
||||
}
|
||||
}
|
||||
|
||||
// Return a format from list of formats in quorum.
|
||||
quorumFormat, err := getFormatErasureInQuorum(formats)
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
|
||||
// Check if the reference format and input formats are same.
|
||||
var id string
|
||||
if id, err = formatErasureGetDeploymentID(quorumFormat, formats); err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
|
||||
if id == "" {
|
||||
t.Fatal("ID cannot be empty.")
|
||||
}
|
||||
|
||||
formats[0] = nil
|
||||
if id, err = formatErasureGetDeploymentID(quorumFormat, formats); err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
if id == "" {
|
||||
t.Fatal("ID cannot be empty.")
|
||||
}
|
||||
|
||||
formats[1].Erasure.Sets[0][0] = "bad-uuid"
|
||||
if id, err = formatErasureGetDeploymentID(quorumFormat, formats); err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
|
||||
if id == "" {
|
||||
t.Fatal("ID cannot be empty.")
|
||||
}
|
||||
|
||||
formats[2].ID = "bad-id"
|
||||
if _, err = formatErasureGetDeploymentID(quorumFormat, formats); !errors.Is(err, errCorruptedFormat) {
|
||||
t.Fatalf("Unexpected error %s", err)
|
||||
}
|
||||
}
|
||||
|
||||
// Initialize new format sets.
|
||||
func TestNewFormatSets(t *testing.T) {
|
||||
setCount := 2
|
||||
|
||||
+40
-37
@@ -25,6 +25,7 @@ import (
|
||||
"fmt"
|
||||
"io"
|
||||
"os"
|
||||
"path"
|
||||
"strings"
|
||||
"time"
|
||||
|
||||
@@ -33,7 +34,7 @@ import (
|
||||
"github.com/minio/minio-go/v7/pkg/credentials"
|
||||
"github.com/minio/minio/internal/auth"
|
||||
xioutil "github.com/minio/minio/internal/ioutil"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/mimedb"
|
||||
ftp "goftp.io/server/v2"
|
||||
)
|
||||
|
||||
@@ -82,8 +83,13 @@ func (m *minioFileInfo) Mode() os.FileMode {
|
||||
return os.ModePerm
|
||||
}
|
||||
|
||||
var minFileDate = time.Date(1980, 1, 1, 0, 0, 0, 0, time.UTC) // Workaround for Filezilla
|
||||
|
||||
func (m *minioFileInfo) ModTime() time.Time {
|
||||
return m.info.LastModified
|
||||
if !m.info.LastModified.IsZero() {
|
||||
return m.info.LastModified
|
||||
}
|
||||
return minFileDate
|
||||
}
|
||||
|
||||
func (m *minioFileInfo) IsDir() bool {
|
||||
@@ -99,7 +105,7 @@ type ftpMetrics struct{}
|
||||
|
||||
var globalFtpMetrics ftpMetrics
|
||||
|
||||
func ftpTrace(s *ftp.Context, startTime time.Time, source, path string, err error) madmin.TraceInfo {
|
||||
func ftpTrace(s *ftp.Context, startTime time.Time, source, objPath string, err error) madmin.TraceInfo {
|
||||
var errStr string
|
||||
if err != nil {
|
||||
errStr = err.Error()
|
||||
@@ -110,7 +116,7 @@ func ftpTrace(s *ftp.Context, startTime time.Time, source, path string, err erro
|
||||
NodeName: globalLocalNodeName,
|
||||
FuncName: fmt.Sprintf("ftp USER=%s COMMAND=%s PARAM=%s ISLOGIN=%t, Source=%s", s.Sess.LoginUser(), s.Cmd, s.Param, s.Sess.IsLogin(), source),
|
||||
Duration: time.Since(startTime),
|
||||
Path: path,
|
||||
Path: objPath,
|
||||
Error: errStr,
|
||||
}
|
||||
}
|
||||
@@ -124,18 +130,18 @@ func (m *ftpMetrics) log(s *ftp.Context, paths ...string) func(err error) {
|
||||
}
|
||||
|
||||
// Stat implements ftpDriver
|
||||
func (driver *ftpDriver) Stat(ctx *ftp.Context, path string) (fi os.FileInfo, err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, path)
|
||||
func (driver *ftpDriver) Stat(ctx *ftp.Context, objPath string) (fi os.FileInfo, err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, objPath)
|
||||
defer stopFn(err)
|
||||
|
||||
if path == SlashSeparator {
|
||||
if objPath == SlashSeparator {
|
||||
return &minioFileInfo{
|
||||
p: SlashSeparator,
|
||||
isDir: true,
|
||||
}, nil
|
||||
}
|
||||
|
||||
bucket, object := path2BucketObject(path)
|
||||
bucket, object := path2BucketObject(objPath)
|
||||
if bucket == "" {
|
||||
return nil, errors.New("bucket name cannot be empty")
|
||||
}
|
||||
@@ -182,8 +188,8 @@ func (driver *ftpDriver) Stat(ctx *ftp.Context, path string) (fi os.FileInfo, er
|
||||
}
|
||||
|
||||
// ListDir implements ftpDriver
|
||||
func (driver *ftpDriver) ListDir(ctx *ftp.Context, path string, callback func(os.FileInfo) error) (err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, path)
|
||||
func (driver *ftpDriver) ListDir(ctx *ftp.Context, objPath string, callback func(os.FileInfo) error) (err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, objPath)
|
||||
defer stopFn(err)
|
||||
|
||||
clnt, err := driver.getMinIOClient(ctx)
|
||||
@@ -194,7 +200,7 @@ func (driver *ftpDriver) ListDir(ctx *ftp.Context, path string, callback func(os
|
||||
cctx, cancel := context.WithCancel(context.Background())
|
||||
defer cancel()
|
||||
|
||||
bucket, prefix := path2BucketObject(path)
|
||||
bucket, prefix := path2BucketObject(objPath)
|
||||
if bucket == "" {
|
||||
buckets, err := clnt.ListBuckets(cctx)
|
||||
if err != nil {
|
||||
@@ -323,7 +329,7 @@ func (driver *ftpDriver) getMinIOClient(ctx *ftp.Context) (*minio.Client, error)
|
||||
}
|
||||
|
||||
// Call hook for site replication.
|
||||
logger.LogIf(context.Background(), globalSiteReplicationSys.IAMChangeHook(context.Background(), madmin.SRIAMItem{
|
||||
replLogIf(context.Background(), globalSiteReplicationSys.IAMChangeHook(context.Background(), madmin.SRIAMItem{
|
||||
Type: madmin.SRIAMItemSTSAcc,
|
||||
STSCredential: &madmin.SRSTSCredential{
|
||||
AccessKey: cred.AccessKey,
|
||||
@@ -361,11 +367,11 @@ func (driver *ftpDriver) getMinIOClient(ctx *ftp.Context) (*minio.Client, error)
|
||||
}
|
||||
|
||||
// DeleteDir implements ftpDriver
|
||||
func (driver *ftpDriver) DeleteDir(ctx *ftp.Context, path string) (err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, path)
|
||||
func (driver *ftpDriver) DeleteDir(ctx *ftp.Context, objPath string) (err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, objPath)
|
||||
defer stopFn(err)
|
||||
|
||||
bucket, prefix := path2BucketObject(path)
|
||||
bucket, prefix := path2BucketObject(objPath)
|
||||
if bucket == "" {
|
||||
return errors.New("deleting all buckets not allowed")
|
||||
}
|
||||
@@ -411,11 +417,11 @@ func (driver *ftpDriver) DeleteDir(ctx *ftp.Context, path string) (err error) {
|
||||
}
|
||||
|
||||
// DeleteFile implements ftpDriver
|
||||
func (driver *ftpDriver) DeleteFile(ctx *ftp.Context, path string) (err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, path)
|
||||
func (driver *ftpDriver) DeleteFile(ctx *ftp.Context, objPath string) (err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, objPath)
|
||||
defer stopFn(err)
|
||||
|
||||
bucket, object := path2BucketObject(path)
|
||||
bucket, object := path2BucketObject(objPath)
|
||||
if bucket == "" {
|
||||
return errors.New("bucket name cannot be empty")
|
||||
}
|
||||
@@ -429,19 +435,19 @@ func (driver *ftpDriver) DeleteFile(ctx *ftp.Context, path string) (err error) {
|
||||
}
|
||||
|
||||
// Rename implements ftpDriver
|
||||
func (driver *ftpDriver) Rename(ctx *ftp.Context, fromPath string, toPath string) (err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, fromPath, toPath)
|
||||
func (driver *ftpDriver) Rename(ctx *ftp.Context, fromObjPath string, toObjPath string) (err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, fromObjPath, toObjPath)
|
||||
defer stopFn(err)
|
||||
|
||||
return NotImplemented{}
|
||||
}
|
||||
|
||||
// MakeDir implements ftpDriver
|
||||
func (driver *ftpDriver) MakeDir(ctx *ftp.Context, path string) (err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, path)
|
||||
func (driver *ftpDriver) MakeDir(ctx *ftp.Context, objPath string) (err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, objPath)
|
||||
defer stopFn(err)
|
||||
|
||||
bucket, prefix := path2BucketObject(path)
|
||||
bucket, prefix := path2BucketObject(objPath)
|
||||
if bucket == "" {
|
||||
return errors.New("bucket name cannot be empty")
|
||||
}
|
||||
@@ -457,21 +463,18 @@ func (driver *ftpDriver) MakeDir(ctx *ftp.Context, path string) (err error) {
|
||||
|
||||
dirPath := buildMinioDir(prefix)
|
||||
|
||||
_, err = clnt.PutObject(context.Background(), bucket, dirPath, bytes.NewReader([]byte("")), 0,
|
||||
// Always send Content-MD5 to succeed with bucket with
|
||||
// locking enabled. There is no performance hit since
|
||||
// this is always an empty object
|
||||
minio.PutObjectOptions{SendContentMd5: true},
|
||||
)
|
||||
_, err = clnt.PutObject(context.Background(), bucket, dirPath, bytes.NewReader([]byte("")), 0, minio.PutObjectOptions{
|
||||
DisableContentSha256: true,
|
||||
})
|
||||
return err
|
||||
}
|
||||
|
||||
// GetFile implements ftpDriver
|
||||
func (driver *ftpDriver) GetFile(ctx *ftp.Context, path string, offset int64) (n int64, rc io.ReadCloser, err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, path)
|
||||
func (driver *ftpDriver) GetFile(ctx *ftp.Context, objPath string, offset int64) (n int64, rc io.ReadCloser, err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, objPath)
|
||||
defer stopFn(err)
|
||||
|
||||
bucket, object := path2BucketObject(path)
|
||||
bucket, object := path2BucketObject(objPath)
|
||||
if bucket == "" {
|
||||
return 0, nil, errors.New("bucket name cannot be empty")
|
||||
}
|
||||
@@ -506,11 +509,11 @@ func (driver *ftpDriver) GetFile(ctx *ftp.Context, path string, offset int64) (n
|
||||
}
|
||||
|
||||
// PutFile implements ftpDriver
|
||||
func (driver *ftpDriver) PutFile(ctx *ftp.Context, path string, data io.Reader, offset int64) (n int64, err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, path)
|
||||
func (driver *ftpDriver) PutFile(ctx *ftp.Context, objPath string, data io.Reader, offset int64) (n int64, err error) {
|
||||
stopFn := globalFtpMetrics.log(ctx, objPath)
|
||||
defer stopFn(err)
|
||||
|
||||
bucket, object := path2BucketObject(path)
|
||||
bucket, object := path2BucketObject(objPath)
|
||||
if bucket == "" {
|
||||
return 0, errors.New("bucket name cannot be empty")
|
||||
}
|
||||
@@ -526,8 +529,8 @@ func (driver *ftpDriver) PutFile(ctx *ftp.Context, path string, data io.Reader,
|
||||
}
|
||||
|
||||
info, err := clnt.PutObject(context.Background(), bucket, object, data, -1, minio.PutObjectOptions{
|
||||
ContentType: "application/octet-stream",
|
||||
SendContentMd5: true,
|
||||
ContentType: mimedb.TypeByExtension(path.Ext(object)),
|
||||
DisableContentSha256: true,
|
||||
})
|
||||
return info.Size, err
|
||||
}
|
||||
|
||||
@@ -33,6 +33,8 @@ import (
|
||||
"github.com/minio/minio-go/v7/pkg/set"
|
||||
"github.com/minio/minio/internal/grid"
|
||||
xnet "github.com/minio/pkg/v2/net"
|
||||
"golang.org/x/exp/maps"
|
||||
"golang.org/x/exp/slices"
|
||||
|
||||
"github.com/minio/minio/internal/amztime"
|
||||
"github.com/minio/minio/internal/config/dns"
|
||||
@@ -73,6 +75,9 @@ const (
|
||||
// and must not set by clients
|
||||
func containsReservedMetadata(header http.Header) bool {
|
||||
for key := range header {
|
||||
if slices.Contains(maps.Keys(validSSEReplicationHeaders), key) {
|
||||
return false
|
||||
}
|
||||
if stringsHasPrefixFold(key, ReservedMetadataPrefix) {
|
||||
return true
|
||||
}
|
||||
@@ -305,6 +310,13 @@ func hasBadHost(host string) error {
|
||||
// Check if the incoming path has bad path components,
|
||||
// such as ".." and "."
|
||||
func hasBadPathComponent(path string) bool {
|
||||
if len(path) > 4096 {
|
||||
// path cannot be greater than Linux PATH_MAX
|
||||
// this is to avoid a busy loop, that can happen
|
||||
// if the caller sends path of following style
|
||||
// a/a/a/a/a/a/a/a...
|
||||
return true
|
||||
}
|
||||
path = filepath.ToSlash(strings.TrimSpace(path)) // For windows '\' must be converted to '/'
|
||||
for _, p := range strings.Split(path, SlashSeparator) {
|
||||
switch strings.TrimSpace(p) {
|
||||
|
||||
@@ -108,15 +108,15 @@ var containsReservedMetadataTests = []struct {
|
||||
},
|
||||
{
|
||||
header: http.Header{crypto.MetaIV: []string{"iv"}},
|
||||
shouldFail: true,
|
||||
shouldFail: false,
|
||||
},
|
||||
{
|
||||
header: http.Header{crypto.MetaAlgorithm: []string{crypto.InsecureSealAlgorithm}},
|
||||
shouldFail: true,
|
||||
shouldFail: false,
|
||||
},
|
||||
{
|
||||
header: http.Header{crypto.MetaSealedKeySSEC: []string{"mac"}},
|
||||
shouldFail: true,
|
||||
shouldFail: false,
|
||||
},
|
||||
{
|
||||
header: http.Header{ReservedMetadataPrefix + "Key": []string{"value"}},
|
||||
|
||||
+149
-110
@@ -1,4 +1,4 @@
|
||||
// Copyright (c) 2015-2022 MinIO, Inc.
|
||||
// Copyright (c) 2015-2024 MinIO, Inc.
|
||||
//
|
||||
// This file is part of MinIO Object Storage stack
|
||||
//
|
||||
@@ -19,16 +19,21 @@ package cmd
|
||||
|
||||
import (
|
||||
"context"
|
||||
"errors"
|
||||
"fmt"
|
||||
"math/rand"
|
||||
"runtime"
|
||||
"sort"
|
||||
"time"
|
||||
|
||||
"github.com/dustin/go-humanize"
|
||||
"github.com/minio/madmin-go/v3"
|
||||
"github.com/minio/minio/internal/bucket/lifecycle"
|
||||
objectlock "github.com/minio/minio/internal/bucket/object/lock"
|
||||
"github.com/minio/minio/internal/bucket/replication"
|
||||
"github.com/minio/minio/internal/bucket/versioning"
|
||||
"github.com/minio/minio/internal/color"
|
||||
"github.com/minio/minio/internal/config/storageclass"
|
||||
xioutil "github.com/minio/minio/internal/ioutil"
|
||||
"github.com/minio/minio/internal/logger"
|
||||
"github.com/minio/pkg/v2/console"
|
||||
"github.com/minio/pkg/v2/wildcard"
|
||||
@@ -65,7 +70,7 @@ func newBgHealSequence() *healSequence {
|
||||
reportProgress: false,
|
||||
scannedItemsMap: make(map[madmin.HealItemType]int64),
|
||||
healedItemsMap: make(map[madmin.HealItemType]int64),
|
||||
healFailedItemsMap: make(map[string]int64),
|
||||
healFailedItemsMap: make(map[madmin.HealItemType]int64),
|
||||
}
|
||||
}
|
||||
|
||||
@@ -135,6 +140,14 @@ func getLocalBackgroundHealStatus(ctx context.Context, o ObjectLayer) (madmin.Bg
|
||||
return status, true
|
||||
}
|
||||
|
||||
type healEntryResult struct {
|
||||
bytes uint64
|
||||
success bool
|
||||
skipped bool
|
||||
entryDone bool
|
||||
name string
|
||||
}
|
||||
|
||||
// healErasureSet lists and heals all objects in a specific erasure set
|
||||
func (er *erasureObjects) healErasureSet(ctx context.Context, buckets []string, tracker *healingTracker) error {
|
||||
scanMode := madmin.HealNormalScan
|
||||
@@ -153,7 +166,7 @@ func (er *erasureObjects) healErasureSet(ctx context.Context, buckets []string,
|
||||
_, err := objAPI.HealBucket(ctx, bucket, madmin.HealOpts{ScanMode: scanMode})
|
||||
if err != nil {
|
||||
// Log bucket healing error if any, we shall retry again.
|
||||
logger.LogIf(ctx, err)
|
||||
healingLogIf(ctx, err)
|
||||
}
|
||||
}
|
||||
|
||||
@@ -177,25 +190,72 @@ func (er *erasureObjects) healErasureSet(ctx context.Context, buckets []string,
|
||||
numHealers = uint64(v)
|
||||
}
|
||||
|
||||
logger.Event(ctx, fmt.Sprintf("Healing drive '%s' - use %d parallel workers.", tracker.disk.String(), numHealers))
|
||||
healingLogEvent(ctx, fmt.Sprintf("Healing drive '%s' - use %d parallel workers.", tracker.disk.String(), numHealers))
|
||||
|
||||
jt, _ := workers.New(int(numHealers))
|
||||
|
||||
healEntryDone := func(name string) healEntryResult {
|
||||
return healEntryResult{
|
||||
entryDone: true,
|
||||
name: name,
|
||||
}
|
||||
}
|
||||
|
||||
healEntrySuccess := func(sz uint64) healEntryResult {
|
||||
return healEntryResult{
|
||||
bytes: sz,
|
||||
success: true,
|
||||
}
|
||||
}
|
||||
|
||||
healEntryFailure := func(sz uint64) healEntryResult {
|
||||
return healEntryResult{
|
||||
bytes: sz,
|
||||
}
|
||||
}
|
||||
|
||||
healEntrySkipped := func(sz uint64) healEntryResult {
|
||||
return healEntryResult{
|
||||
bytes: sz,
|
||||
skipped: true,
|
||||
}
|
||||
}
|
||||
|
||||
// Collect updates to tracker from concurrent healEntry calls
|
||||
results := make(chan healEntryResult, 1000)
|
||||
defer close(results)
|
||||
|
||||
go func() {
|
||||
for res := range results {
|
||||
if res.entryDone {
|
||||
tracker.setObject(res.name)
|
||||
if time.Since(tracker.getLastUpdate()) > time.Minute {
|
||||
healingLogIf(ctx, tracker.update(ctx))
|
||||
}
|
||||
continue
|
||||
}
|
||||
|
||||
tracker.updateProgress(res.success, res.skipped, res.bytes)
|
||||
}
|
||||
}()
|
||||
|
||||
var retErr error
|
||||
|
||||
// Heal all buckets with all objects
|
||||
for _, bucket := range healBuckets {
|
||||
if tracker.isHealed(bucket) {
|
||||
continue
|
||||
}
|
||||
|
||||
var forwardTo string
|
||||
// If we resume to the same bucket, forward to last known item.
|
||||
if b := tracker.getBucket(); b != "" {
|
||||
if b == bucket {
|
||||
forwardTo = tracker.getObject()
|
||||
} else {
|
||||
// Reset to where last bucket ended if resuming.
|
||||
tracker.resume()
|
||||
}
|
||||
b := tracker.getBucket()
|
||||
if b == bucket {
|
||||
forwardTo = tracker.getObject()
|
||||
}
|
||||
if b != "" {
|
||||
// Reset to where last bucket ended if resuming.
|
||||
tracker.resume()
|
||||
}
|
||||
tracker.setObject("")
|
||||
tracker.setBucket(bucket)
|
||||
@@ -204,67 +264,75 @@ func (er *erasureObjects) healErasureSet(ctx context.Context, buckets []string,
|
||||
if _, err := objAPI.HealBucket(ctx, bucket, madmin.HealOpts{
|
||||
ScanMode: scanMode,
|
||||
}); err != nil {
|
||||
logger.LogIf(ctx, err)
|
||||
// Set this such that when we return this function
|
||||
// we let the caller retry this disk again for the
|
||||
// buckets that failed healing.
|
||||
retErr = err
|
||||
healingLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
|
||||
vc, _ := globalBucketVersioningSys.Get(bucket)
|
||||
var (
|
||||
vc *versioning.Versioning
|
||||
lc *lifecycle.Lifecycle
|
||||
lr objectlock.Retention
|
||||
rcfg *replication.Config
|
||||
)
|
||||
|
||||
// Check if the current bucket has a configured lifecycle policy
|
||||
lc, _ := globalLifecycleSys.Get(bucket)
|
||||
|
||||
// Check if bucket is object locked.
|
||||
lr, _ := globalBucketObjectLockSys.Get(bucket)
|
||||
rcfg, _ := getReplicationConfig(ctx, bucket)
|
||||
if !isMinioMetaBucketName(bucket) {
|
||||
vc, err = globalBucketVersioningSys.Get(bucket)
|
||||
if err != nil {
|
||||
retErr = err
|
||||
healingLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
// Check if the current bucket has a configured lifecycle policy
|
||||
lc, err = globalLifecycleSys.Get(bucket)
|
||||
if err != nil && !errors.Is(err, BucketLifecycleNotFound{Bucket: bucket}) {
|
||||
retErr = err
|
||||
healingLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
// Check if bucket is object locked.
|
||||
lr, err = globalBucketObjectLockSys.Get(bucket)
|
||||
if err != nil {
|
||||
retErr = err
|
||||
healingLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
rcfg, err = getReplicationConfig(ctx, bucket)
|
||||
if err != nil {
|
||||
retErr = err
|
||||
healingLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
}
|
||||
|
||||
if serverDebugLog {
|
||||
console.Debugf(color.Green("healDrive:")+" healing bucket %s content on %s erasure set\n",
|
||||
bucket, humanize.Ordinal(er.setIndex+1))
|
||||
}
|
||||
|
||||
disks, _ := er.getOnlineDisksWithHealing(false)
|
||||
if len(disks) == 0 {
|
||||
// No object healing necessary
|
||||
tracker.bucketDone(bucket)
|
||||
logger.LogIf(ctx, tracker.update(ctx))
|
||||
continue
|
||||
disks, _, healing := er.getOnlineDisksWithHealingAndInfo(true)
|
||||
if len(disks) == healing {
|
||||
// All drives in this erasure set were reformatted for some reasons, abort healing and mark it as successful
|
||||
healingLogIf(ctx, errors.New("all drives are in healing state, aborting.."))
|
||||
return nil
|
||||
}
|
||||
|
||||
// Limit listing to 3 drives.
|
||||
if len(disks) > 3 {
|
||||
disks = disks[:3]
|
||||
disks = disks[:len(disks)-healing] // healing drives are always at the end of the list
|
||||
|
||||
if len(disks) < er.setDriveCount/2 {
|
||||
return fmt.Errorf("not enough drives (found=%d, healing=%d, total=%d) are available to heal `%s`", len(disks), healing, er.setDriveCount, tracker.disk.String())
|
||||
}
|
||||
|
||||
type healEntryResult struct {
|
||||
bytes uint64
|
||||
success bool
|
||||
skipped bool
|
||||
entryDone bool
|
||||
name string
|
||||
}
|
||||
healEntryDone := func(name string) healEntryResult {
|
||||
return healEntryResult{
|
||||
entryDone: true,
|
||||
name: name,
|
||||
}
|
||||
}
|
||||
healEntrySuccess := func(sz uint64) healEntryResult {
|
||||
return healEntryResult{
|
||||
bytes: sz,
|
||||
success: true,
|
||||
}
|
||||
}
|
||||
healEntryFailure := func(sz uint64) healEntryResult {
|
||||
return healEntryResult{
|
||||
bytes: sz,
|
||||
}
|
||||
}
|
||||
healEntrySkipped := func(sz uint64) healEntryResult {
|
||||
return healEntryResult{
|
||||
bytes: sz,
|
||||
skipped: true,
|
||||
}
|
||||
}
|
||||
rand.Shuffle(len(disks), func(i, j int) {
|
||||
disks[i], disks[j] = disks[j], disks[i]
|
||||
})
|
||||
|
||||
expectedDisks := len(disks)/2 + 1
|
||||
fallbackDisks := disks[expectedDisks:]
|
||||
disks = disks[:expectedDisks]
|
||||
|
||||
filterLifecycle := func(bucket, object string, fi FileInfo) bool {
|
||||
if lc == nil {
|
||||
@@ -286,27 +354,11 @@ func (er *erasureObjects) healErasureSet(ctx context.Context, buckets []string,
|
||||
}
|
||||
}
|
||||
|
||||
// Collect updates to tracker from concurrent healEntry calls
|
||||
results := make(chan healEntryResult, 1000)
|
||||
go func() {
|
||||
for res := range results {
|
||||
if res.entryDone {
|
||||
tracker.setObject(res.name)
|
||||
if time.Since(tracker.getLastUpdate()) > time.Minute {
|
||||
logger.LogIf(ctx, tracker.update(ctx))
|
||||
}
|
||||
continue
|
||||
}
|
||||
|
||||
tracker.updateProgress(res.success, res.skipped, res.bytes)
|
||||
}
|
||||
}()
|
||||
|
||||
send := func(result healEntryResult) bool {
|
||||
select {
|
||||
case <-ctx.Done():
|
||||
if !contextCanceled(ctx) {
|
||||
logger.LogIf(ctx, ctx.Err())
|
||||
healingLogIf(ctx, ctx.Err())
|
||||
}
|
||||
return false
|
||||
case results <- result:
|
||||
@@ -348,7 +400,7 @@ func (er *erasureObjects) healErasureSet(ctx context.Context, buckets []string,
|
||||
var result healEntryResult
|
||||
fivs, err := entry.fileInfoVersions(bucket)
|
||||
if err != nil {
|
||||
_, err := er.HealObject(ctx, bucket, encodedEntryName, "",
|
||||
res, err := er.HealObject(ctx, bucket, encodedEntryName, "",
|
||||
madmin.HealOpts{
|
||||
ScanMode: scanMode,
|
||||
Remove: healDeleteDangling,
|
||||
@@ -360,9 +412,9 @@ func (er *erasureObjects) healErasureSet(ctx context.Context, buckets []string,
|
||||
return
|
||||
}
|
||||
result = healEntryFailure(0)
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to heal object %s/%s: %w", bucket, entry.name, err))
|
||||
healingLogIf(ctx, fmt.Errorf("unable to heal object %s/%s: %w", bucket, entry.name, err))
|
||||
} else {
|
||||
result = healEntrySuccess(0)
|
||||
result = healEntrySuccess(uint64(res.ObjectSize))
|
||||
}
|
||||
|
||||
send(result)
|
||||
@@ -385,11 +437,12 @@ func (er *erasureObjects) healErasureSet(ctx context.Context, buckets []string,
|
||||
continue
|
||||
}
|
||||
|
||||
if _, err := er.HealObject(ctx, bucket, encodedEntryName,
|
||||
res, err := er.HealObject(ctx, bucket, encodedEntryName,
|
||||
version.VersionID, madmin.HealOpts{
|
||||
ScanMode: scanMode,
|
||||
Remove: healDeleteDangling,
|
||||
}); err != nil {
|
||||
})
|
||||
if err != nil {
|
||||
if isErrObjectNotFound(err) || isErrVersionNotFound(err) {
|
||||
// queueing happens across namespace, ignore
|
||||
// objects that are not found.
|
||||
@@ -399,52 +452,48 @@ func (er *erasureObjects) healErasureSet(ctx context.Context, buckets []string,
|
||||
// If not deleted, assume they failed.
|
||||
result = healEntryFailure(uint64(version.Size))
|
||||
if version.VersionID != "" {
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to heal object %s/%s-v(%s): %w", bucket, version.Name, version.VersionID, err))
|
||||
healingLogIf(ctx, fmt.Errorf("unable to heal object %s/%s-v(%s): %w", bucket, version.Name, version.VersionID, err))
|
||||
} else {
|
||||
logger.LogIf(ctx, fmt.Errorf("unable to heal object %s/%s: %w", bucket, version.Name, err))
|
||||
healingLogIf(ctx, fmt.Errorf("unable to heal object %s/%s: %w", bucket, version.Name, err))
|
||||
}
|
||||
} else {
|
||||
result = healEntrySuccess(uint64(version.Size))
|
||||
result = healEntrySuccess(uint64(res.ObjectSize))
|
||||
}
|
||||
|
||||
if !send(result) {
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
// All versions resulted in 'ObjectNotFound/VersionNotFound'
|
||||
if versionNotFound == len(fivs.Versions) {
|
||||
return
|
||||
}
|
||||
select {
|
||||
case <-ctx.Done():
|
||||
return
|
||||
case results <- healEntryDone(entry.name):
|
||||
}
|
||||
|
||||
send(healEntryDone(entry.name))
|
||||
|
||||
// Wait and proceed if there are active requests
|
||||
waitForLowHTTPReq()
|
||||
}
|
||||
|
||||
actualBucket, prefix := path2BucketObject(bucket)
|
||||
|
||||
// How to resolve partial results.
|
||||
resolver := metadataResolutionParams{
|
||||
dirQuorum: 1,
|
||||
objQuorum: 1,
|
||||
bucket: actualBucket,
|
||||
bucket: bucket,
|
||||
}
|
||||
|
||||
err := listPathRaw(ctx, listPathRawOptions{
|
||||
err = listPathRaw(ctx, listPathRawOptions{
|
||||
disks: disks,
|
||||
bucket: actualBucket,
|
||||
path: prefix,
|
||||
fallbackDisks: fallbackDisks,
|
||||
bucket: bucket,
|
||||
recursive: true,
|
||||
forwardTo: forwardTo,
|
||||
minDisks: 1,
|
||||
reportNotFound: false,
|
||||
agreed: func(entry metaCacheEntry) {
|
||||
jt.Take()
|
||||
go healEntry(actualBucket, entry)
|
||||
go healEntry(bucket, entry)
|
||||
},
|
||||
partial: func(entries metaCacheEntries, _ []error) {
|
||||
entry, ok := entries.resolve(&resolver)
|
||||
@@ -454,18 +503,17 @@ func (er *erasureObjects) healErasureSet(ctx context.Context, buckets []string,
|
||||
entry, _ = entries.firstFound()
|
||||
}
|
||||
jt.Take()
|
||||
go healEntry(actualBucket, *entry)
|
||||
go healEntry(bucket, *entry)
|
||||
},
|
||||
finished: nil,
|
||||
})
|
||||
jt.Wait() // synchronize all the concurrent heal jobs
|
||||
xioutil.SafeClose(results)
|
||||
if err != nil {
|
||||
// Set this such that when we return this function
|
||||
// we let the caller retry this disk again for the
|
||||
// buckets it failed to list.
|
||||
retErr = err
|
||||
logger.LogIf(ctx, err)
|
||||
healingLogIf(ctx, err)
|
||||
continue
|
||||
}
|
||||
|
||||
@@ -475,7 +523,7 @@ func (er *erasureObjects) healErasureSet(ctx context.Context, buckets []string,
|
||||
return ctx.Err()
|
||||
default:
|
||||
tracker.bucketDone(bucket)
|
||||
logger.LogIf(ctx, tracker.update(ctx))
|
||||
healingLogIf(ctx, tracker.update(ctx))
|
||||
}
|
||||
}
|
||||
|
||||
@@ -499,16 +547,7 @@ func healObject(bucket, object, versionID string, scan madmin.HealScanMode) erro
|
||||
// Get background heal sequence to send elements to heal
|
||||
bgSeq, ok := globalBackgroundHealState.getHealSequenceByToken(bgHealingUUID)
|
||||
if ok {
|
||||
return bgSeq.queueHealTask(healSource{
|
||||
bucket: bucket,
|
||||
object: object,
|
||||
versionID: versionID,
|
||||
noWait: true, // do not block callers.
|
||||
opts: &madmin.HealOpts{
|
||||
Remove: healDeleteDangling, // if found dangling purge it.
|
||||
ScanMode: scan,
|
||||
},
|
||||
}, madmin.HealItemObject)
|
||||
return bgSeq.healObject(bucket, object, versionID, scan)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
+8
-11
@@ -171,7 +171,8 @@ type serverCtxt struct {
|
||||
ReadHeaderTimeout time.Duration
|
||||
MaxIdleConnsPerHost int
|
||||
|
||||
CrossDomainXML string
|
||||
SendBufSize, RecvBufSize int
|
||||
CrossDomainXML string
|
||||
// The layout of disks as interpreted
|
||||
Layout disksLayout
|
||||
}
|
||||
@@ -241,7 +242,7 @@ var (
|
||||
globalBucketMonitor *bandwidth.Monitor
|
||||
globalPolicySys *PolicySys
|
||||
globalIAMSys *IAMSys
|
||||
globalBytePoolCap *bpool.BytePoolCap
|
||||
globalBytePoolCap atomic.Pointer[bpool.BytePoolCap]
|
||||
|
||||
globalLifecycleSys *LifecycleSys
|
||||
globalBucketSSEConfigSys *BucketSSEConfigSys
|
||||
@@ -348,7 +349,7 @@ var (
|
||||
globalDNSConfig dns.Store
|
||||
|
||||
// GlobalKMS initialized KMS configuration
|
||||
GlobalKMS kms.KMS
|
||||
GlobalKMS *kms.KMS
|
||||
|
||||
// Common lock for various subsystems performing the leader tasks
|
||||
globalLeaderLock *sharedLock
|
||||
@@ -398,12 +399,8 @@ var (
|
||||
|
||||
globalInternodeTransport http.RoundTripper
|
||||
|
||||
globalProxyTransport http.RoundTripper
|
||||
|
||||
globalRemoteTargetTransport http.RoundTripper
|
||||
|
||||
globalHealthChkTransport http.RoundTripper
|
||||
|
||||
globalDNSCache = &dnscache.Resolver{
|
||||
Timeout: 5 * time.Second,
|
||||
}
|
||||
@@ -450,11 +447,11 @@ var (
|
||||
subnetAdminPublicKey = []byte("-----BEGIN PUBLIC KEY-----\nMIIBCgKCAQEAyC+ol5v0FP+QcsR6d1KypR/063FInmNEFsFzbEwlHQyEQN3O7kNI\nwVDN1vqp1wDmJYmv4VZGRGzfFw1q+QV7K1TnysrEjrqpVxfxzDQCoUadAp8IxLLc\ns2fjyDNxnZjoC6fTID9C0khKnEa5fPZZc3Ihci9SiCGkPmyUyCGVSxWXIKqL2Lrj\nyDc0pGeEhWeEPqw6q8X2jvTC246tlzqpDeNsPbcv2KblXRcKniQNbBrizT37CKHQ\nM6hc9kugrZbFuo8U5/4RQvZPJnx/DVjLDyoKo2uzuVQs4s+iBrA5sSSLp8rPED/3\n6DgWw3e244Dxtrg972dIT1IOqgn7KUJzVQIDAQAB\n-----END PUBLIC KEY-----")
|
||||
subnetAdminPublicKeyDev = []byte("-----BEGIN PUBLIC KEY-----\nMIIBCgKCAQEArhQYXQd6zI4uagtVfthAPOt6i4AYHnEWCoNeAovM4MNl42I9uQFh\n3VHkbWj9Gpx9ghf6PgRgK+8FcFvy+StmGcXpDCiFywXX24uNhcZjscX1C4Esk0BW\nidfI2eXYkOlymD4lcK70SVgJvC693Qa7Z3FE1KU8Nfv2bkxEE4bzOkojX9t6a3+J\nR8X6Z2U8EMlH1qxJPgiPogELhWP0qf2Lq7GwSAflo1Tj/ytxvD12WrnE0Rrj/8yP\nSnp7TbYm91KocKMExlmvx3l2XPLxeU8nf9U0U+KOmorejD3MDMEPF+tlk9LB3JWP\nZqYYe38rfALVTn4RVJriUcNOoEpEyC0WEwIDAQAB\n-----END PUBLIC KEY-----")
|
||||
|
||||
globalConnReadDeadline time.Duration
|
||||
globalConnWriteDeadline time.Duration
|
||||
// dynamic sleeper to avoid thundering herd for trash folder expunge routine
|
||||
deleteCleanupSleeper = newDynamicSleeper(5, 25*time.Millisecond, false)
|
||||
|
||||
// Controller for deleted file sweeper.
|
||||
deletedCleanupSleeper = newDynamicSleeper(5, 25*time.Millisecond, false)
|
||||
// dynamic sleeper for multipart expiration routine
|
||||
deleteMultipartCleanupSleeper = newDynamicSleeper(5, 25*time.Millisecond, false)
|
||||
|
||||
// Is _MINIO_DISABLE_API_FREEZE_ON_BOOT set?
|
||||
globalDisableFreezeOnBoot bool
|
||||
|
||||
+46
-33
@@ -18,9 +18,11 @@
|
||||
package cmd
|
||||
|
||||
import (
|
||||
"math"
|
||||
"net/http"
|
||||
"os"
|
||||
"runtime"
|
||||
"slices"
|
||||
"strconv"
|
||||
"strings"
|
||||
"sync"
|
||||
@@ -37,13 +39,11 @@ import (
|
||||
type apiConfig struct {
|
||||
mu sync.RWMutex
|
||||
|
||||
requestsDeadline time.Duration
|
||||
requestsPool chan struct{}
|
||||
clusterDeadline time.Duration
|
||||
listQuorum string
|
||||
corsAllowOrigins []string
|
||||
// total drives per erasure set across pools.
|
||||
totalDriveCount int
|
||||
requestsDeadline time.Duration
|
||||
requestsPool chan struct{}
|
||||
clusterDeadline time.Duration
|
||||
listQuorum string
|
||||
corsAllowOrigins []string
|
||||
replicationPriority string
|
||||
replicationMaxWorkers int
|
||||
transitionWorkers int
|
||||
@@ -55,7 +55,7 @@ type apiConfig struct {
|
||||
gzipObjects bool
|
||||
rootAccess bool
|
||||
syncEvents bool
|
||||
objectMaxVersions int
|
||||
objectMaxVersions int64
|
||||
}
|
||||
|
||||
const (
|
||||
@@ -109,7 +109,7 @@ func availableMemory() (available uint64) {
|
||||
return
|
||||
}
|
||||
|
||||
func (t *apiConfig) init(cfg api.Config, setDriveCounts []int) {
|
||||
func (t *apiConfig) init(cfg api.Config, setDriveCounts []int, legacy bool) {
|
||||
t.mu.Lock()
|
||||
defer t.mu.Unlock()
|
||||
|
||||
@@ -124,27 +124,24 @@ func (t *apiConfig) init(cfg api.Config, setDriveCounts []int) {
|
||||
}
|
||||
t.corsAllowOrigins = corsAllowOrigin
|
||||
|
||||
maxSetDrives := 0
|
||||
for _, setDriveCount := range setDriveCounts {
|
||||
t.totalDriveCount += setDriveCount
|
||||
if setDriveCount > maxSetDrives {
|
||||
maxSetDrives = setDriveCount
|
||||
}
|
||||
}
|
||||
|
||||
var apiRequestsMaxPerNode int
|
||||
if cfg.RequestsMax <= 0 {
|
||||
maxSetDrives := slices.Max(setDriveCounts)
|
||||
|
||||
// Returns 75% of max memory allowed
|
||||
maxMem := availableMemory()
|
||||
|
||||
// max requests per node is calculated as
|
||||
// total_ram / ram_per_request
|
||||
// ram_per_request is (2MiB+128KiB) * driveCount \
|
||||
// + 2 * 10MiB (default erasure block size v1) + 2 * 1MiB (default erasure block size v2)
|
||||
blockSize := xioutil.BlockSizeLarge + xioutil.BlockSizeSmall
|
||||
apiRequestsMaxPerNode = int(maxMem / uint64(maxSetDrives*blockSize+int(blockSizeV1*2+blockSizeV2*2)))
|
||||
if globalIsDistErasure {
|
||||
logger.Info("Automatically configured API requests per node based on available memory on the system: %d", apiRequestsMaxPerNode)
|
||||
blockSize := xioutil.LargeBlock + xioutil.SmallBlock
|
||||
if legacy {
|
||||
// ram_per_request is (1MiB+32KiB) * driveCount \
|
||||
// + 2 * 10MiB (default erasure block size v1) + 2 * 1MiB (default erasure block size v2)
|
||||
apiRequestsMaxPerNode = int(maxMem / uint64(maxSetDrives*blockSize+int(blockSizeV1*2+blockSizeV2*2)))
|
||||
} else {
|
||||
// ram_per_request is (1MiB+32KiB) * driveCount \
|
||||
// + 2 * 1MiB (default erasure block size v2)
|
||||
apiRequestsMaxPerNode = int(maxMem / uint64(maxSetDrives*blockSize+int(blockSizeV2*2)))
|
||||
}
|
||||
} else {
|
||||
apiRequestsMaxPerNode = cfg.RequestsMax
|
||||
@@ -153,6 +150,10 @@ func (t *apiConfig) init(cfg api.Config, setDriveCounts []int) {
|
||||
}
|
||||
}
|
||||
|
||||
if globalIsDistErasure {
|
||||
logger.Info("Configured max API requests per node based on available memory: %d", apiRequestsMaxPerNode)
|
||||
}
|
||||
|
||||
if cap(t.requestsPool) != apiRequestsMaxPerNode {
|
||||
// Only replace if needed.
|
||||
// Existing requests will use the previous limit,
|
||||
@@ -320,13 +321,21 @@ func maxClients(f http.HandlerFunc) http.HandlerFunc {
|
||||
}
|
||||
}
|
||||
|
||||
globalHTTPStats.addRequestsInQueue(1)
|
||||
defer globalHTTPStats.addRequestsInQueue(-1)
|
||||
|
||||
pool, deadline := globalAPIConfig.getRequestsPool()
|
||||
if pool == nil {
|
||||
f.ServeHTTP(w, r)
|
||||
return
|
||||
}
|
||||
|
||||
globalHTTPStats.addRequestsInQueue(1)
|
||||
// No deadline to wait, there is nothing to queue
|
||||
// perform the API call immediately.
|
||||
if deadline <= 0 {
|
||||
f.ServeHTTP(w, r)
|
||||
return
|
||||
}
|
||||
|
||||
if tc, ok := r.Context().Value(mcontext.ContextTraceKey).(*mcontext.TraceCtxt); ok {
|
||||
tc.FuncName = "s3.MaxClients"
|
||||
@@ -335,25 +344,29 @@ func maxClients(f http.HandlerFunc) http.HandlerFunc {
|
||||
deadlineTimer := time.NewTimer(deadline)
|
||||
defer deadlineTimer.Stop()
|
||||
|
||||
ctx := r.Context()
|
||||
select {
|
||||
case pool <- struct{}{}:
|
||||
defer func() { <-pool }()
|
||||
globalHTTPStats.addRequestsInQueue(-1)
|
||||
if contextCanceled(ctx) {
|
||||
w.WriteHeader(499)
|
||||
return
|
||||
}
|
||||
f.ServeHTTP(w, r)
|
||||
case <-deadlineTimer.C:
|
||||
if contextCanceled(ctx) {
|
||||
w.WriteHeader(499)
|
||||
return
|
||||
}
|
||||
// Send a http timeout message
|
||||
writeErrorResponse(r.Context(), w,
|
||||
writeErrorResponse(ctx, w,
|
||||
errorCodes.ToAPIErr(ErrTooManyRequests),
|
||||
r.URL)
|
||||
globalHTTPStats.addRequestsInQueue(-1)
|
||||
return
|
||||
case <-r.Context().Done():
|
||||
// When the client disconnects before getting the S3 handler
|
||||
// status code response, set the status code to 499 so this request
|
||||
// will be properly audited and traced.
|
||||
w.WriteHeader(499)
|
||||
globalHTTPStats.addRequestsInQueue(-1)
|
||||
return
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -393,13 +406,13 @@ func (t *apiConfig) isSyncEventsEnabled() bool {
|
||||
return t.syncEvents
|
||||
}
|
||||
|
||||
func (t *apiConfig) getObjectMaxVersions() int {
|
||||
func (t *apiConfig) getObjectMaxVersions() int64 {
|
||||
t.mu.RLock()
|
||||
defer t.mu.RUnlock()
|
||||
|
||||
if t.objectMaxVersions <= 0 {
|
||||
// defaults to 'maxObjectVersions' when unset.
|
||||
return maxObjectVersions
|
||||
// defaults to 'IntMax' when unset.
|
||||
return math.MaxInt64
|
||||
}
|
||||
|
||||
return t.objectMaxVersions
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user